nothing gets my heart rate up like waiting for eval results on new models to come in
RESEARCH
-
Fine-tuning GPT-3.5: Use Cases and Community Experiences
By
–
Using https://
platform.openai.com/docs/guides/fi
ne-tuning
… ? What have you used that for – I've not heard many examples of people fine-tuning 3.5 -
torch.compile uses Triton kernels under the hood for optimization
By
–
So if you're using torch.compile you're already using a lot of triton under the hood, afaik PyTorch picks and chooses whether to call cuda kernels or triton for different ops / settings. Triton is really awesome, but of course you're staying in the Python / torch universe. Which
-
llm.c Matches PyTorch Performance Training GPT-2 on GPU
By
–
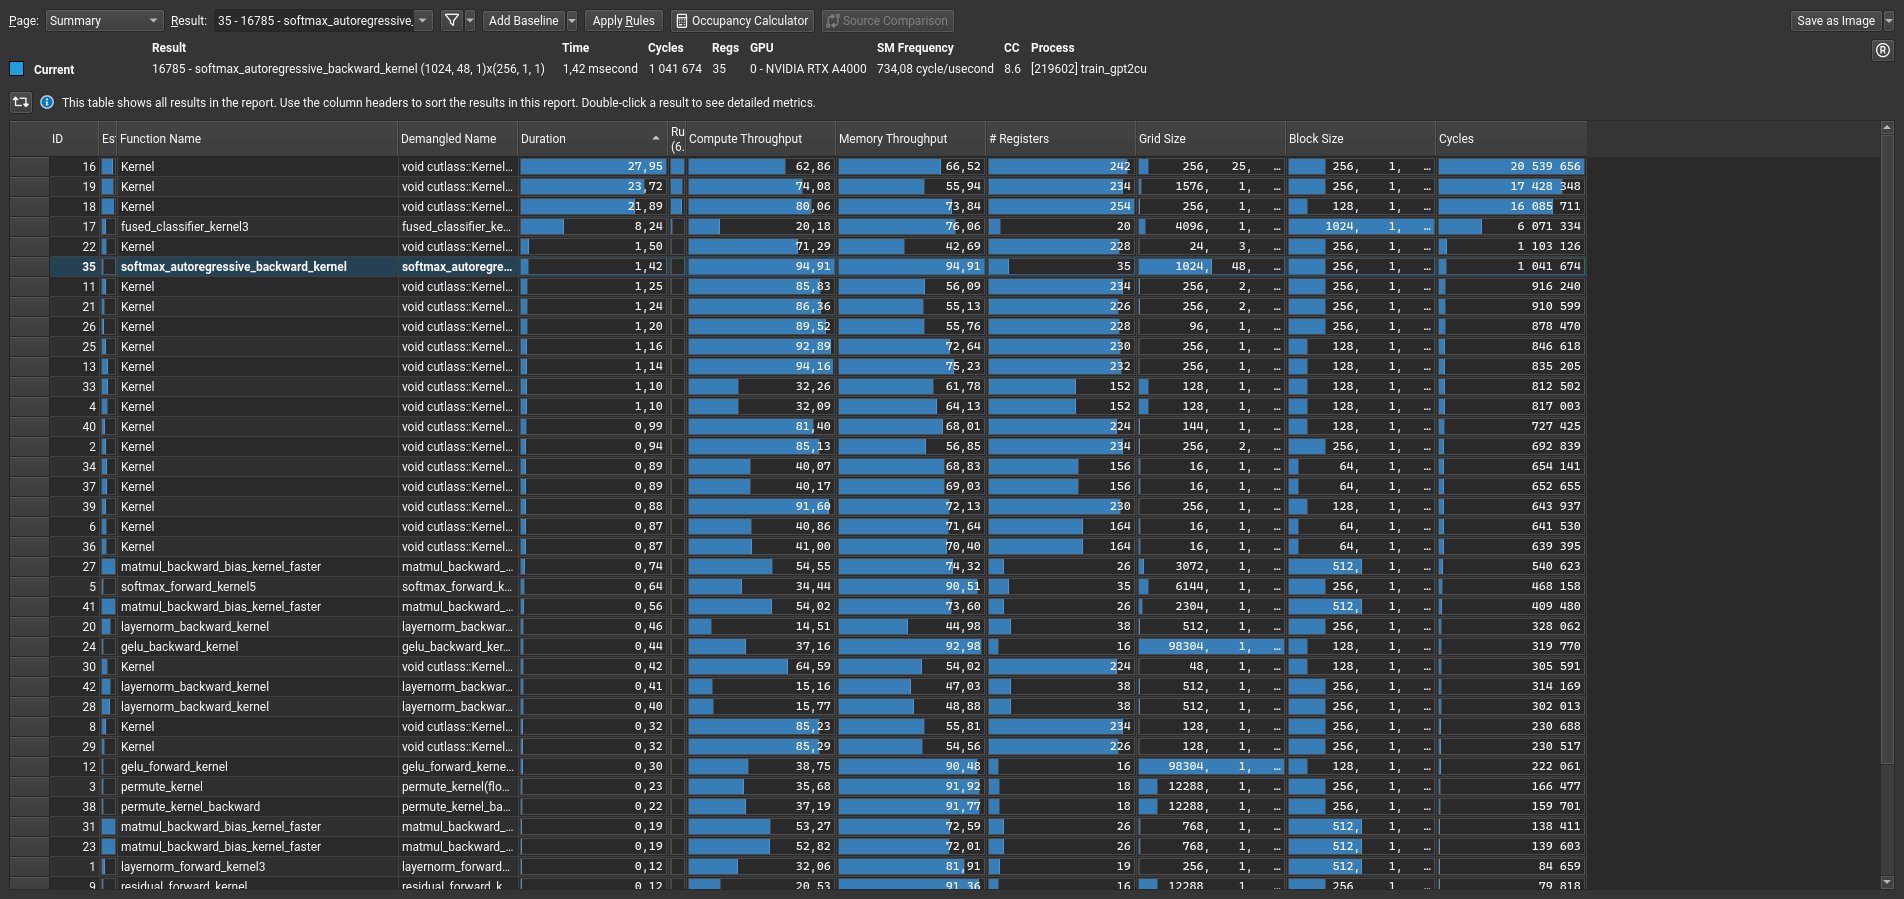
llm.c update: Our single file of 2,000 ~clean lines of C/CUDA code now trains GPT-2 (124M) on GPU at speeds ~matching PyTorch (fp32, no flash attention) https://
github.com/karpathy/llm.c
/blob/master/train_gpt2.cu
… On my A100 I'm seeing 78ms/iter for llm.c and 80ms/iter for PyTorch. Keeping in mind this is fp32, -
Rodney Brooks Mourns Passing of Philosopher Daniel Dennett
By
–
My dear and long time friend Daniel Dennett passed away today. He was a towering figure in philosophy and in particular in the philosophy of AI. Now we have only memories of him. [[And do keep up to date with your correspondence–I have a 30 day old email from him in my inbox
-
Benchmarking Results: OpenAI and Anthropic Lead Agent Performance
By
–
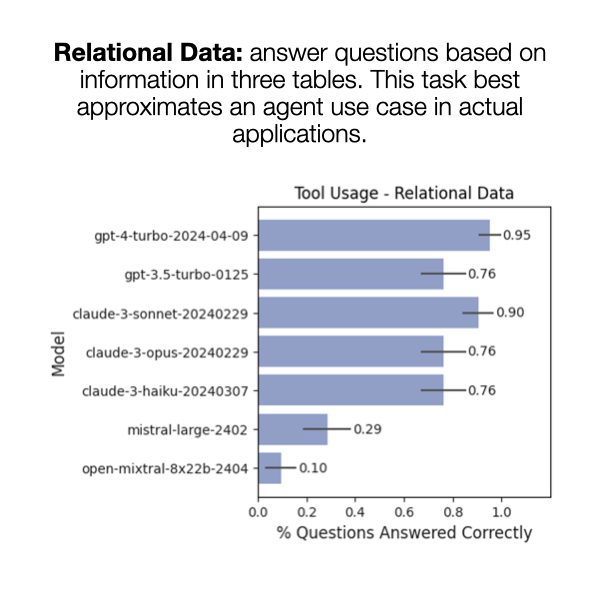
Benchmarking Agents We’re happy to share updated benchmarking results using `langchain-benchmarks` to evaluate agents based on different models. @OpenAI and @AnthropicAI take the lead across a variety of tasks. For more explanation about the various benchmarking
-

Remembering Daniel Dennett: Philosopher of Mind and Intelligence
By
–
One of the greatest minds of our times has died. This is a huge blow to the fields of philosophy, morality, consciousness and intelligence. I adored his teachings even though sometimes it took me years to get them. His ideas will live on. @danieldennett
-
Open Models Drive Rapid AI Capability Improvements and Speed
By
–
Because anyone can work with them, open models are likely to improve very quickly, creating a lot of capabilities focused on factors ranging from speed to costs.
— Ethan Mollick (@emollick) 19 avril 2024
Here is the new Llama 3 70B being served by Groq (with a q) at 224 tokens/second. This is real-time of me using it. pic.twitter.com/L6i6T6OBbWBecause anyone can work with them, open models are likely to improve very quickly, creating a lot of capabilities focused on factors ranging from speed to costs. Here is the new Llama 3 70B being served by Groq (with a q) at 224 tokens/second. This is real-time of me using it.
-

KRAS Cancer Mutations Now Druggable With AI Advances
By
–
Not many years ago we had no treatments vs KRAS driver mutations for cancer. Considered undruggable. Now look! https://
nature.com/articles/s4159
1-024-02903-0
… @NatureMedicine @EileenMOReilly @MSKCancerCenter -
Fine-tuning vs RAG: When to Use Each Approach
By
–
That's not the same as believing that fine tuning can't teach a model new knowledge under any circumstances – but in practice many people I see who think they need to fine tune a model would be better off using RAG instead