Trends of top arXiv papers this past month Showing views on alphaXiv over time for
– DeepSeek V3
– DeepSeek R1
– s1: Simple test-time scaling
RESEARCH
-

Top arXiv Paper Trends: DeepSeek and Test-Time Scaling
By
–
-

R1 Explicit Preference Reward Training Purpose Discussion
By
–
Why not? I mean R1 even had an explicit preference reward at the end of training; I think that's there exactly for that purpose.
-
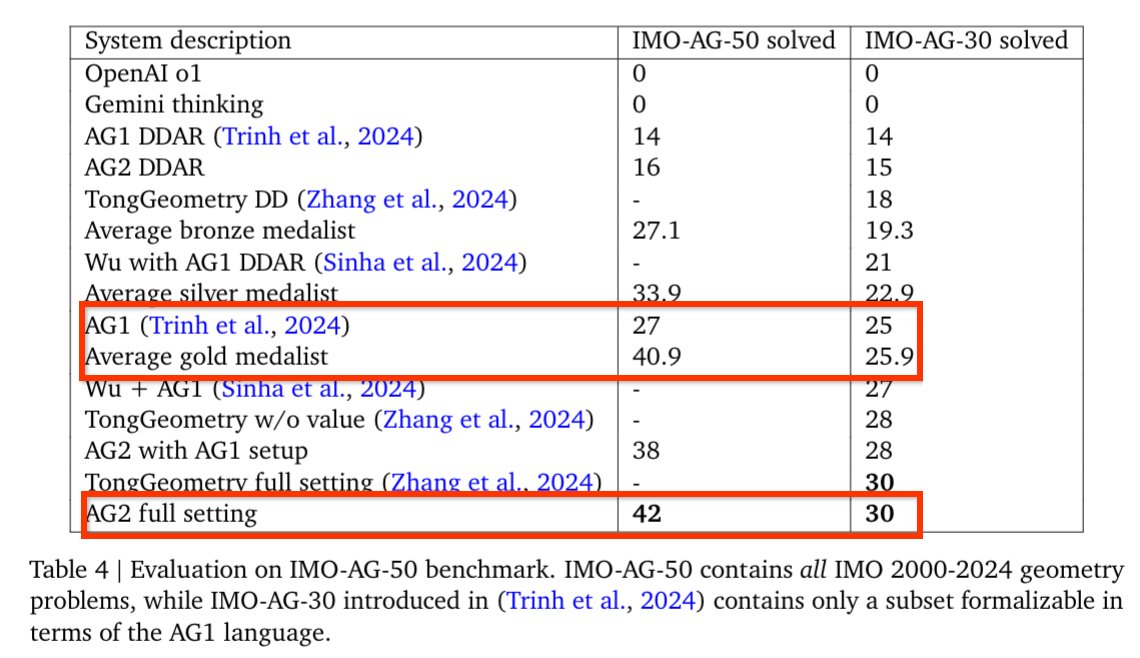
AG2 Advances: Expanded Language and Faster Symbolic Engine
By
–
AG2 comes with significant upgrades:
* an expanded domain-specific language to cover 88% of IMO geometry problems compared to 66% previously.
* an improved symbolic engine that is more robust and two-order of magnitude faster.
* an enhanced language model that is based on Gemini -
Why DPO Remains Popular Over Reinforcement Learning
By
–
"just" RL :). There's a reason why DPO is so popular (even Llama 3 used it )
-
Arc Prize Organization on Hugging Face Launches Next Activity
By
–
There's a already an org: https://
huggingface.co/arcprize. Feel free to follow it for next activity. Can't wait to see what they do next! -
Expert LLMs Don’t Require Reasoning Capabilities
By
–
The one thing to add though is that an "expert" LLM doesn't necessarily have to be a reasoning LLM (you could have one that answers biology Q&As perfectly without reasoning steps involved).
Similarly, you can have a generalist reasoning LLM that is not an expert in one -

AlphaGeometry2 Surpasses Gold-Medalist Standard IMO Geometry
By
–
Excited to share details of AlphaGeometry2 (AG2), part of the system that achieved silver-medal standard at IMO 2024 last July! AG2 now has surpassed the average gold-medalist in solving Olympiad geometry problems, achieving a solving rate of 84% for all IMO geometry problems
-
Rule-Based Rewards Scale Better Than Style Preferences
By
–
The nice thing here is that the rule-based rewards scale better. And for things like code and math, they also make a lot more sense. I.e., you care more about correctness than style preference. Btw @natolambert 's team's OLMo 2 also used verifiable rewards in the RLHF stage for
-
From Prompt Engineering to Personality Engineering: 2025 Trends
By
–
2024: all about prompt engineering
2025: all about personality engineering -

Mistral Small 3: Fast Open-Source Model Competes with Larger Models
By
–
5/ Mistral Small 3: fast, open-source, and ready to compete Mistral released Small 3, a 24B model with 81% MMLU accuracy, impressing the community with its performance and efficiency in the small model category. It can even compete with models 3x its size.