With #WWDC25 today, it's worth taking a look at new Apple research that suggests large reasoning models (LRMs) maybe don't think differently than other LLMs. On, in honor of the iconic Apple ad campaign, Apple's researchers could've said LRMs don't "think different."
RESEARCH
-
DeepMind’s automated research agents discussed by SR Schmidgall
By
–
Excited to have @SRSchmidgall from DeepMind discussing his work this Friday on automated research agents. Shoutout to @IntologyAI for making this happen! https://
x.com/IntologyAI/sta
/IntologyAI/status/1932144619015586183
… -

Fast AI Models: Optimus Alpha and Grok 3 Beat R1
By
–
BTW on the next page, there's some interesting fast-yet-decent models, including the mysterious Optimus Alpha (is this the upcoming OpenAI open source model?) and Grok 3 Beta, which are both super fast! (~40x faster than R1!) (GPT 4.5 tldr: slow, very expensive, & wrong.)
-
AI Quality Depends on Data Quality and Your Actions
By
–
AI Is Only As Good As The Data Behind It—And What You Can Do About It
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @fabiomoioli @pascal_bornet @alliekmiller @mattshumer_ @OfficialLoganK @jeremyphoward @GaryMarcus -
Random Forests for Reliable Feature Importance Measurement
By
–
Random forests are pretty much impossible to mess up. That's important for measuring feature importance, because you want your measurements to be reliable.
-

Stanford AI Startup Series: Ethical Design and Implementation
By
–
As part of the @StanfordHAI Startup Series, join us on June 11 to explore the unique opportunities and challenges that AI startups face in turning AI research into viable products, with a focus on ethical design and implementation. RSVP here: https://
bit.ly/3Hz4dsW -

AReaL: Asynchronous Reinforcement Learning System for Language Reasoning
By
–
AReaL: A Large-Scale Asynchronous Reinforcement Learning System for Language Reasoning AReaL is an asynchronous reinforcement learning system that efficiently trains large language models for reasoning tasks by maximizing GPU usage and decoupling generation from training.
-

Pseudo-Simulation: New Autonomous Driving Evaluation Paradigm
By
–
Pseudo-Simulation for Autonomous Driving Pseudo-simulation is a new evaluation paradigm for autonomous vehicles that blends the realism of real-world data with the generalization power of simulation, enabling robust, scalable testing without the need for interactive
-
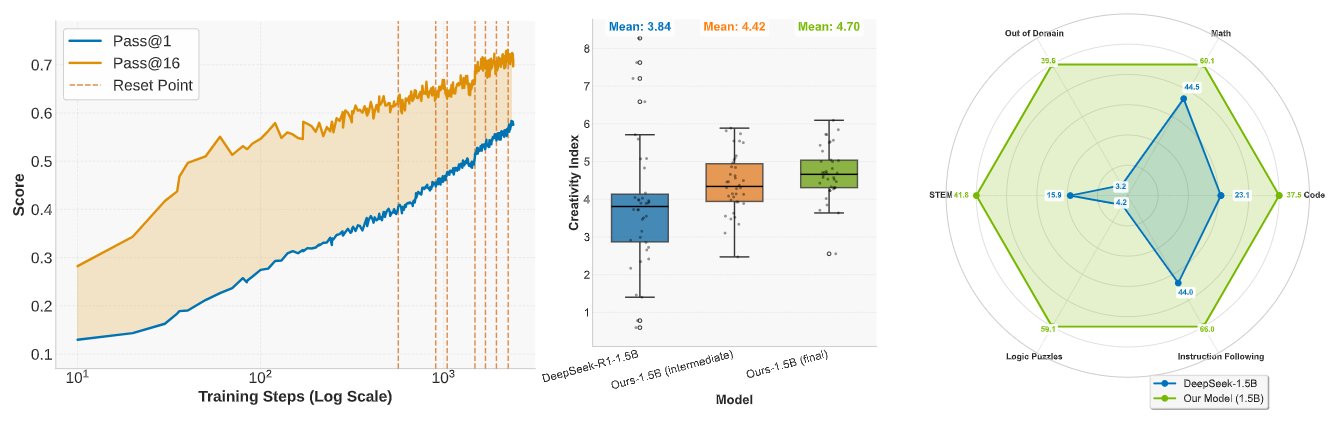
ProRL: Long-Horizon Reinforcement Learning Unlocks New LLM Reasoning
By
–
ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models This paper introduces ProRL, a method that uses long-horizon reinforcement learning to unlock new reasoning strategies in LLMs—strategies that base models cannot access, even with
-

Negative Reinforcement Improves LLM Reasoning Without Explicit Rewards
By
–
The Surprising Effectiveness of Negative Reinforcement in LLM Reasoning This paper shows that punishing incorrect answers—without explicitly rewarding correct ones—can be surprisingly effective for improving reasoning in large language models trained via reinforcement learning