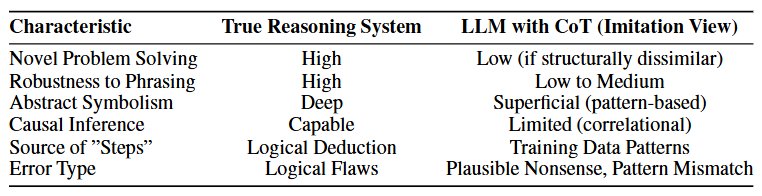
CoT is Not True Reasoning, It Is Just a Tight Constraint to Imitate: A Theory Perspective This paper challenges the idea that Chain-of-Thought (CoT) prompting enables true reasoning in LLMs, arguing instead that CoT acts as a structural constraint that guides models to imitate
RESEARCH
-
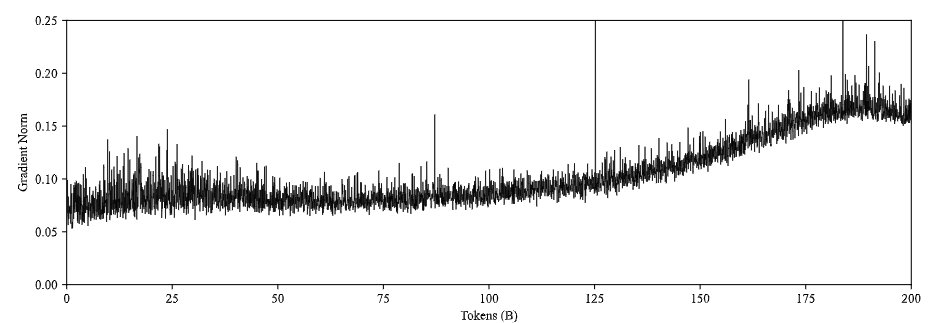
Gradient Surge in LLM Training: Weight Decay and Normalization
By
–
Why Gradients Rapidly Increase Near the End of Training This note investigates a sudden rise in gradient norms during the late stages of LLM training and identifies a surprising cause: the interplay between weight decay, normalization layers, and scheduled learning rate decay.
-
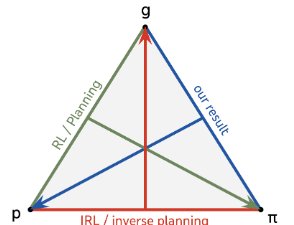
General agents require world models for reliable task completion
By
–
General agents need world models This paper proves that any general agent capable of reliably completing diverse, goal-directed tasks must implicitly learn a predictive model of its environment—challenging the notion that model-free learning is sufficient for general
-

High-Entropy Tokens Drive LLM Reasoning via Reinforcement Learning
By
–
Beyond the 80/20 Rule: High-Entropy Minority Tokens Drive Effective Reinforcement Learning for LLM Reasoning This paper investigates how a small subset of high-entropy tokens—termed "forking tokens"—drives the performance of reinforcement learning with verifiable rewards (RLVR)
-
Autonomous AI: Evolution Without Human Intervention
By
–
Et si une IA pouvait s’auto-modifier, se corriger, évoluer… sans aucune intervention humaine ? C’est l’idée radicale explorée par Sakana AI : une machine qui code sa propre évolution.
— VISION IA (@vision_ia) 9 juin 2025
Forget fine-tuning — bienvenue dans l’ère des IA autonomes. pic.twitter.com/iFYt74mDygWhat if an AI could self-modify, self-correct, and evolve—without any human intervention? That’s the radical idea explored by Sakana AI: a machine that codes its own evolution. Forget fine-tuning—welcome to the era of autonomous AI.
-
Is Technology an Extension of Human Life?
By
–
Do you think technology is an extension of human life?
-
Input Token Proportionality in Language Model Economics
By
–
no…. they are both proportional to the number of input tokens…
-

Gemini 2.5 Pro Solves Hanoi Tower Problem with Limitations
By
–
Al final me he puesto a replicar también los resultados con los prompts del paper y me he hecho un validador del jueguito de las torres de hanoi.
— Carlos Santana (@DotCSV) 9 juin 2025
Gemini 2.5 Pro con 9 discos lo resuelve sin problema y con 10 ha fallado el primer intento. Pero en ambos casos no abortan la tarea. pic.twitter.com/qvZfdpQ4NpAl final me he puesto a replicar también los resultados con los prompts del paper y me he hecho un validador del jueguito de las torres de hanoi. Gemini 2.5 Pro con 9 discos lo resuelve sin problema y con 10 ha fallado el primer intento. Pero en ambos casos no abortan la tarea.
-
Tiffany Farriss Speaks at UN Open Source Week NYC
By
–
We're excited that our own Tiffany @farriss has been invited to speak at the UN Open Source Week! From June 16-20 in NYC, this event explores how we can use open source to digitally facilitate cooperation and tackle global challenges https://
bit.ly/3FKrpUz #opensource #foss #un -

Statistical Physics Framework for Language Model Reasoning
By
–
A Statistical Physics of Language Model Reasoning Jack David Carson, Amir Reisizadeh: https://
arxiv.org/abs/2506.04374 #ArtificialIntelligence #DeepLearning #MachineLearning