
It is remarkable that a committee of deliberating AI models can diagnose patients, propose the next tests, use the results of the tests to improve the diagnosis, order more tests, and eventually arrive at diagnoses, outperforming doctors. It is a specific setting, but nonetheless
RESEARCH
-
Microsoft AI System Diagnoses Patients 4x Better Than Doctors
By
–
Microsoft Says Its New #AI System Diagnosed Patients 4 Times More Accurately Than Human Doctors #RiseoftheRobots
-
The Godfather of AI: Emerging New AI Species Phenomenon
By
–
The Godfather of AI: A New Species Is Emerging — And We Can’t Stop It | … https://
youtu.be/Sb_zlOtmrdM?si
=6RyMi4_FqmQso_vJ
… via @YouTube -

BLIP3-o: Salesforce’s New Unified Multimodal AI Model
By
–
Introducing BLIP3-o: The Unified Multimodal Model BLIP3-o is pushing multimodal AI into a new era. From image captioning to visual question answering, this fully open-source model family from Salesforce AI bridges text and vision like never before. With 4B and 8B parameter
-
Generative AI Optimizes Robot Design Through Simulation
By
–
Could generative AI improve how robots perform?
— MIT CSAIL (@MIT_CSAIL) 30 juin 2025
MIT method uses genAI to refine specific parts of a robot blueprint & tests new 3D designs in simulation. It created a machine that out-jumped & landed more consistently than a human-designed robot: https://t.co/uMzvEFXP8U pic.twitter.com/4BZ4LLYaL6Could generative AI improve how robots perform? MIT method uses genAI to refine specific parts of a robot blueprint & tests new 3D designs in simulation. It created a machine that out-jumped & landed more consistently than a human-designed robot: https://
tinyurl.com/r84k4muw -

Master’s Research on Convolutional Networks Interpretability Journey
By
–
Three years ago, I was wrapping up my Master’s thesis: two years of research on convolutional networks’ interpretability. Back then, I was deep in both writing and research, crafting thesis drafts while also scripting YouTube videos to explain research papers. I lived in
-
HopeLLM: LangGraph Agent for Patient Journey Summarization in Healthcare
By
–
In healthcare, every decision must be grounded in accuracy and trust. @cityofhope — a national medical center specializing in cancer care and diabetes — developed HopeLLM to help with just that.
— LangChain (@LangChain) 30 juin 2025
HopeLLM is a LangGraph-powered agent designed to help summarize patient journeys for… pic.twitter.com/U9qDVfjCIDIn healthcare, every decision must be grounded in accuracy and trust. @cityofhope — a national medical center specializing in cancer care and diabetes — developed HopeLLM to help with just that. HopeLLM is a LangGraph-powered agent designed to help summarize patient journeys for
-
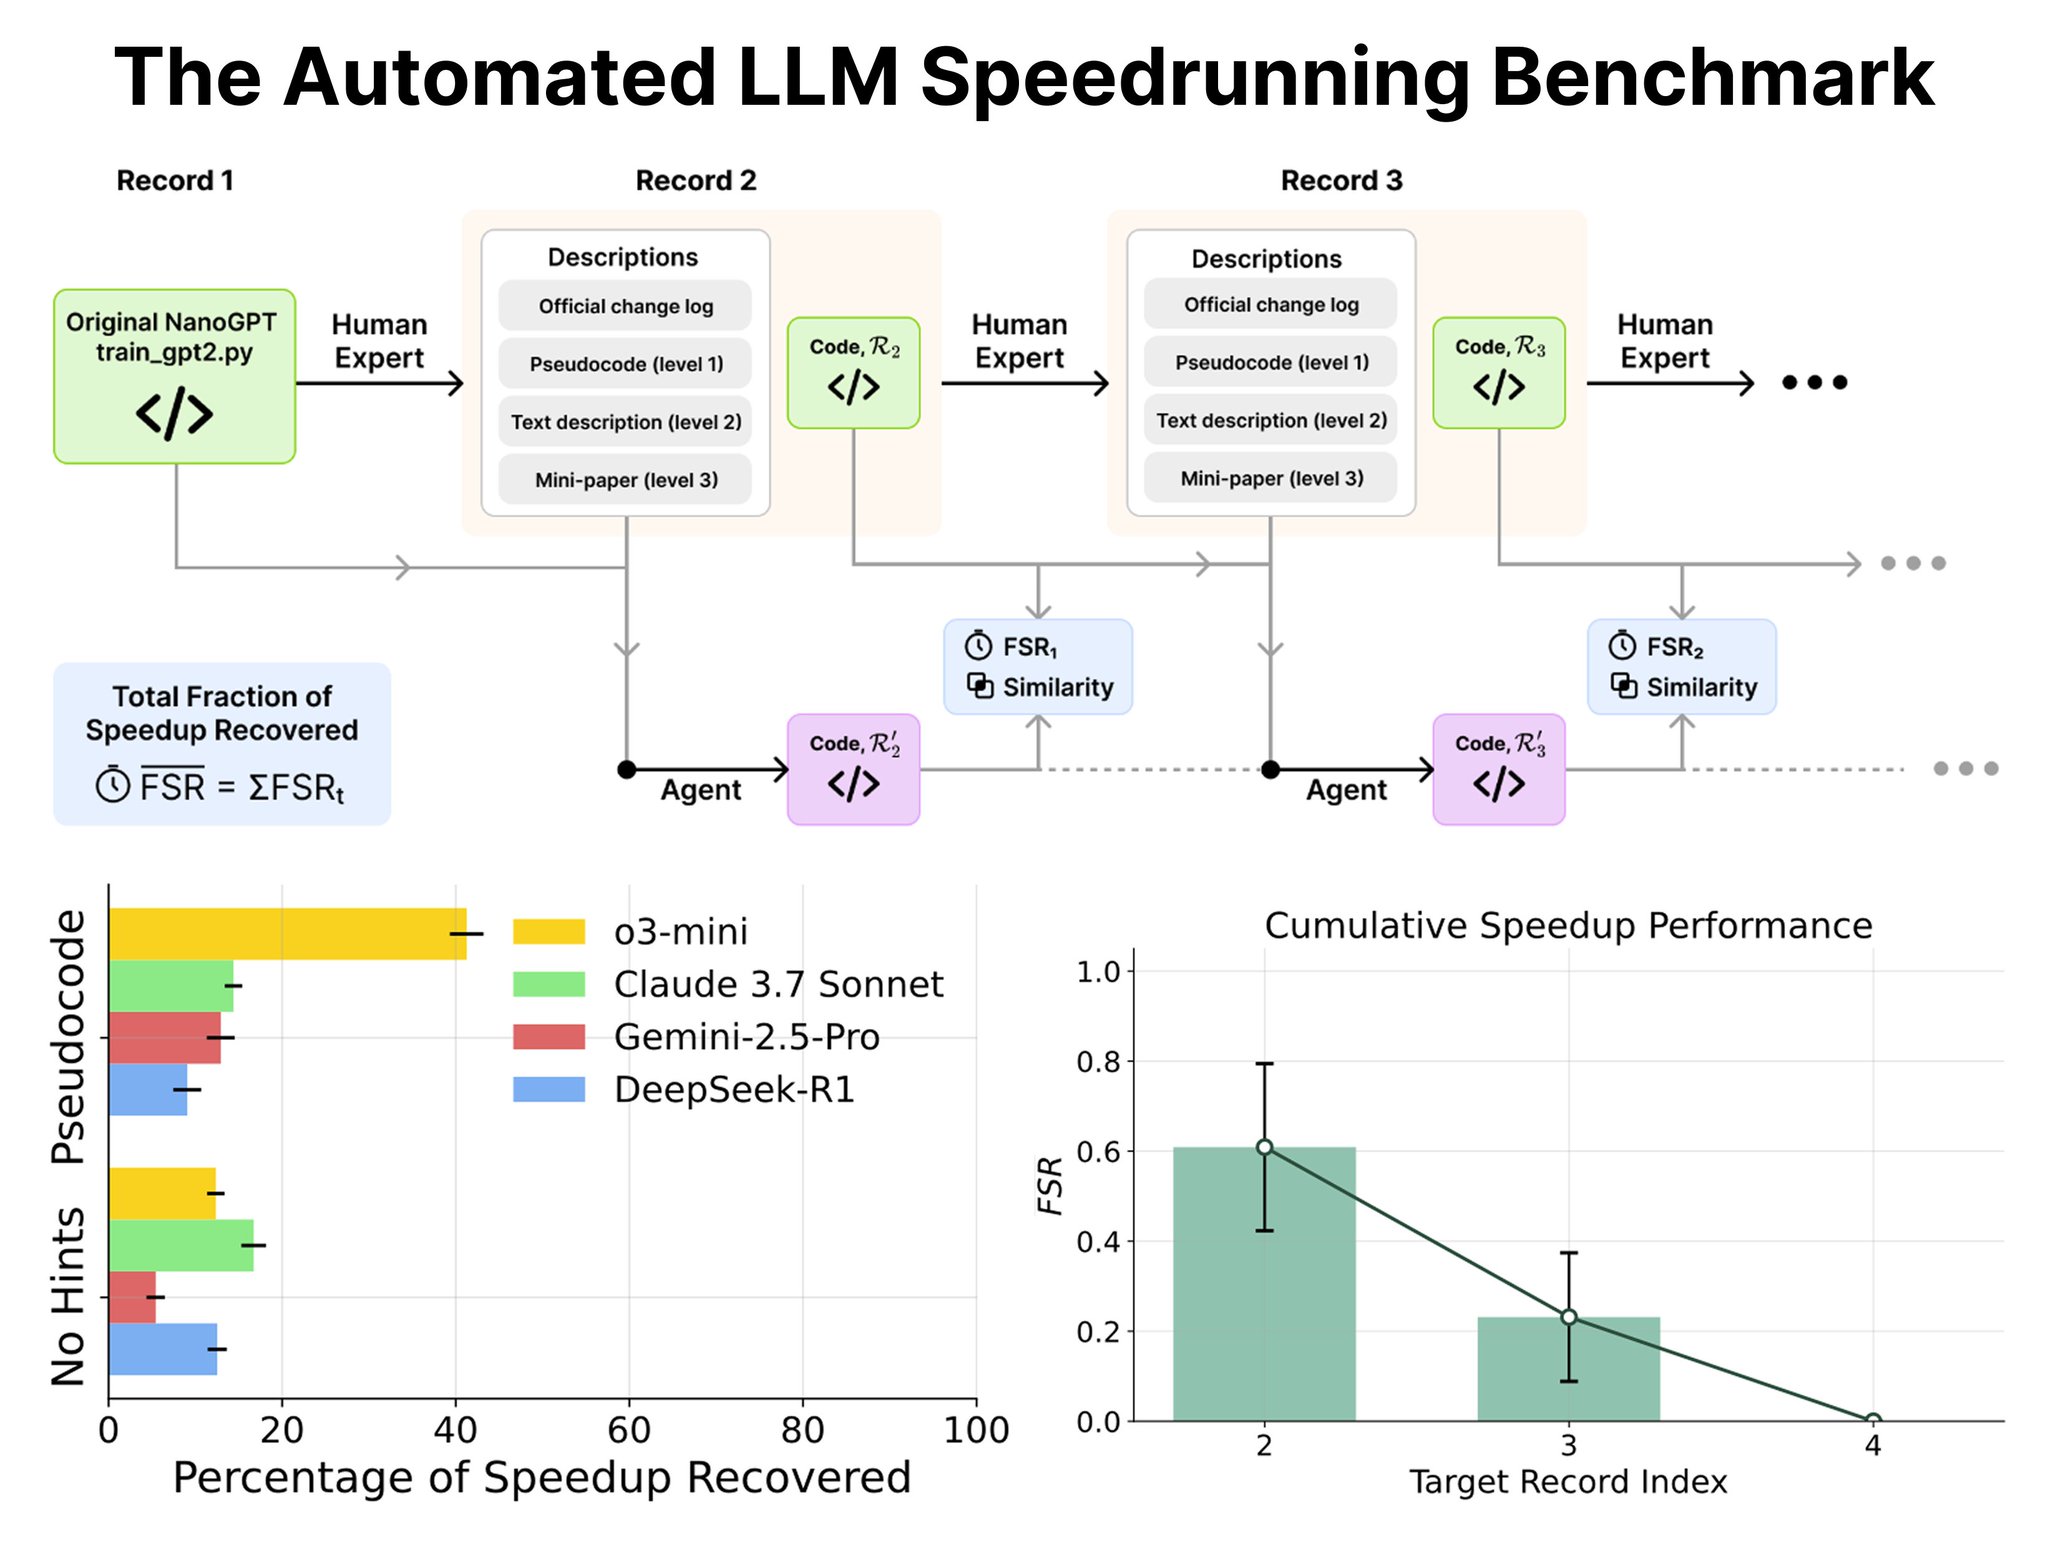
nanoGPT: From Teaching Tool to Self-Improvement Benchmark
By
–
Love this project: nanoGPT -> recursive self-improvement benchmark. Good old nanoGPT keeps on giving and surprising 🙂 – First I wrote it as a small little repo to teach people the basics of training GPTs.
– Then it became a target and baseline for my port to direct C/CUDA -

ChatGPT o3 Solves Movie Recognition Task with Extended Thinking
By
–
Wow. 40 seconds of ChatGPT o3 correctly guessing four movies based solely on 8 scene slices.
— Allie K. Miller (@alliekmiller) 30 juin 2025
Each one solved in 30 seconds of thinking.
The fifth one, however… pic.twitter.com/X6ispDNrfhWow. 40 seconds of ChatGPT o3 correctly guessing four movies based solely on 8 scene slices. Each one solved in 30 seconds of thinking. The fifth one, however…
-

ChatGPT o3 Fails Movie Task Despite 15x Processing Time
By
–
ChatGPT o3 takes 7.5 minutes to do the exact same movie task.
— Allie K. Miller (@alliekmiller) 30 juin 2025
Same code to split it into 8 slices, same relative reasoning process (image by image), but this took 15x longer…
AND ChatGPT fails and gets it wrong.
Testing AI is important – behavior is not only use… pic.twitter.com/GRsgN3IOrHChatGPT o3 takes 7.5 minutes to do the exact same movie task. Same code to split it into 8 slices, same relative reasoning process (image by image), but this took 15x longer… AND ChatGPT fails and gets it wrong. Testing AI is important – behavior is not only use