
Our third agent was developed for the Claude 4 alignment assessment. It red-teams LLMs for concerning behaviors by having hundreds of probing conversations in parallel. We find the agent uncovers 7/10 behaviors implanted into test models.
RESEARCH
-

AI Agent Creates Behavioral Model Evaluations Successfully
By
–
Our second agent builds behavioral evaluations: tests of how often a target model exhibits a specific behavior (like sycophancy). Our agent designs, codes, runs, and analyzes evals. They consistently work: 88% of our agent’s evals measure what they’re supposed to.
-

RLVR Models Sacrifice Diversity for Base Model Preferences
By
–
RLVR'd model would fail to answer questions that its base model previously could. "The Invisible Leash: Why RLVR May Not Escape Its Origin" This research shows that RLVR just boosts the base model’s favorite answers (raising pass@1) and would sacrifice diversity.
-

Databricks Free Edition: Learn AI, Data, and ML Technologies
By
–
Learn and explore on the latest data and AI technologies for free with Databricks Free Edition. Users can experiment with the full range of use cases — from building AI agents to collaborating on DS/ML projects to analyzing data with SQL — on the same platform used by
-
Dynamic Few Shot Prompting to Prevent Agent Overfitting
By
–
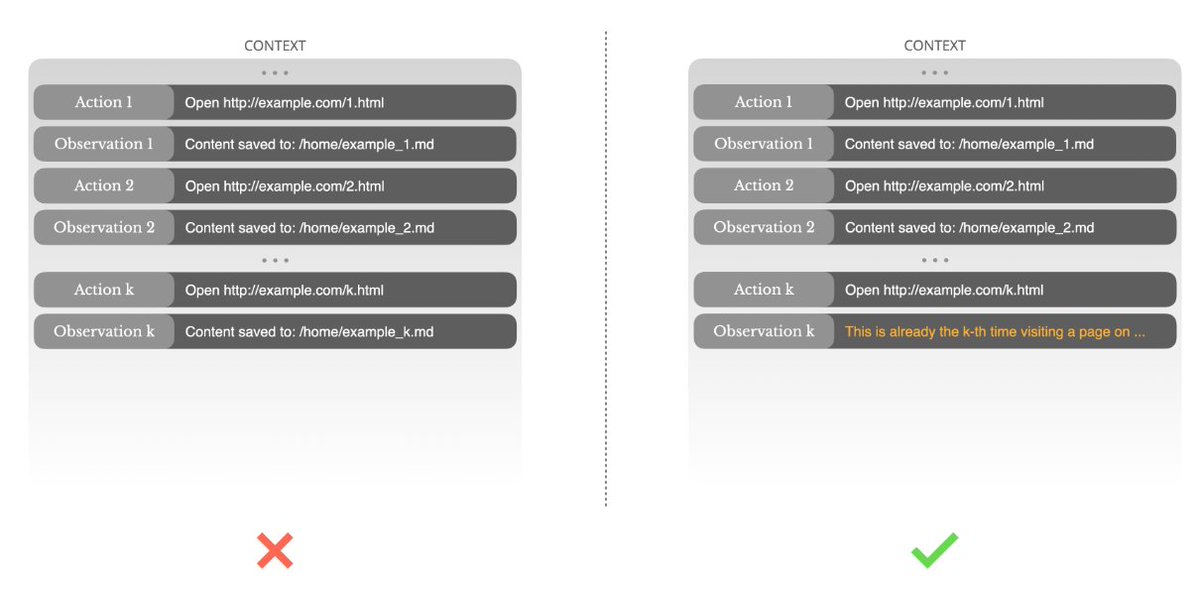
3. Dynamic few shot prompting They cautioned against using traditional few shot prompting for agents. Seeing the same few examples repeatedly will cause the agent to overfit to these examples. Ex: if you ask the agent to process a batch of 20 resumes, and one example in the prompt visits the job description, the agent might visit the same job description 20 times for these 20 resumes. Their solution is to introduce small structured variations each time an example is used: different phrasing, minor noise in formatting, etc. [Translated from EN to English]
-
Context Engineering: Reversible Compact Summaries for Memory Management
By
–
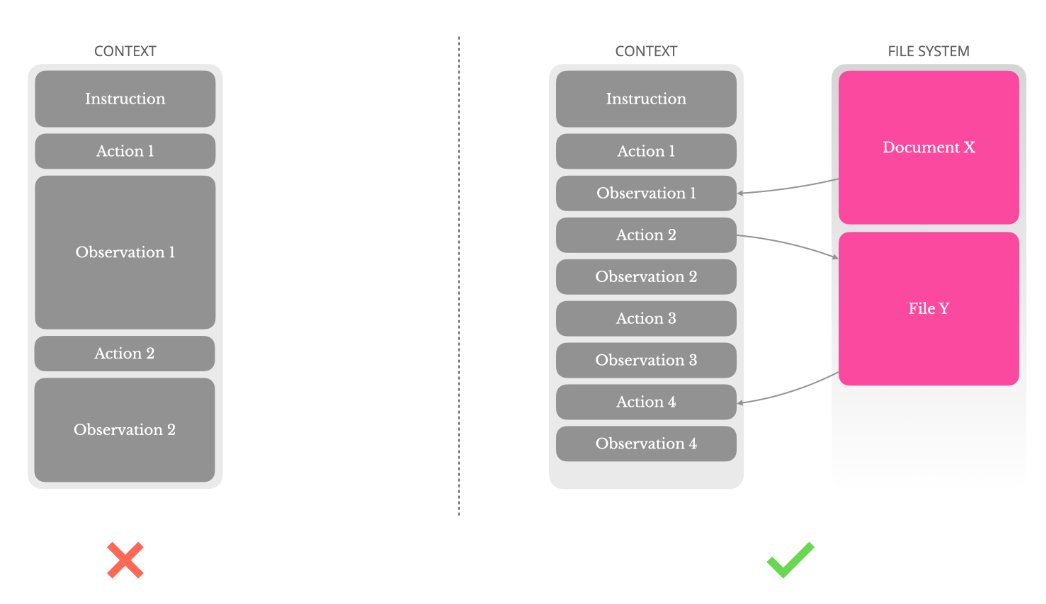
Very useful tips on tool use and memory from Manus's context engineering blog post. Key takeaways. 1. Reversible compact summary Most models allow 128K context, which can easily fill up after a few turns when working with data like PDFs or web pages. When the context gets full, they have to compact it. It’s important to compact the context so that it’s reversible. Eg, removing the content of a file/web page if the path/URL is kept.
-

Ingestible Pill Innovation Monitors Gut Inflammation
By
–
A simple ingestible pill innovation for monitoring inflammation of the gut https://
cell.com/device/fulltex
t/S2666-9986(25)00178-4?_returnURL=httpslinkinghub.elsevier.comretrievepiiS2666998625001784showalltrue
… -
Economics of superintelligence raises concerns about AI benefits
By
–
It doesn't make superintelligence look good 😉 https://
economist.com/leaders/2025/0
7/24/the-economics-of-superintelligence
… -

Kimi K2: Open-Source Trillion-Parameter MoE Model Released
By
–
Kimi K2 = Hype or Not?
— Louis-François Bouchard 🎥🤖 (@Whats_AI) 24 juillet 2025
It is the first open‑source trillion‑parameter MoE model
• 1 T total / 32 B active parameters → giant yet efficient
• Outscores GPT‑4.1 & Claude‑4 (65.8 % SWE‑Bench, 53.7 % LiveCodeBench)
• 128 k context, MIT‑licensed, no vision implemented…… pic.twitter.com/tiouZDLCScKimi K2 = Hype or Not? It is the first open‑source trillion‑parameter MoE model • 1 T total / 32 B active parameters → giant yet efficient
• Outscores GPT‑4.1 & Claude‑4 (65.8 % SWE‑Bench, 53.7 % LiveCodeBench)
• 128 k context, MIT‑licensed, no vision implemented… -
Humanity’s Last Exam Benchmark Flawed AI Measurement Concerns
By
–
This is bad for AI measurement. As other AI benchmarks have become saturated, model makers have turned to Humanity’s Last Exam as a good measure of AI ability. Except a careful review suggests many of the exam questions have incorrect “right” answers. Benchmarking is hard.