
The new Kimi K2 snapshot is here! Kimi-K2-0905 brings a 256k context window (double the previous version), enhanced coding and math skills, and overall performance improvements. (1/2)
RESEARCH
-
Model Evaluation: Testing AI Bias in Self-Assessment Rankings
By
–
I love doing this actually :). I think it's a pretty powerful eval too. Have all models generate something, then put it all together and give it back to all of them and ask them to rank all outputs. I thought models might have a bias to prefer their own outputs, but this doesn't
-

AI and Physics: Deep Connections Explored at Princeton IAS
By
–
Talking of physics, I recently visited the hallowed @the_IAS at Princeton, and had a really fun conversation with Director David Nirenberg about AI, science, & the deep connection between physics & information. I also got to work in Einstein's office, which was beyond inspiring!
-
Data Quality Over Model Size: Enterprise AI Strategy
By
–
Bigger models ≠ better AI.
Better data = better AI. The future belongs to enterprises that can rapidly create, customize & evaluate their data. Snorkel co-founder Braden Hancock explains: https://
youtube.com/watch?v=27Dbq2
ykyko
… #AI #LLMs #DataCentricAI -

Qwen3-Max-Preview Release Announced
By
–

BREAKING : Qwen got a big Qwen3-Max-Preview release. Now available via Qwen Chat & Alibaba Cloud API. Open models are conquering the space
-

LLMs Struggle with PhD-Level Dynamic Programming Problems
By
–
Are LLMs truly capable of “PhD level” reasoning? FormulaOne: Measuring the Depth of Algorithmic Reasoning Beyond Competitive Programming Evaluated through PhD-level Dynamic Programming problems, and spoiler alert, AI code-solvers are only able to get under 1% right (for now…?)
-
Community-Sourced AI Evaluations: Weval Project Calls for Experts
By
–
A friend recently share a project called Weval (community-sourced evals) that I found very interesting. There is a big call for subject matter experts to weigh in on meaningful evals in their field. If you’re frustrated by AI not working for you or your field, this is a great
-
Why AI Evaluations Matter: Building Better Feedback Loops
By
–
Why AI evals matter and why I believe most of the tweets are getting it wrong. We need a better feedback loop in AI. It’s how we measure success, it’s how we measure doom, it’s how we improve, it’s how we rally around goals… it’s a lot. In short: we need to know what good
-
AI Doomsday Machine Reality Check and Politico Narrative
By
–
I am totally disappointed that Politico would spin things to fit a doomer narrative like this. But read the article and form your own opinion: The AI Doomsday Machine Is Closer to Reality Than You Think
-
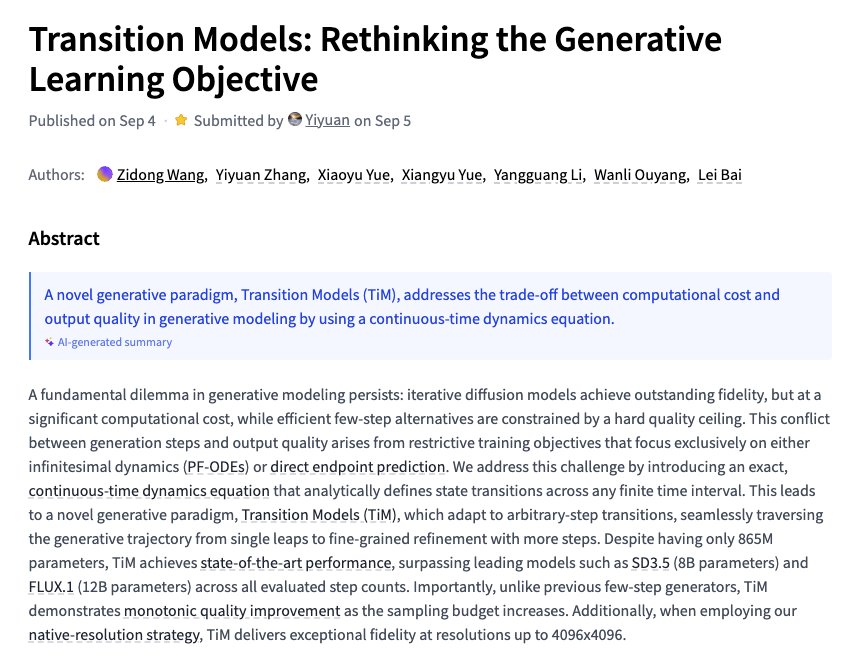
Transition Models: Rethinking the Generative Learning Objective
By
–
Transition Models Rethinking the Generative Learning Objective