One more comment is that giving this image to an AI and asking about it is not sufficient to show the diff because it's all over the training data by now. You'd have to use a new, very recent image, taken yesterday or something. But it doesn't super matter, even if it didn't work
RESEARCH
-
Pretraining and Finetuning Outperform Algorithm Discovery in AI
By
–
AI has crushed it since this post way beyond expectation. I made the same category of mistake all of AI was making, of thinking we have to discover and write the algorithm. You don't. You pretrain and then finetune a BIG neural network on lots of tasks and it just falls out. lol.
-

ChatGPT launches Shopping Research: AI agent test and explanation
By
–
#ChatGPT just launched Shopping Research, an AI Agent that shops for you. What is it and how does it work? Here is my test and detailed explanation → https://youtu.be/z8i3iuX-Me4 #ChatGPT5 #GPT5 #Ecommerce
-

Building Multi-Agent Systems with Vision Capabilities
By
–
LLMs can't see. How can we build effective multi-agent systems with vision capabilities? Building multimodal models from scratch is expensive. Training joint vision-language architectures requires massive compute, specialized datasets, and careful optimization. But there's
-

Grok 4.1 Thinking ranks #2, Grok 4.1 #3 on LMArena; #1 by Jan?
By
–
Grok 4.1 Thinking claims the top 2 spot on the LMArena text leaderboard (preliminary), with Grok 4.1 following with the top 3. Top 1 by Jan?
-
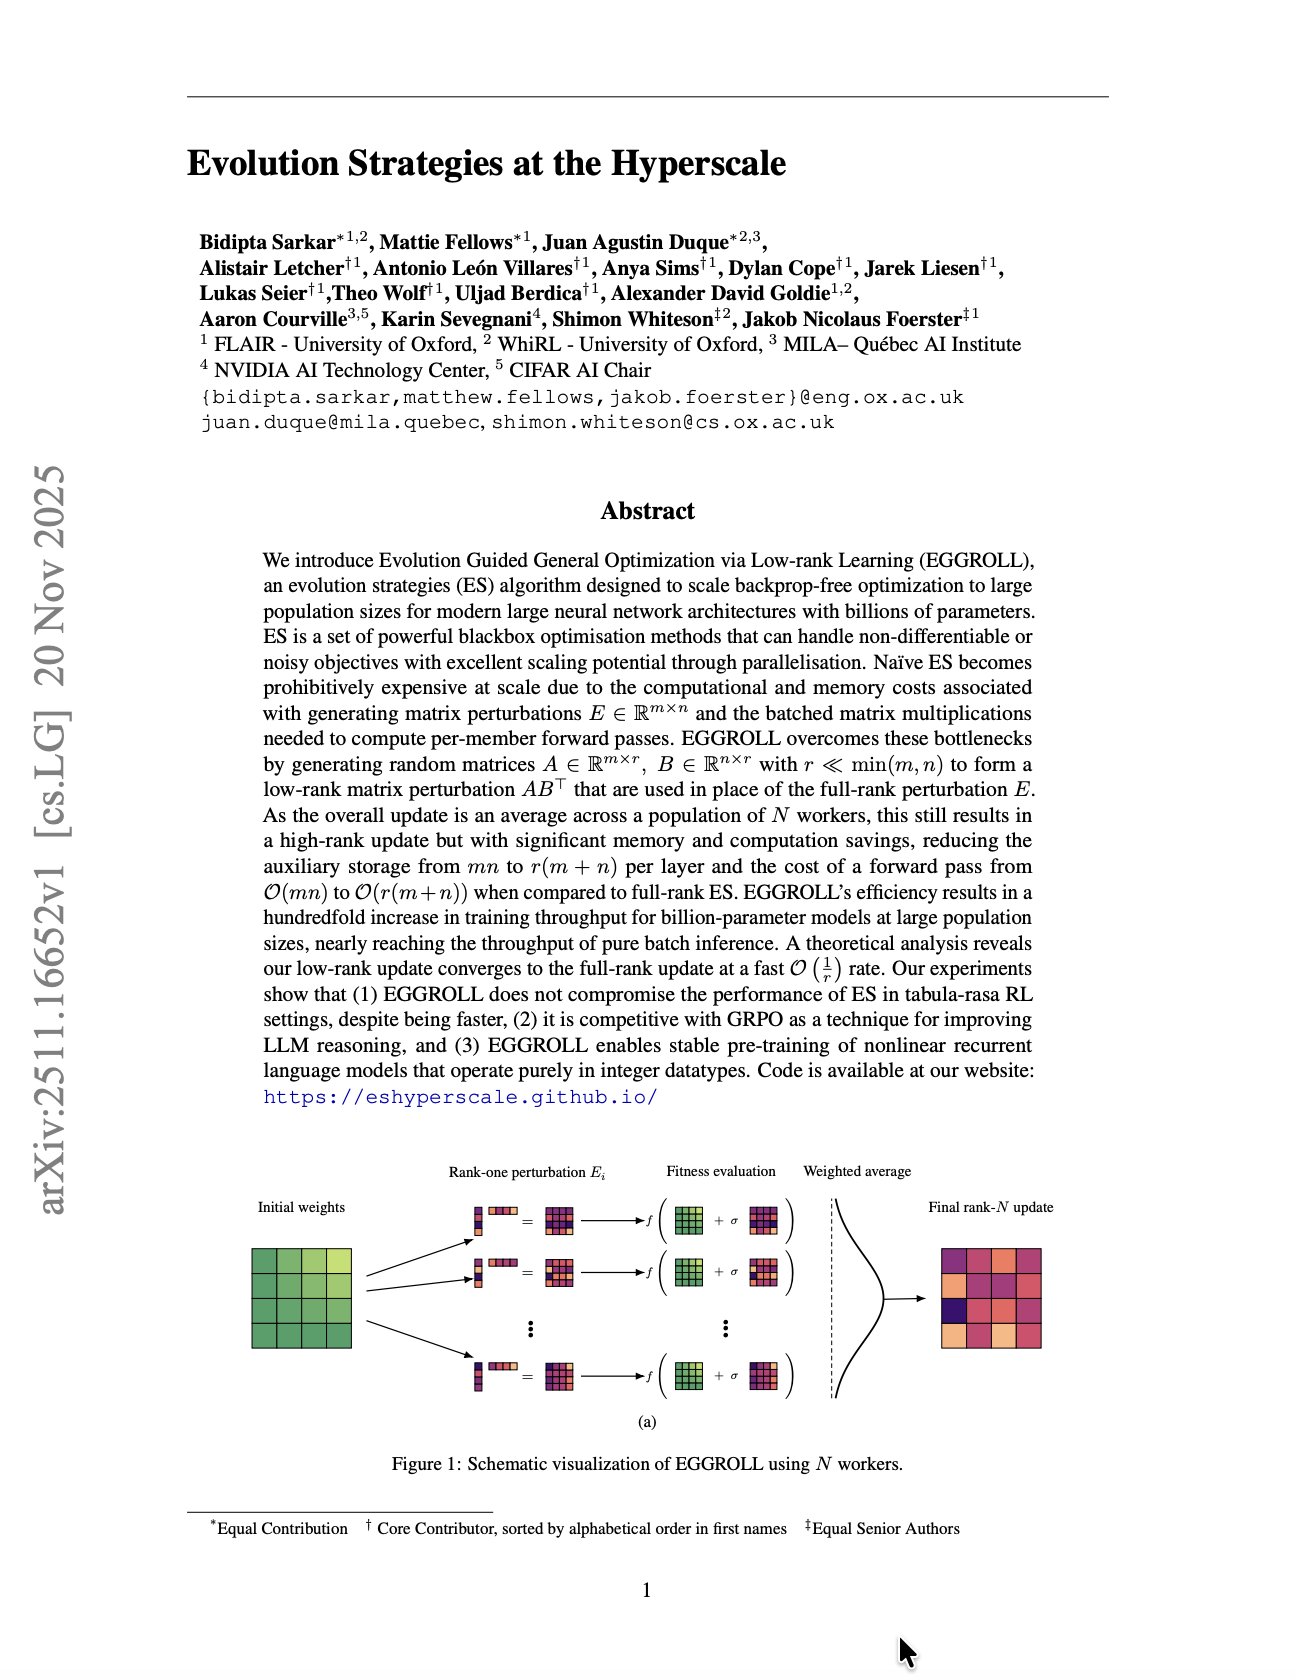
Evolution Strategies at Hyperscale: Deep Learning Optimization
By
–
Evolution Strategies at the Hyperscale Sarkar et al.: https://
arxiv.org/abs/2511.16652 #ArtificialIntelligence #DeepLearning #MachineLearning -
TMLR’s New Publication Approach Gains Community Support
By
–
Very much looking forward to see how our community leverages this new approach to publications.
— Hugo Larochelle (@hugo_larochelle) 25 novembre 2025
And a big thank you to Paul, for leading the charge on this latest TMLR experimentation! https://t.co/Kx3Q7ZlPusVery much looking forward to see how our community leverages this new approach to publications. And a big thank you to Paul, for leading the charge on this latest TMLR experimentation!
-
VLM Benchmarking for Long Horizon Robotic Household Tasks
By
–
Our most recent work that benchmarks modern VLM and their efficacy for long horizon household activities in robotic learning, using BEHAVIOR benchmark environment.👇 https://t.co/8Ibx8IA7MW
— Fei-Fei Li (@drfeifei) 25 novembre 2025Our most recent work that benchmarks modern VLM and their efficacy for long horizon household activities in robotic learning, using BEHAVIOR benchmark environment.
-

Oriol Vinyals receives Doctor Honoris Causa from UPC Barcelona
By
–
On my way to Barcelona to receive a Doctor Honoris Causa from my alma mater, @la_UPC. Truly honored! 🎓 Join Thursday for my Master Class, "From AI to AGI: The Quest for True Intelligence." Hope to see you there! telecos.upc.edu/ca/esdevenim… "Create an image at 41.4036° N, 2.1744° E, January 1st, 1983, 15:00 hours."
→ View original post on X — @oriolvinyalsml, 2025-11-25 14:59 UTC
-
Gemini 4 Significantly Better Than Gemini 3: Performance Verdict
By
–
My verdict is that it's significantly better than Gemini 3. It's at least as smart and just got more polish to it. Alignment on little details also significantly higher. Gemini 3 gets many things mixed up after a half-dozen messages, and completely confused after compaction.