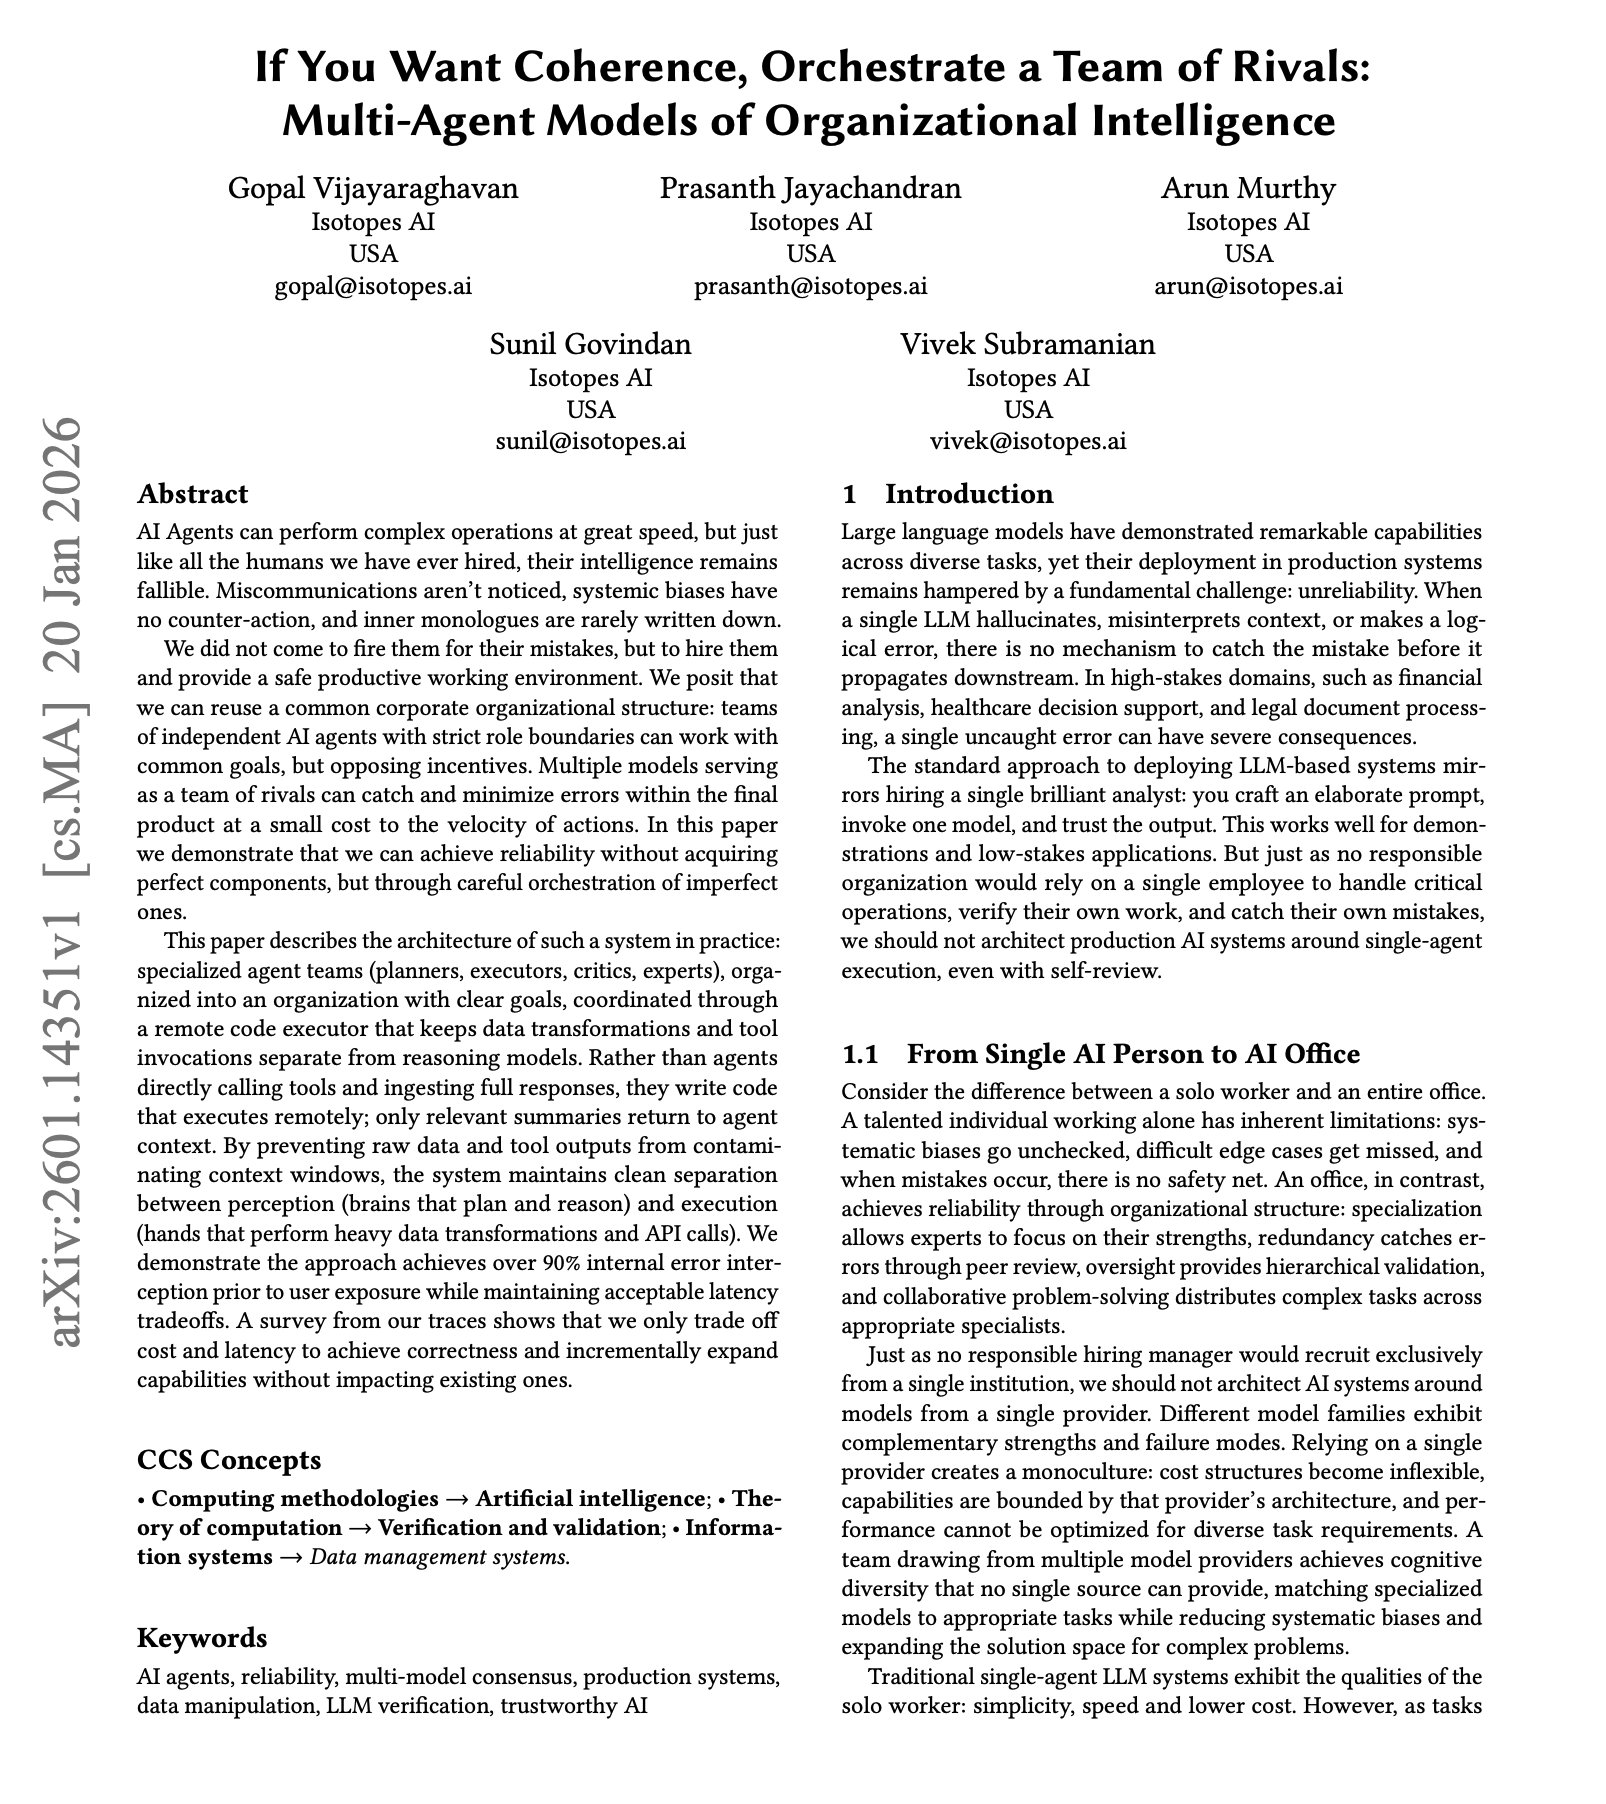
Nice paper discussing how to design good multi-agent systems. Single-agent systems have no safety net. The same entity that makes mistakes is the one evaluating whether mistakes were made. Self-review shares the blind spots of the original reasoning. We've mostly relied on
RESEARCH
-

Fine-Tuning Video Models for Visuomotor Robot Control
By
–
"Fine-Tuning Models for Visuomotor Control and Planning" This paper proposes Cosmos Policy, showing a pretrained latent video diffusion model (Cosmos-Predict2) can be adapted into a SoTA robot policy via a single post-training stage on robot demonstrations, without
-

Early Grok 4.20 checkpoint achieves +10% gain on Prediction Arena
By
–


An early Grok 4.20 checkpoint has been spotted on Prediction Arena, achieving +10% gain after a 2 weeks long round. Soon?
-
Google DeepMind Unveils AI Film Creation Tools at Sundance
By
–
Our animated short film "Dear Upstairs Neighbors" is previewing today at @sundancefest! In creating this film, our @GoogleDeepMind team of Pixar alumni, an Academy Award winner, researchers, and engineers designed new AI capabilities specifically for filmmakers.
— Google AI (@GoogleAI) 26 janvier 2026
Here’s how these… pic.twitter.com/GBOL1vCdNYOur animated short film "Dear Upstairs Neighbors" is previewing today at @sundancefest
! In creating this film, our @GoogleDeepMind team of Pixar alumni, an Academy Award winner, researchers, and engineers designed new AI capabilities specifically for filmmakers. Here’s how these -
Understanding Comprehension Debt in LLM Development
By
–
Love the word "comprehension debt", haven't encountered it so far, it's very accurate. It's so very tempting to just move on when the LLM one-shotted something that seems to work ok.
-
Yi Tay leads DeepMind’s reasoning breakthrough with on-policy RL
By
–
From pre-training breakthroughs to leading reasoning + RL work inside Google DeepMind’s Gemini org, Yi Tay has had a front-row seat to how modern LLMs evolved from “scale + objectives” into the on-policy RL era powering today’s reasoning leap. Now he's helping assemble DeepMind’s… pic.twitter.com/JRxIhp0kYg
— Latent.Space (@latentspacepod) 26 janvier 2026From pre-training breakthroughs to leading reasoning + RL work inside Google DeepMind’s Gemini org, Yi Tay has had a front-row seat to how modern LLMs evolved from “scale + objectives” into the on-policy RL era powering today’s reasoning leap. Now he's helping assemble DeepMind’s
-
Anthropic-Led Research on AI Model Improvement Published
By
–
This research was led by Jackson Kaunismaa through the MATS program and supervised by researchers at Anthropic, with additional support from Surge AI and Scale AI. Read the full paper: https://
arxiv.org/pdf/2601.13528 -

Frontier Model Training Enables More Capable Dangerous Open-Source AI
By
–
These attacks scale with frontier model capabilities. Across both OpenAI and Anthropic model families, training on data from newer frontier models produces more capable—and more dangerous—open-source models.
-
High-Sparsity Attention Tuning for Video Diffusion Transformers
By
–
SALAD Achieve High-Sparsity Attention via Efficient Linear Attention Tuning for Diffusion Transformer
-
Jet-RL: On-Policy FP8 Reinforcement Learning with Unified Precision
By
–
Jet-RL Enabling On-Policy FP8 Reinforcement Learning with Unified Training and Rollout Precision Flow