Domino was honored to support the warfighter community at AFCEA West 2026 – and especially proud to convene a standout panel on “Edge AI for Maritime and National Security Superiority: Turning Data into Decision Advantage.” Watch the full panel: https://
domino.buzz/4qKJdjX
RESEARCH
-

Edge AI Maritime Security: Data to Decision Advantage Panel
By
–
-

Sonnet-4.6 Dominates Latest AI Model Benchmarks and Evaluations
By
–
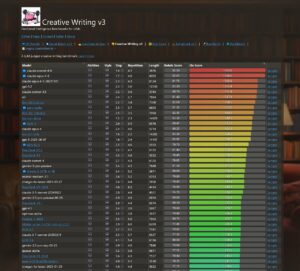

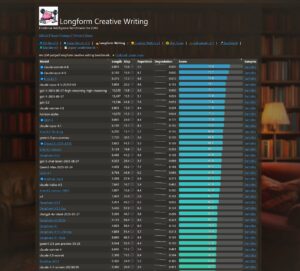
Sonnet-4.6 takes top place on all my evals: EQ-Bench, Creative writing, Longform writing & Judgemark. Opus 4.6 within margin of error. GLM-5 and Qwen3.5-397B nipping at their heels.
→ View original post on X — @maximelabonne, 2026-02-18 21:33 UTC
-
Snorkel Releases Agentic RL Eval Environment and Finance Reasoning Benchmark
By
–
Snorkel contributed: • An agentic RL eval environment • FinQA-Reasoning dataset • Finance Reasoning benchmark Full technical breakdown from the rLLM team + our enterprise takeaways here:
-
Tool Discipline Improves AI Reasoning Better Than Scale
By
–
Key insight: tool discipline > scale. Instead of complex multi-table training, we reinforced reliable tool use on simple queries — and saw transfer to 12-step reasoning tasks (59.7% Pass@1).
-

4B Model Outperforms 235B on Financial Reasoning Tasks
By
–
A 4B model > 235B on financial reasoning. We partnered with @rllm_project to fine-tune Qwen3-4B-Instruct-2507 — and it outperformed Qwen3-235B-A22B on expert-curated financial benchmarks.
-
Quantum interpretations: Copenhagen versus Penrose perspectives illustrated
By
–
contrast this with the copenhagen interpretation or penrose's take and illustrate
-
Quantum Superposition Limited by Physical Laws Universe
By
–
i thought it’s not infinite because most of the possible states are not consistent with the laws of the universe. schrodingers cat can live or die but cannot transport to alpha centauri in a planck second so that state is not part of the superposition?
-

Agentic AI Tools in Software Engineering and Risk Monitoring
By
–
Software engineering makes up ~50% of agentic tool calls on our API, but we see emerging use in other industries. As the frontier of risk and autonomy expands, post-deployment monitoring becomes essential. We encourage other model developers to extend this research.
-

Claude Code Enhances AI Safety Through Uncertainty Recognition
By
–
Claude Code also encourages oversight by stopping to ask questions. On complex tasks, Claude Code pauses for clarification more than twice as often as humans interrupt it. Training models to recognize uncertainty is an important, under-appreciated safety property.
-
Real-world agent deployment: safety implications across contexts
By
–
Agents are already being deployed across contexts that range from e-mail triage to cybersecurity research. Understanding this spectrum is critical for safe deployment, yet we know surprisingly little about how people actually use agents in the real world.