Thanks for this writeup, Sebastian!
RESEARCH
-
Secure Intelligence Institute Publishes Autonomous Agents Security Research
By
–
The first paper from the Secure Intelligence Institute responds to NIST's request for information on securing autonomous agents. Read the paper on arXiv: arxiv.org/abs/2603.12230 [Translated from EN to English]
→ View original post on X — @perplexity_ai, 2026-03-31 17:16 UTC
-

Perplexity Launches Secure Intelligence Institute for Security Research
By
–
Today, we're launching the Secure Intelligence Institute. SII partners with top cryptography, security, and ML teams to advance security research and industry collaboration. It is led by Dr. Ninghui Li at Purdue. perplexity.ai/secure-intelli…
→ View original post on X — @aravsrinivas, 2026-03-31 17:16 UTC
-

Agent Improvement Loop: Tracing as Foundation for Enhancement
By
–
New conceptual guide: The agent improvement loop starts with a trace Tracing is the foundational primitive for improving agents. A trace gives you the full behavioral record of what an agent actually did. From there, teams can enrich traces with evals and human feedback,
-
AI’s Role in Scientific Peer Review: Spotting Gaps, Needing Human Judgment
By
–
Stanford computer scientist @james_y_zou is exploring how AI can accelerate scientific research and peer review. His finding: AI excels at spotting gaps, but judgment calls still need humans. hai.stanford.edu/news/ais-gr…
→ View original post on X — @stanfordhai, 2026-03-31 17:03 UTC
-
Nature Article: Complete Automation of AI Research
By
–
Nature research paper: Towards end-to-end automation of AI research
go.nature.com/4rSOGFK [Translated from EN to English]→ View original post on X — @sakanaailabs, 2026-03-31 16:52 UTC
-
Detecting and Preventing Distillation Attacks in AI Models
By
–
Detecting and preventing distillation attacks \ Anthropic bit.ly/3ORbiJ7 #AI #MachineLearning #DeepLearning #LLMs #DataScience
→ View original post on X — @miketamir, 2026-03-31 16:47 UTC
-
New arXiv Paper and Official Launch of ARC Prize
By
–
arXiv paper: arxiv.org/abs/2603.24621 ARC Prize official page: arcprize.org/blog/arc-agi-3-launch [Translated from EN to English]
→ View original post on X — @aihighlight, 2026-03-31 16:46 UTC
-
Convolutional Networks History and Attribution in AI
By
–
I have read him (a) that’s not true (eg see long history of convnets that precedes him, and (b) he brings receipts. seeya
-
ARC-AGI-3: New Benchmark Reveals AI-Human Gap
By
–
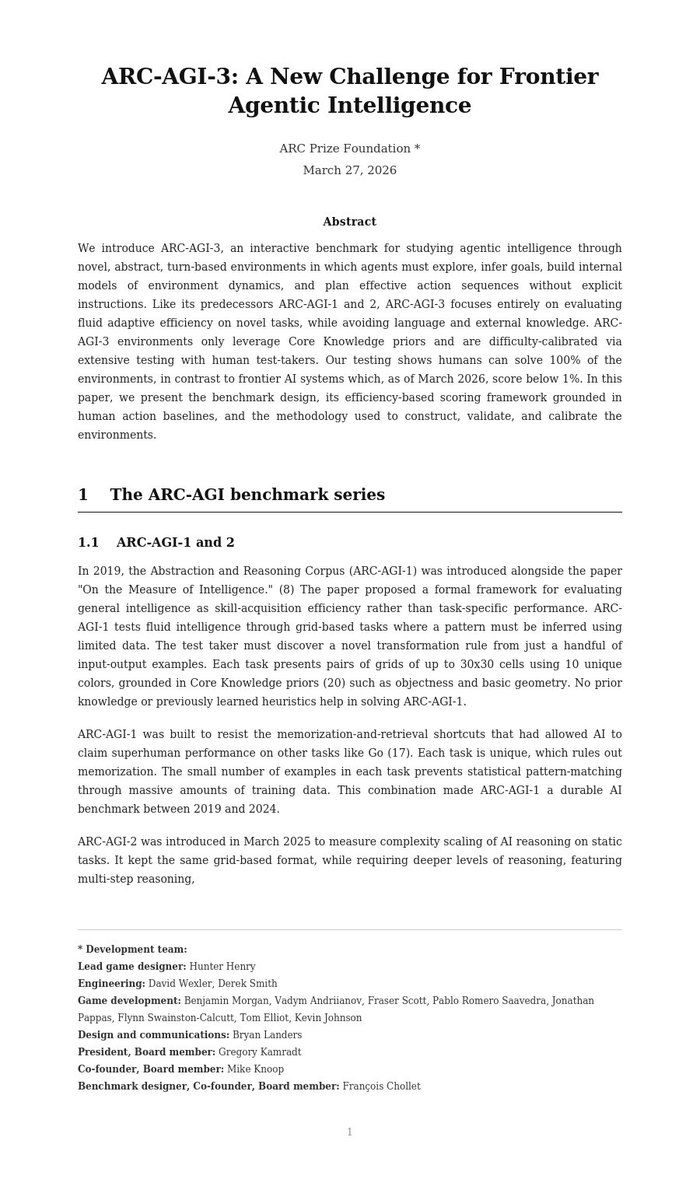
François Chollet just dropped the toughest benchmark that made every frontier AI look lost. ARC-AGI-3. 135 game environments built from scratch by game designers. No instructions, no rules, no stated goal. The AI gets placed inside and has to work out what it is even trying to do. Untrained humans cleared all 135. Every major model landed below 1%. Humans: 100%. Gemini 3.1 Pro: 0.37%. GPT 5.4: 0.26%. Opus 4.6: 0.25%. Grok-4.20: 0.00%. The scoring is built to punish shortcuts. A human solves it in 10 moves, the AI uses 100, the AI gets 1%. Throwing more compute at it makes no difference. For context: ARC-AGI-1 is essentially a solved problem at this point. Gemini scores 98% on it. ARC-AGI-2 went from 3% to 77% in less than a year with labs pouring millions into it. ARC-AGI-3 made all of that progress feel small. Announced live at Y Combinator in a fireside between Chollet and Sam Altman. $2M in prizes on Kaggle. Every winning solution has to be open sourced. Scaling will not fix this. We are not close to AGI. (Find link in the comments) [Translated from EN to English]
→ View original post on X — @aihighlight, 2026-03-31 16:44 UTC