From the replies it is clear there is still no agreement what RAG is, so I guess the truth of my statement depends on your definition of RAG.
RESEARCH
-

Teaching LLMs to Reason Like Bayesians
By
–
Teaching LLMs to reason like Bayesians buff.ly/oZEF0YH #AI #MachineLearning #DeepLearning #LLMs #DataScience
→ View original post on X — @miketamir, 2026-04-03 16:49 UTC
-
Gemma 4 Checkpoints Available on Hugging Face with Apache License
By
–
Thanks for following us!
— Google Gemma (@googlegemma) 3 avril 2026
We're excited to see what you all build with Gemma 4!
In case you missed it, you can find all our checkpoints, with an Apache 2.0 License, on Hugging Face: pic.twitter.com/64t6fSefw4Thanks for following us! We're excited to see what you all build with Gemma 4! In case you missed it, you can find all our checkpoints, with an Apache 2.0 License, on Hugging Face:
→ View original post on X — @huggingface, 2026-04-03 16:43 UTC
-
METR Study Shows Mixed Results on AI Model Capabilities
By
–
most recent, somewhat mixed METR study below (and Claude Code may change things):
-
MultiGen: Level Design for Editable Multiplayer Worlds in Diffusion Engines
By
–
MultiGen
— AK (@_akhaliq) 3 avril 2026
Level-Design for Editable Multiplayer Worlds in Diffusion Game Engines
paper: https://t.co/UT01uUYBxj pic.twitter.com/AMY0bDusAjMultiGen Level-Design for Editable Multiplayer Worlds in Diffusion Game Engines paper: huggingface.co/papers/2603.0…
-
Frozen Data Limitations in LLM Reasoning Systems
By
–
it’s an issue of using frozen data in lieu of reasoning etc
-
Opus Model Performance Degradation Comparison Analysis
By
–
Both models still degrade too much for that to be really useful, though Opus is a bit better at that. For now.
-
LLM Knowledge Bases: Building Personal Research Wiki Systems
By
–
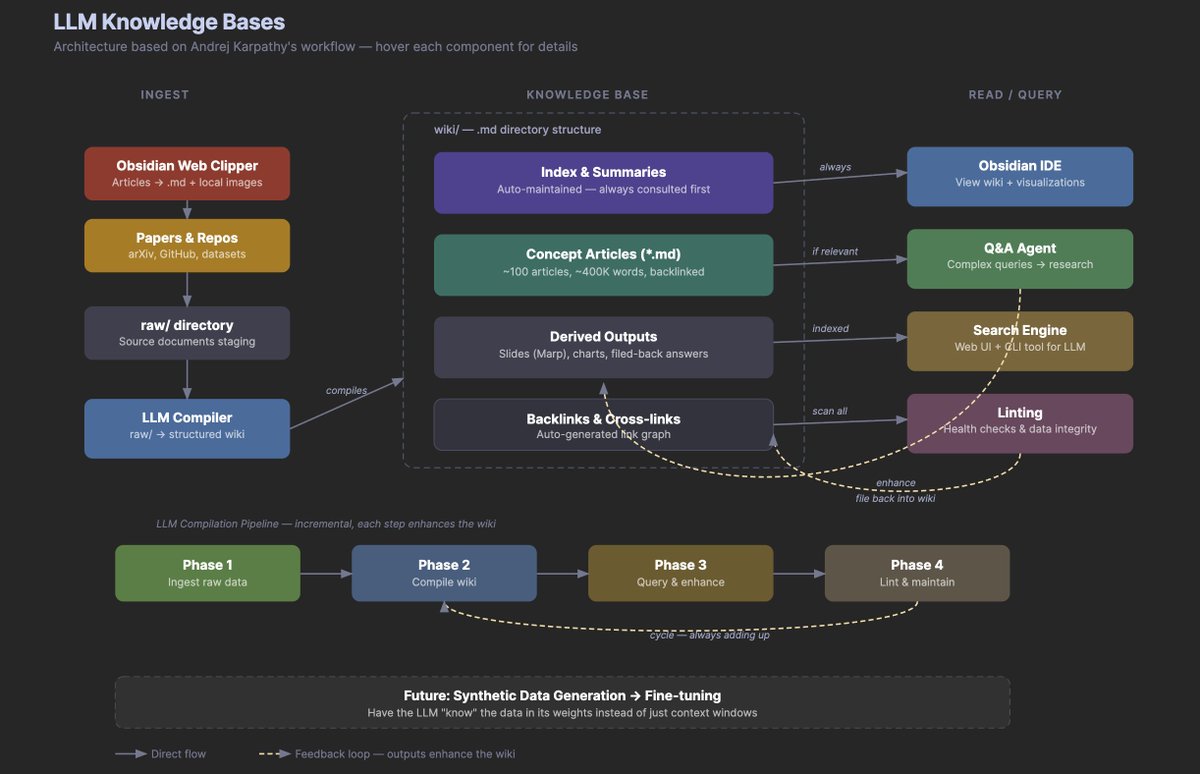
Diagram of the LLM Knowledge Base system. Feed this to your favorite agent and get your own LLM knowledge base going. Andrej Karpathy (@karpathy) LLM Knowledge Bases Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So: Data ingest: I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them. IDE: I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides). Q&A: Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale. Output: Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base. Linting: I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into. Extra tools: I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries. Further explorations: As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows. TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts. — https://nitter.net/karpathy/status/2039805659525644595#m
-
Visual Guide to Gemma 4: Exploring Google DeepMind’s New Models
By
–
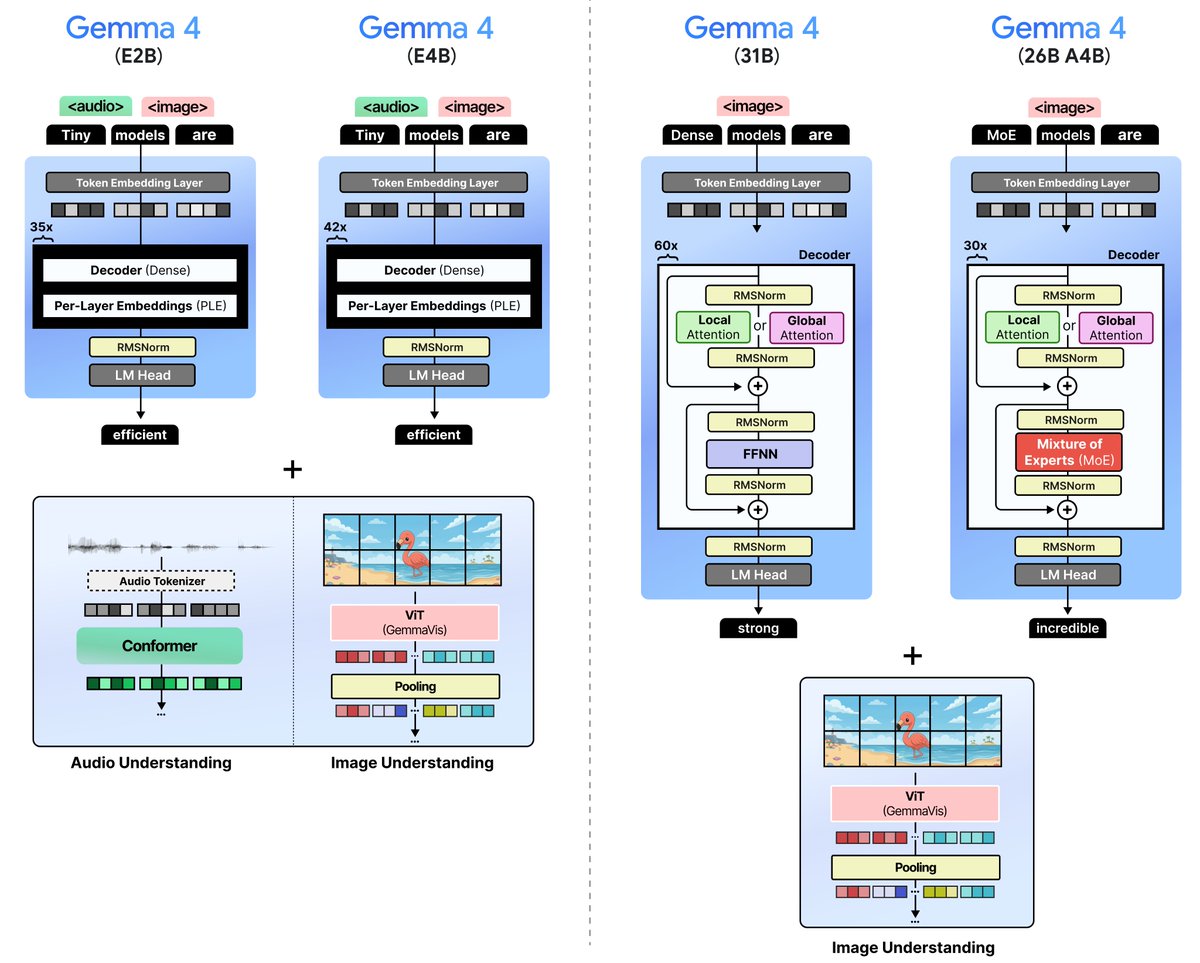
A Visual Guide to Gemma 4 With almost 40 (!) custom visuals, explore the new models from Google DeepMind. We explore various techniques, ranging from Mixture of Experts and the Vision Encoder all the way up to Per-Layer Embeddings and the Audio Encoder. Link below 👇
→ View original post on X — @jeremyphoward, 2026-04-03 16:10 UTC
-
AI Tools May Reduce Coder Productivity Despite User Perception
By
–
Interesting take, consistent with the surprising @METR_Evals study that showed coders using AI tools took a hit on productivity even they imagined otherwise.