So we now have a pretty good picture of the state of the frontier AI model makers. US closed source models continue to lead. Google, OpenAI, and Anthropic stand well ahead of the pack, and may have signs of recursive self-improvement. xAI has fallen from frontier status for now
RESEARCH
-

Matei Zaharia Wins ACM Prize in Computing
By
–
Congratulations to @matei_zaharia on winning this year's ACM Prize in Computing! This is very well-deserved!
-
Amazon Nova 2 trails Sonnet 4.5 and remains in preview
By
–
So what's the deal with Amazon Nova? They released Nova 2 in December, and even then, the top flight Nova 2 model trailed Sonnet 4.5. And it still hasn't left preview.
-
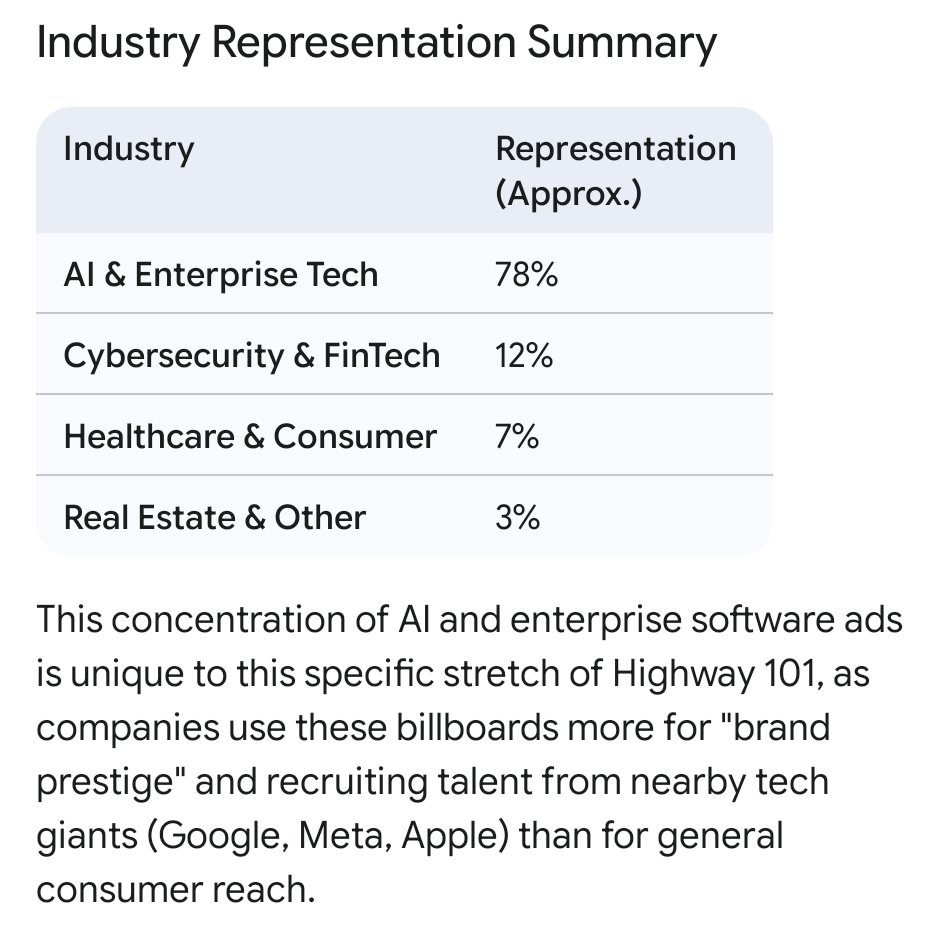
Gemini analyzes billboard advertising industries with AI
By
–
I asked Gemini: "Can you analyze all the billboards listed on https://
101ads.org and give me a report of what industry is represented by the company on each billboard" -
Revela: Efficient AI Retrievers Without Expensive Annotated Datasets
By
–
What if we could train powerful AI retrievers to find specialized information without needing huge, expensive datasets?
— 机器之心 JIQIZHIXIN (@jiqizhixin) 9 avril 2026
A team from TU Darmstadt, University of Washington, CMU, Microsoft, and Tencent AI Lab presents Revela!
Revela leverages self-supervised language modeling. It… pic.twitter.com/bC4emjEYdVWhat if we could train powerful AI retrievers to find specialized information without needing huge, expensive datasets? A team from TU Darmstadt, University of Washington, CMU, Microsoft, and Tencent AI Lab presents Revela! Revela leverages self-supervised language modeling. It teaches retrievers to understand semantic relationships between document segments by predicting "next chunks" of info, integrating retriever similarity scores directly into this learning process. Without any annotated query-document pairs, Revela surpasses larger supervised models and proprietary APIs in code and reasoning-intensive domains. It achieves unsupervised SoTA on general benchmarks with ~1000x less data and 10x less compute! Revela: Dense Retriever Learning via Language Modeling Paper: openreview.net/forum?id=e7pA… Code: github.com/TRUMANCFY/Revela Model: huggingface.co/trumancai/Rev… Our report: mp.weixin.qq.com/s/9TmVSNHMQ… 📬 #PapersAccepted by Jiqizhixin
-
Small AI Model Advancement Outpaces Large Model Development
By
–
Our rate of advancement with the small model has been so fast that the large model has not yet caught up. V15 will be the large model.
-
Digital twin of world created with millimeter accuracy
By
–
They used that data to build a digital twin of the world down to 1 mm accuracy. It is sick
-
8 Types of Visualization Techniques Used in Data Analytics
By
–
8 Types of Visualization Technique Used in #DataAnalytics
— Ronald van Loon (@Ronald_vanLoon) 9 avril 2026
by @Python_Dv
#DataScience #BigData pic.twitter.com/L6oiYaR6n08 Types of Visualization Technique Used in #DataAnalytics by @Python_Dv #DataScience #BigData
-

Multimodal Protein Design Enables DNA-Based Chemistry Encoding
By
–
General Multimodal Protein Design Enables DNA-Encoding of Chemistry Rector-Brooks et al.: https://
arxiv.org/abs/2604.05181 #ArtificialIntelligence #DeepLearning #Chemistry -
AI Designs Multimodal Proteins to Encode Chemistry in DNA
By
–
General Multimodal Protein Design Enables DNA-Encoding of Chemistry
— AGI.Eth (@ceobillionaire) 9 avril 2026
Rector-Brooks et al.: https://t.co/dY9Zho50xY#ArtificialIntelligence #DeepLearning #Chemistry pic.twitter.com/iSwMFXQWHwGeneral Multimodal Protein Design Enables DNA-Encoding of Chemistry Rector-Brooks et al.: arxiv.org/abs/2604.05181 #ArtificialIntelligence #DeepLearning #Chemistry