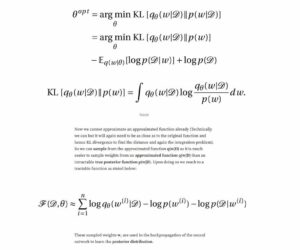
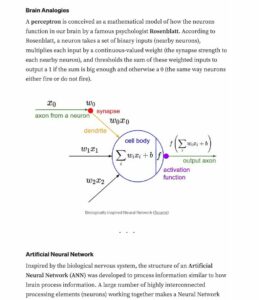
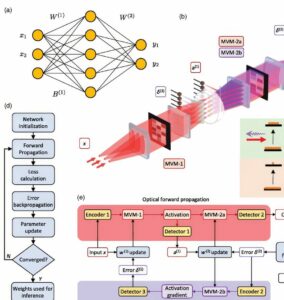
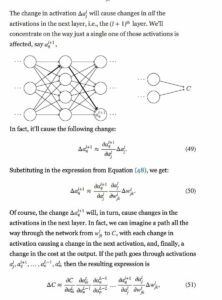
Training Neural Network on Optical Backpropagation! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode References Linnainmaa, S. I. (1976). Taylor expansion of the accumulated rounding error. BIT Numerical Mathematics, 16(2), 146–160. Published June 1976. Retrieved March 10, 2025, from doi.org/10.1007/BF01931367 Lvovsky, A. I., Guo, X., & Spall, J. (2025). Training neural networks with end-to-end optical backpropagation. Advanced Photonics, 7(1), 016004. Published February 4, 2025. Retrieved March 10, 2025, from doi.org/10.1117/1.AP.7.1.016… Nielsen, M. A. (2015). How the backpropagation algorithm works. In Neural networks and deep learning. Published 2015. Retrieved March 10, 2025, from neuralnetworksanddeeplearnin… Spall, J., Guo, X., & Lvovsky, A. I. (2025). The optical implementation of backpropagation (Oxford, Lumai). Semiconductor Engineering. Published February 4, 2025. Retrieved March 10, 2025, from semiengineering.com/the-opti…
Midnight in Beijing, Chinese humanoid robots were practicing for their half-marathon scheduled on April 19. This is what the future looks like! #marathon #humanoidtech #humanoid #robot #Robotics #AI #TechRevolution #TechInnovation
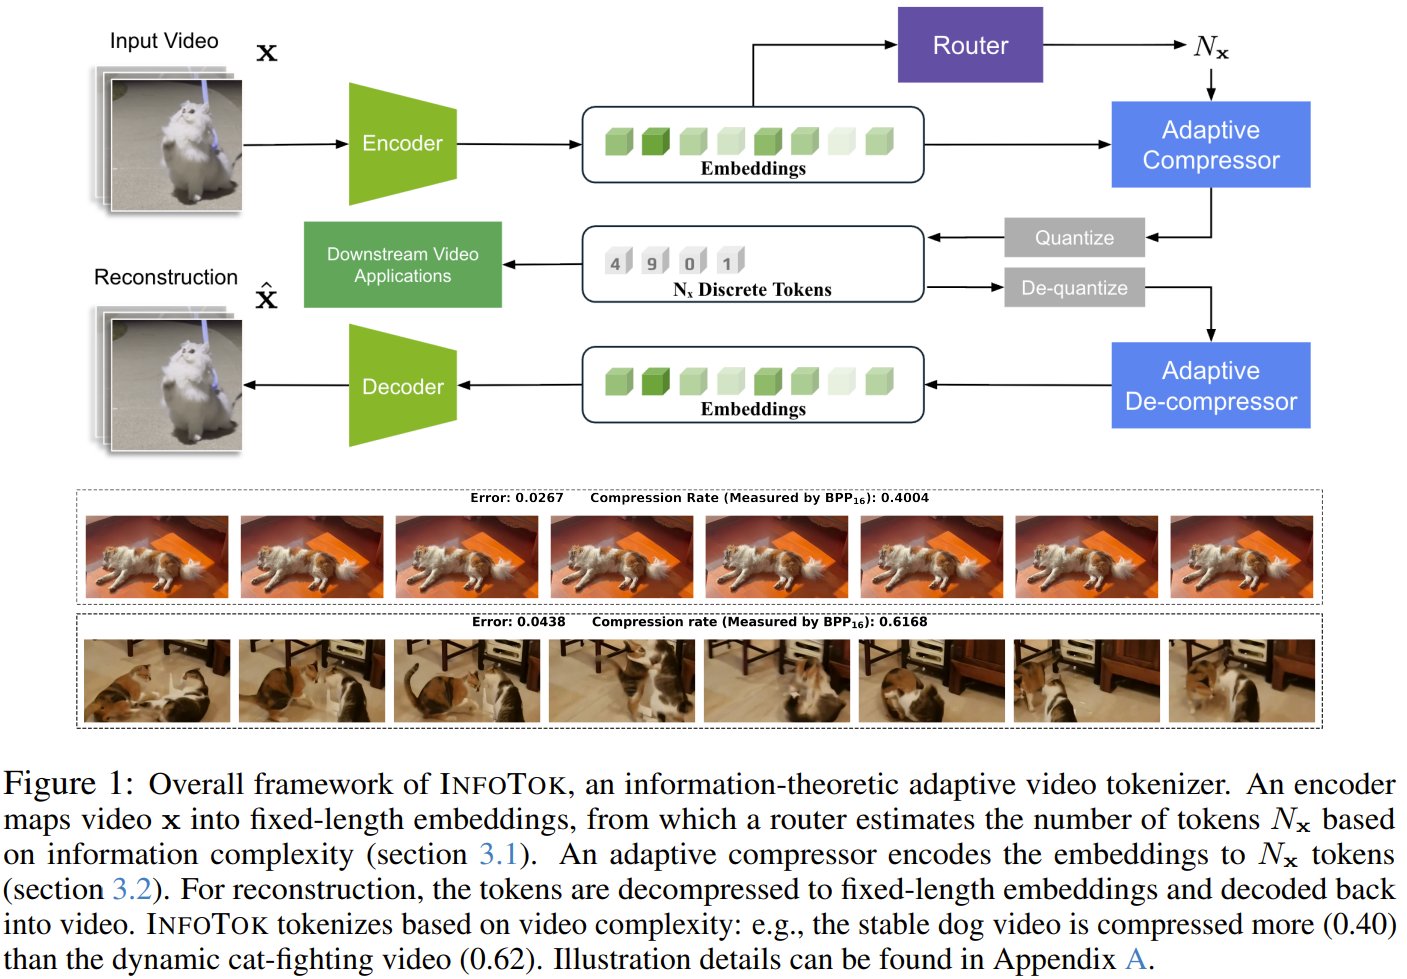
How do we process long videos efficiently without losing crucial information? NVIDIA, Stanford University, and National University of Singapore have an answer! They introduce InfoTok, a breakthrough method inspired by Shannon's information theory. It intelligently allocates
What if robots could perform complex manipulation tasks with zero prior examples, just from an image and instruction? Researchers from National University of Singapore, The University of Hong Kong, Peking University, and Tsinghua University present Goal-VLA! Their Goal-VLA uses
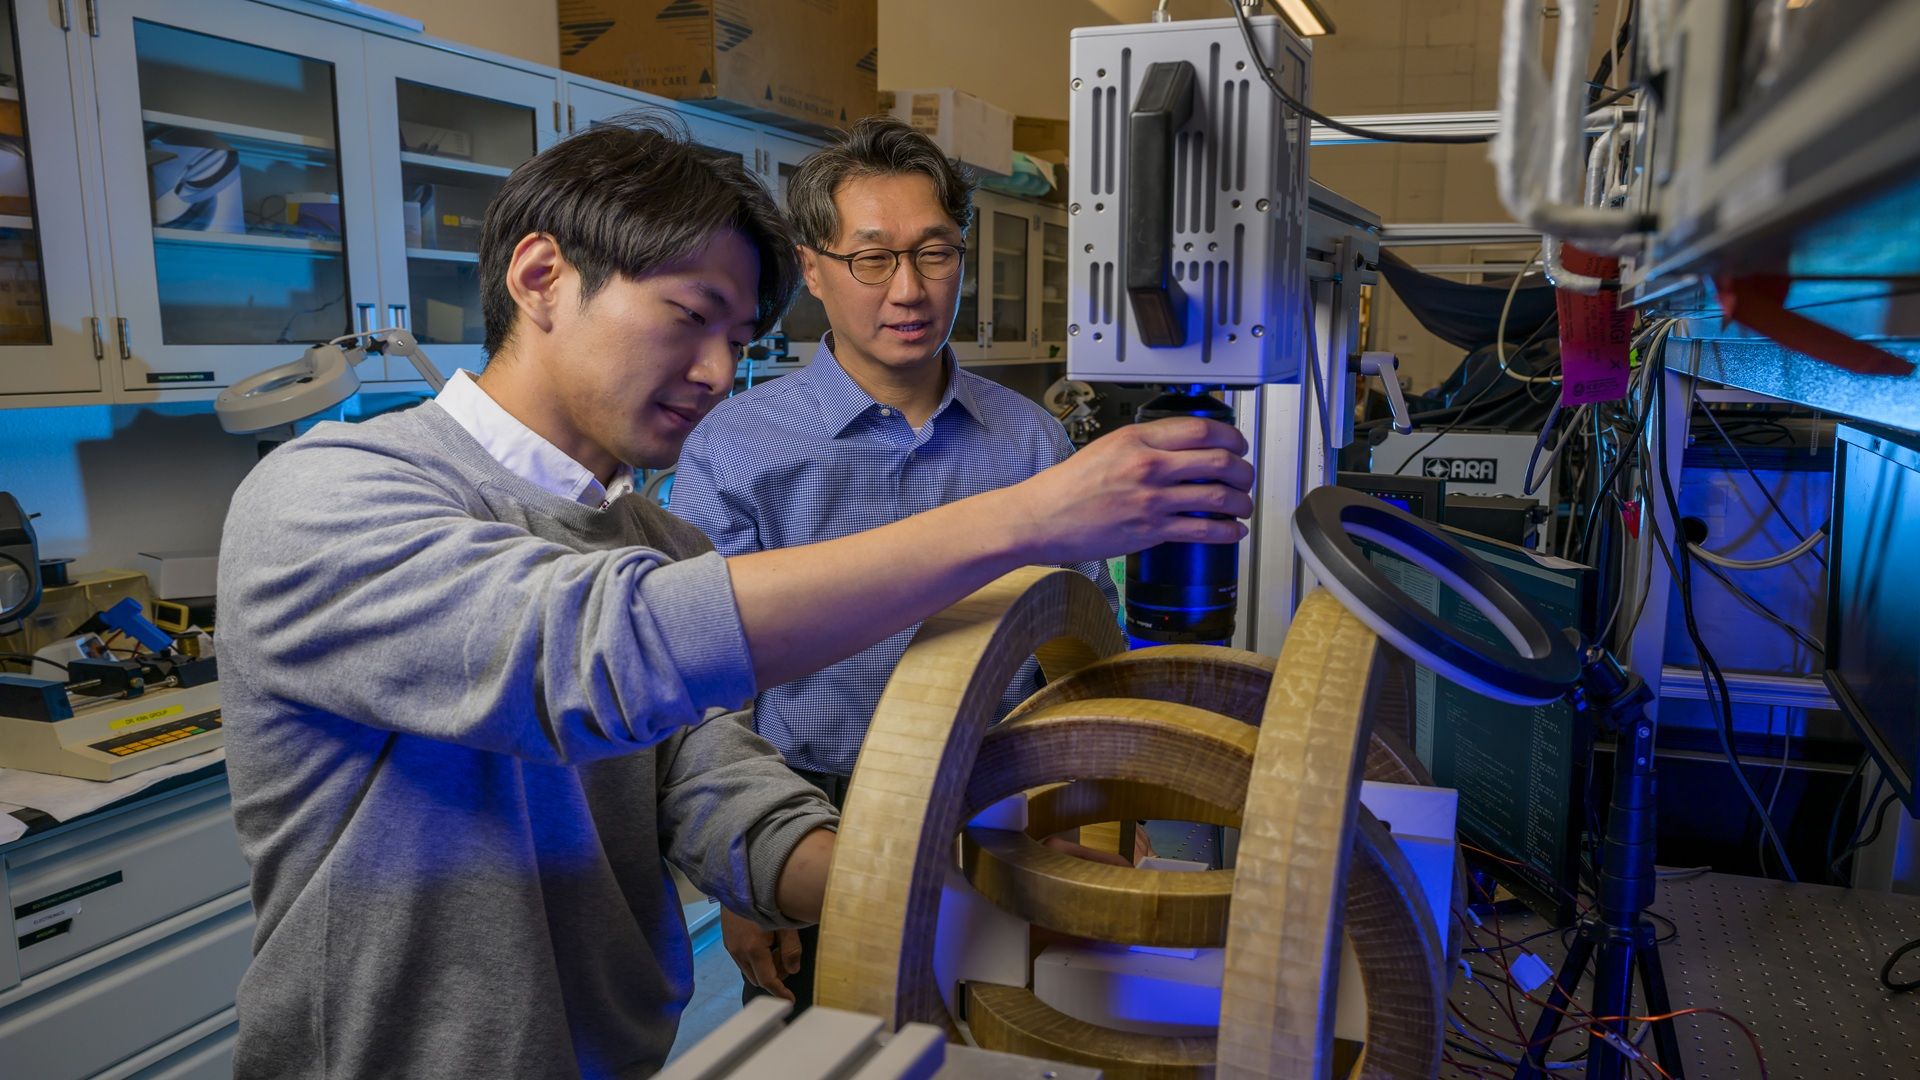
New magnetic system lets microrobots move without cameras or tracking systems
by Neetika Walter @IntEngineering Learn more: https://
bit.ly/41UBeqi #Robotics #Engineering #ArtificialIntelligence #Innovation #Technology
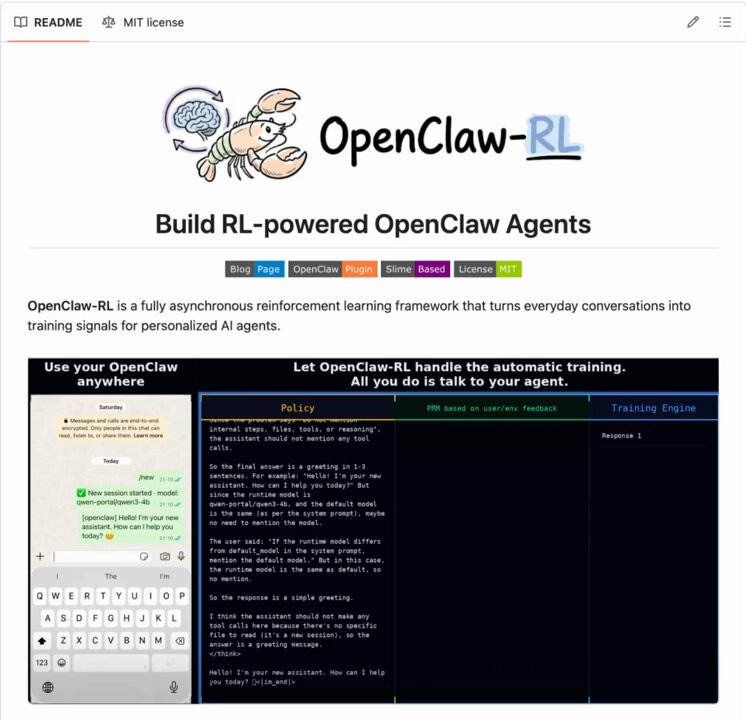
OpenClaw-RL Repo: github.com/Gen-Verse/OpenCla… If you want to learn AI/ML engineering, I have put together a free PDF (380+ pages) with 150+ core lessons. Download for free: dailydoseofds.github.io/ai-e…
OpenClaw Agents adapt through memory files and skills, but the base model weights never actually change.
OpenClaw-RL solves this!
It wraps a self-hosted model as an OpenAI-compatible API, intercepts live conversations from OpenClaw, and trains the policy in… pic.twitter.com/4kxY1b2wSC
OpenClaw meets RL! OpenClaw Agents adapt through memory files and skills, but the base model weights never actually change. OpenClaw-RL solves this! It wraps a self-hosted model as an OpenAI-compatible API, intercepts live conversations from OpenClaw, and trains the policy in the background using RL. The architecture is fully async. This means serving, reward scoring, and training all run in parallel. Once done, weights get hot-swapped after every batch while the agent keeps responding. Currently, it has two training modes: – Binary RL (GRPO): A process reward model scores each turn as good, bad, or neutral. That scalar reward drives policy updates via a PPO-style clipped objective. – On-Policy Distillation: When concrete corrections come in like "you should have checked that file first," it uses that feedback as a richer, directional training signal at the token level. When to use OpenClaw-RL? To be fair, a lot of agent behavior can already be improved through better memory and skill design. OpenClaw's existing skill ecosystem and community-built self-improvement skills handle a wide range of use cases without touching model weights at all. If the agent keeps forgetting preferences, that's a memory problem. And if it doesn't know how to handle a specific workflow, that's a skill problem. Both are solvable at the prompt and context layer. Where RL becomes interesting is when the failure pattern lives deeper in the model's reasoning itself. Things like consistently poor tool selection order, weak multi-step planning, or failing to interpret ambiguous instructions the way a specific user intends. Research on agentic RL (like ARTIST and Agent-R1) has shown that these behavioral patterns hit a ceiling with prompt-based approaches alone, especially in complex multi-turn tasks where the model needs to recover from tool failures or adapt its strategy mid-execution. That's the layer OpenClaw-RL targets, and it's a meaningful distinction from what OpenClaw offers. I have shared the repo in the replies!