New magnetic system lets microrobots move without cameras or tracking systems
by Neetika Walter @IntEngineering Learn more: https://
bit.ly/41UBeqi #Robotics #Engineering #ArtificialIntelligence #Innovation #Technology
RESEARCH
-
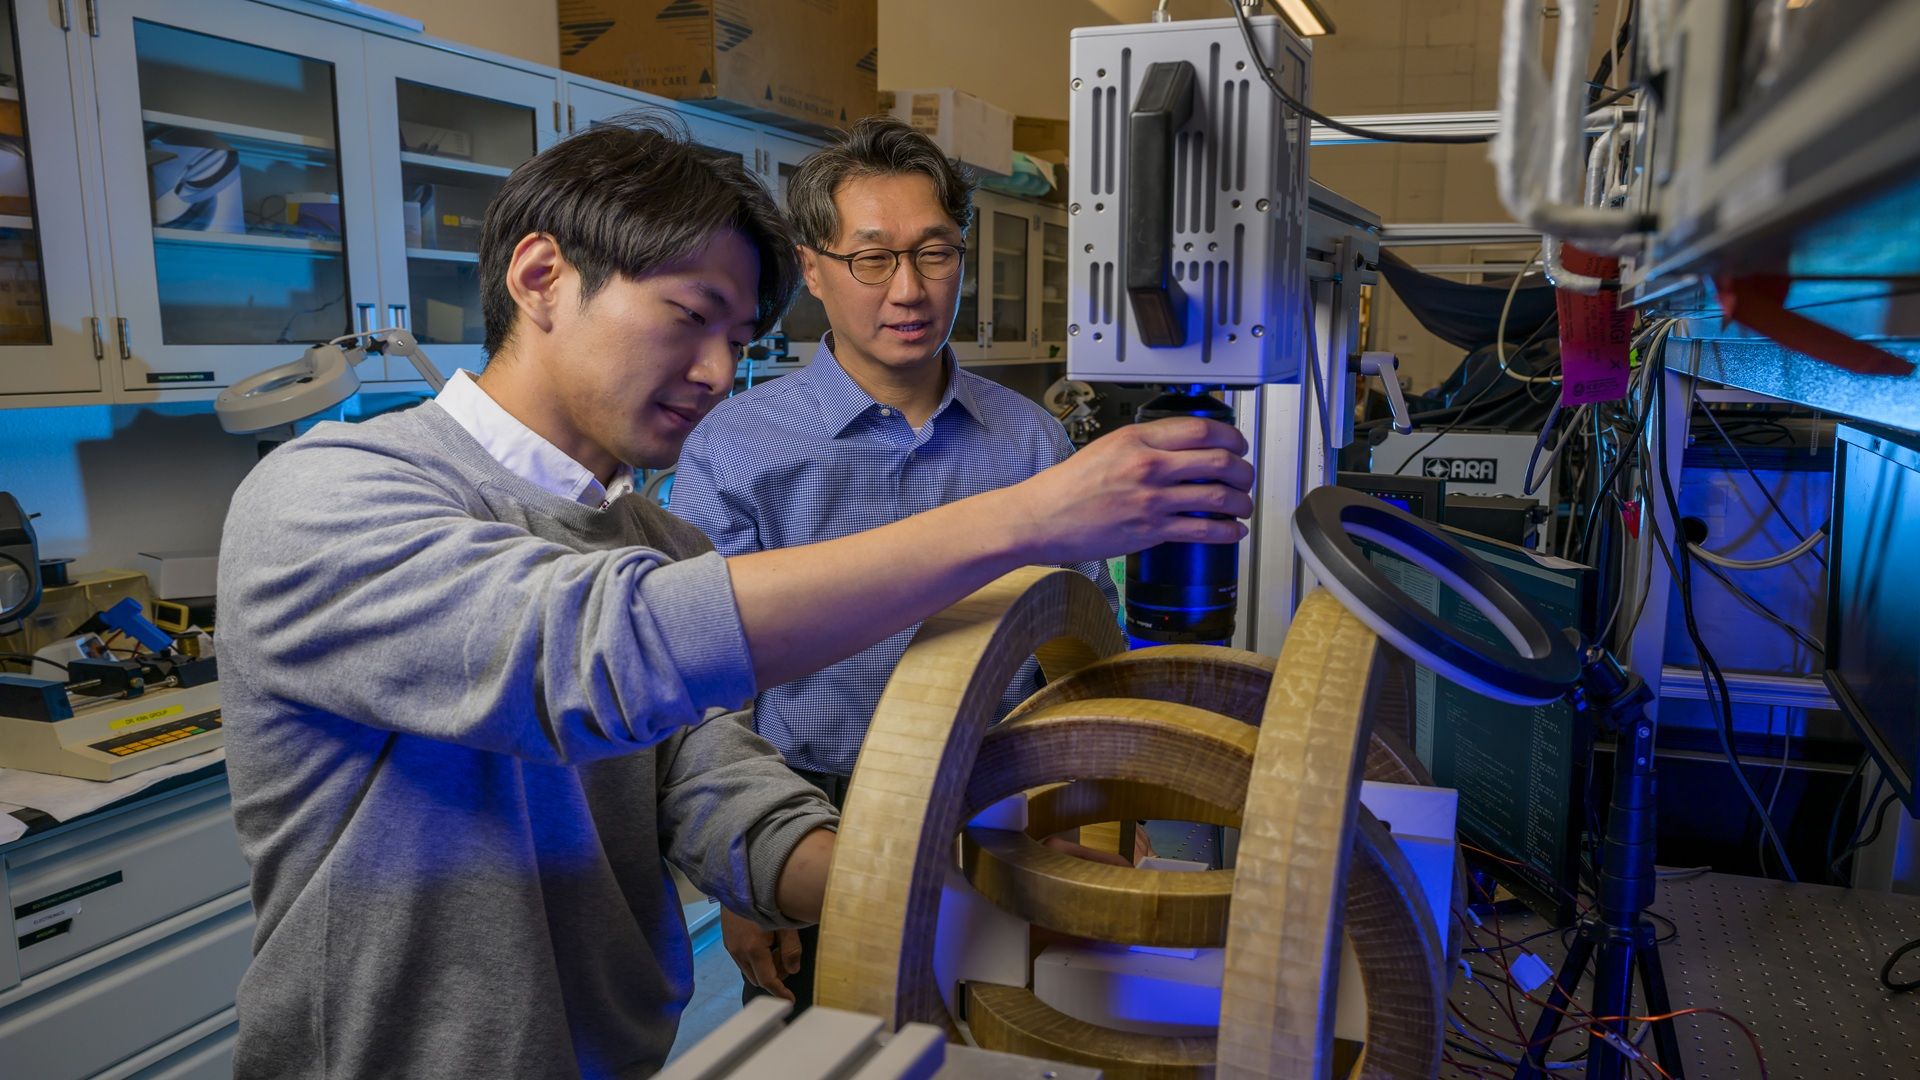
Magnetic System Enables Autonomous Microrobot Movement Without Tracking
By
–
-
OpenClaw-RL Repository and Free AI/ML Engineering PDF Guide
By
–
OpenClaw-RL Repo: github.com/Gen-Verse/OpenCla… If you want to learn AI/ML engineering, I have put together a free PDF (380+ pages) with 150+ core lessons. Download for free: dailydoseofds.github.io/ai-e…
→ View original post on X — @akshay_pachaar, 2026-04-12 13:35 UTC
-
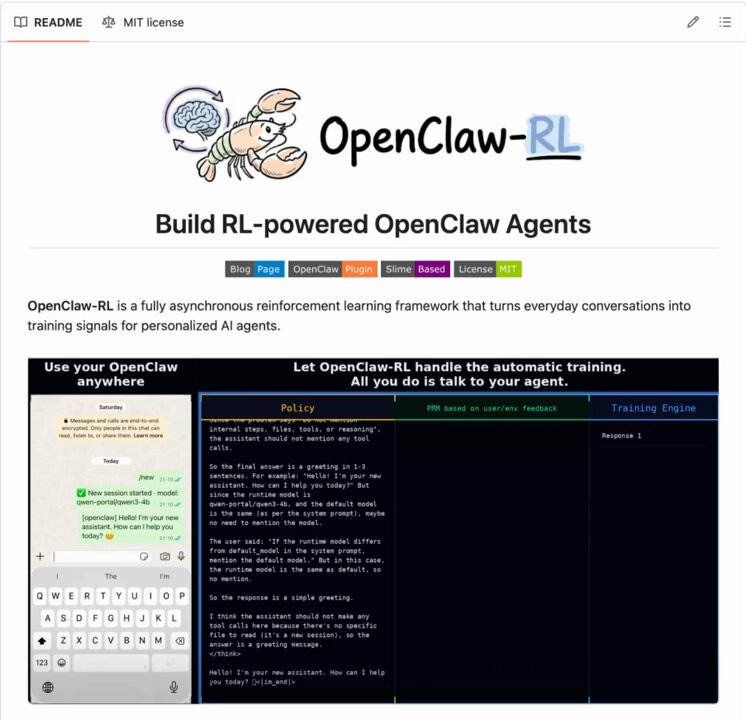
OpenClaw-RL: Reinforcement Learning for Agent Model Weights
By
–
OpenClaw meets RL!
— Akshay 🚀 (@akshay_pachaar) 12 avril 2026
OpenClaw Agents adapt through memory files and skills, but the base model weights never actually change.
OpenClaw-RL solves this!
It wraps a self-hosted model as an OpenAI-compatible API, intercepts live conversations from OpenClaw, and trains the policy in… pic.twitter.com/4kxY1b2wSCOpenClaw meets RL! OpenClaw Agents adapt through memory files and skills, but the base model weights never actually change. OpenClaw-RL solves this! It wraps a self-hosted model as an OpenAI-compatible API, intercepts live conversations from OpenClaw, and trains the policy in the background using RL. The architecture is fully async. This means serving, reward scoring, and training all run in parallel. Once done, weights get hot-swapped after every batch while the agent keeps responding. Currently, it has two training modes: – Binary RL (GRPO): A process reward model scores each turn as good, bad, or neutral. That scalar reward drives policy updates via a PPO-style clipped objective. – On-Policy Distillation: When concrete corrections come in like "you should have checked that file first," it uses that feedback as a richer, directional training signal at the token level. When to use OpenClaw-RL? To be fair, a lot of agent behavior can already be improved through better memory and skill design. OpenClaw's existing skill ecosystem and community-built self-improvement skills handle a wide range of use cases without touching model weights at all. If the agent keeps forgetting preferences, that's a memory problem. And if it doesn't know how to handle a specific workflow, that's a skill problem. Both are solvable at the prompt and context layer. Where RL becomes interesting is when the failure pattern lives deeper in the model's reasoning itself. Things like consistently poor tool selection order, weak multi-step planning, or failing to interpret ambiguous instructions the way a specific user intends. Research on agentic RL (like ARTIST and Agent-R1) has shown that these behavioral patterns hit a ceiling with prompt-based approaches alone, especially in complex multi-turn tasks where the model needs to recover from tool failures or adapt its strategy mid-execution. That's the layer OpenClaw-RL targets, and it's a meaningful distinction from what OpenClaw offers. I have shared the repo in the replies!
→ View original post on X — @akshay_pachaar, 2026-04-12 13:35 UTC
-

MIT’s Self-Folding Origami Robot: Flat to Crawling Machine
By
–
MIT’s Self-Folding Origami #Robot Transforms from Flat Sheet to Crawling, Climbing, Swimming Machine
— Ronald van Loon (@Ronald_vanLoon) 12 avril 2026
by @tweetciiiim#Robotics #MachineLearning #ArtificialIntelligence #ML pic.twitter.com/6UdsasuOcmMIT’s Self-Folding Origami #Robot Transforms from Flat Sheet to Crawling, Climbing, Swimming Machine
by @tweetciiiim #Robotics #MachineLearning #ArtificialIntelligence #ML -
Model Training Harness Modifications and Testing Requirements
By
–
Potentially, but needs more testing. Most other models are trained on a claude code-like harness, whereas codex is different enough to justify modifications. You can change a gate line in hackable install to test. If I enable it for all and it does not help, I get shit here
-
AISLE vs Mythos: LLM Vulnerability Scanning Benchmark Debate
By
–
The moment you've read the analysis done by AISLE, you'll realize that the criticism made here has no basis. The reason is that AISLE hasn't actually reproduced the task that Mythos has solved (letting the LLM scan entire projects until it finds vulnerabilities without human
-
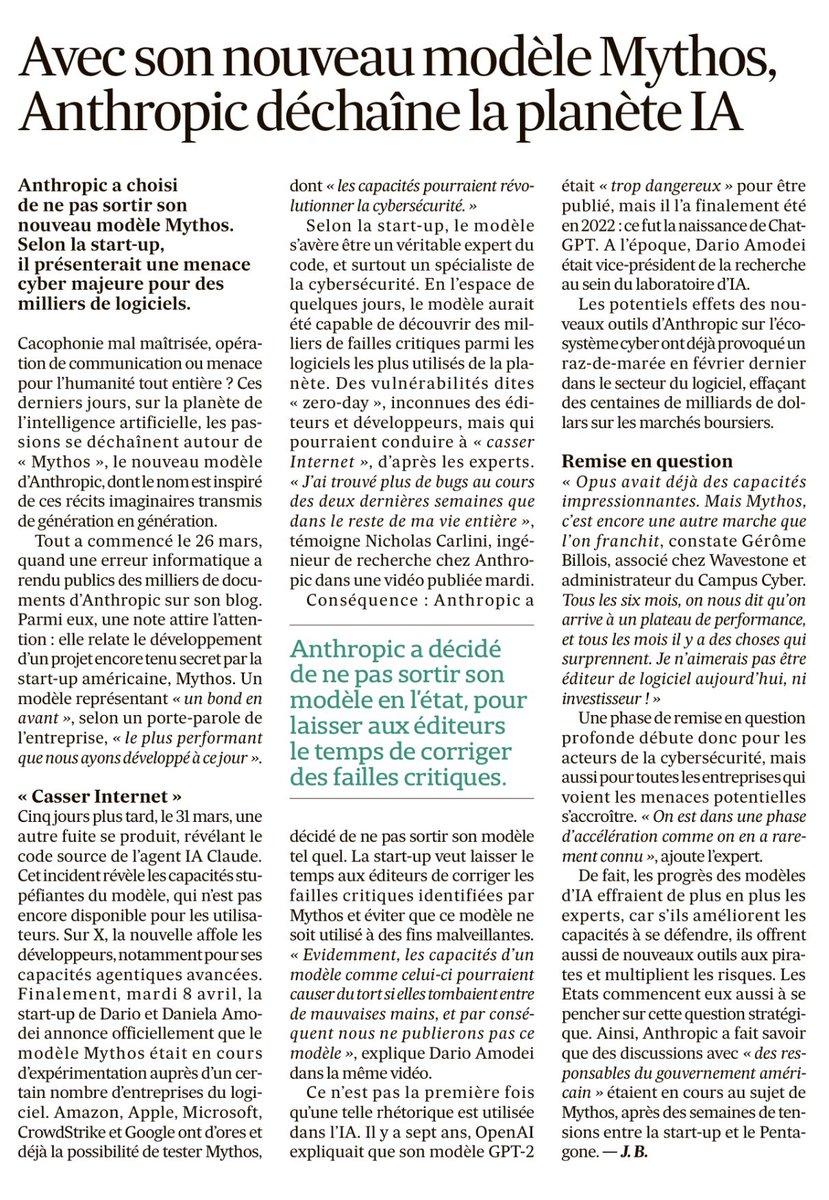
Anthropic Refuses to Release Its Too Powerful Mythos AI Model
By
–
Anthropic has created an AI model so powerful that it refuses to release it. Mythos discovered thousands of critical zero-day vulnerabilities in the world's most used software within days. Amazon, Apple, Microsoft, Google are already testing it. An Anthropic engineer: "I found more bugs in two weeks than in the rest of my entire life." [Translated from EN to English]
→ View original post on X — @alex_tsico, 2026-04-12 11:39 UTC
-

Human intelligence versus AI capability debate continues
By
–
And some say all humans are way smarter than the most capable AI pic.twitter.com/2T21G3VtdR
— AI (@DeepLearn007) 12 avril 2026And some say all humans are way smarter than the most capable AI
-

Atlas Robot Learns Human-Inspired Movements Through Reinforcement Learning
By
–
Reinforcement-Learned Atlas Performs Moves Inspired by Human Mocap and Animation
— Ronald van Loon (@Ronald_vanLoon) 12 avril 2026
via @ZappyZappy7
#Robotics #Engineering #ArtificialIntelligence #Innovation #Technology pic.twitter.com/4zXXce8uXwReinforcement-Learned Atlas Performs Moves Inspired by Human Mocap and Animation via @ZappyZappy7 #Robotics #Engineering #ArtificialIntelligence #Innovation #Technology
→ View original post on X — @ronald_vanloon, 2026-04-12 10:18 UTC
-
Claude Mythos Linked to ByteDance’s Looped LLM Research
By
–
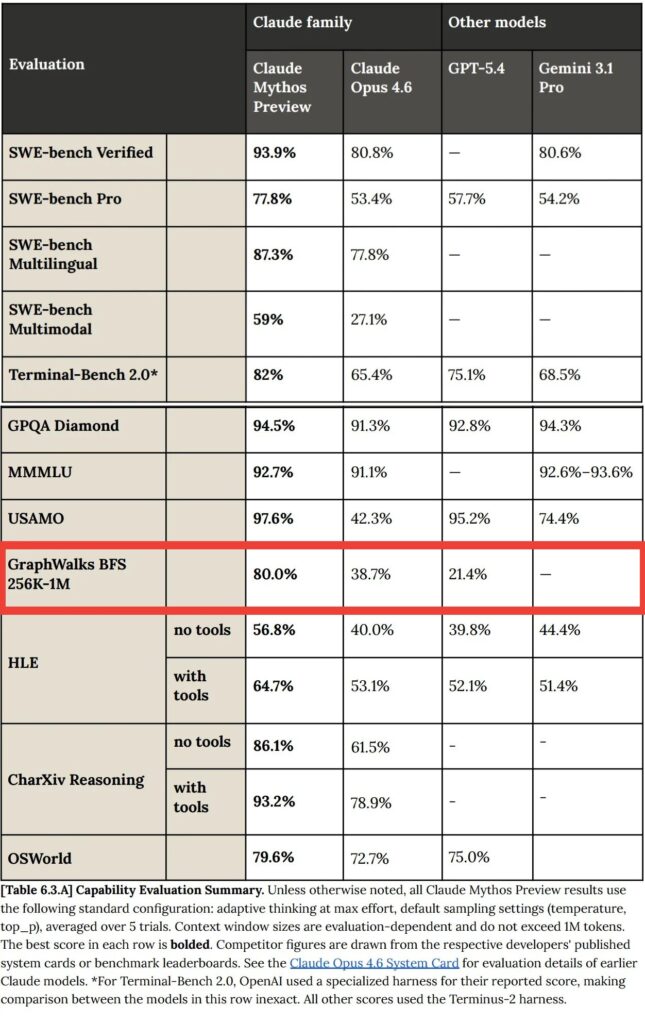
This might be the most important observation about Claude Mythos that nobody is picking up on. Chris is connecting Mythos to ByteDance’s “Scaling Latent Reasoning via Looped Language Models” paper. The core idea: instead of thinking out loud with chain-of-thought text, a looped