https://
artificialanalysis.ai/models/gpt-oss
-120b/providers#aime25x32-performance-gpt-oss-120b
…
OPEN SOURCE
-
GPT-OSS-120B Open Source Model Performance Analysis
By
–
-

Cerebras Leads GPT OSS 120B in AIME25 Math Evaluations
By
–
GPT OSS 120B endpoints are not created equal.
In AIME25 math evals, Artificial Analysis found Cerebras was #1 in accuracy. -

Open-source model families evolutionary analysis on Hugging Face
By
–
Fun to think about open-source models and their variants as families from an evolutionary biology standpoint and analyze "genetic similarity and mutation of traits over model families". These are the 2,500th, 250th, 50th and 25th largest families on @huggingface
: -
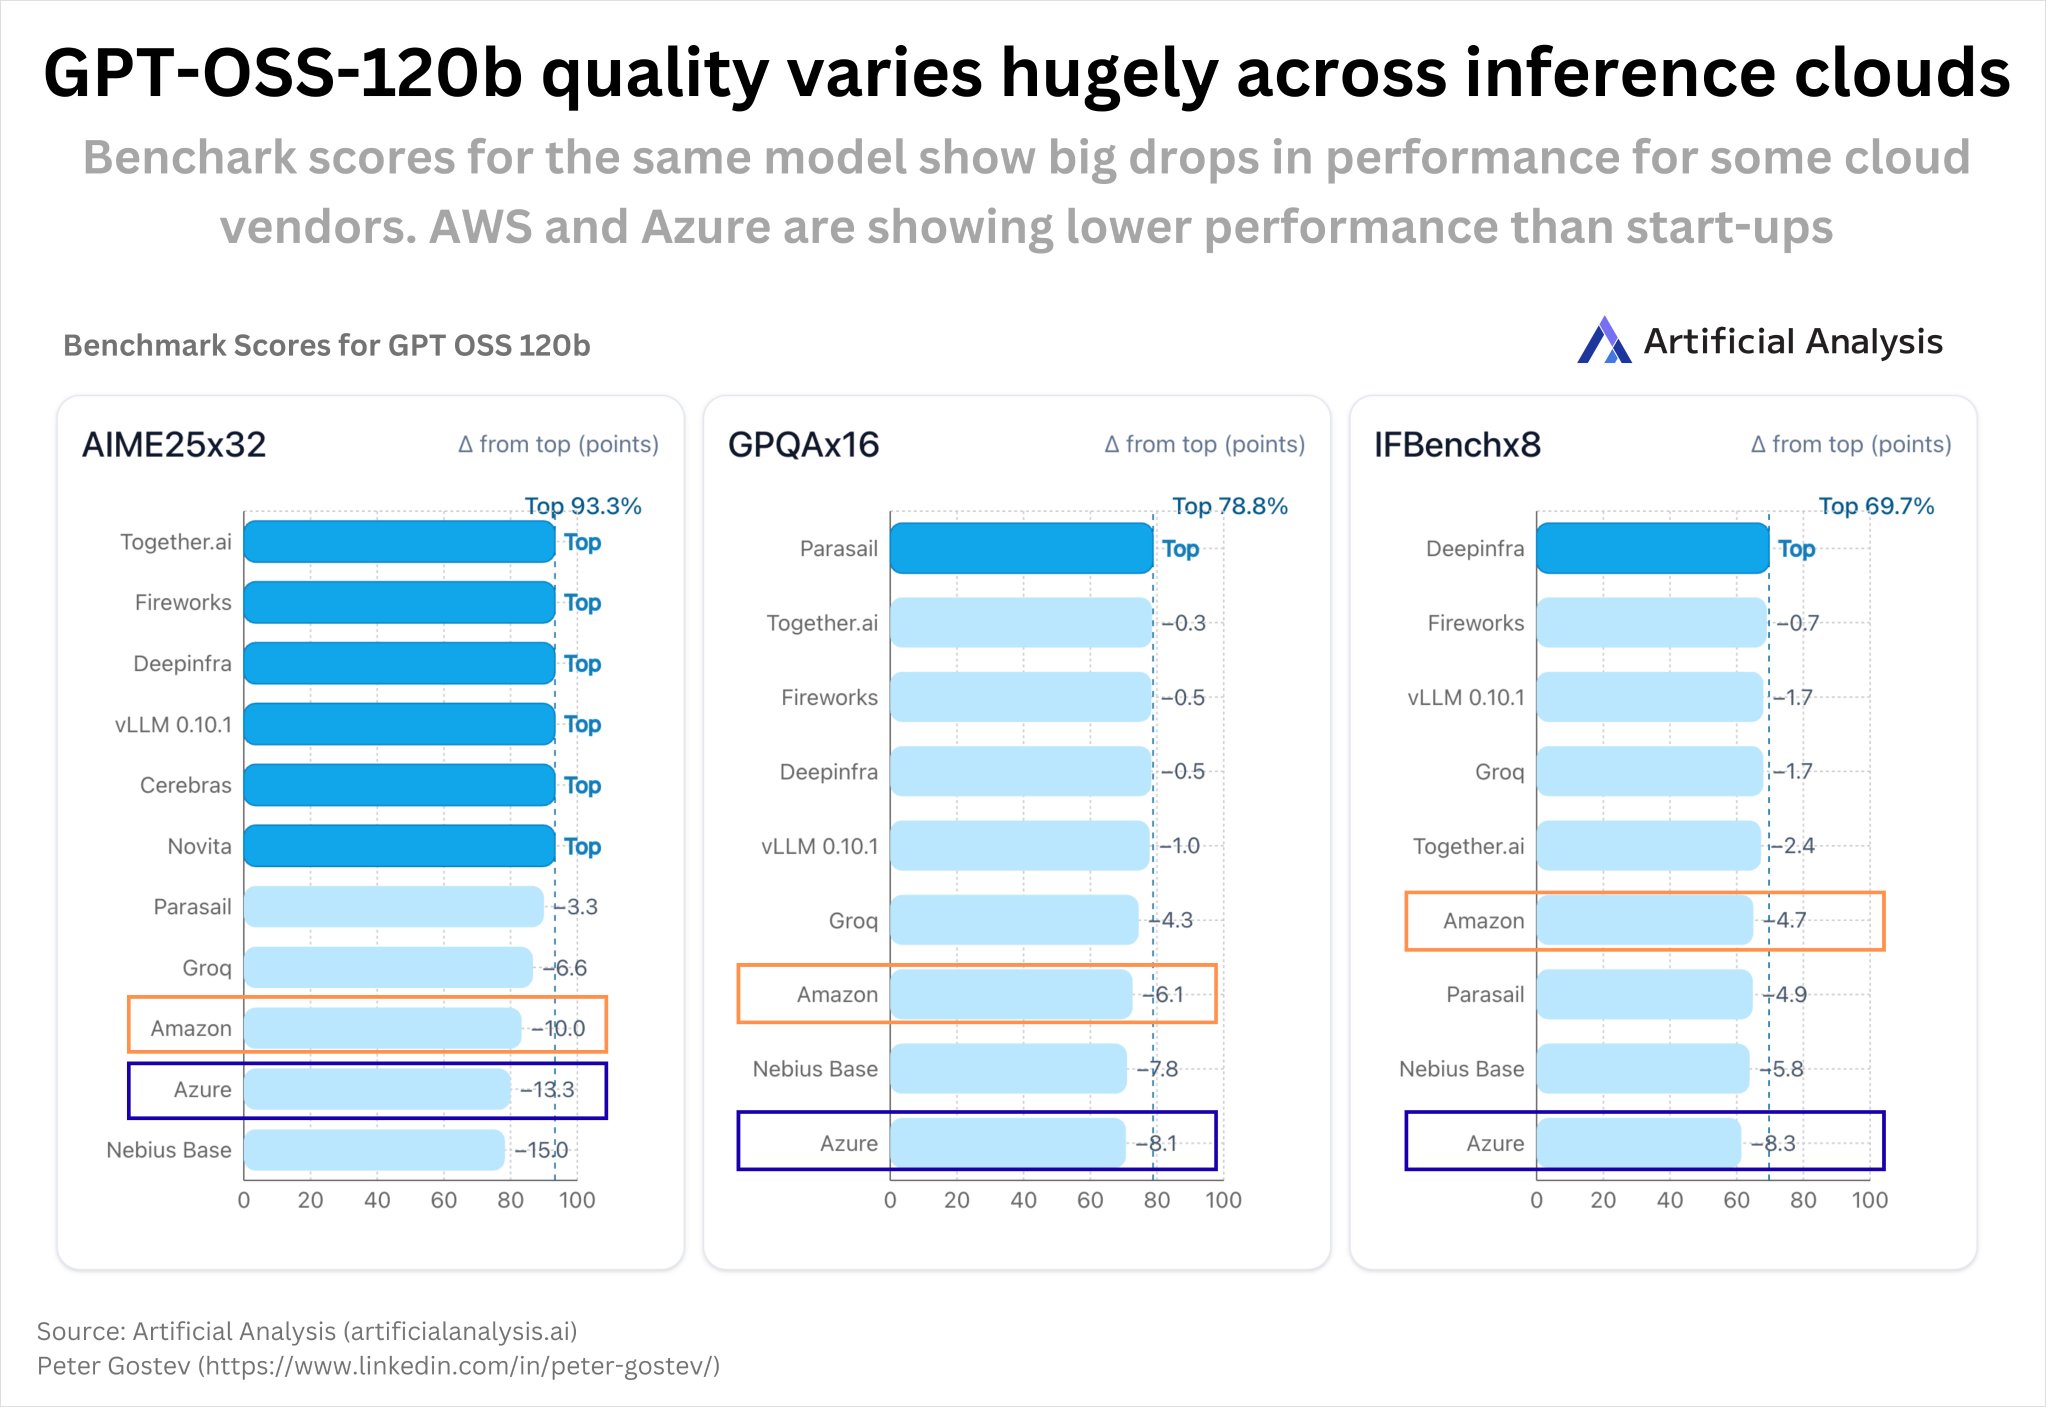
GPT 120B Performance Analysis: AWS and Azure Implementation Issues
By
–
Artificial analysis team did great work analysing the performance of the OpenAI's GPT OSS 120b model across providers – AWS and Azure are lagging behind. I really did not appreciate the extend to which the performance can drop if the model is not implemented correctly
-

Open Weight Model Performance Varies by Cloud Host Provider
By
–
This is actually a pretty surprising and something that should lead companies to change how they are thinking about hosting. Model performance for the open weights GPT model vary by meaningful amounts depending on who is hosting it, with Azure & AWS being low. Worth watching.
-
Comparing Kimi K2 and GPT-OSS Integration in Development Workflows
By
–
For those who’ve built with both Kimi K2 and gpt-oss, how have you integrated them into your workflows and which is working better for you?
-

Mistral Medium 3.1 Released
By
–

Mistral released Mistral Medium 3.1! It is now available as a default model on Le Chat as well as in the API as mistral-medium-2508
-

Fixing Transformers GPT-OSS MoE Finetuning Issues
By
–
"i thought the transformers gpt-oss MoE finetuning was broken, how did you get it working?"
-

LFM2-VL Models: 1.6B and 450M Vision-Language Released
By
–
We also provide an inference and a fine-tuning Colab notebooks. LFM2-VL-1.6B: https://
huggingface.co/LiquidAI/LFM2-
VL-1.6B
… LFM2-VL-450M: https://
huggingface.co/LiquidAI/LFM2-
VL-450M
… -

Liquid Releases Fast 450M and 1.6B Parameter VLM Models
By
–
Liquid just released two 450M and 1.6B param VLMs! They're super fast and leverage SigLIP2 NaFlex encoders to handle native resolutions without distortion. Available today on @huggingface
!