
Everyone's bragging about 200k, 1M, even 10M token context windows in 2026. Nobody's talking about what actually happens inside them. I just fell down this rabbit hole and I can't stop thinking about it: A new paper published January 2026 tested hundreds of thousands of data
OPEN SOURCE
-

Open Source Data: Essential Missing Component for Large-Scale Training
By
–
More Open Source Data. The main missing ingredient for large scale training.
-

OpenEnv Hackathon SF: Connect with Our Team on Agentic Systems
By
–
If you’re attending OpenEnv Hackathon (SF) — let’s connect! We’re excited to be one of the sponsors and our team will be there as to support builders on open environments & agentic systems. https://
cerebralvalley.ai/e/openenv-hack
athon-sf
… -
Okara launches a secure AI chat solution
By
–
Okara launched a new AI chat solution powered by open-source models, where all your conversations are encrypted. https://t.co/TIK6byJhPf pic.twitter.com/EdtDEbqmO5
— 🚨 AI News | TestingCatalog (@testingcatalog) 24 février 2026Okara launched a new AI chat solution powered by open-source models, where all your conversations are encrypted.
-
Introducing the LFM2-24B-A2B Model on Hugging Face
By
–
huggingface.co/LiquidAI/LFM2… [Translated from EN to English]
→ View original post on X — @maximelabonne, 2026-02-24 17:48 UTC
-
Unfortunate timing: 24B-A2B release coincides with Qwen3.5 launch
By
–
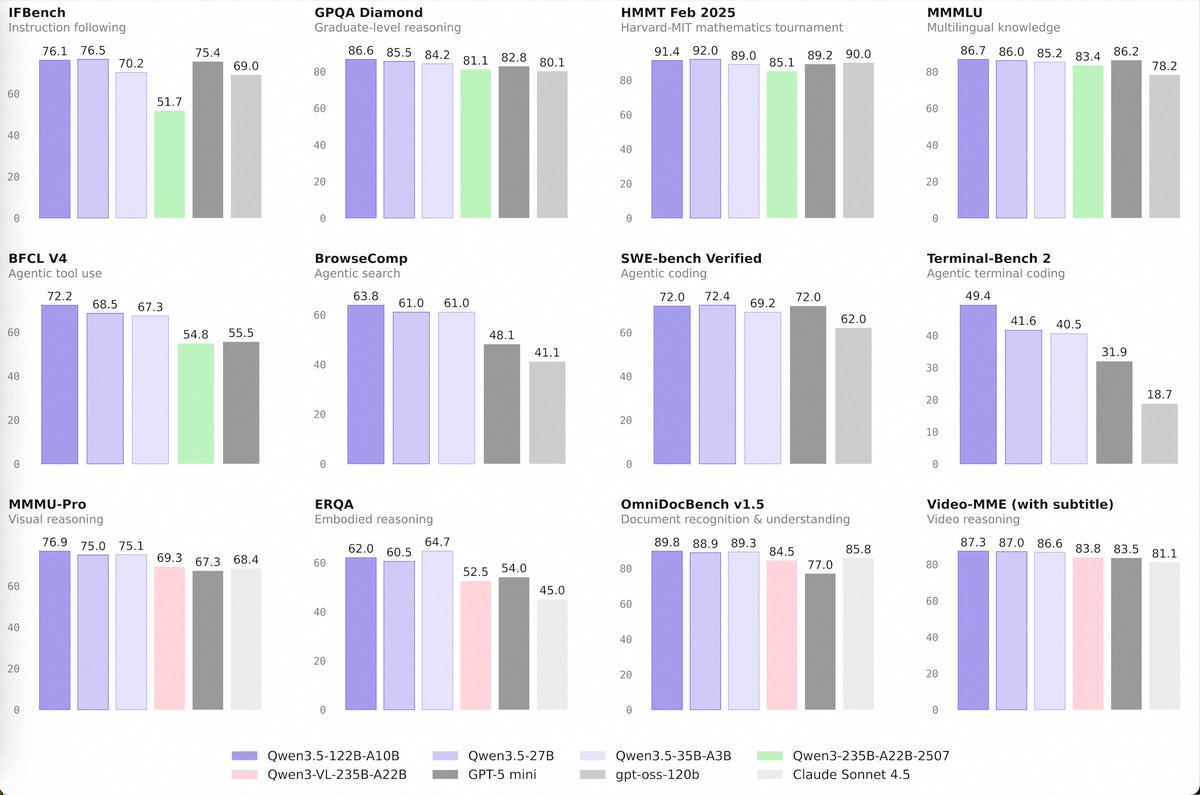
Releasing a 24B-A2B model on the same day as Qwen3.5-35B-A3B is NOT great timing 🥲 Qwen (@Alibaba_Qwen) 🚀 Introducing the Qwen 3.5 Medium Model Series Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B ✨ More intelligence, less compute. • Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts. • Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios. • Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring: – 1M context length by default – Official built-in tools 🔗 Hugging Face: huggingface.co/collections/Q… 🔗 ModelScope: modelscope.cn/collections/Qw… 🔗 Qwen3.5-Flash API: modelstudio.console.alibabac… Try in Qwen Chat 👇 Flash: chat.qwen.ai/?models=qwen3.5… 27B: chat.qwen.ai/?models=qwen3.5… 35B-A3B: chat.qwen.ai/?models=qwen3.5… 122B-A10B: chat.qwen.ai/?models=qwen3.5… Would love to hear what you build with it. — https://nitter.net/Alibaba_Qwen/status/2026339351530188939#m
→ View original post on X — @maximelabonne, 2026-02-24 17:01 UTC
-
LFM2-24B-A2B: Liquid AI’s Fastest 24B MoE Model Released
By
–
Meet LFM2-24B-A2B, @liquidai's largest model. 24B MoE, 2B active. Blazing fast even on CPU. Available now in LM Studio 👾💧 lmstudio.ai/models/lfm2-24b-…
→ View original post on X — @maximelabonne, 2026-02-24 15:44 UTC
-
Liquid AI releases LFM2-24B-A2B model for on-device inference
By
–
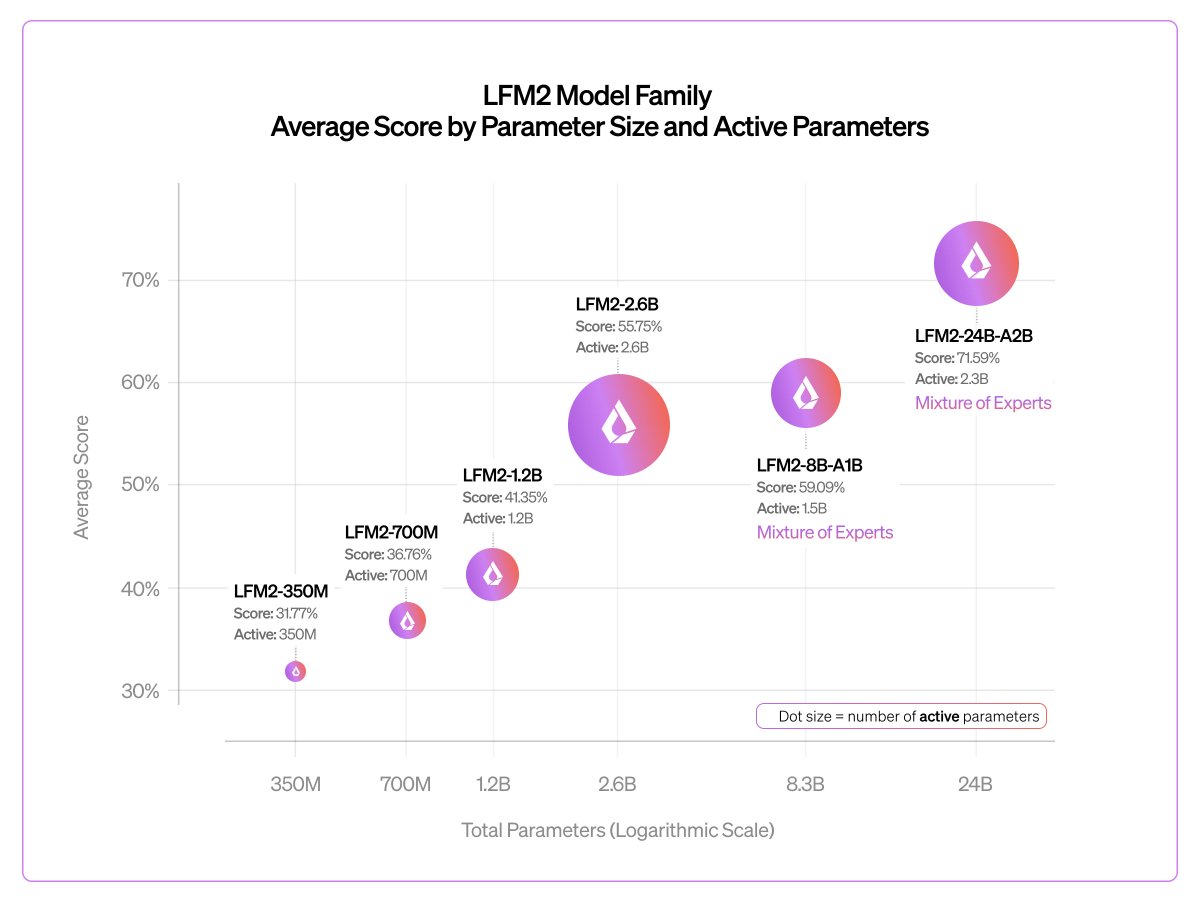
ollama run lfm2:24b-a2b .@liquidai's latest on-device model is here! It's the largest LFM2 model yet, and is designed to run fast on device, and fits on devices with 32GB of unified memory. Liquid AI (@liquidai) Today, we release our largest LFM2 model: LFM2-24B-A2B 🐘 > 24B total parameters > 2.3B active per token > Built on our hybrid, hardware-aware LFM2 architecture It combines LFM2’s fast, memory-efficient design with a Mixture of Experts setup, so only 2.3B parameters activate each run. The result: best-in-class efficiency, fast edge inference, and predictable log-linear scaling all in a 32GB, 2B-active MoE footprint. 🧵 — https://nitter.net/liquidai/status/2026301771539202269#m
→ View original post on X — @maximelabonne, 2026-02-24 14:36 UTC
-
Liquid AI Releases Largest LFM2-24B-A2B Model with Fast Inference
By
–
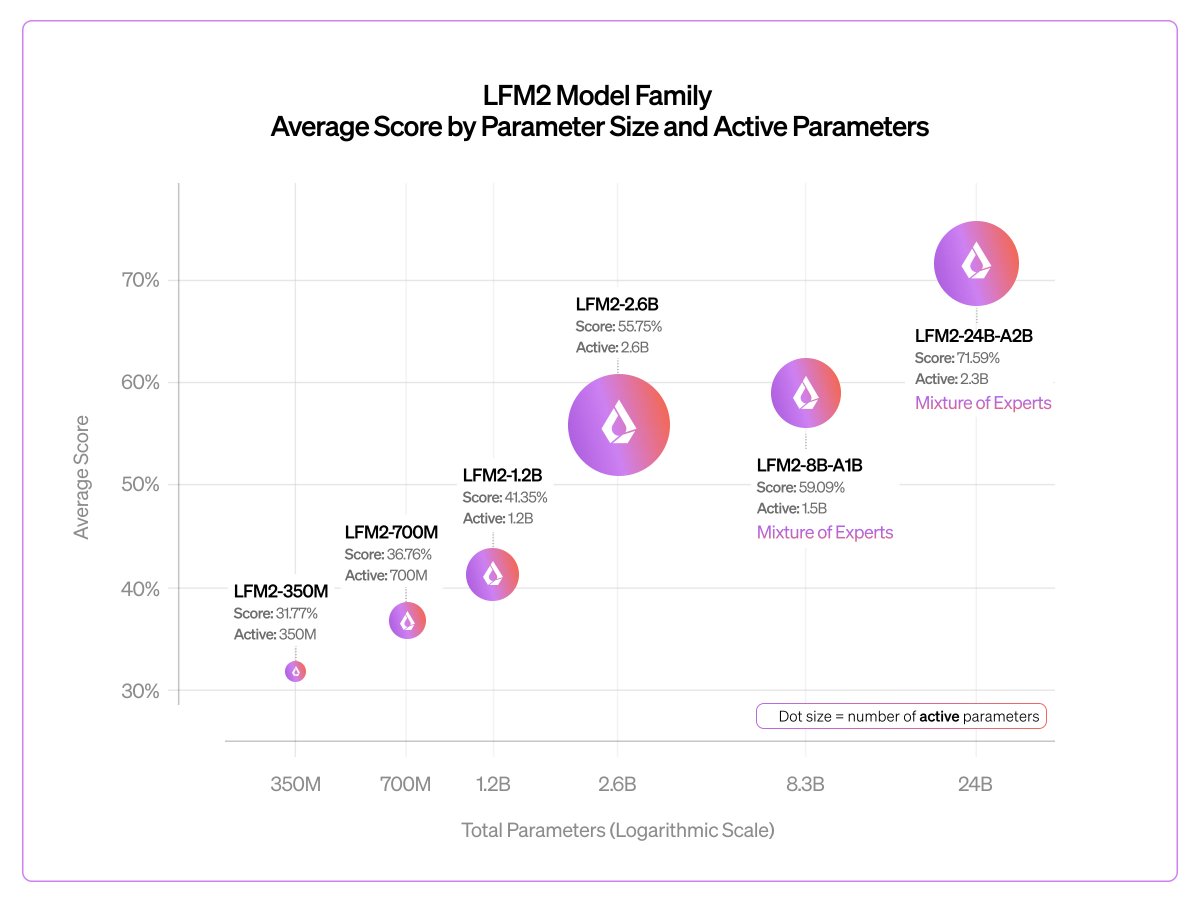
Early checkpoint of our biggest LFM2 model to date 🎉 It shows good scaling and extremely fast inference vs. gpt-oss-20b and Qwen3-30B-A3B We'll release an LFM2.5 version with more pre-training and RL in a few months Liquid AI (@liquidai) Today, we release our largest LFM2 model: LFM2-24B-A2B 🐘 > 24B total parameters > 2.3B active per token > Built on our hybrid, hardware-aware LFM2 architecture It combines LFM2’s fast, memory-efficient design with a Mixture of Experts setup, so only 2.3B parameters activate each run. The result: best-in-class efficiency, fast edge inference, and predictable log-linear scaling all in a 32GB, 2B-active MoE footprint. 🧵 — https://nitter.net/liquidai/status/2026301771539202269#m
→ View original post on X — @maximelabonne, 2026-02-24 14:31 UTC
-

AI mimics devs but lacks real expertise
By
–
When you say "act as a senior developer" the model doesn't think like one. It writes like one. Big difference. It pattern-matches to how developers sound in training data. Not how they actually solve problems. You get confident-sounding output. Not expert-level thinking.