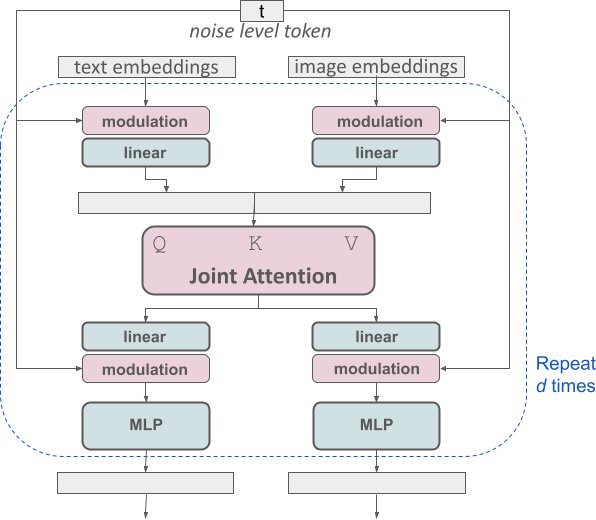
(3/3) Our new Multimodal Diffusion Transformer (MMDiT) architecture uses separate sets of weights for image and language representations, which improves text understanding and spelling capabilities compared to previous versions of SD3. Read the full blog post and access the
MULTIMODAL AI
-

Stable Diffusion 3 Outperforms DALL-E 3 and Midjourney
By
–
(2/3) Stable Diffusion 3 outperforms state-of-the-art text-to-image generation systems such as DALL·E 3, Midjourney v6, and Ideogram v1 in typography and prompt adherence, based on human preference evaluations. With SD3 as a baseline, this chart outlines the areas it wins against
-
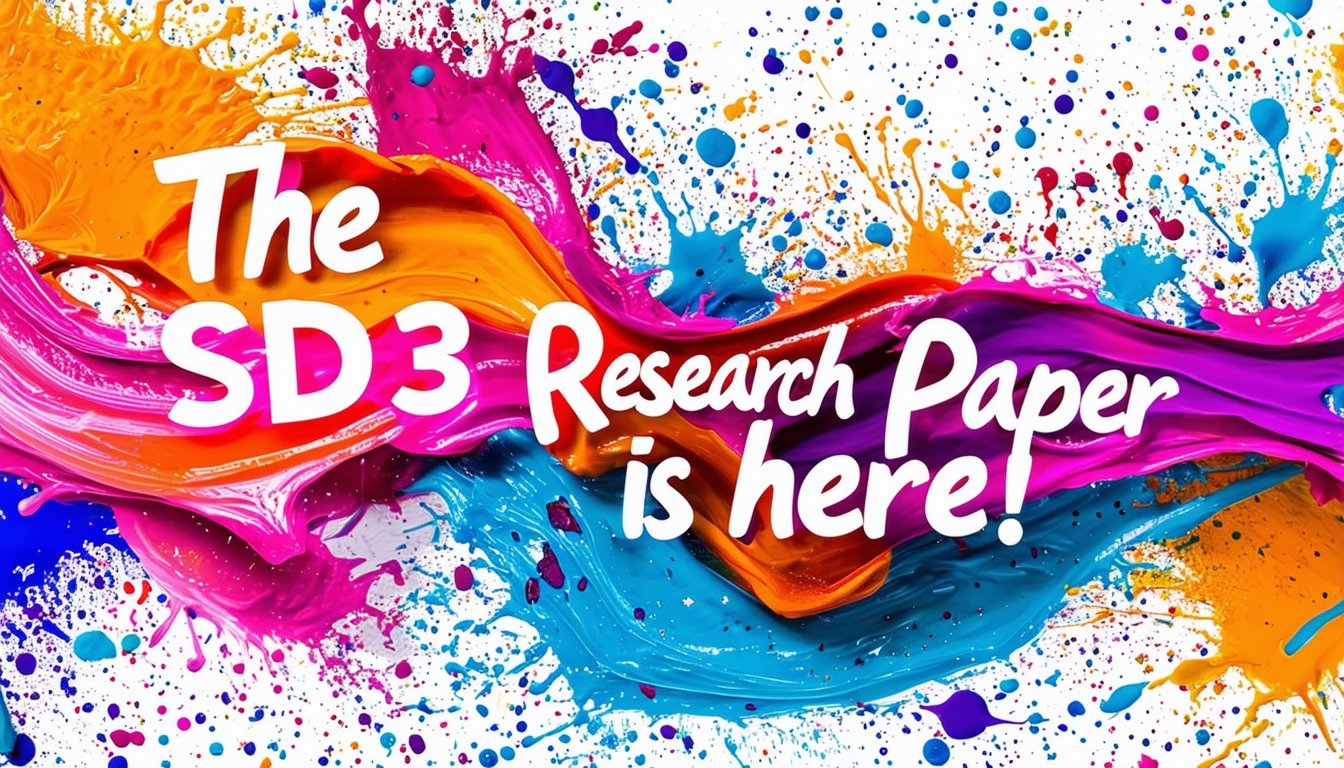
Stable Diffusion 3 Research Paper Released
By
–
(1/3) Today, we're publishing our research paper that dives into the underlying technology powering Stable Diffusion 3. Prompt: A beautiful painting of flowing colors and styles forming the words “The SD3 research paper is here!”, the background is speckled with drops and
-
Flowise Adds Open Source Vision Models Like LLava
By
–
Amazing to see how community has been using the latest vision capability in Flowise!
— FlowiseAI (@FlowiseAI) 5 mars 2024
We're also adding support for open source models like Llava🌋
Share with us what you have been building with the vision & speech to text features🙌 https://t.co/Rp8NvK14vaAmazing to see how community has been using the latest vision capability in Flowise! We're also adding support for open source models like Llava Share with us what you have been building with the vision & speech to text features
-
LLMs vs Image Generators: Understanding Distinct Capabilities
By
–
AI image generators, and their errors, tell you very little about LLMs & their capabilities. When you ask ChatGPT or Bard to produce an image, the LLM is just writing prompts (often inexpertly) and those prompts are then processed separately by the relatively dumb image makers.
-
Claude Outperforms in Multimodal Graph Analysis Study
By
–
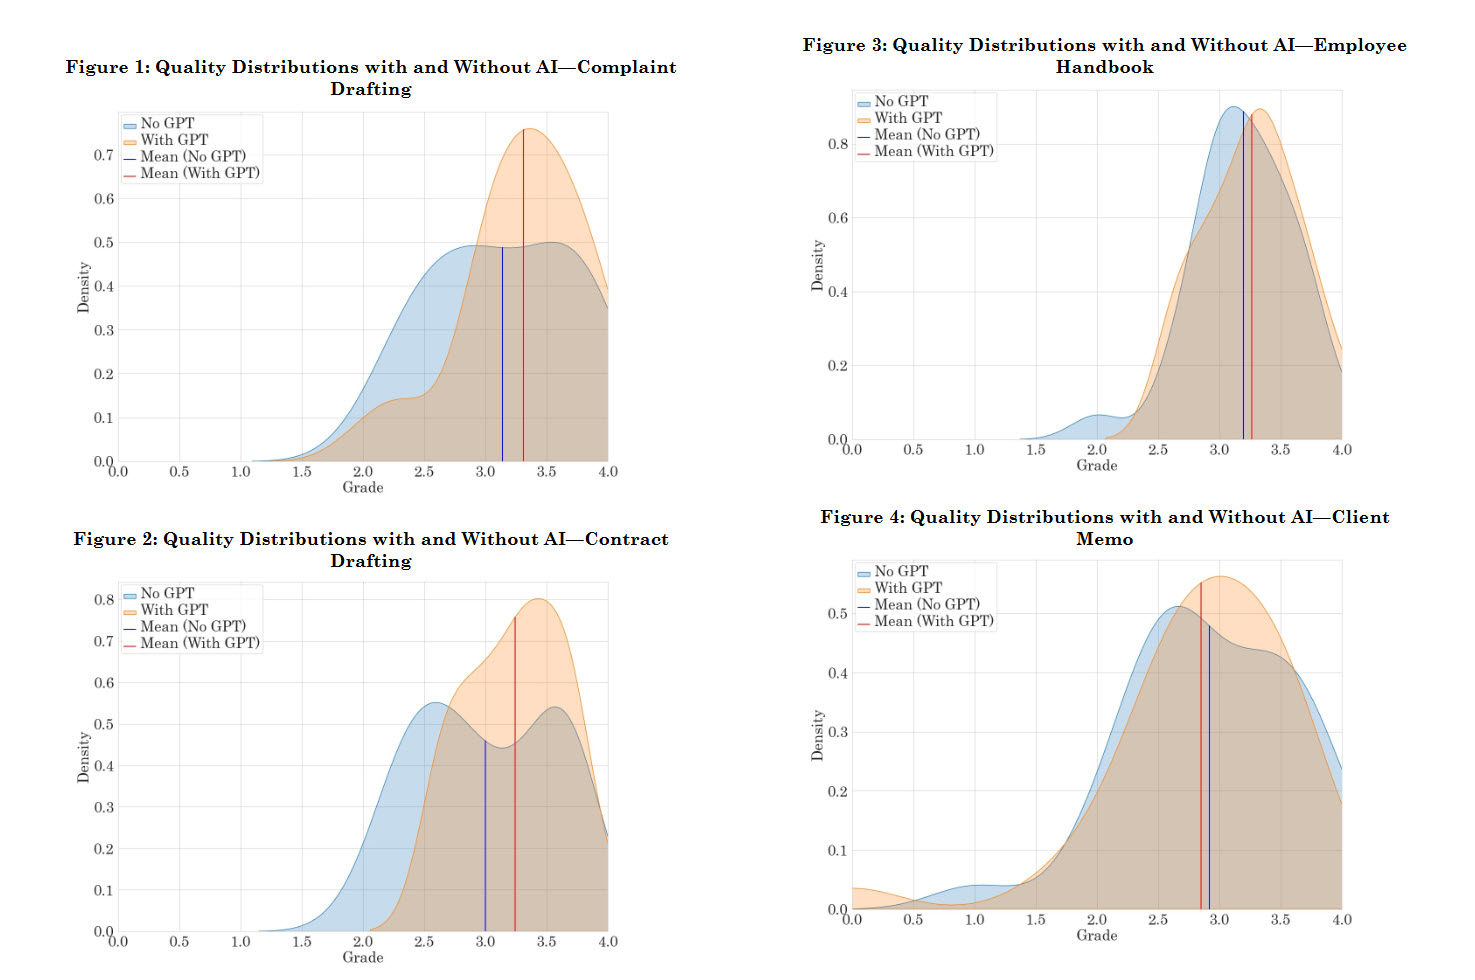
Multimodal & graphs: Looking at a set of four graphs from a study of law students & AI, Claude does by far the best, Gemini 1.5 does well, and GPT-4 has trouble with visual details, leading to some hallucinations. However, when asked to provide the means for the graph, all fail.
-
Router Architecture for Multiple Image Generation Models
By
–
Maybe the future is multiple models. You prompt an image and a router decides the best AI image model for that prompt… Same concept as Mistral 8x7B or Mix of Experts but with image models…
-
TripoSR: Fast Image-to-3D Model Released by Stability AI
By
–
Today we are releasing TripoSR in collaboration with @tripoAI. TripoSR is a new image-to-3D model capable of creating high quality outputs in less than a second.
— Stability AI (@StabilityAI) 4 mars 2024
Learn more here: https://t.co/qfg5MYunOD pic.twitter.com/0erACTTTf0Today we are releasing TripoSR in collaboration with @tripoAI
. TripoSR is a new image-to-3D model capable of creating high quality outputs in less than a second. Learn more here: https://
bit.ly/3P7bNMn -
Perplexity Pro integrates Playground AI V2.5 image generation
By
–
Perplexity Pro users can now experience @playground_ai's new V2.5 as the default model to generate images. Whether you need photographs, paintings, illustrations, diagrams, or something more custom to visually enhance your answer, the choice is yours! pic.twitter.com/yMdh3l5AhC
— Perplexity (@perplexity_ai) 4 mars 2024Perplexity Pro users can now experience @playground_ai
's new V2.5 as the default model to generate images. Whether you need photographs, paintings, illustrations, diagrams, or something more custom to visually enhance your answer, the choice is yours! -
Snap optimizes OCR inference with computer vision at GTC24
By
–
Join us at #GTC24 on March 20 to learn how Snap optimizes optical character recognition (OCR) inference with #computervision to create interactive experiences. Register now.
— NVIDIA AI (@NVIDIAAI) 4 mars 2024
https://t.co/jajojWY6LV pic.twitter.com/vFTfCPjC2kJoin us at #GTC24 on March 20 to learn how Snap optimizes optical character recognition (OCR) inference with #computervision to create interactive experiences. Register now. https://
nvda.ws/3T0lbT3