Google Lookout Uses AI to Describe Images for the Visually Impaired: Google Lookout’s latest breakthrough in accessibility technology has introduced a new… https://
analyticsvidhya.com/blog/2024/02/g
oogle-lookout-uses-ai-to-describe-images-for-the-visually-impaired/?utm_source=dlvr.it&utm_medium=twitter
… #DataAnalytics #DataScience #DataDriven #Blockchain #CIO #MachineLearning #BusinessIntelligence #AI
MULTIMODAL AI
-
Google Lookout AI Describes Images for Visually Impaired Users
By
–
-
Lip Sync AI Tool: Create Videos with Custom Voice Synthesis
By
–
Ready to get rolling with Lip Sync? Here’s a quick how-to. Start with a front-facing, human video; then just fill in the voice.
— Pika (@pika_labs) 6 mars 2024
Can’t wait to hear what you come up with in the comments! pic.twitter.com/YjDzybvEf9Ready to get rolling with Lip Sync? Here’s a quick how-to. Start with a front-facing, human video; then just fill in the voice. Can’t wait to hear what you come up with in the comments!
-
Stable Diffusion 3 Research Paper Released with Text Generation Capabilities
By
–
In case you missed it, diffusion models can spell now! We released the Stable Diffusion 3 research paper yesterday, outlining the underlying technology powering the model. Read the paper here: https://
bit.ly/3uTsh3T -
Anthropic Announces Claude 3 Model Family
By
–
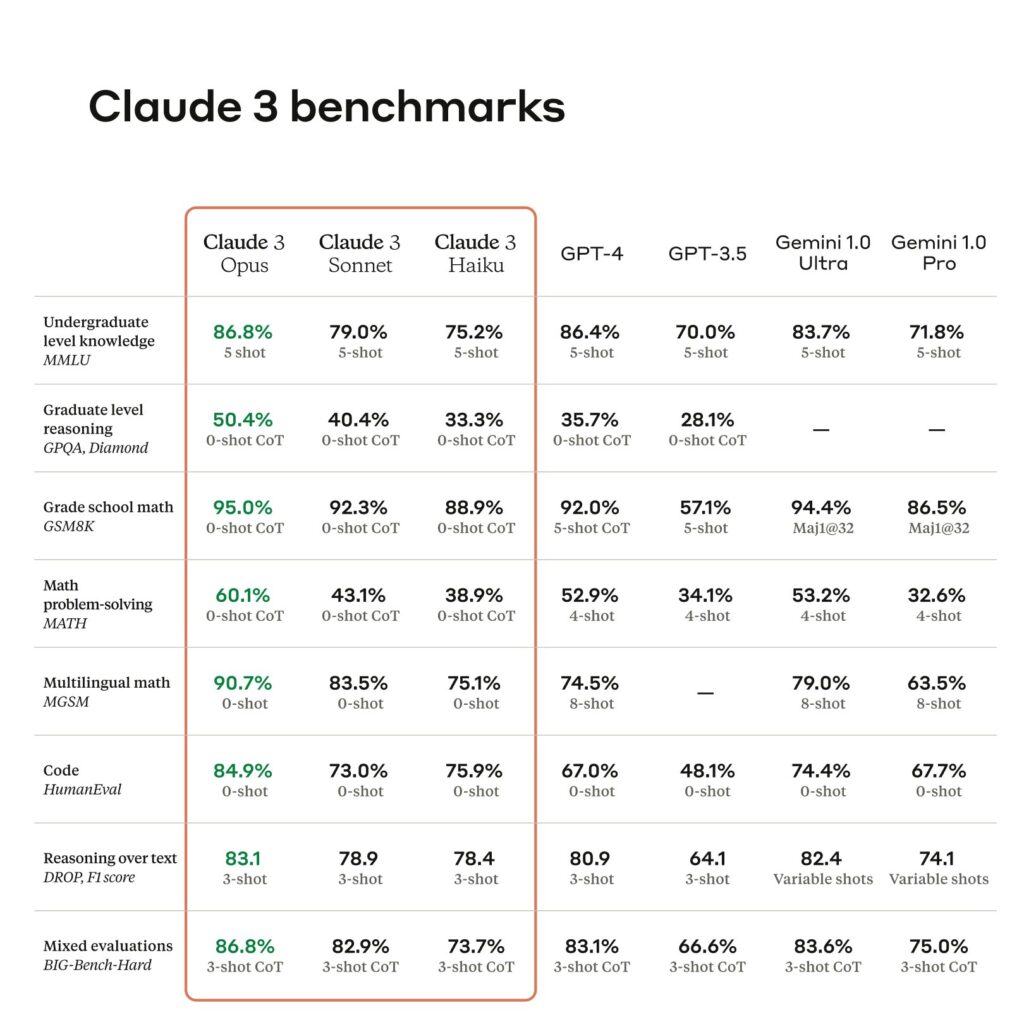
Today, we're announcing Claude 3, our next generation of AI models. The three state-of-the-art models—Claude 3 Opus, Claude 3 Sonnet, and Claude 3 Haiku—set new industry benchmarks across reasoning, math, coding, multilingual understanding, and vision.
-
Future of Generative AI and Non-Human Content Production
By
–
Wonder what is coming next in the world of generative AI and production of non-human content? This has some pointers that can inform your decision-making:
-
Google Gemini Advanced: Detailed Tasting Notes Analysis
By
–
From my discussion of Gemini. https://
oneusefulthing.org/p/google-gemin
i-advanced-tasting-notes
… -
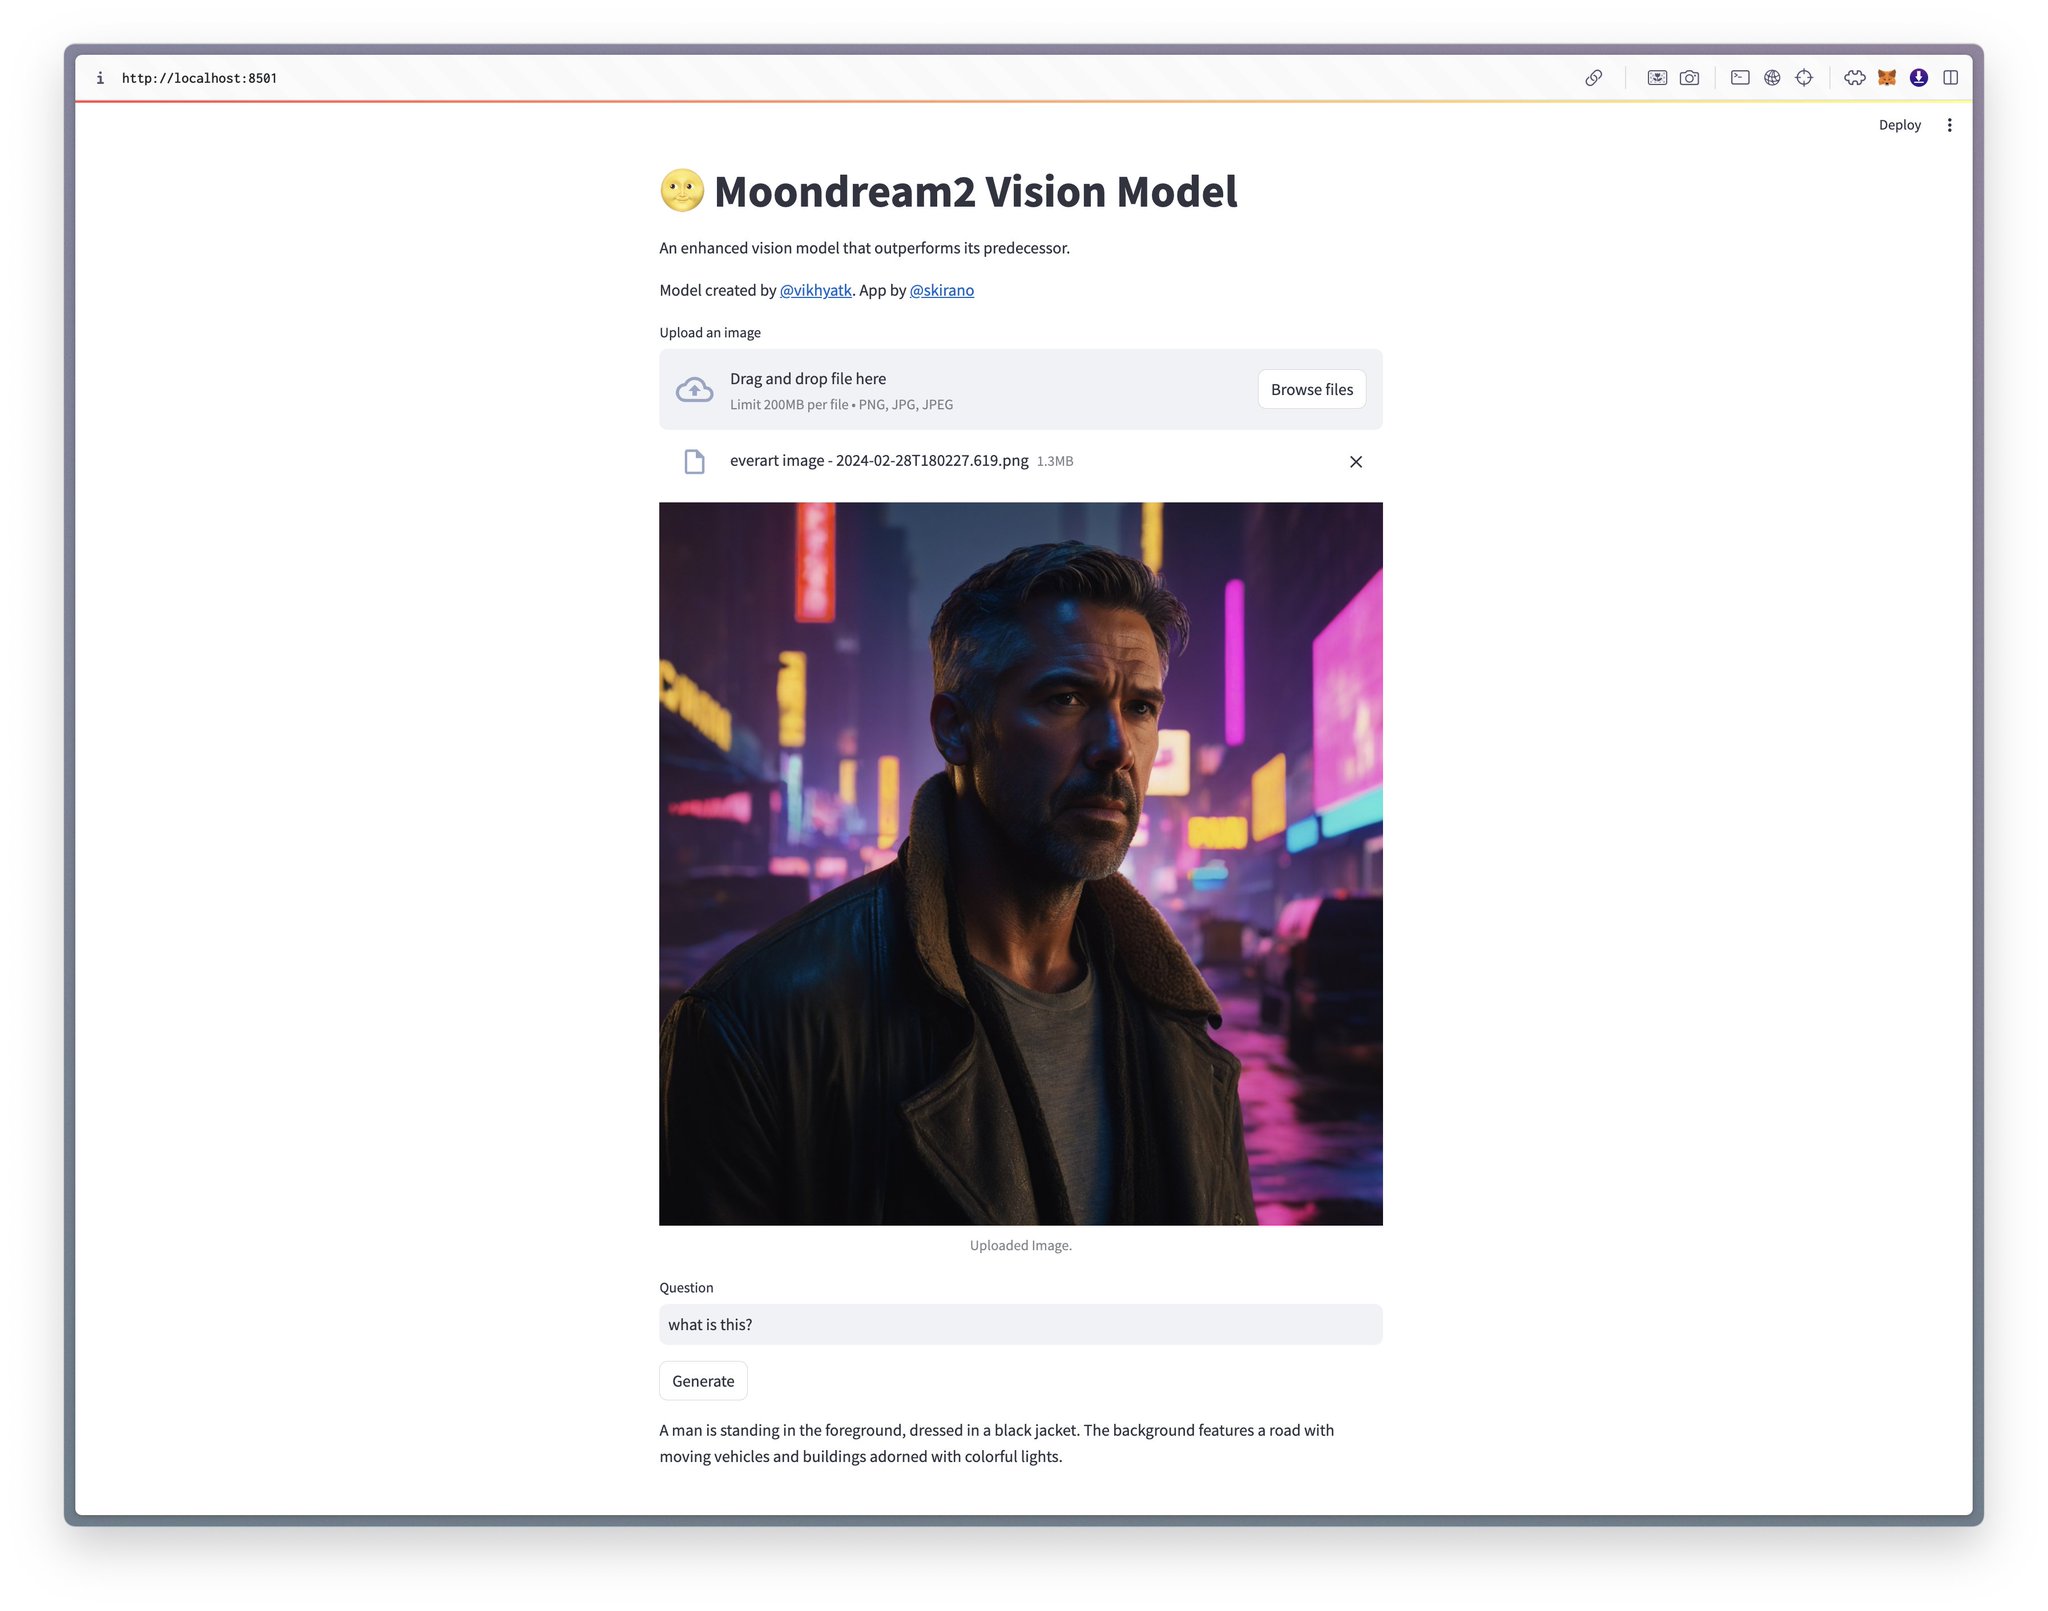
Moondream Streamlit App Updated to Version 2 Model
By
–
My Moondream Streamlit app has been updated to v2 of the model. Incredible work! @vikhyatk
-
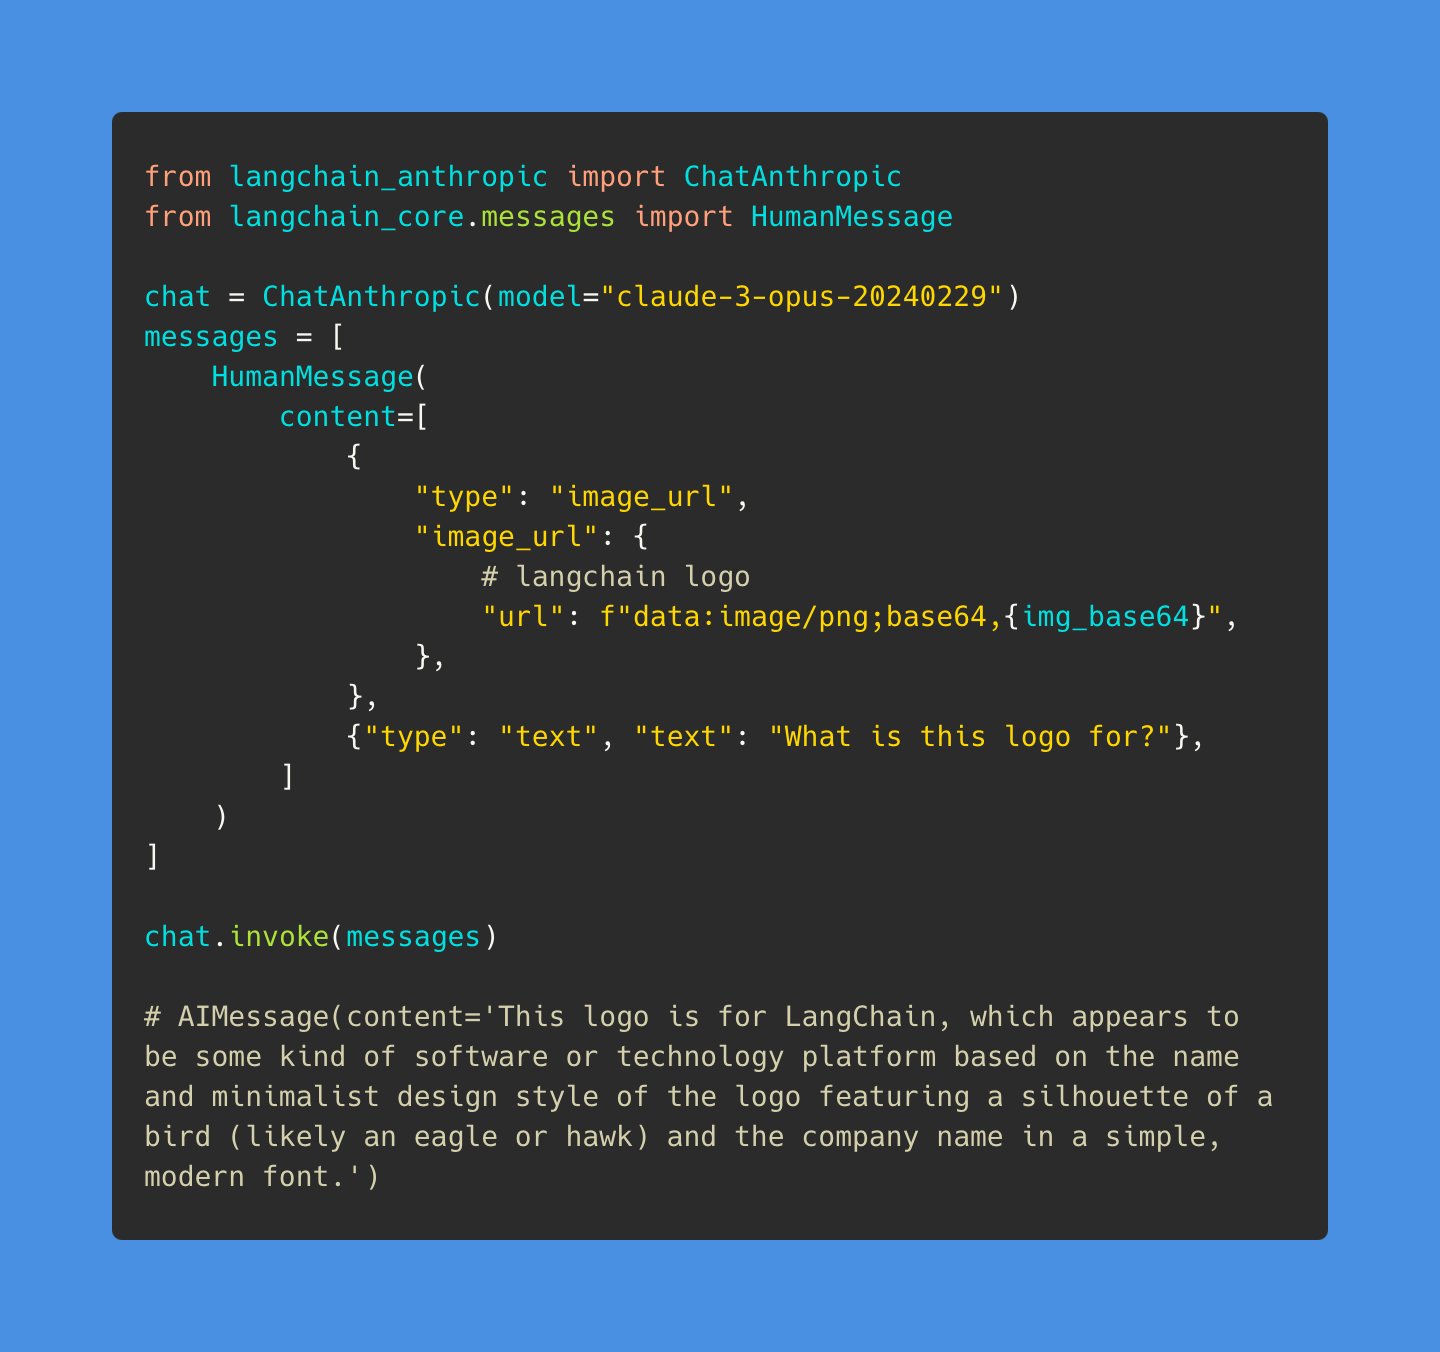
Claude-3 Models Add Vision Capabilities to LangChain
By
–
Anthropic Multimodal Inputs @AnthropicAI
's state-of-the-art new Claude-3 models can reason about images as well as text! We've added support for this awesome new capability in LangChain, allowing you to create vision-based AI apps. Bump to the latest -
Pika Launches Lip Sync Feature for Everyone
By
–
Did someone say ‘Lip Sync is now open to everyone?’ That was us. Just now.
— Pika (@pika_labs) 5 mars 2024
Start talking at https://t.co/nqzjGy82Lx pic.twitter.com/KZVlNJUWRwDid someone say ‘Lip Sync is now open to everyone?’ That was us. Just now. Start talking at http://
pika.art -

ChatGPT Image View Now Includes Prompt Generation Feature
By
–
ICYMI: Now you can open a side tab on the image view to see the prompt which can be used to generate a similar image. Note that this is not a prompt you've been submitting – it is a ChatGPT-generated prompt.