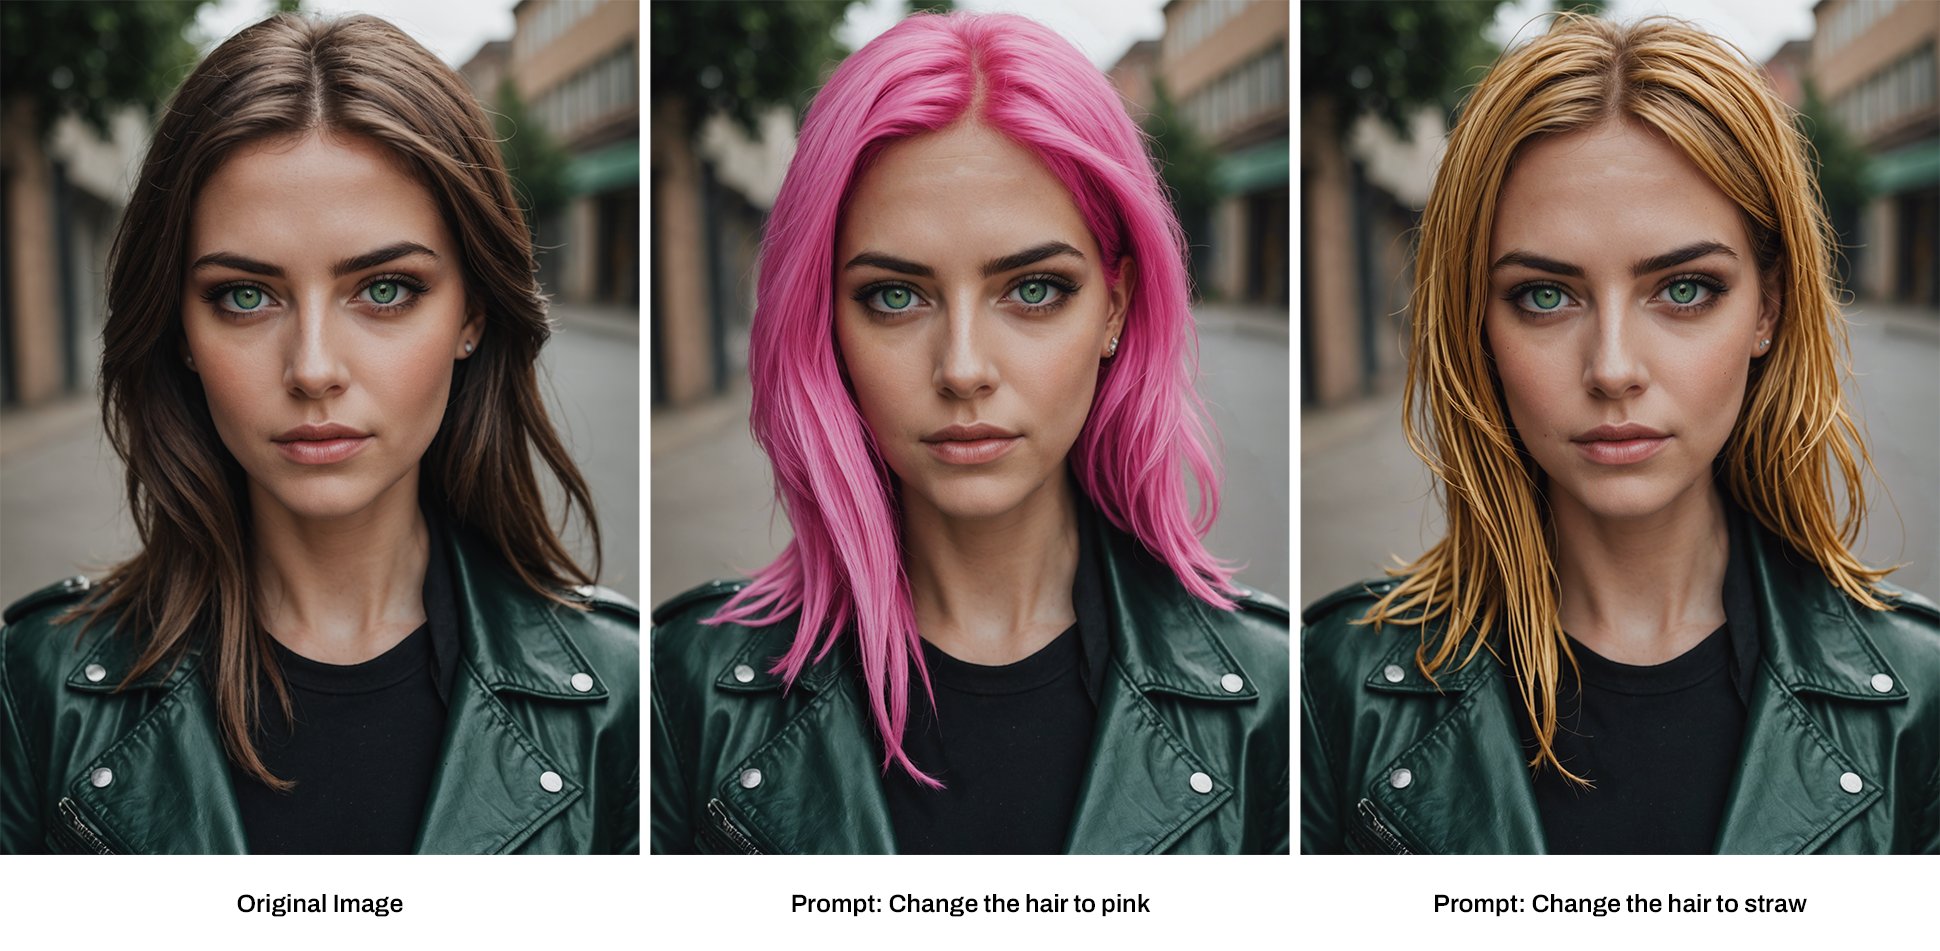
Edit: Intuitively edit images and videos through natural language prompts, encompassing tasks such as inpainting, outpainting, and modification. (4/4)
MULTIMODAL AI
-

Stable Image Core and Diffusion 3 image generation launch
By
–
Generate: Create new, original media from text descriptions using our flagship image service Stable Image Core or our groundbreaking image models including the soon to be released Stable Diffusion 3. (2/4)
-
Gemini 1.5 Million Token Context Window Capabilities
By
–
If you want a hint about the future of AI, it is worth trying Gemini 1.5 with the 1M token context window, now available to everyone, apparently. Some of my experiments: giving it a video and having it figure out a recipe, execute instructions, watching my screen, summarize work
-

ChatGPT iOS App Updated with Enhanced Image Prompting and Downloading
By
–
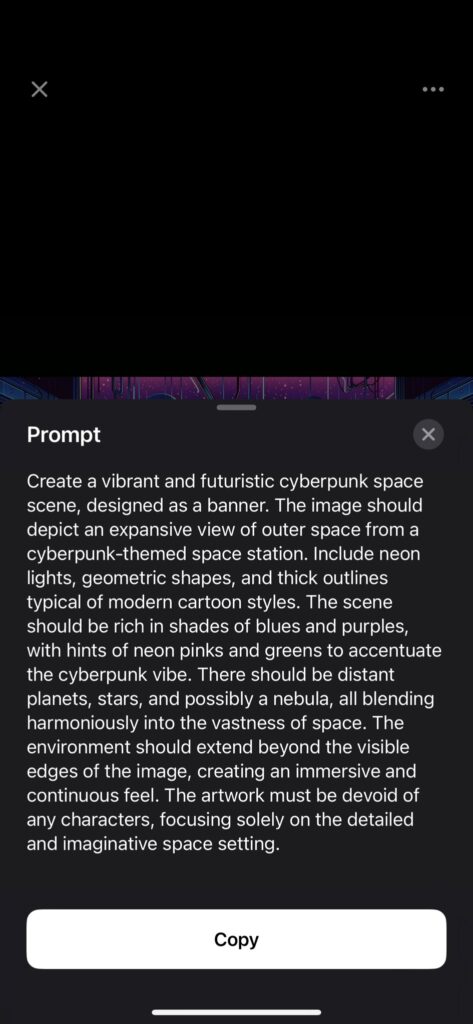
ICYMI: ChatGPT app for iOS got an enhanced image view from where you can copy image prompt. Apart from that, there is a new button for quick image downloading.
-
Foundation Models Learning Biology Fundamentals Make Discoveries
By
–
With vast amounts of data about genes and cells, foundation models are learning the fundamentals of biology. As the models scale up, scientists predict they will start making more profound discoveries. HAI faculty affiliate @jure was quoted in this story:
-
GR00T: General Purpose Foundational Model for Humanoid Robot Learning
By
–
2. Project GR00T: A general purpose foundational model for humanoid robot learning pic.twitter.com/of6AAw4tIM
— Rowan Cheung (@rowancheung) 21 mars 20242. Project GR00T: A general purpose foundational model for humanoid robot learning
-
BAIR Research: Modeling Extremely Large Images
By
–
New BAIR blog post on modeling extremely large images, by @Ritwik_G @JitendraMalikCV @trevordarrell and more!: https://
bair.berkeley.edu/blog/2024/03/2
1/xt/
… -
EverArt AI Achieves Hollywood-Grade People Fine-Tuning Quality
By
–
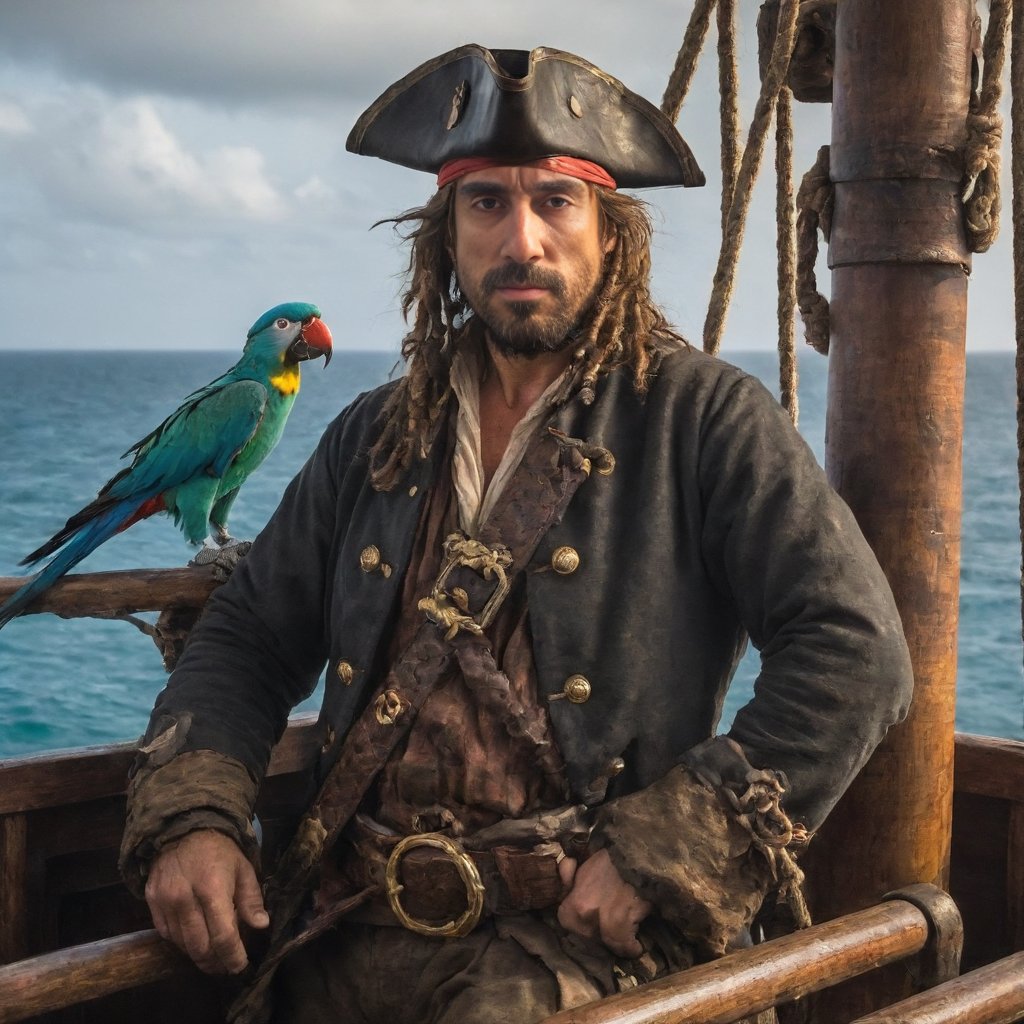
I truly believe @everartai has the best people fine-tuning on the market at the moment. Hollywood grade. Please enjoy a few photos of me as a pirate.
-
Combining 500K Models to Train Foundation Models Efficiently
By
–
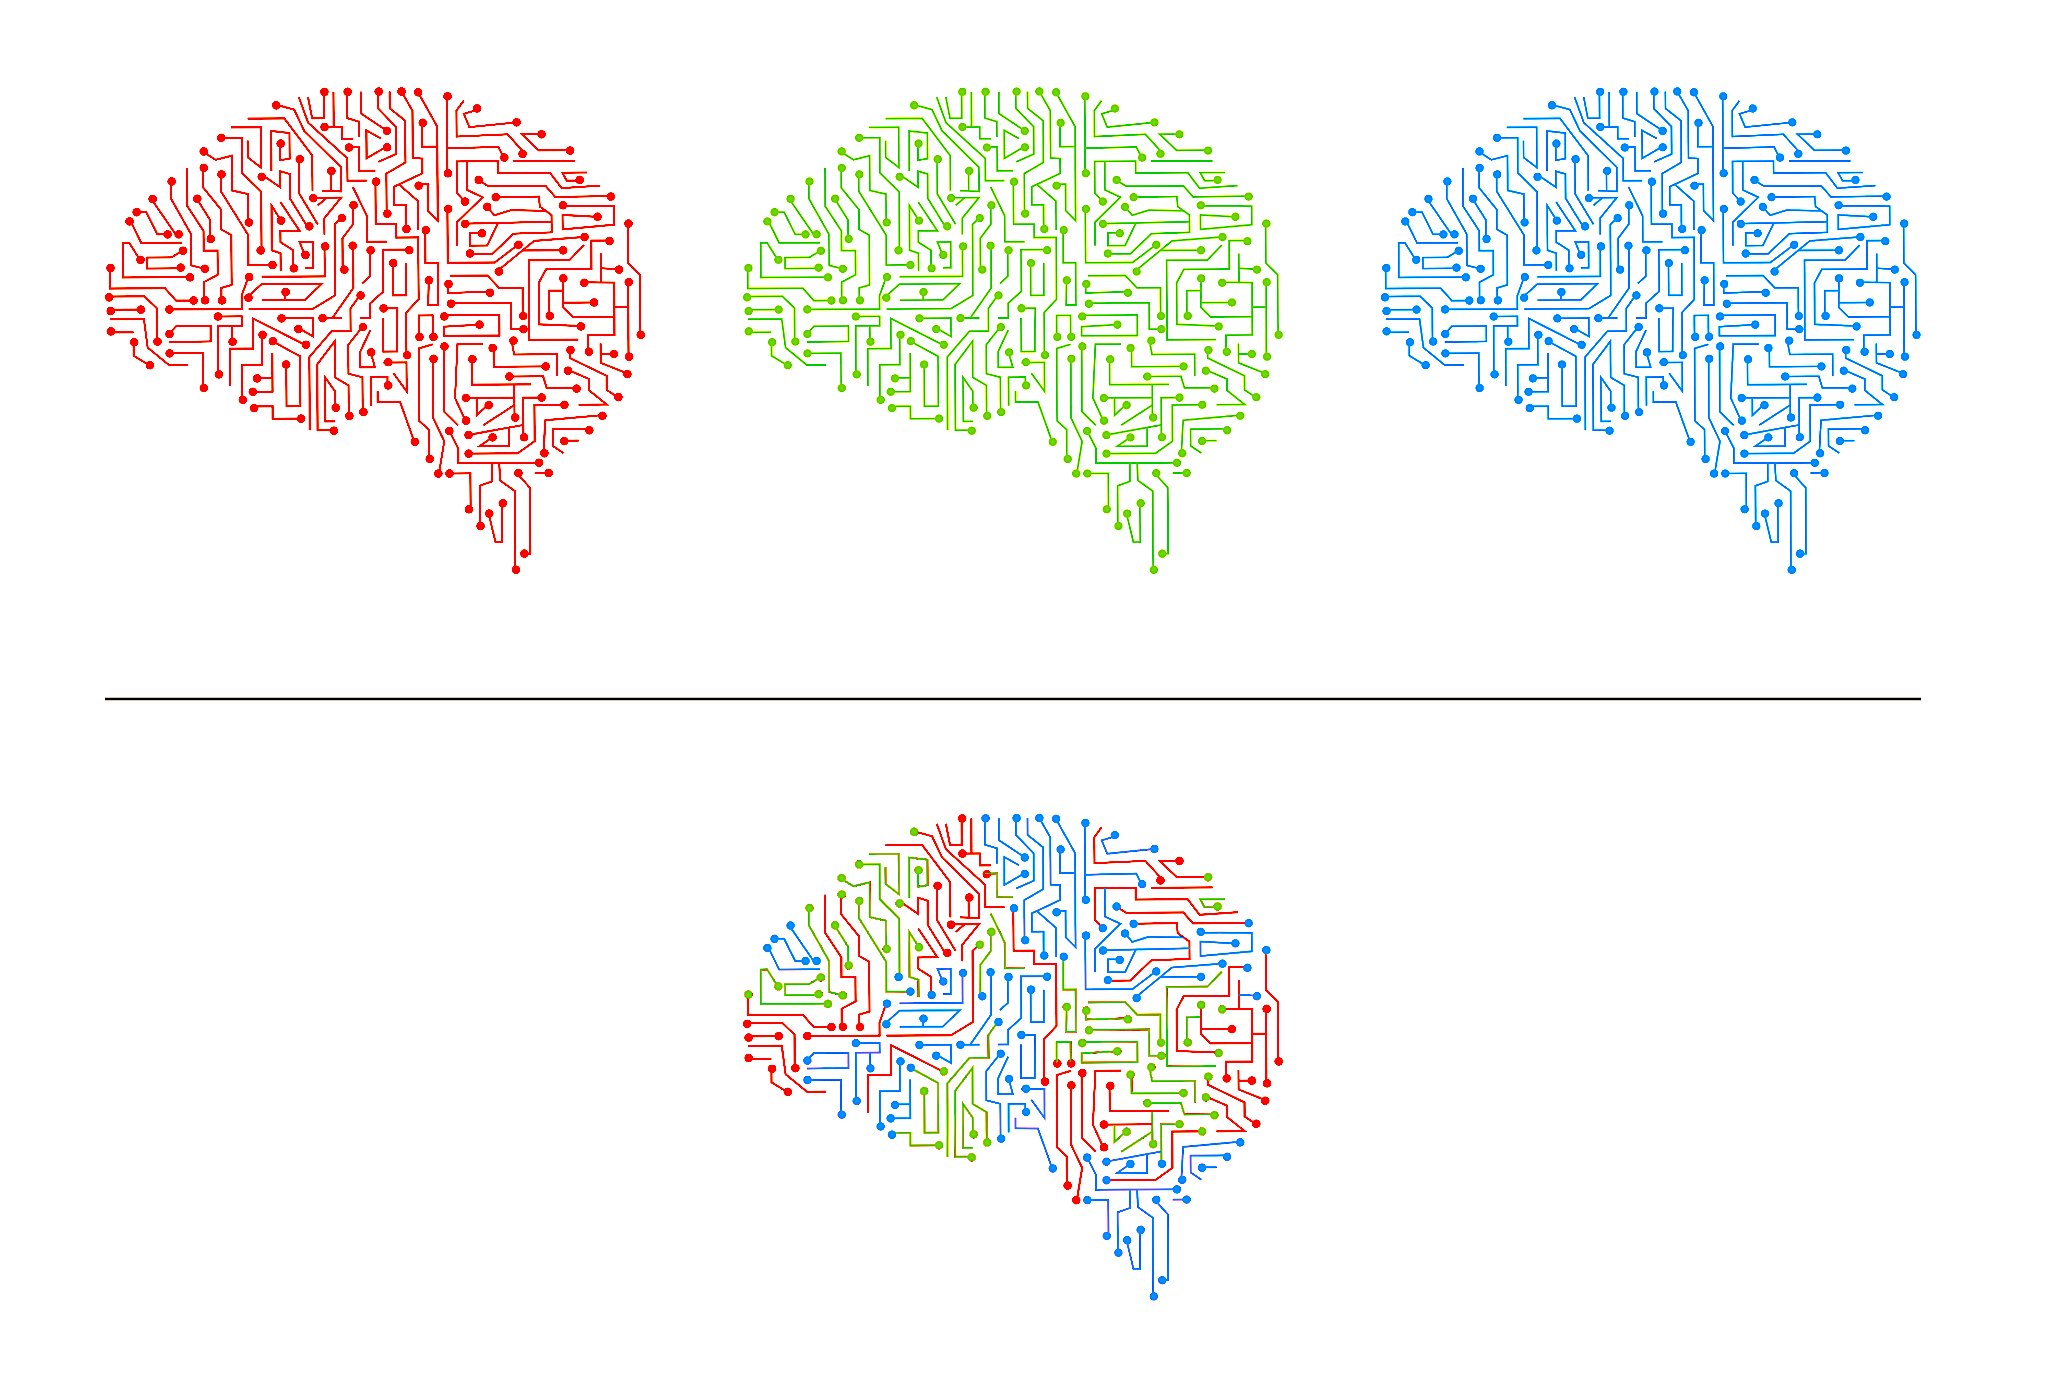
Training foundation models require enormous resources. We can overcome this by working with the vast collective intelligence of existing models. @HuggingFace has over 500k models in dozens of modalities that, in principle, can be combined to form new models with new capabilities!
-
Moving from Large Language Models to Vision Language Models
By
–
https://
drdebashisdutta.com/moving-from-la
rge-language-models-llm-to-vlms-vision-language-models-vlms/
…