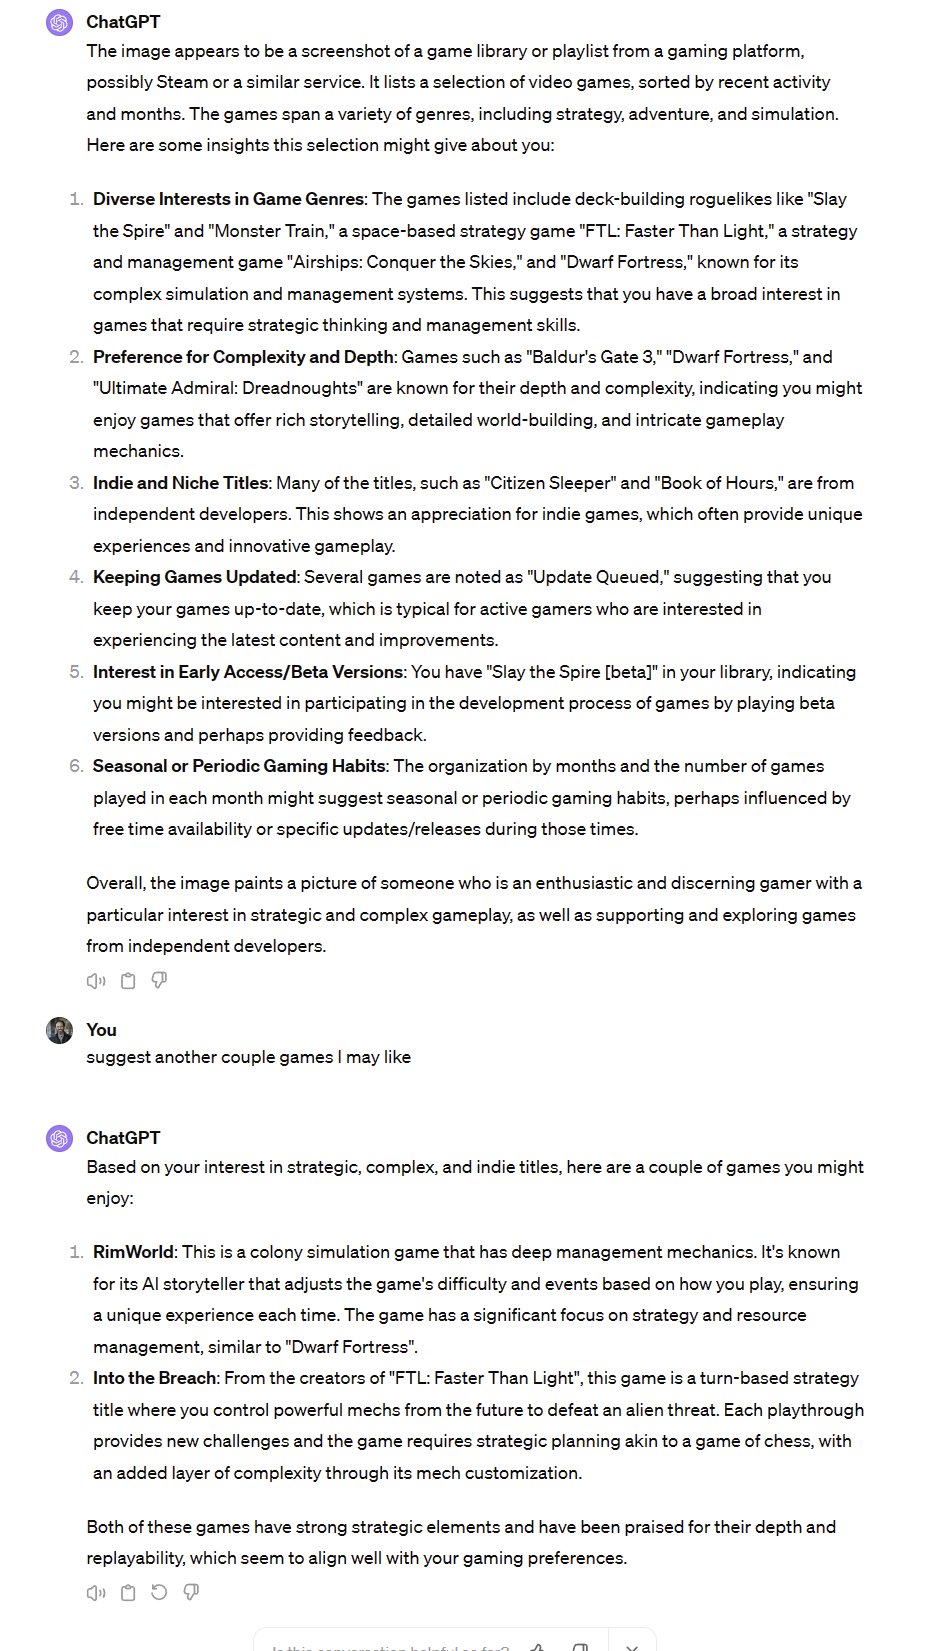
Because AI knows is good at connections and context, it can make reasonable guesses about you from limited data I gave Gemini and GPT-4 a screenshot of my Steam library and got excellent insights on what I might like (Claude 3 isn't internet connected, so doesn't know the games)
MULTIMODAL AI
-
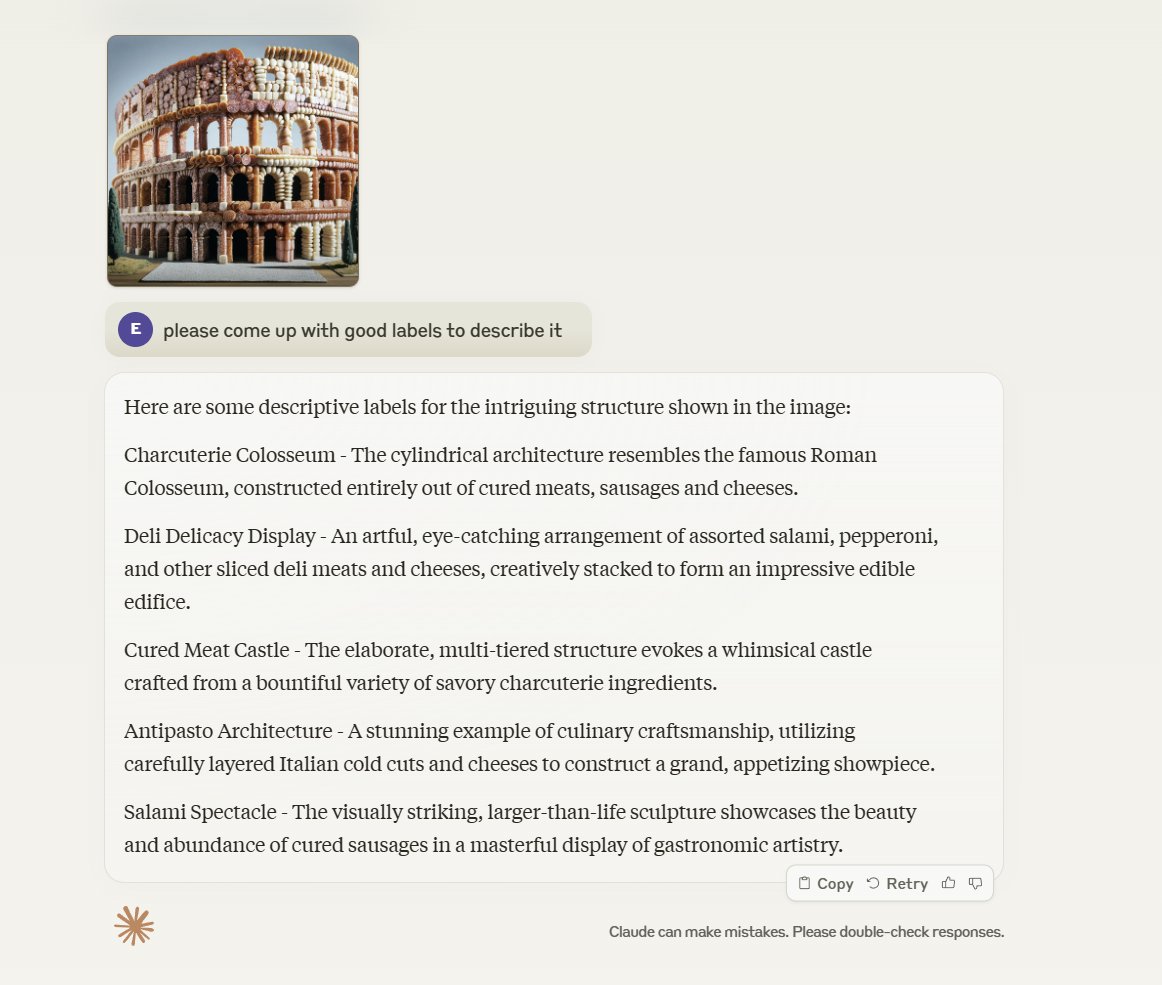
Claude 3 AI Guardrails on Dinosaur Wildlife Interaction Content
By
–
I appreciate Claude 3's ability to roll with whatever weird AI generated images I give it …until you hit its odd guardrails around human-wildlife interaction: "the idea of casting dinosaurs, especially predatory ones, in an action film alongside humans raises ethical concerns"
-
Meta’s SceneScript enables 3D scene reconstruction for metaverse
By
–
Meta introduces SceneScript, a novel approach for 3D scene reconstruction
— AI Breakfast (@AiBreakfast) 22 mars 2024
You will be able to upload your own environment to the metaverse: pic.twitter.com/4DNNR0AJuhMeta introduces SceneScript, a novel approach for 3D scene reconstruction You will be able to upload your own environment to the metaverse:
-
Character AI Launches Voice Creation Feature with 10 Seconds Audio
By
–
Character AI introduced a new feature allowing users to add and create voices for their characters with just 10 seconds of audio. The voices add to each characters unique personality and are quite realistic, imo.
-
Open Interpreter Launches 01 Light Portable AI Voice Interface
By
–
Open Interpreter unveiled the 01 Light.
— Rowan Cheung (@rowancheung) 22 mars 2024
It's a new, portable open-source voice interface that connects to a user’s computer, allowing the AI to control apps, learn skills, and observe screens.pic.twitter.com/5zEKTZqZfyOpen Interpreter unveiled the 01 Light. It's a new, portable open-source voice interface that connects to a user’s computer, allowing the AI to control apps, learn skills, and observe screens.
-
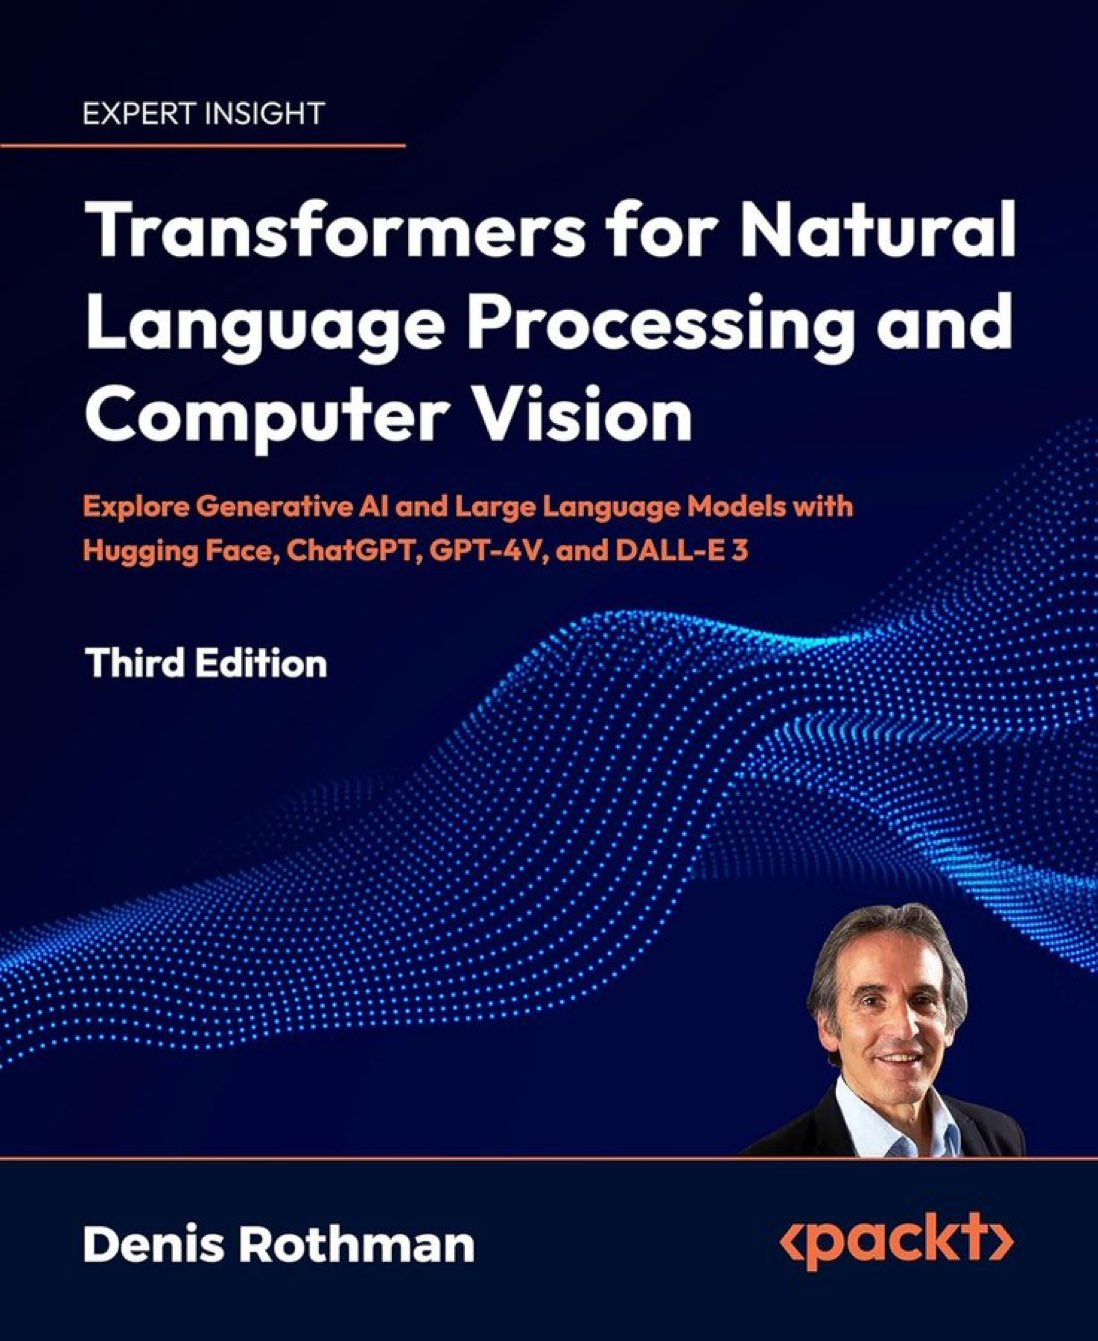
Updated Transformers Book Covers LLMs and Generative AI
By
–
WOW! I have a copy of the updated 3rd Edition of this book: http://
amzn.to/3TkBknI
"Transformers for Natural Language Processing and Computer Vision: Explore #GenerativeAI and Large Language Models #LLMs with Hugging Face, ChatGPT, GPT-4V, and DALL-E 3" Huge! 728 pages of #AI / -
BEHAVIOR-1K Benchmark for Embodied AI Robotics Research
By
–
As a reminder, BEHAVIOR-1K is a benchmark for embodied AI and robotics research with realistic simulation of 1,000 diverse household activities grounded in human needs. 2/n
Website: https://
behavior.stanford.edu
Paper: -
BEHAVIOR-1K Full Release Announced at NVIDIA GTC2024
By
–
One year ago, we first introduced BEHAVIOR-1K, which we hope will be an important step towards human-centered robotics. After our year-long beta, we’re thrilled to announce its full release, which our team just presented at NVIDIA #GTC2024. 1/n pic.twitter.com/z313Wwvrzr
— Fei-Fei Li (@drfeifei) 22 mars 2024One year ago, we first introduced BEHAVIOR-1K, which we hope will be an important step towards human-centered robotics. After our year-long beta, we’re thrilled to announce its full release, which our team just presented at NVIDIA #GTC2024. 1/n
-
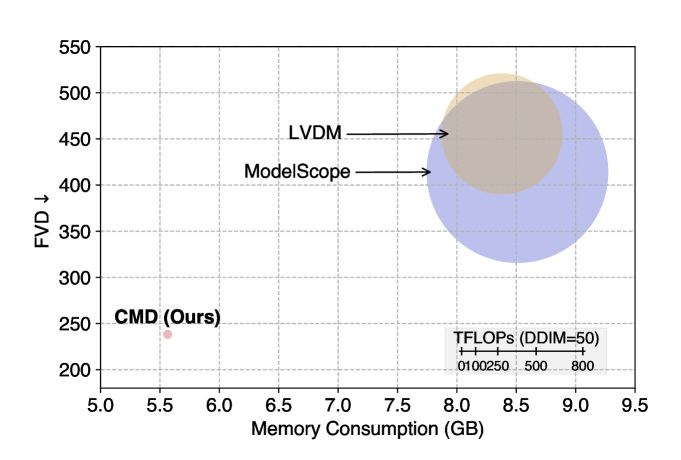
Efficient Video Diffusion Model with Motion Latent Representation
By
–
Thank you @_akhaliq for showcasing our paper on efficient video diffusion. We propose content-motion latent diffusion model – an efficient video model that utilizes pretrained image diffusion models and a low-dimensional motion latent representation for video generation
-
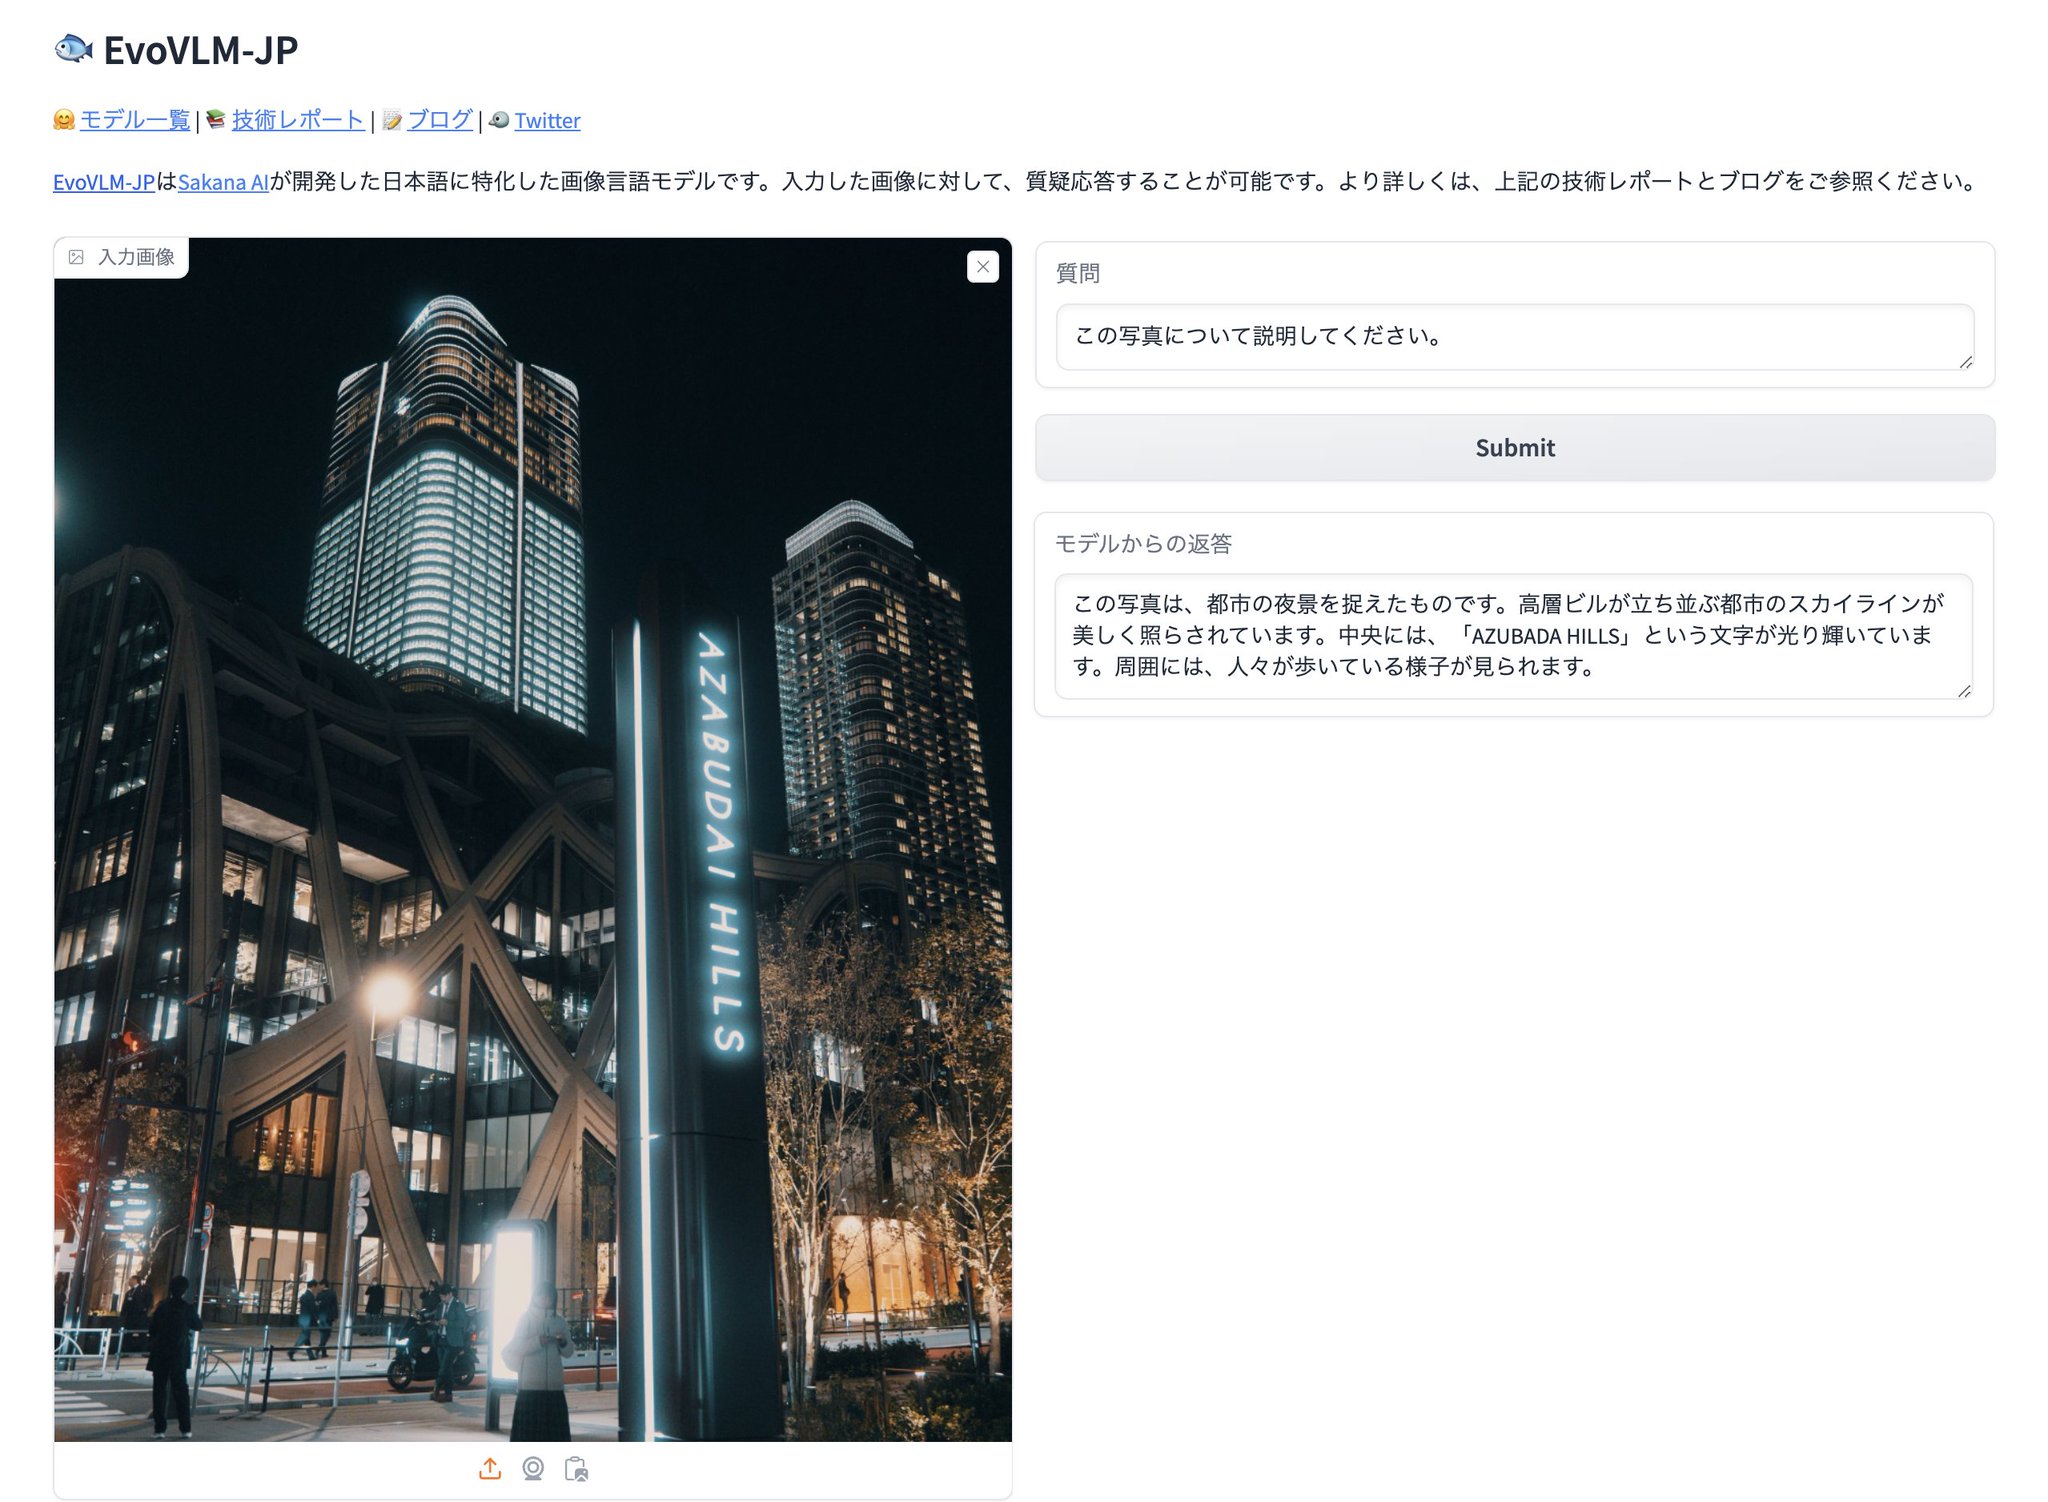
EvoVLM-JP: Advanced Japanese Vision-Language Model Demo
By
–
進化的モデルマージにより試作した日本語画像言語モデル「EvoVLM-JP」は以下からご自身の画像ですぐお試し頂けます。https://t.co/cAHls3fJ0u
— Sakana AI (@SakanaAILabs) 22 mars 2024
画像と質問文を送信するとモデルが回答します。成功例か失敗例かに関わらず、興味深い例が出来ましたらこのツイートへのリプライで是非ご共有下さい。🤗 https://t.co/VBi1iuhWZO pic.twitter.com/x5nUtPZt8t進化的モデルマージにより試作した日本語画像言語モデル「EvoVLM-JP」は以下からご自身の画像ですぐお試し頂けます。 https://
huggingface.co/spaces/SakanaA
I/EvoVLM-JP
… 画像と質問文を送信するとモデルが回答します。成功例か失敗例かに関わらず、興味深い例が出来ましたらこのツイートへのリプライで是非ご共有下さい。