Multimodal Large Language Models! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode https://
geni.us/Multimodal-LLMs
MULTIMODAL AI
-
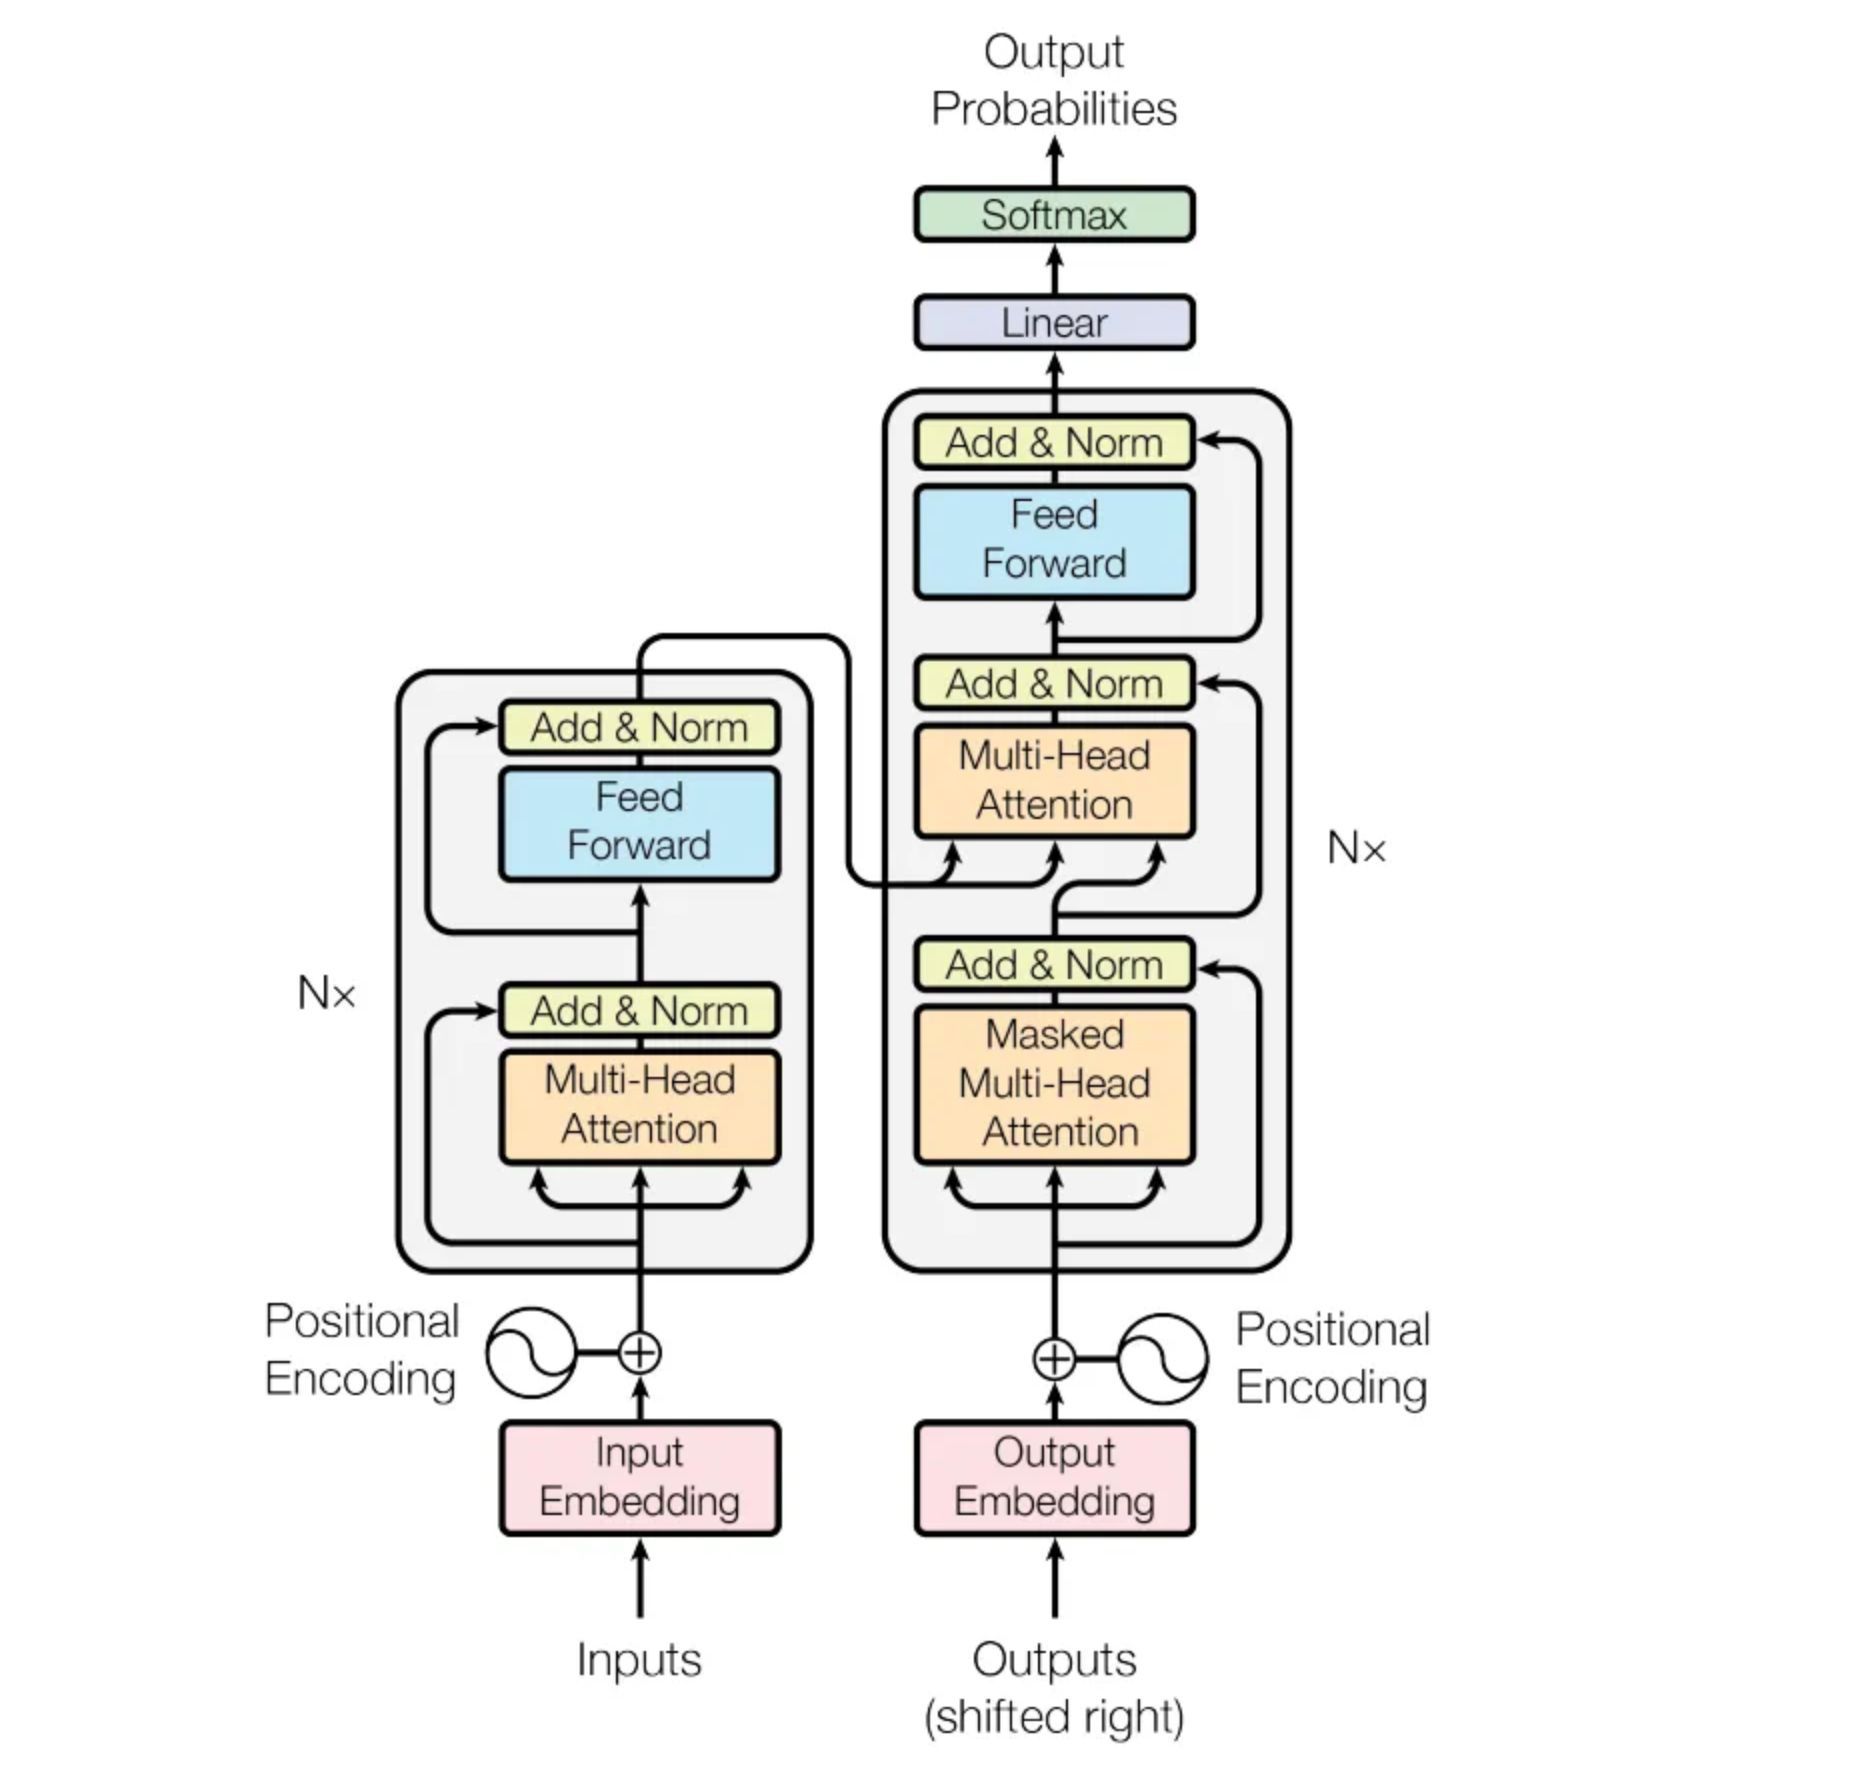
Multimodal Large Language Models: Key Technologies and Frameworks
By
–
-
Voice Notes App Transcribes to Podcast-Like Format
By
–
It’s so interesting how it listens like a podcast when it plays through. Even though it’s just threaded voice notes to each other with pretty accurate transcription. pic.twitter.com/RN3qSPtkTh
— 🖤 Christine (@christinelu) 20 avril 2024It’s so interesting how it listens like a podcast when it plays through. Even though it’s just threaded voice notes to each other with pretty accurate transcription.
-
GPT-5 Predictions: Multi-modal generation from any input with precise refinement
By
–
Alright, GPT-5 Predictions: Generate text, images, video, 3D assets or music FROM text, images, video, or music (basically it can take anything as input, and produce any medium for output depending on the prompt direction) with much more precise refinement process to massage an
-
Stable Diffusion 3 and SD3 Turbo Now Available on Poe
By
–
Stable Diffusion 3 and the faster SD3 Turbo are hosted by @FireworksAI_HQ and available at SD3 https://
poe.com/StableDiffusio
n3
…, and SD3-Turbo https://
poe.com/SD3-Turbo, and across all Poe apps. We look forward to seeing what you create! (2/2) -
Stable Diffusion 3 Now Available on Poe Platform
By
–
New: Stable Diffusion 3 is on Poe! SD3 is the latest image generation model from Stability, and it is especially good at typography and prompt accuracy. It understands complex prompts, supports multiple languages, and has improved spelling over SDXL. (1/2)
-
Wayfair Improves Model Accuracy 20+ Points Using Snorkel
By
–
If you missed our session with Wayfair and Google Cloud at Google Next '24… Register for our webinar on April 25 to learn how Wayfair leveraged Snorkel to label millions of images in months and improved the accuracy of their models by 20+ points. https://
buff.ly/4aXqt9w -
Speech AI: Core Concepts, Applications, and Future Growth
By
–
Looking to deepen your understanding of Speech AI? Sirisha Rella, the Technical Product Marketing Manager at Nvidia, explores Speech AI: shedding light on its core concepts, applications, and potential for future growth. Watch: https://
buff.ly/4aDLLcf -
Meta Llama 3, VASA-1, GPT-4 advances and new AI jobs
By
–
Top stories in AI today: -Meta releases next-gen Llama 3
-Microsoft’s VASA-1 brings still photos to life
-Personalize the new version of GPT-4 Turbo
-GPT-4 nears expert eye doctor analysis
-6 new AI tools & 4 new AI jobs Read more: http://
therundown.ai/p/metas-llama-
3-is-here
… -
Microsoft’s VASA-1: Real-Time Lifelike Audio-Driven Talking Faces
By
–
Microsoft publishes paper on VASA-1: Lifelike Audio-Driven Talking Faces Generated in Real Time
— AI Breakfast (@AiBreakfast) 19 avril 2024
VASA is capable of generating a large spectrum of expressive facial nuances and natural head motions
It can handle long-form audio and stably output seamless talking face videos: pic.twitter.com/FiBb11G1ruMicrosoft publishes paper on VASA-1: Lifelike Audio-Driven Talking Faces Generated in Real Time VASA is capable of generating a large spectrum of expressive facial nuances and natural head motions It can handle long-form audio and stably output seamless talking face videos:
