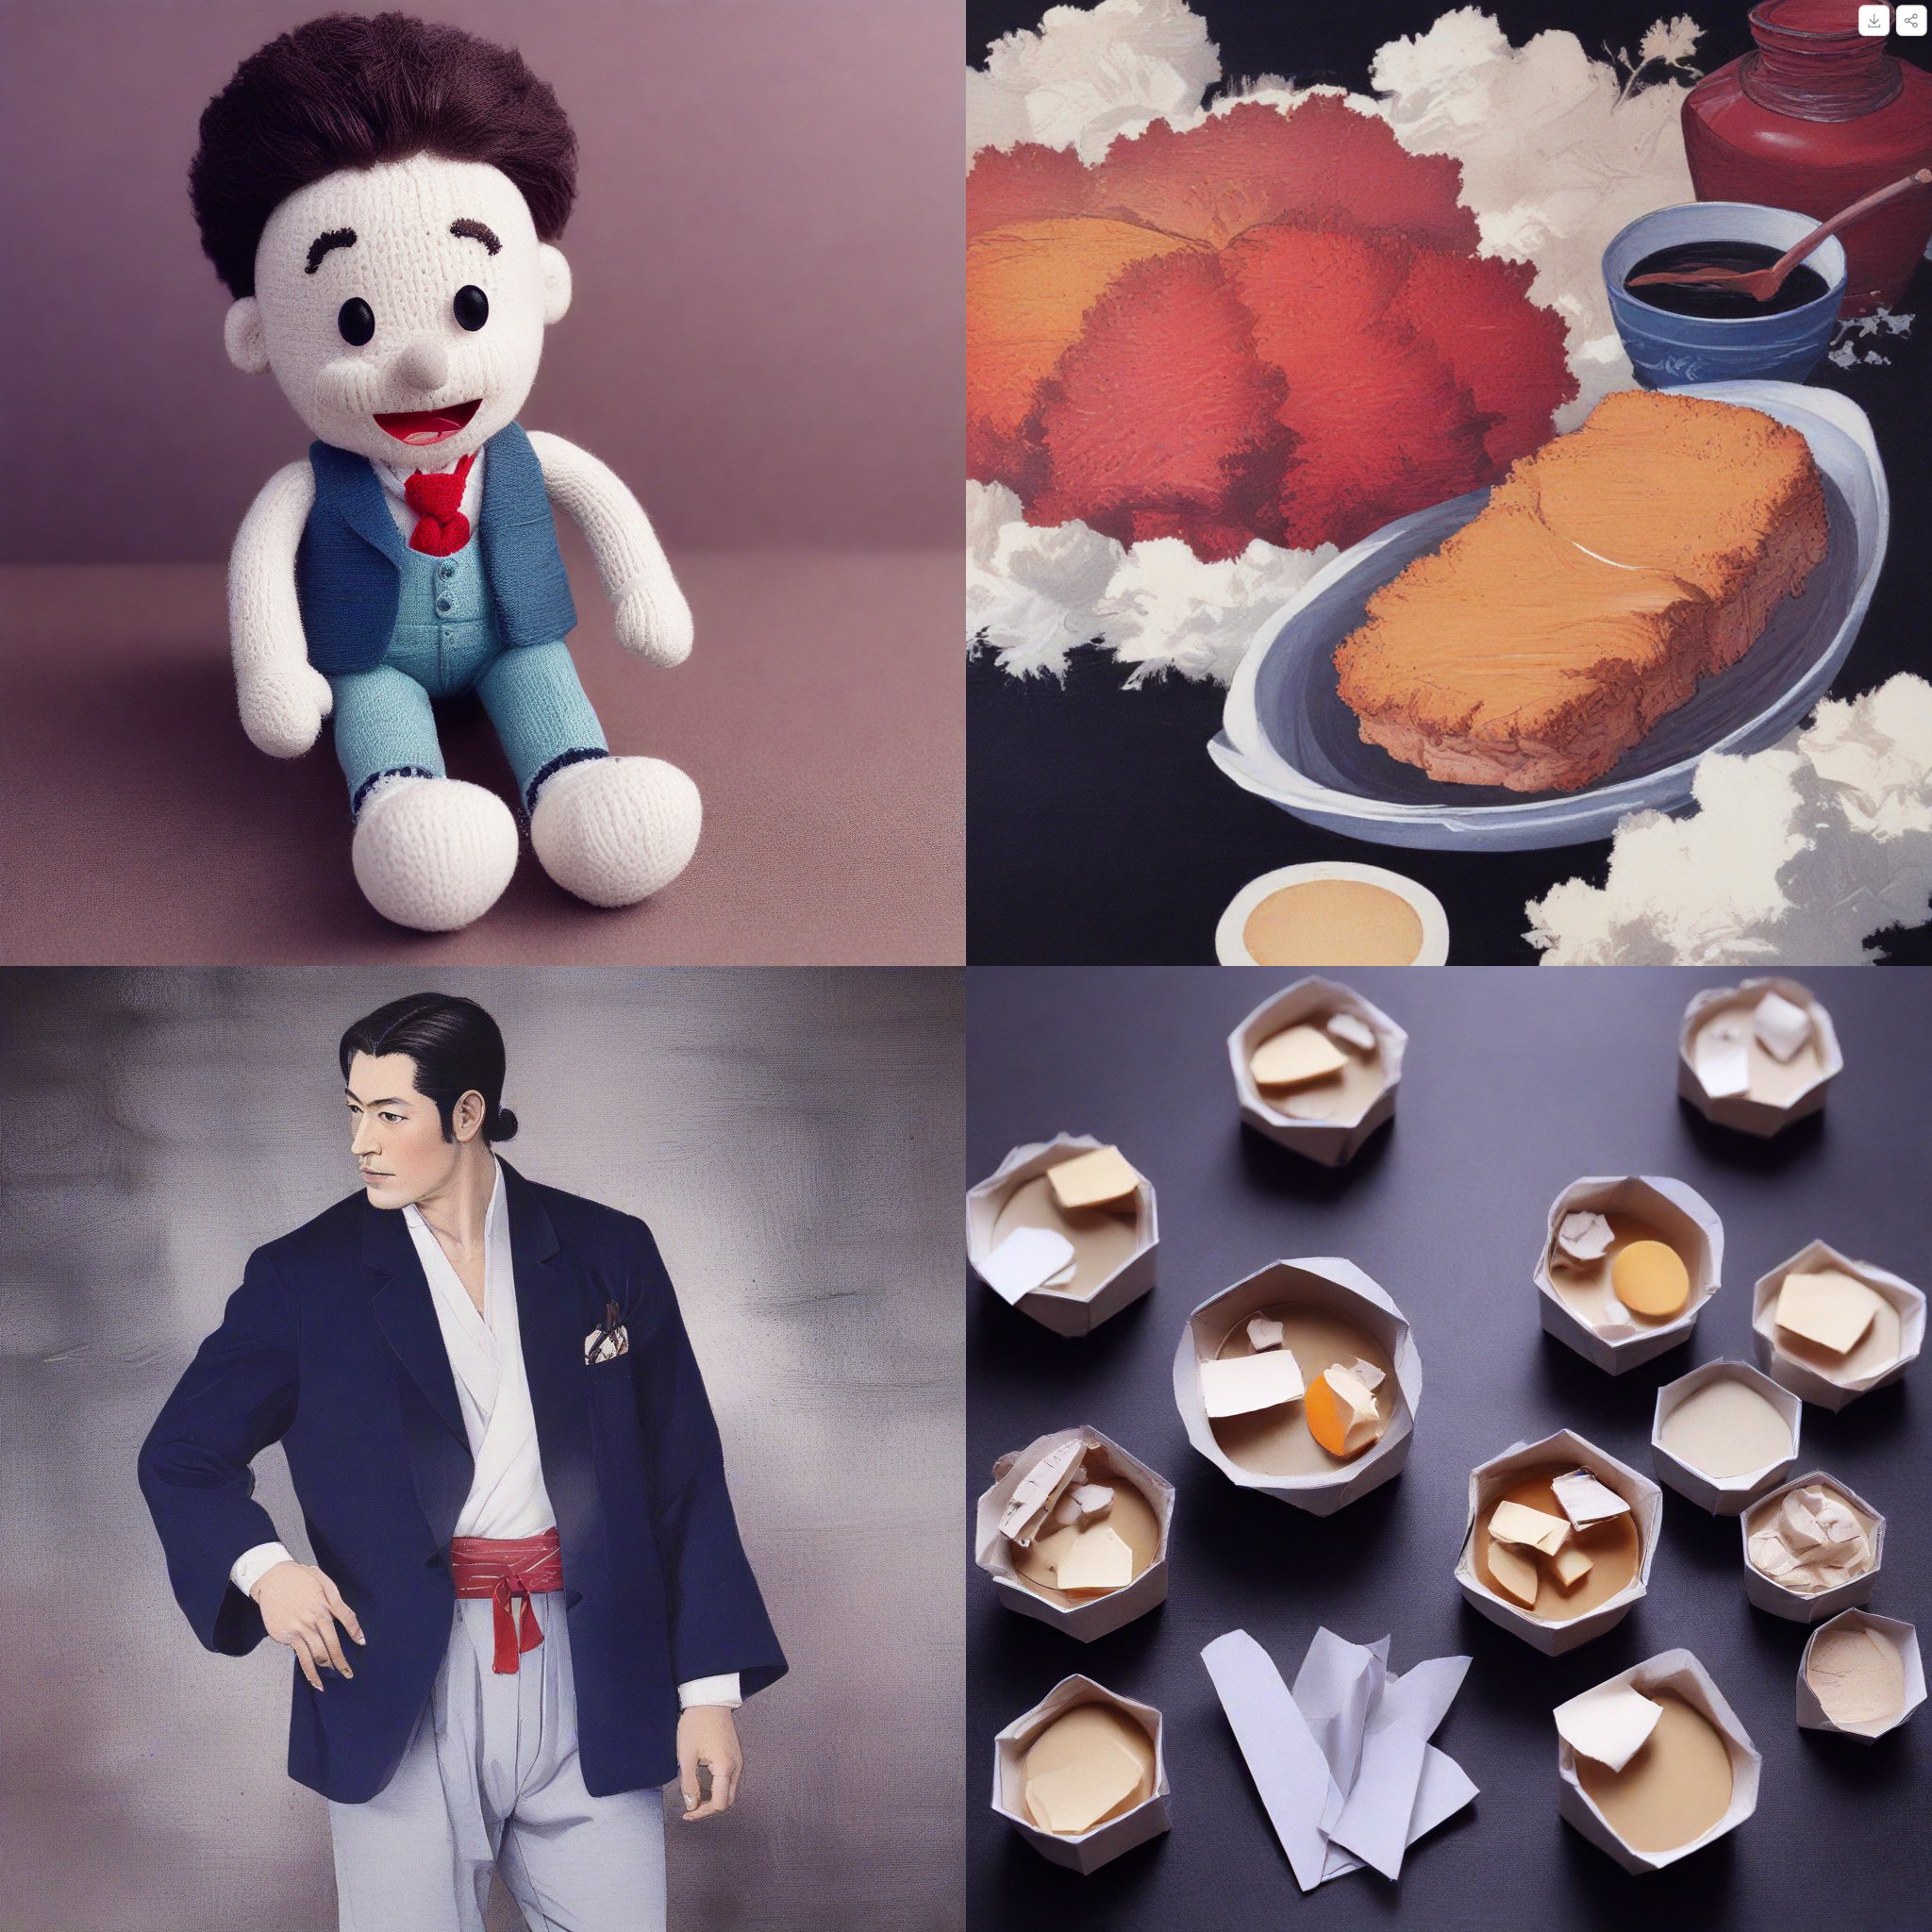
プロンプト: 「お笑い芸人、編みぐるみ。」
「美味しいカツカレー、浮世絵。」
「江戸時代メンズスーツ、最高品質の浮世絵。」
「折り紙味噌汁。」 ぜひお試しください! → https://
huggingface.co/spaces/SakanaA
I/EvoSDXL-JP
…
MULTIMODAL AI
-
EvoSDXL-JP: Japanese Creative AI Image Generation Model
By
–
-
Sakana AI Releases EvoSDXL-JP Image Generation Model
By
–
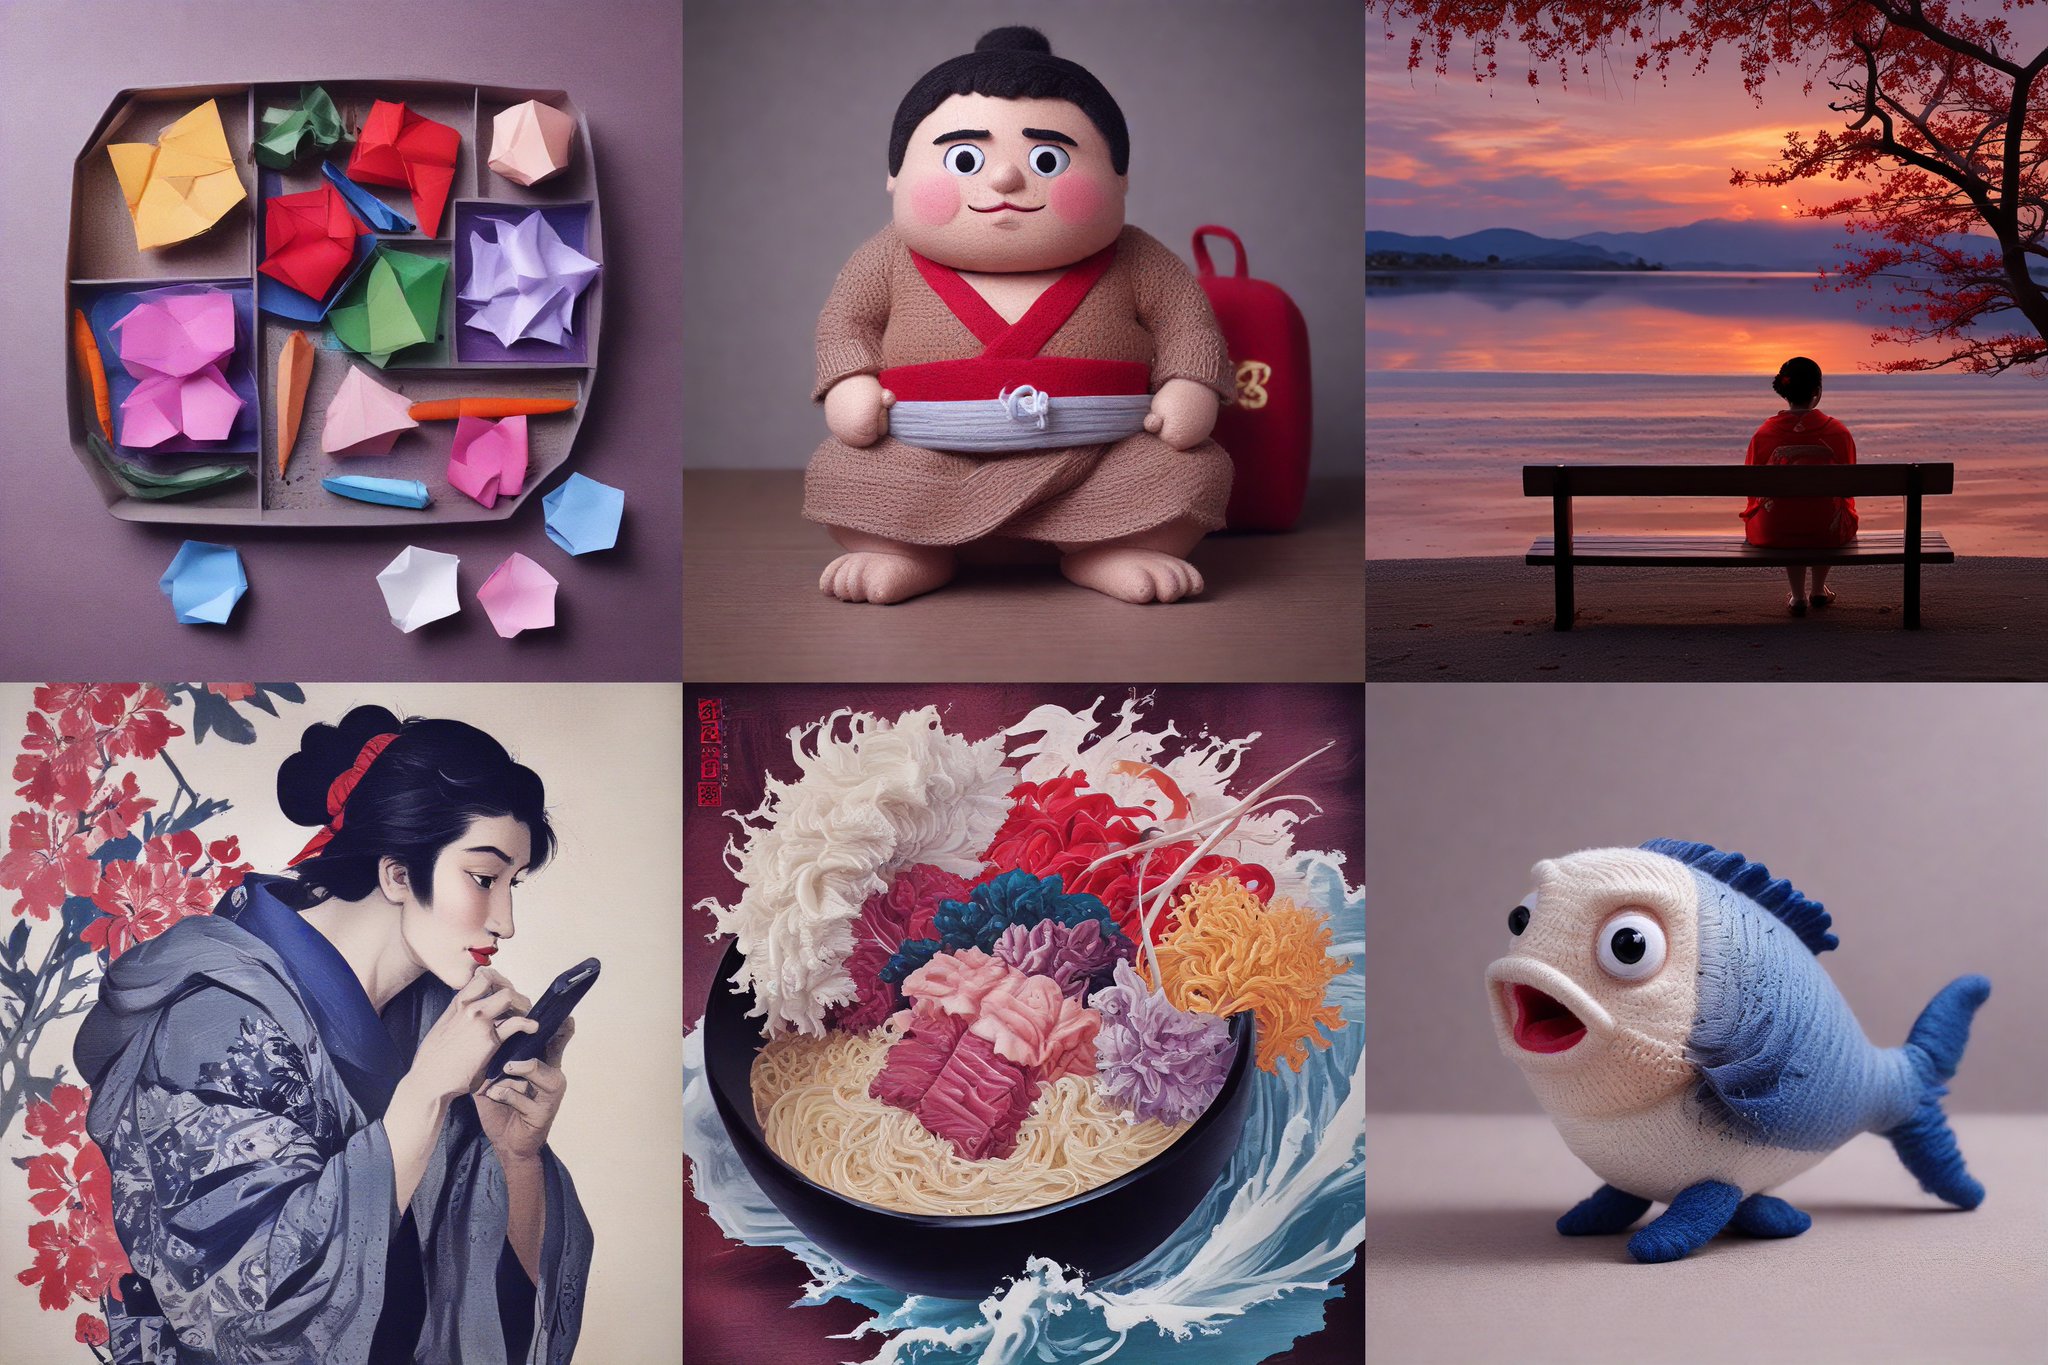
We have released "EvoSDXL-JP," an image generation model constructed using the "Evolutionary Model Merging" proposed by Sakana AI. The constructed model supports Japanese and can generate images 10 times faster than conventional Japanese models. Blog → https://
sakana.ai/evosdxl-jp -
Gaussian Splats Transform Movie Scenes Into Navigable 3D Experiences
By
–
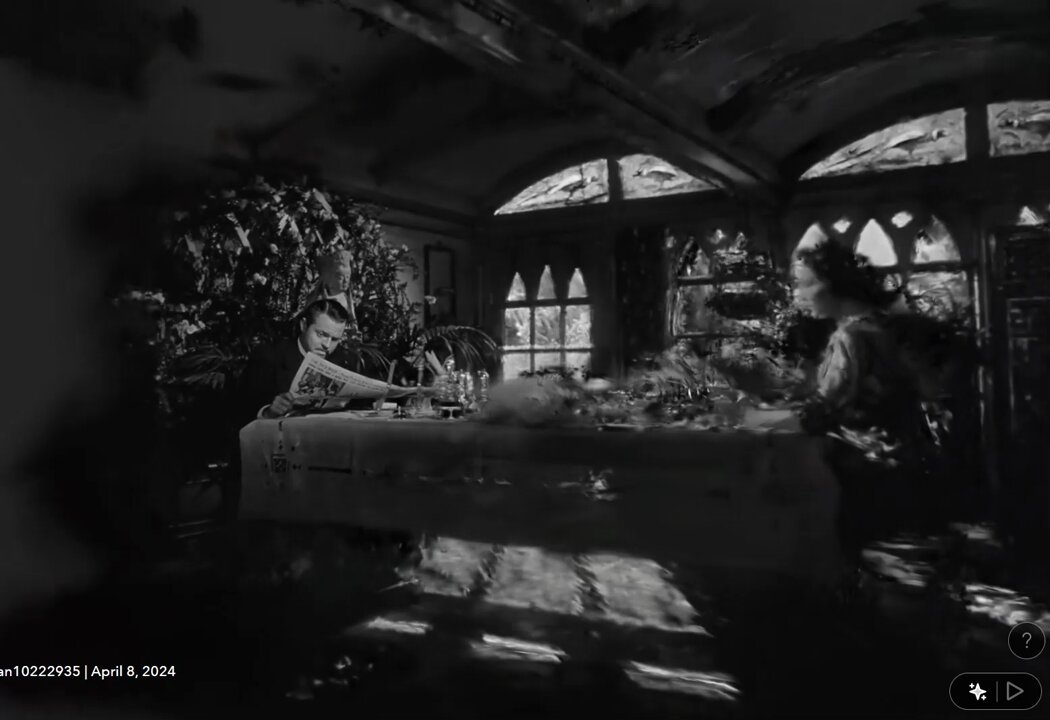
Reddit has a thread of famous movie scenes turned into Gaussian Splats, a way of converting a 2D image taken from multiple points of view into a 3D one.
— Ethan Mollick (@emollick) 22 avril 2024
You can navigate through them, up to a point. I can finally play Citizen Kane as the first person shooter it was meant to be. pic.twitter.com/SCmNfwF0rfReddit has a thread of famous movie scenes turned into Gaussian Splats, a way of converting a 2D image taken from multiple points of view into a 3D one. You can navigate through them, up to a point. I can finally play Citizen Kane as the first person shooter it was meant to be.
-

Gato: Multimodal LLM Pioneer for Robotics Development
By
–
Fully agree that multimodal LLMs are the solution to robotics. This is why my team pioneered Gato (General AgenT One): https://
arxiv.org/pdf/2205.06175
.pdf
… which we built over two years since 2020 to 2022. One of the most important parts of Gato was the data and its engineering pipeline. -
Meta’s AR Assistant and Neural Interface Dataset Development
By
–
Also this dataset reminds me a lot of what Meta is doing to build a real world AR assistant and neural interfaces https://t.co/LX9O7bWH5E
— Bilawal Sidhu (@bilawalsidhu) 21 avril 2024Also this dataset reminds me a lot of what Meta is doing to build a real world AR assistant and neural interfaces
-
3D Tracking and Reflection Rendering in AI Visual Systems
By
–
3d tracking goes a long way — nice touch emulating the reflections on the table
-
Non-invasive neural interfaces: wearable and in-ear designs v1
By
–
A wrist wearable plus one of these in-ear designs is right on the money for a pretty epic v1 of non invasive neural interfaces
-
Multimodal World Models: The Future of Grounded AI Systems
By
–
How to attain Multimodal World Models is a great open question in AI. The solutions will likely lead to more grounded models that interact better with people and make better physics predictions. Hopefully, they will enable scientific generalisation, but this too I feel is an open
-
Claude 3 Opus Extracts Structured Data from Images Demo
By
–
Mind-blowing demo of #Claude3 Opus that can now pull structured data straight from images! Most of the LLM implementation is handled by this script from @timpaul
: → https://
github.com/timpaul/form-e
xtractor-prototype/blob/main/data/extract-form-questions.json
… -
Groq Compiler Supports Hundreds of Models Beyond LLMs
By
–
No, we actually have hundreds of models built into the compiler and we've done demos with computer vision, audio, speech to text, stylegan and more. We also have national labs customers running GNNs, RNNs, and custom proprietary models. There's lots more coming, stay tuned.