Awesome models and datasets released by our friends at @DbrxMosaicAI Not only is this a large openly licensed image-text pair dataset (~70M images), it is also the largest dataset hosted on the Hugging Face Hub
MULTIMODAL AI
-
Google Gemini 1.5 Pro and Flash Now Available on Poe
By
–
You can now build prompt and server bots using Gemini 1.5 Pro and Gemini 1.5 Flash on Poe! These state-of-the-art multimodal models from Google can handle context windows up to 1 million tokens, enabling you to create highly specialized bots with long context understanding. pic.twitter.com/0pUsArgZOo
— Poe (@poe_platform) 16 mai 2024You can now build prompt and server bots using Gemini 1.5 Pro and Gemini 1.5 Flash on Poe! These state-of-the-art multimodal models from Google can handle context windows up to 1 million tokens, enabling you to create highly specialized bots with long context understanding.
-

ZeroGPU Infrastructure Success at Sakana AI Labs
By
–
ZeroGPU is a fantastic example of great AI infrastructure developed by @HuggingFace
. At @SakanaAILabs we’ve already been using it to showcase models like EvoVLM and EvoSDXL and it works like a charm. -
Google and OpenAI Release Major Model Upgrades
By
–
This week, Google announced a doubling of Gemini Pro 1.5's input context window from 1 million to 2 million tokens, and OpenAI released GPT-4o, which generates tokens 2x faster and 50% cheaper than GPT-4 Turbo and natively accepts and generates multimodal tokens. I view these
-
User Experiments with Generative AI Video Following Google I/O
By
–
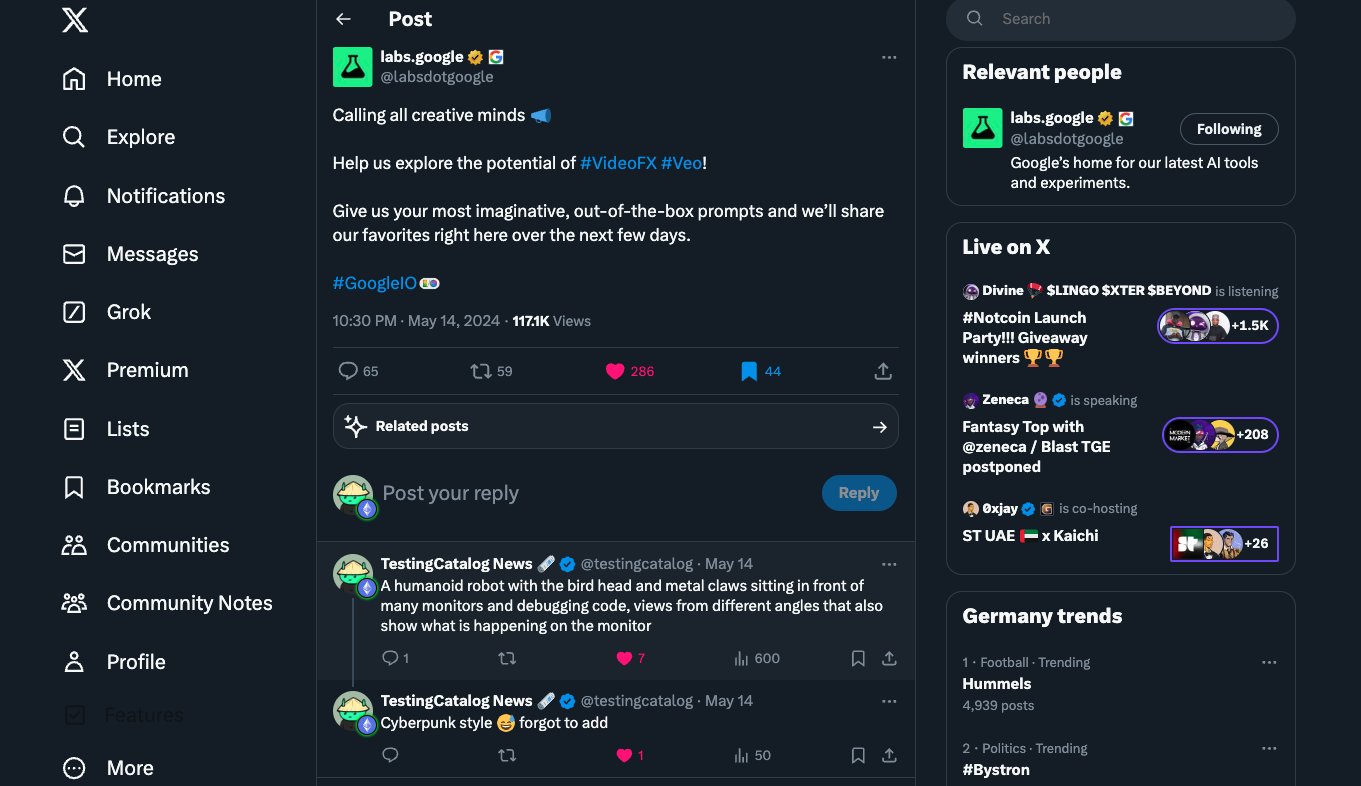
Remember when after I/O Google asked us to share prompts so they could generate videos based on them? Similar to what OpenAI did with Sora. As we still didn't get any samples I tried generating them myself
-
Google’s VideoFX and ImageFX AI Capability Parity
By
–
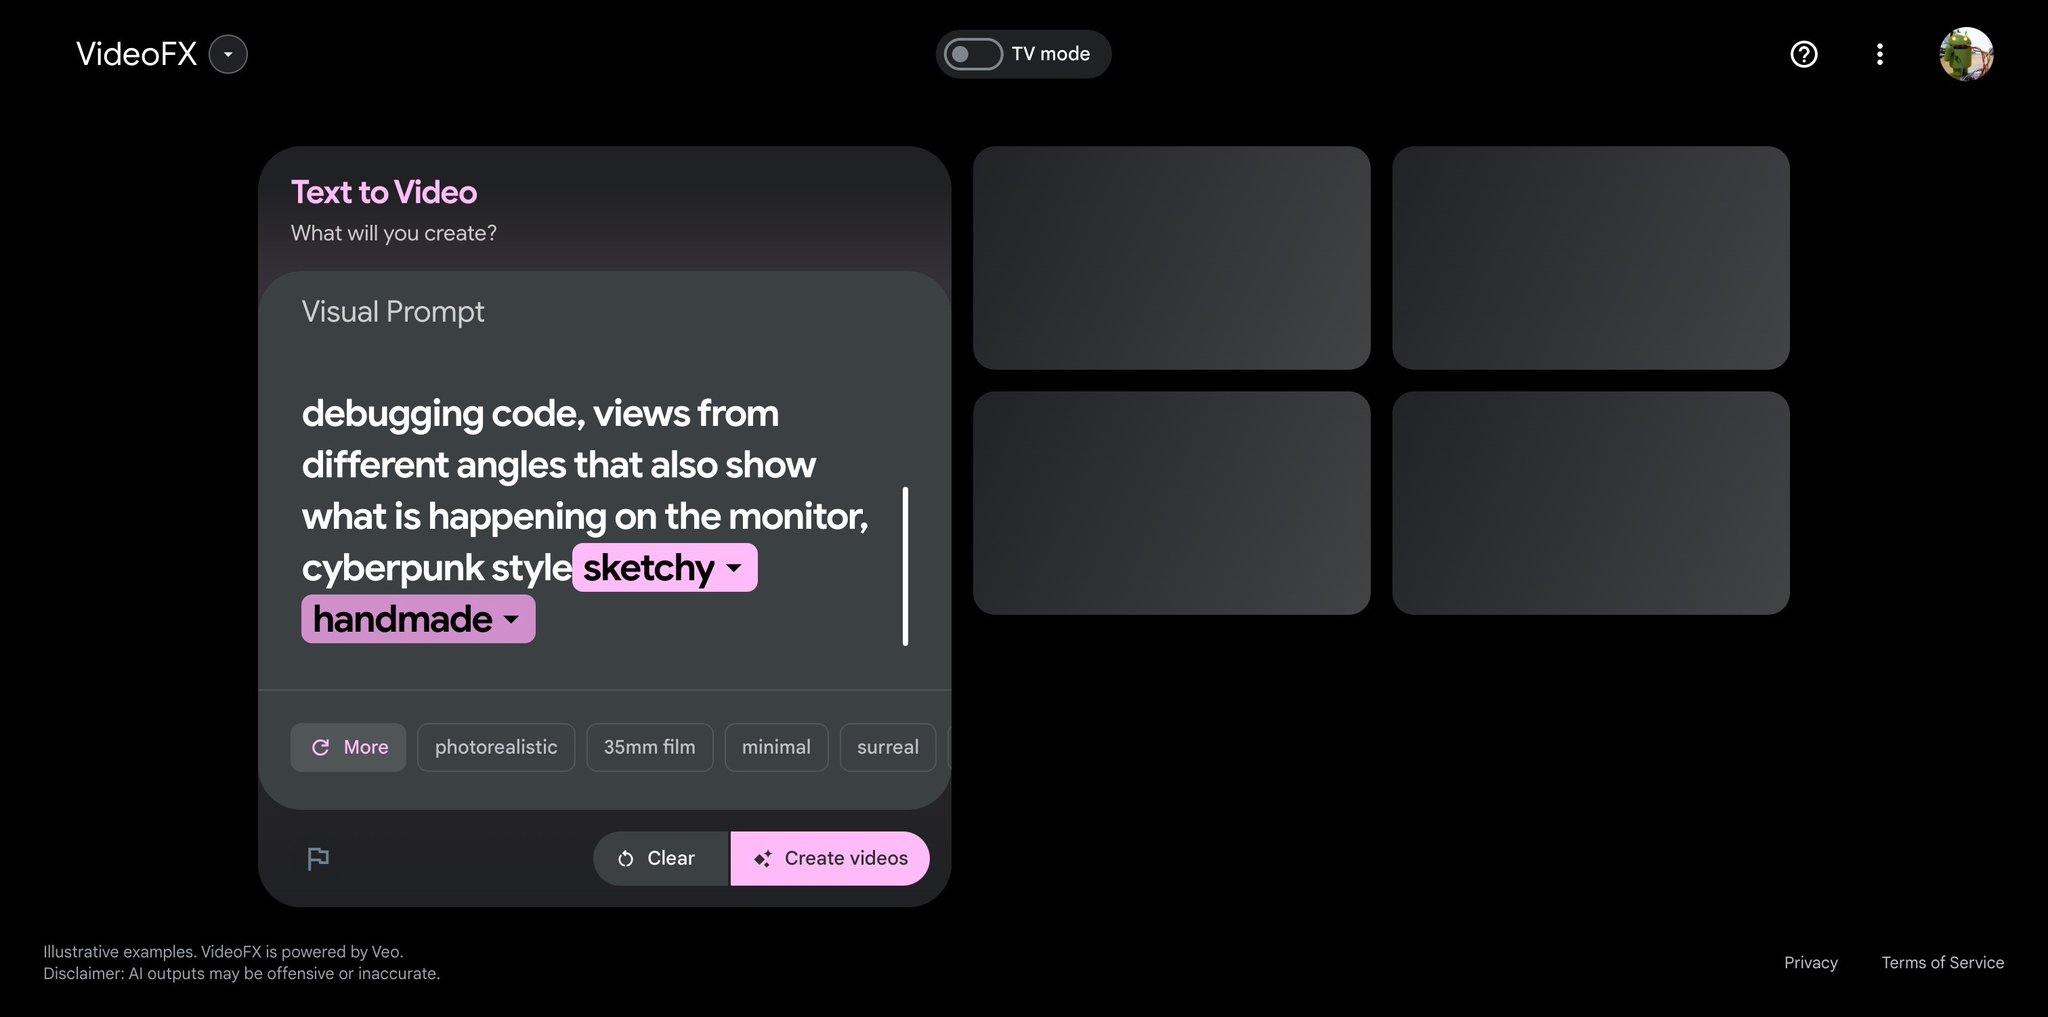
FX experiment on AI Test Kitchen will have a similar UI and capabilities to what is available on ImageFX. You will be able to select a style from the suggested options and it will generate 4 different samples.
-
OpenAI Omni Label Strategy and NVIDIA Omniverse Multimodal AI
By
–
Me pregunto si OpenAI le habrá echado un capote a NVIDIA con la etiqueta Omni para referirse a multimodal, teniendo los de Huang desde hace años la idea de Omniverse sin terminar de aterrizar. Omniverse es una tecnología que se potencia enormemente de la IA multimodal, y sin
-

Residual Quantisation: VQ-VAE Improvement for Data Compression
By
–
This is a great K-AI paper on residual quantisation. It is an improvement over VQ-VAE. In short, after quantising the data (images, video, audio) one also quantizes the resulting error to get a finer aggregate description, which is then passed to the decoder. @kchonyc I’m
-
Astra Iteratively Critiques and Improves Veo Video Output
By
–
What happens if Astra watches a Veo video, critiques it, asks Veo to make improvements, and repeat…. hmm, what will we get after lots of iterations