Hallo-Live: Real-Time Streaming Joint Audio-Video Avatar Generation with Asynchronous Dual-Stream and Human-Centric Preference Distillation Paper: https://
arxiv.org/abs/2604.23632
Code: https://
github.com/fudan-generati
ve-vision/Hallo-Live
… Our report: https://
mp.weixin.qq.com/s/LCgg_MzjSHqv
YxPIOIhZIw
… #PapersAccepted by Jiqizhixin
MULTIMODAL AI
-
Hallo-Live: Real-Time Joint Audio-Video Avatar Generation
By
–
-
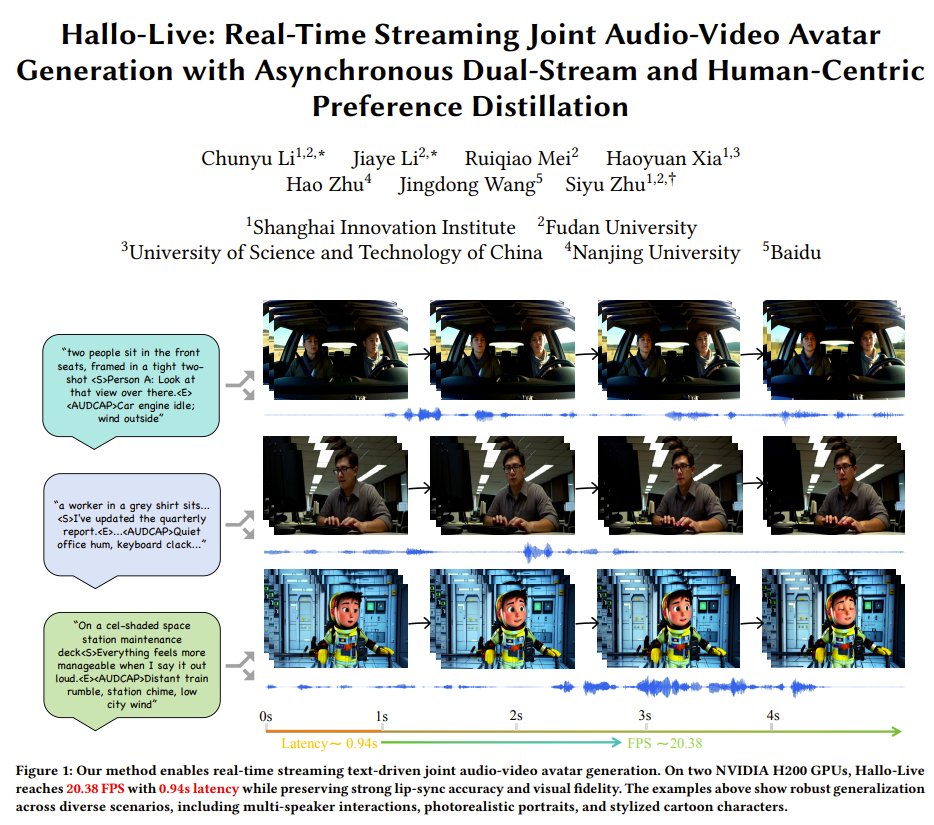
Hallo-Live: streaming audio-video avatar generation from Fudan & Baidu
By
–
What if your avatar could talk and move in real time?
— 机器之心 JIQIZHIXIN (@jiqizhixin) 3 juin 2026
Fudan & Baidu present Hallo-Live: streaming audio-video avatar generation.
Dual-stream diffusion + future-expanding attention syncs lips to upcoming speech.
Human-preference distillation preserves quality. 20 FPS, 0.94s… pic.twitter.com/0GHiOm5h2xWhat if your avatar could talk and move in real time? Fudan & Baidu present Hallo-Live: streaming audio-video avatar generation. Dual-stream diffusion + future-expanding attention syncs lips to upcoming speech. Human-preference distillation preserves quality. 20 FPS, 0.94s
-
Microsoft Builds Own AI: 7 New Models Trained From Scratch
By
–
🚨Microsoft just stopped renting intelligence and started building their own!
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 3 juin 2026
7 new MAI models. Reasoning. Coding. Image. Voice. Transcription. All trained from scratch. Zero distillation. No third-party model outputs. Just clean data and their own infrastructure.
Their… pic.twitter.com/kilTDSO8lNMicrosoft just stopped renting intelligence and started building their own! 7 new MAI models. Reasoning. Coding. Image. Voice. Transcription. All trained from scratch. Zero distillation. No third-party model outputs. Just clean data and their own infrastructure. Their
-

VLMs learn 3D natively, skipping expert architectures and complex designs
By
–
"VLM^3: VLMs Are Native 3D Learners" This paper shows that VLMs can learn 3D natively. Most 3D vision systems rely on expert architectures, regression heads, heavy augmentations, and task-specific losses. But they show that you can skip the majority of these designs. All they
-
AI identifies cat; bounding box pixel decoding is slow
By
–
An AI can tell you there's a cat in the image. Pointing to the exact pixels is the hard part.
— Satya Mallick (@LearnOpenCV) 2 juin 2026
The reason it's slow: most VLMs spell out a bounding box one coordinate token at a time — some even split "1024" into single digits. But a box's corners are connected. Decode them… pic.twitter.com/eoJu0PiHGUAn AI can tell you there's a cat in the image. Pointing to the exact pixels is the hard part.
The reason it's slow: most VLMs spell out a bounding box one coordinate token at a time — some even split "1024" into single digits. But a box's corners are connected. Decode them -

7 new models: Image, Voice, Transcribe, Coding, Thinking
By
–
7 new models Image, Voice, Transcribe, Coding, Thinking!
-
Vision-Language Reasoning for Physical World Understanding
By
–
Vision-Language Reasoning: Reason through the physical world. pic.twitter.com/VHxJEJZQrz
— NVIDIA AI (@NVIDIAAI) 2 juin 2026Vision-Language Reasoning: Reason through the physical world.
-

Microsoft Announces New MAI Code 1 Flash and Thinking 1 Models
By
–
MICROSOFT : New MAI Code 1 Flash and MAI Thinking 1 models have been revealed on the official MAI website! Also, MAI Image 2.5, MAI Voice 2, and MAI Transcribe 1.5 are there too. > MAI-Code-1-Flash plans and reasons through complex coding tasks from start to finish, so you
-
Gemini 3.5 Flash: Understand Research Papers Faster with Highlighted Q&A and Cross-Paper Context
By
–
Introducing Gemini 3.5 Flash for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 2 juin 2026
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references pic.twitter.com/6bmBR63SegIntroducing Gemini 3.5 Flash for understanding research papers Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references
-

AI badge device featuring camera, voice control, and agents
By
–
Badge form factor AI device With camara, voice control and AI Agents