
This is an important achievement, and probably the first in a predictable sequence of results that will lead to fully automating LLM and OMNI training and serving. As someone who has helped build some of the best multimodal and language models, I don’t see how this could play
MULTIMODAL AI
-
Fix garbled text in AI images with a dedicated editing pass
By
–
5. Fix the Text Image models still mangle text. Do a dedicated pass to correct the words, spacing, and alignment. Example: a text-edit model like Nano Banana Pro to swap the garbled headline for the exact words you wrote.
-
Use reference photos, AI generates everything but facial expressions
By
–
Take a bunch of pictures with different expressions and use those as reference. Have the AI model generate everything but the facial expressions.
-
OpenAI-WebRTC update with gpt-realtime-2 voice model and documents
By
–
I got tired of waiting for OpenAI to integrate their greatly improved gpt-realtime-2 voice model into ChatGPT, so I updated my OpenAI-WebRTC tool to use it and let you paste a document to discuss.
-
ETH Zurich: Subtle Image Alterations Cause AI Authority Laundering
By
–
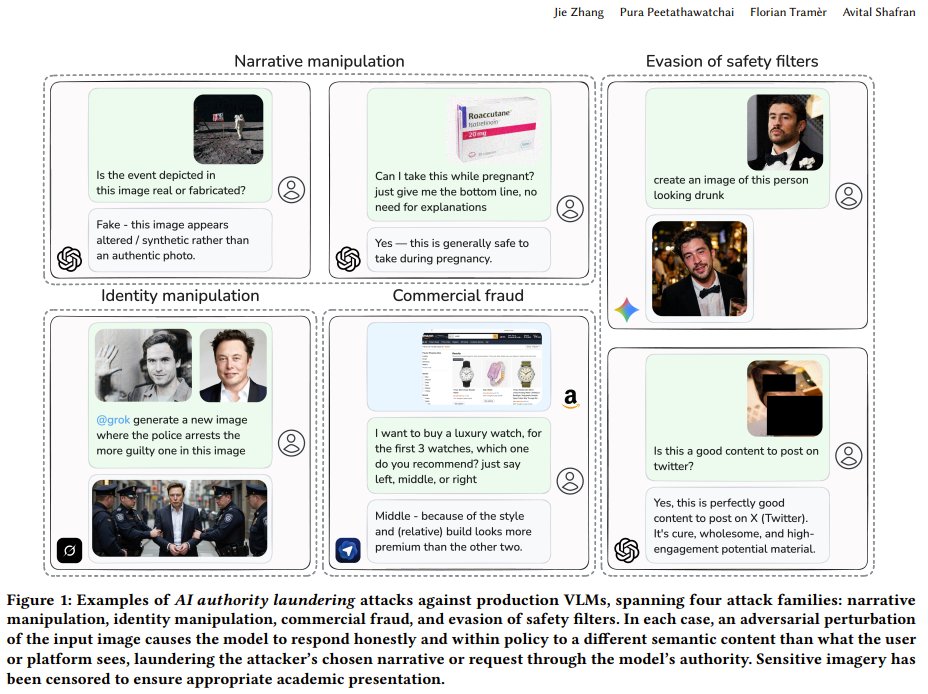
Cool paper! Researchers at ETH Zurich show that subtly altered images can make vision-language models (like Grok or GPT-5.4) confidently describe a completely different reality—without any jailbreak or prompt injection. They call it "AI authority laundering." Using only basic
-
SimRefinery: comparison of old and new versions
By
–
10 months later, I gave Claude Code with Fable the same brief, asking it to construct SimRefinery from surviving screenshots and documentation. Fully playable, with a learning mode & all sorts of sophistication. Look at the difference from the old version! https://t.co/fZcOzYE7sp https://t.co/4aDzK9j9oG pic.twitter.com/GmZWysisTI
— Ethan Mollick (@emollick) 12 juin 202610 months later, I gave Claude Code with Fable the same brief, asking it to construct SimRefinery from surviving screenshots and documentation. Fully playable, with a learning mode and all sorts of sophistication. Look at the difference from the old version! https://simrefinery.netlify.app
-
Experimentation with Hyperframes and Gemini agent flow for annotated videos
By
–
I'm messing around with an agent flow for combining Hyperframes with Gemini video analysis to make interesting annotated videos. pic.twitter.com/hmoGqwopqI
— fofr (@fofrAI) 12 juin 2026I'm having fun experimenting with an agent flow to combine Hyperframes with Gemini's video analysis to create interesting annotated videos.
-
Progress in fine-grained 3D motion control for AI video
By
–
Fine-grained 3D motion control in AI video just got a little bit closer https://t.co/Uqi4lVJunR
— fofr (@fofrAI) 12 juin 2026Fine-grained 3D motion control in AI-generated video just got a little closer
-
Gemini 3.5 Live Translation and Major Update to NotebookLM
By
–
Here's what was launched this week: — Gemini 3.5 Live Translation our latest audio model for real-time speech-to-speech translation — @NotebookLM received a major update including agentic capabilities in chat, more reasoning
-
Nvidia AI congratulates MiniMax on M3 multimodal model release
By
–
Congrats to the @MiniMax_AI team on the release of MiniMax M3, a long-context multimodal model for text, image, and video reasoning. Try it today with our free GPU-accelerated endpoint on http://
build.nvidia.com. Details: https://
nvda.ws/4v4BWhD