atm nanochat does not pretokenize, instead tokenization is done live during training in the dataloader, which is ok and gives the CPU something to do while the GPUs are working. So I didn't try too hard to optimize this part.
MACHINE LEARNING
-
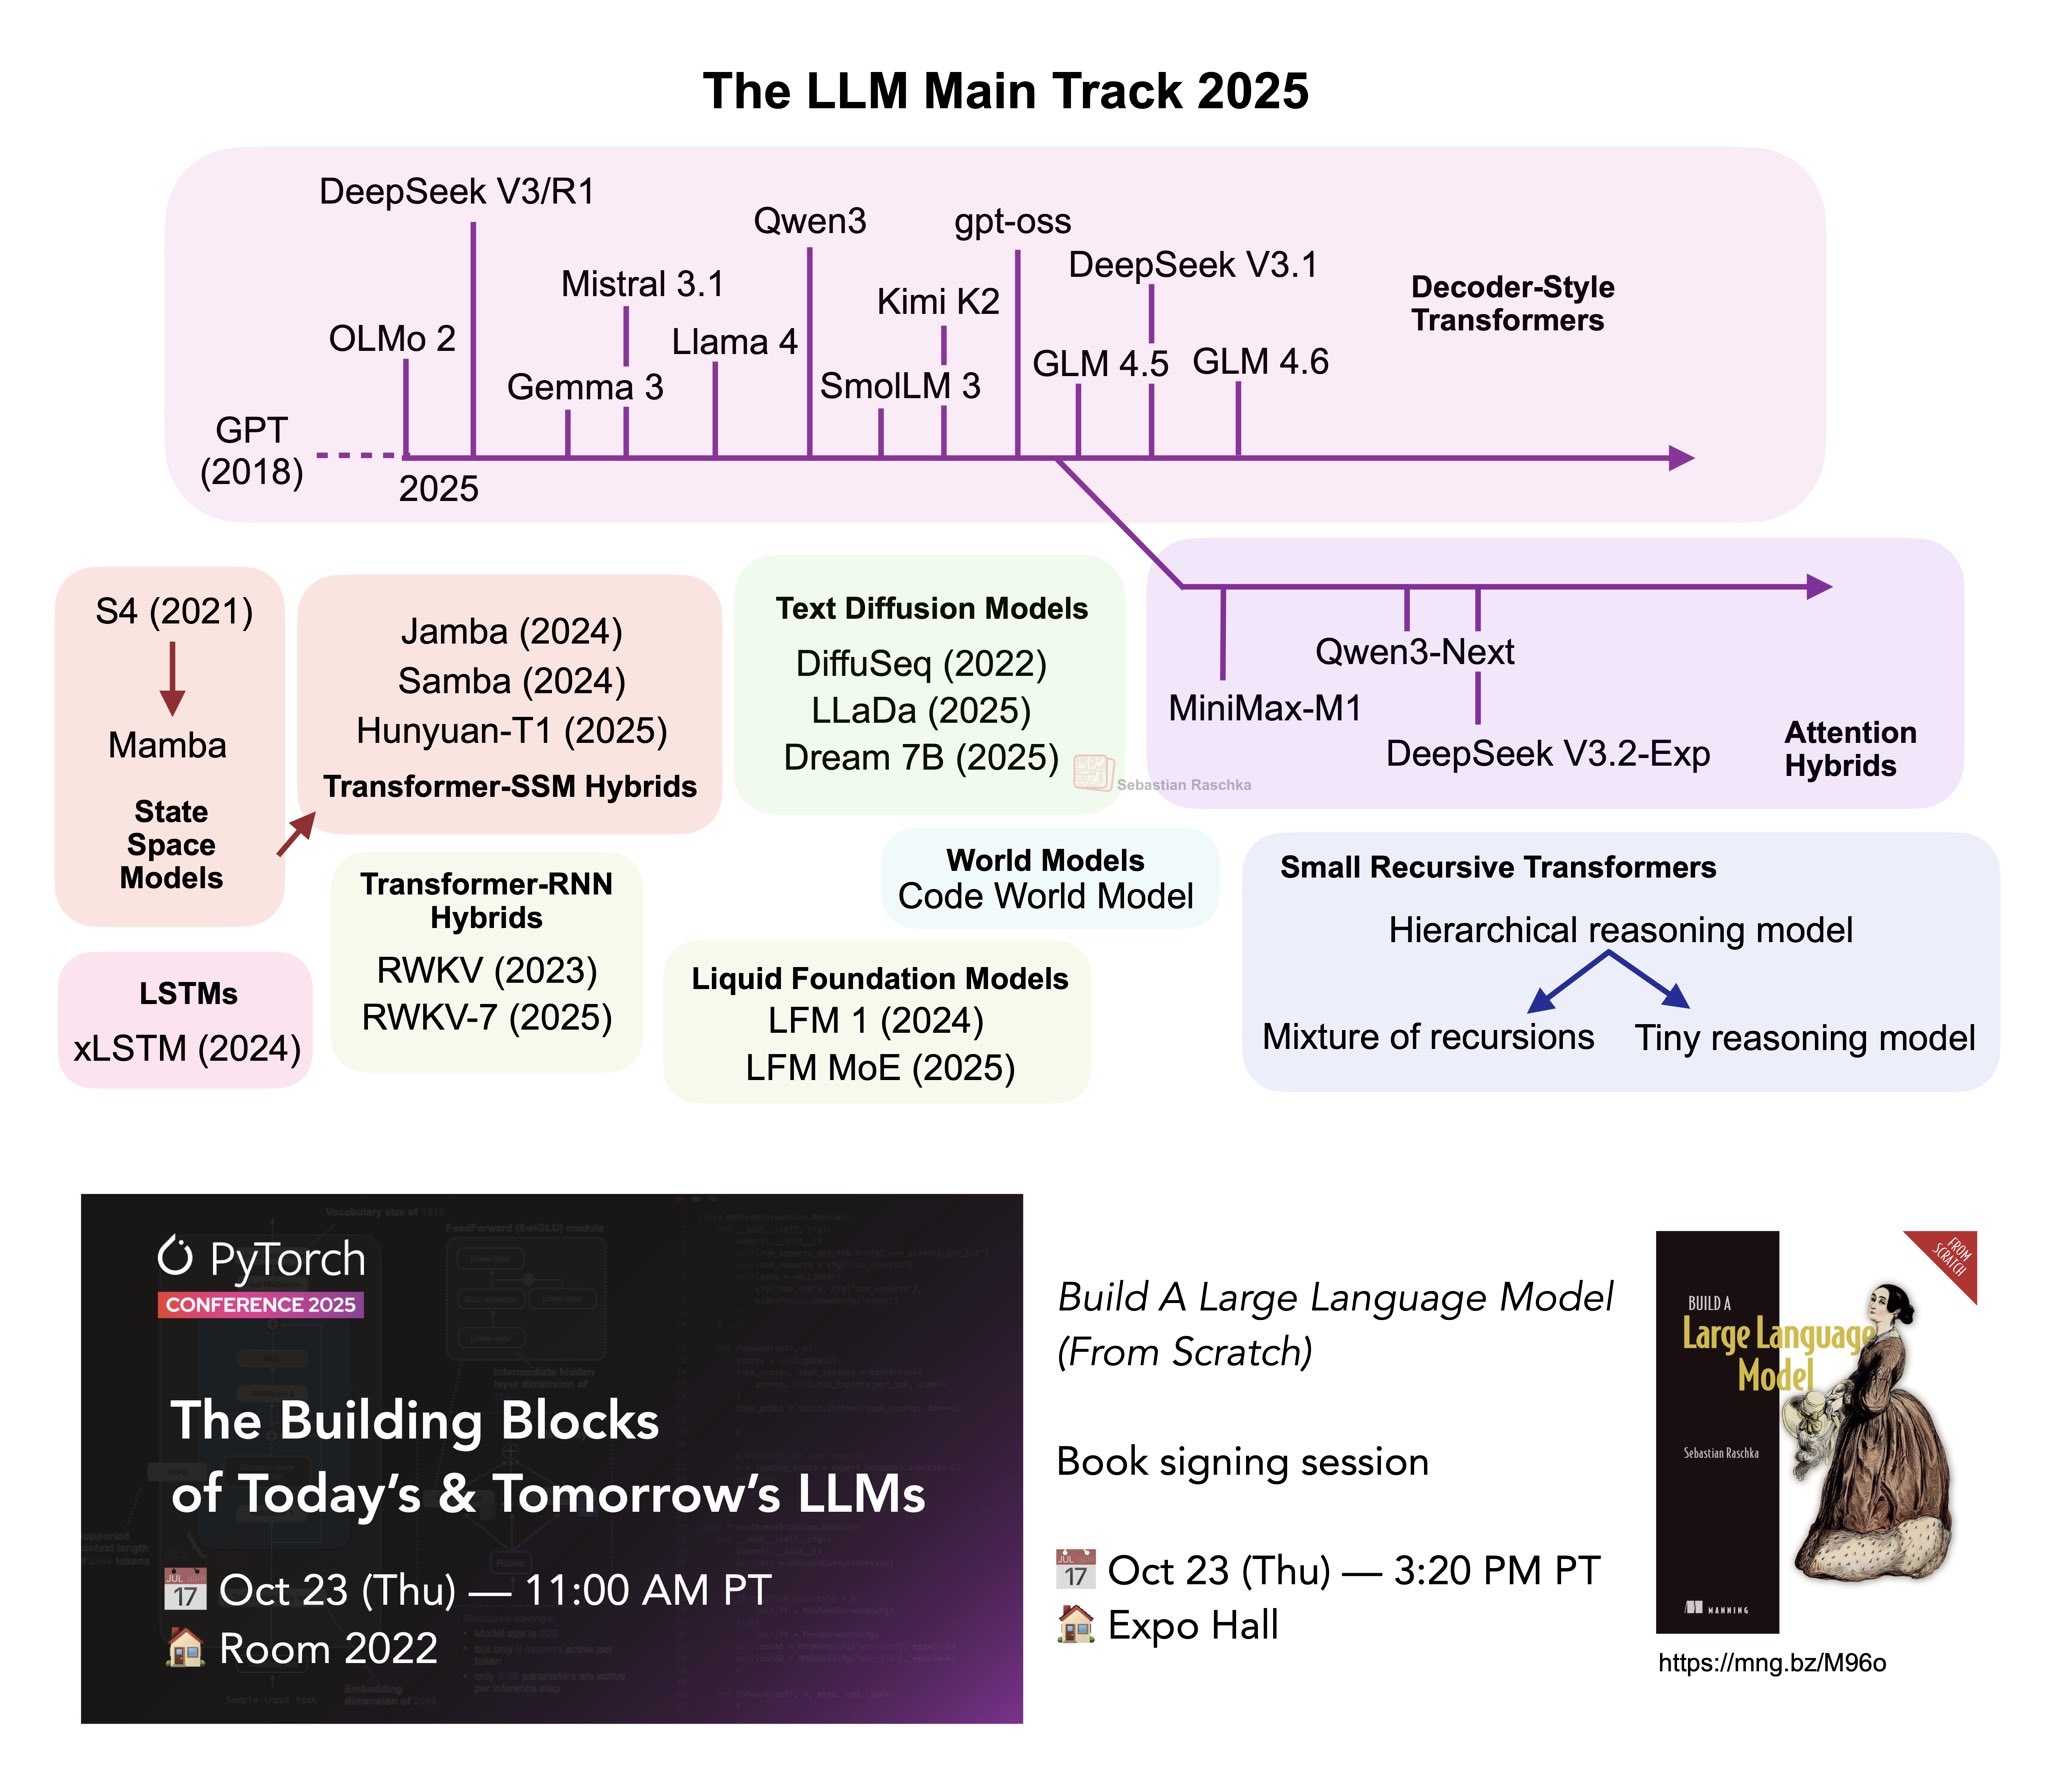
PyTorch Conference Talk on LLM Landscape 2025
By
–
Excited to be (finally) heading to the PyTorch Conference! I’ll be giving a talk tomorrow at 11:00 AM on “The LLM Landscape 2025”, where I’ll discuss the key components behind this year’s most prominent open-weight LLMs, and highlight a few architectural developments that go
-
Learning Error Recovery Without Creating Errors in Testing
By
–
That’s almost separate… You certainly want to learn recoveries in the event of errors at test time. You just don’t want to also learn to actively create errors.
-
GPT-10 Input Architecture: Pixels Over Tokenization
By
–
Haha. I am afraid people interpreted my “delete tokenizer” as “use bytes directly without BPE”, the issue is you *still* need bytes encoding arbitrariness even for that! Pixels is the only way. Just like humans. It is written. If GPT-10 uses utf8 at the input I will eat a shoe.
-
Process Supervision and Error Recovery in RL Training
By
–
Fair but it’s still actively learning to make those errors (just so it can recover from them later), which imo is still a bit weird. In an ideal world you wouldn’t, possibly process supervision is one way to get there even within RL framework. Def agree on “recovery learning”.
-
TMLR Papers Eligible for NeurIPS ICML ICLR Presentation
By
–
We at TMLR are proud to announce that selected papers will now be eligible for an opportunity to present at the joint NeurIPS/ICML/ICLR Journal-to-Conference (J2C) Track:
-
Data Mixing Balance: Vision-Language Skills and Regional Imbalance
By
–
That's a great question and will take the opportunity to dash off a bit on the data mixing. Mixing data is a tricky balance it turns out. There were two main factors at play: – we wanted to keep general vision-language skills.
– and had unbalanced regions and languages: think -
Training multilingual cultural model improves multimodal benchmark performance
By
–
Thank you so much and appreciate you taking time to check the paper. We trained a model(
https://
huggingface.co/neulab/Cultura
lPangea-7B
…) on the subset of the dataset and were able to improve performance on many multilingual/cultural multimodal benchmarks. Yeahhh, would be great too if you could also -
Scaling 2.8M Images and 3M Entities with Flexible Data Curation Pipeline
By
–
We have around 2.8M unique images and 3M unique entities and the data curation pipeline allow scaling that up(more images per entity, adding new countries/languages, questions per entity, etc…). Very glad to hear people were asking about this 🙂
-
Major VQA Dataset Release: 30M Samples Across 42 Countries
By
–
Congrats! Big props unifying vision language datasets and making it easy to access them. We also recently released a massive VQA dataset of 30M samples(22M filtered), spanning 42 countries and 39 languages. The dataset contains factual visual questions and answers about world