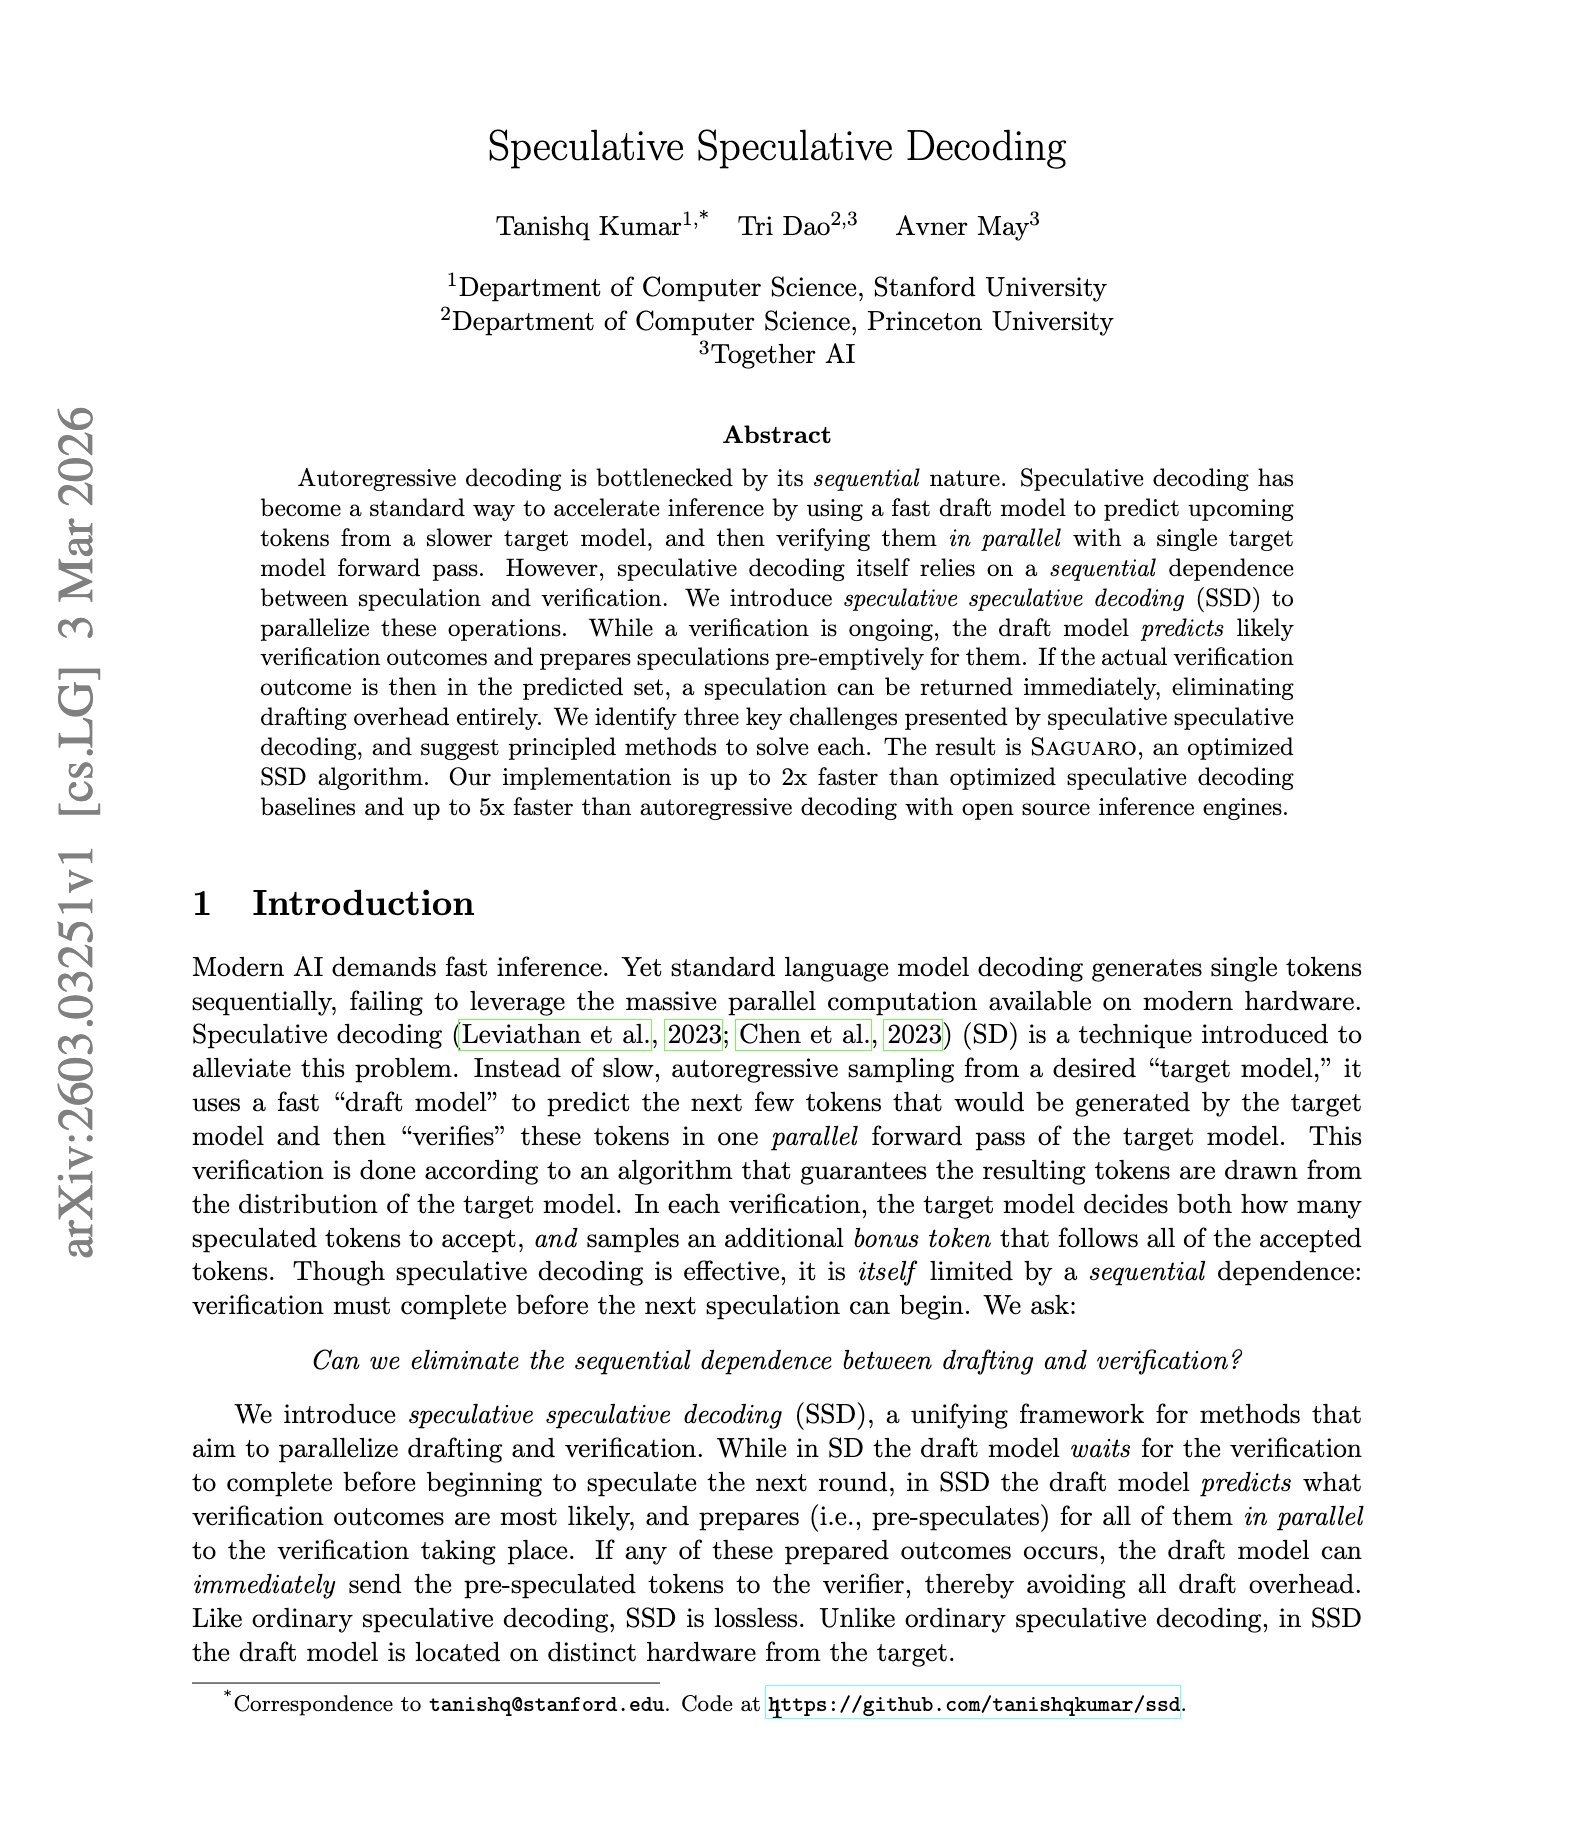
“Speculative Speculative Decoding” Even though speculative decoding speed up LLM inference, it still has a hidden “stop-and-wait” step, where the draft model can’t start the next guess until the big model finishes verifying the last one. This paper fixes that by making drafting
MACHINE LEARNING
-
Tether: Self-Supervised Robot Learning Through Autonomous Play
By
–
Congrats @willjhliang, @JasonMa2020 @dineshjayaraman and collaborators on this cool combination of VLMs, keypoint detectors, and GOFE trajectory warping to self-supervise and reset 1000s of diverse pick-and-place demonstrations that are then used to train a VLA policy. https://t.co/OzEp63lx99
— Ken Goldberg (@Ken_Goldberg) 5 mars 2026Congrats @willjhliang, @JasonMa2020 @dineshjayaraman and collaborators on this cool combination of VLMs, keypoint detectors, and GOFE trajectory warping to self-supervise and reset 1000s of diverse pick-and-place demonstrations that are then used to train a VLA policy. Will Liang (@willjhliang) Introducing Tether 🪢, a fun little idea to scale data by having our robot “play” in the real world for over 24 hours, throughout the day and overnight—improving policies from zero to mastery with minimal supervision! But play is messy, with out-of-distribution scenarios that are hard to anticipate. To perform autonomous functional play in the real world, from just a handful of demos, we propose a highly robust few-shot imitation method that warps demo trajectories using visual correspondences. Then, continuously running it within a multi-task VLM-guided cycle, we generate a data stream that produces 1000+ expert-level demos. This generated data is finally funneled downstream to train imitation learning policies, which improve from zero to near-perfect success rates. We’ll be presenting Tether at #ICLR2026 in just a few weeks! But before that, deep dive with me… 🧵 — https://nitter.net/willjhliang/status/2029238456766087386#m
→ View original post on X — @ken_goldberg, 2026-03-05 06:35 UTC
-
Building an AI to read content for you, launching in weeks
By
–
I'm building an AI to read it for you. Out in a couple of weeks.
-
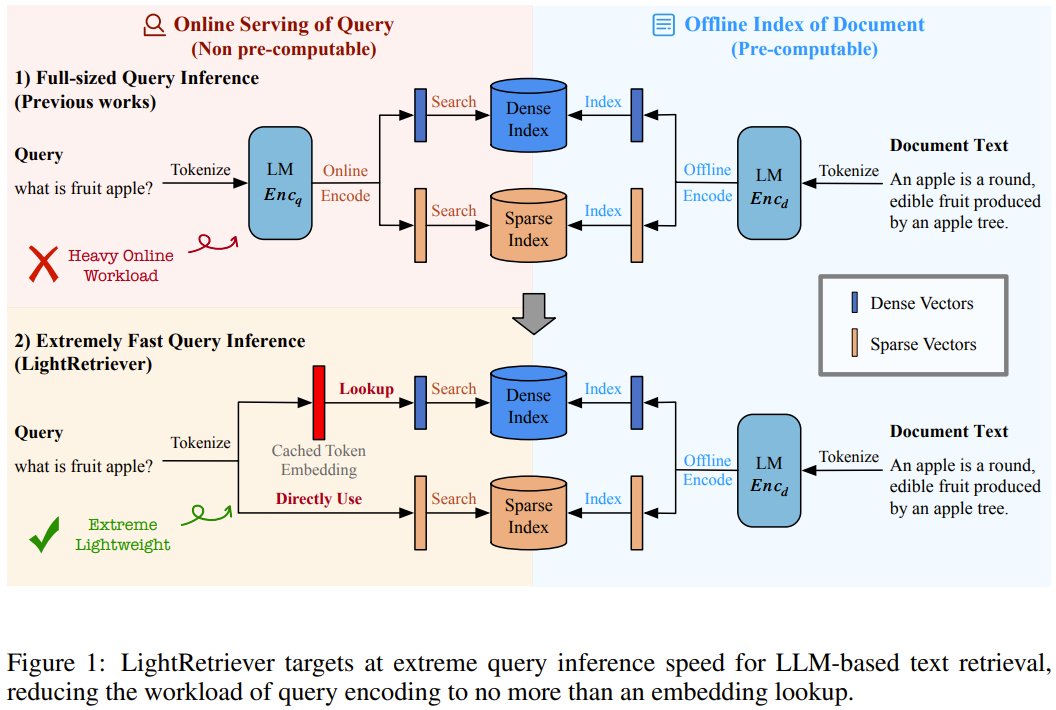
LightRetriever promises LLM-level search with 1000x faster queries
By
–
What if you could get LLM-level search accuracy with 1000x faster query speeds? CAS and Langboat Technology present LightRetriever to do just that. The architecture keeps a powerful LLM for heavy document processing offline but replaces slow real-time query encoding with a
-
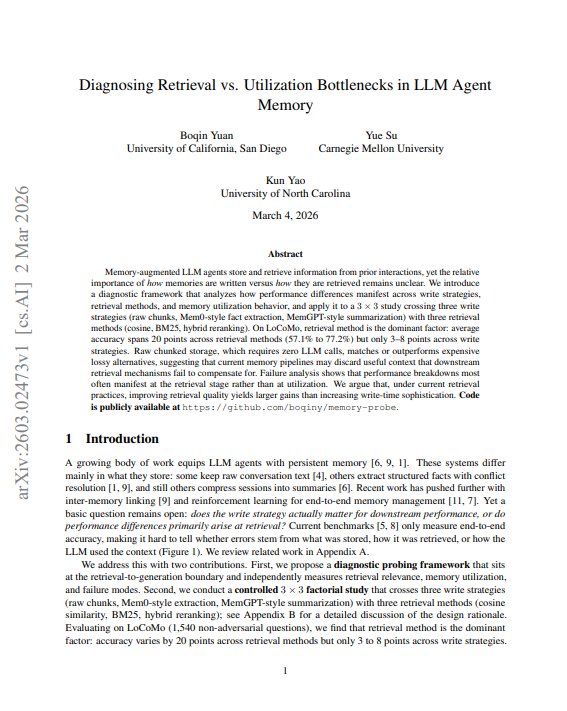
Retrieval Method Trumps Memory Writing in AI Agents
By
–
most people building AI agents obsess over how they WRITE memories
turns out that's basically irrelevant new research analyzed 9 different memory systems across 1,540 questions the finding?
retrieval method drives 20-point accuracy swings
write strategy? 3–8 points max raw -
IEEE Transactions on Robot Learning launches March 30
By
–
The @IEEE Transactions on Robot Learning (T-RL) will launch on March 30! Co-EiCs: Todd Murphey and Vincent Vanhoucke ieee-ras.org/publications/t-…
→ View original post on X — @ken_goldberg, 2026-03-04 19:51 UTC
-

New JAX Course: Build and Train LLMs from Scratch
By
–
New course: Build and Train an LLM with JAX, built in partnership with @Google and taught by @chrisachard.
— Andrew Ng (@AndrewYNg) 4 mars 2026
JAX is the open-source library behind Google's Gemini, Veo, and other advanced models. This short course teaches you to build and train a 20-million parameter language… pic.twitter.com/iBJTIjTOIWNew course: Build and Train an LLM with JAX, built in partnership with @Google and taught by @chrisachard. JAX is the open-source library behind Google's Gemini, Veo, and other advanced models. This short course teaches you to build and train a 20-million parameter language model from scratch using JAX and its ecosystem of tools. You'll implement a complete MiniGPT-style architecture from scratch, train it, and chat with your finished model through a graphical interface. Skills you'll gain: – Learn JAX's core primitives: automatic differentiation, JIT compilation, and vectorized execution – Build a MiniGPT-style LLM using Flax/NNX, implementing embedding and transformer blocks – Load a pretrained MiniGPT model and run inference through a chat interface Come learn this important software layer for building LLMs! deeplearning.ai/short-course…
→ View original post on X — @andrewyng, 2026-03-04 18:41 UTC
-
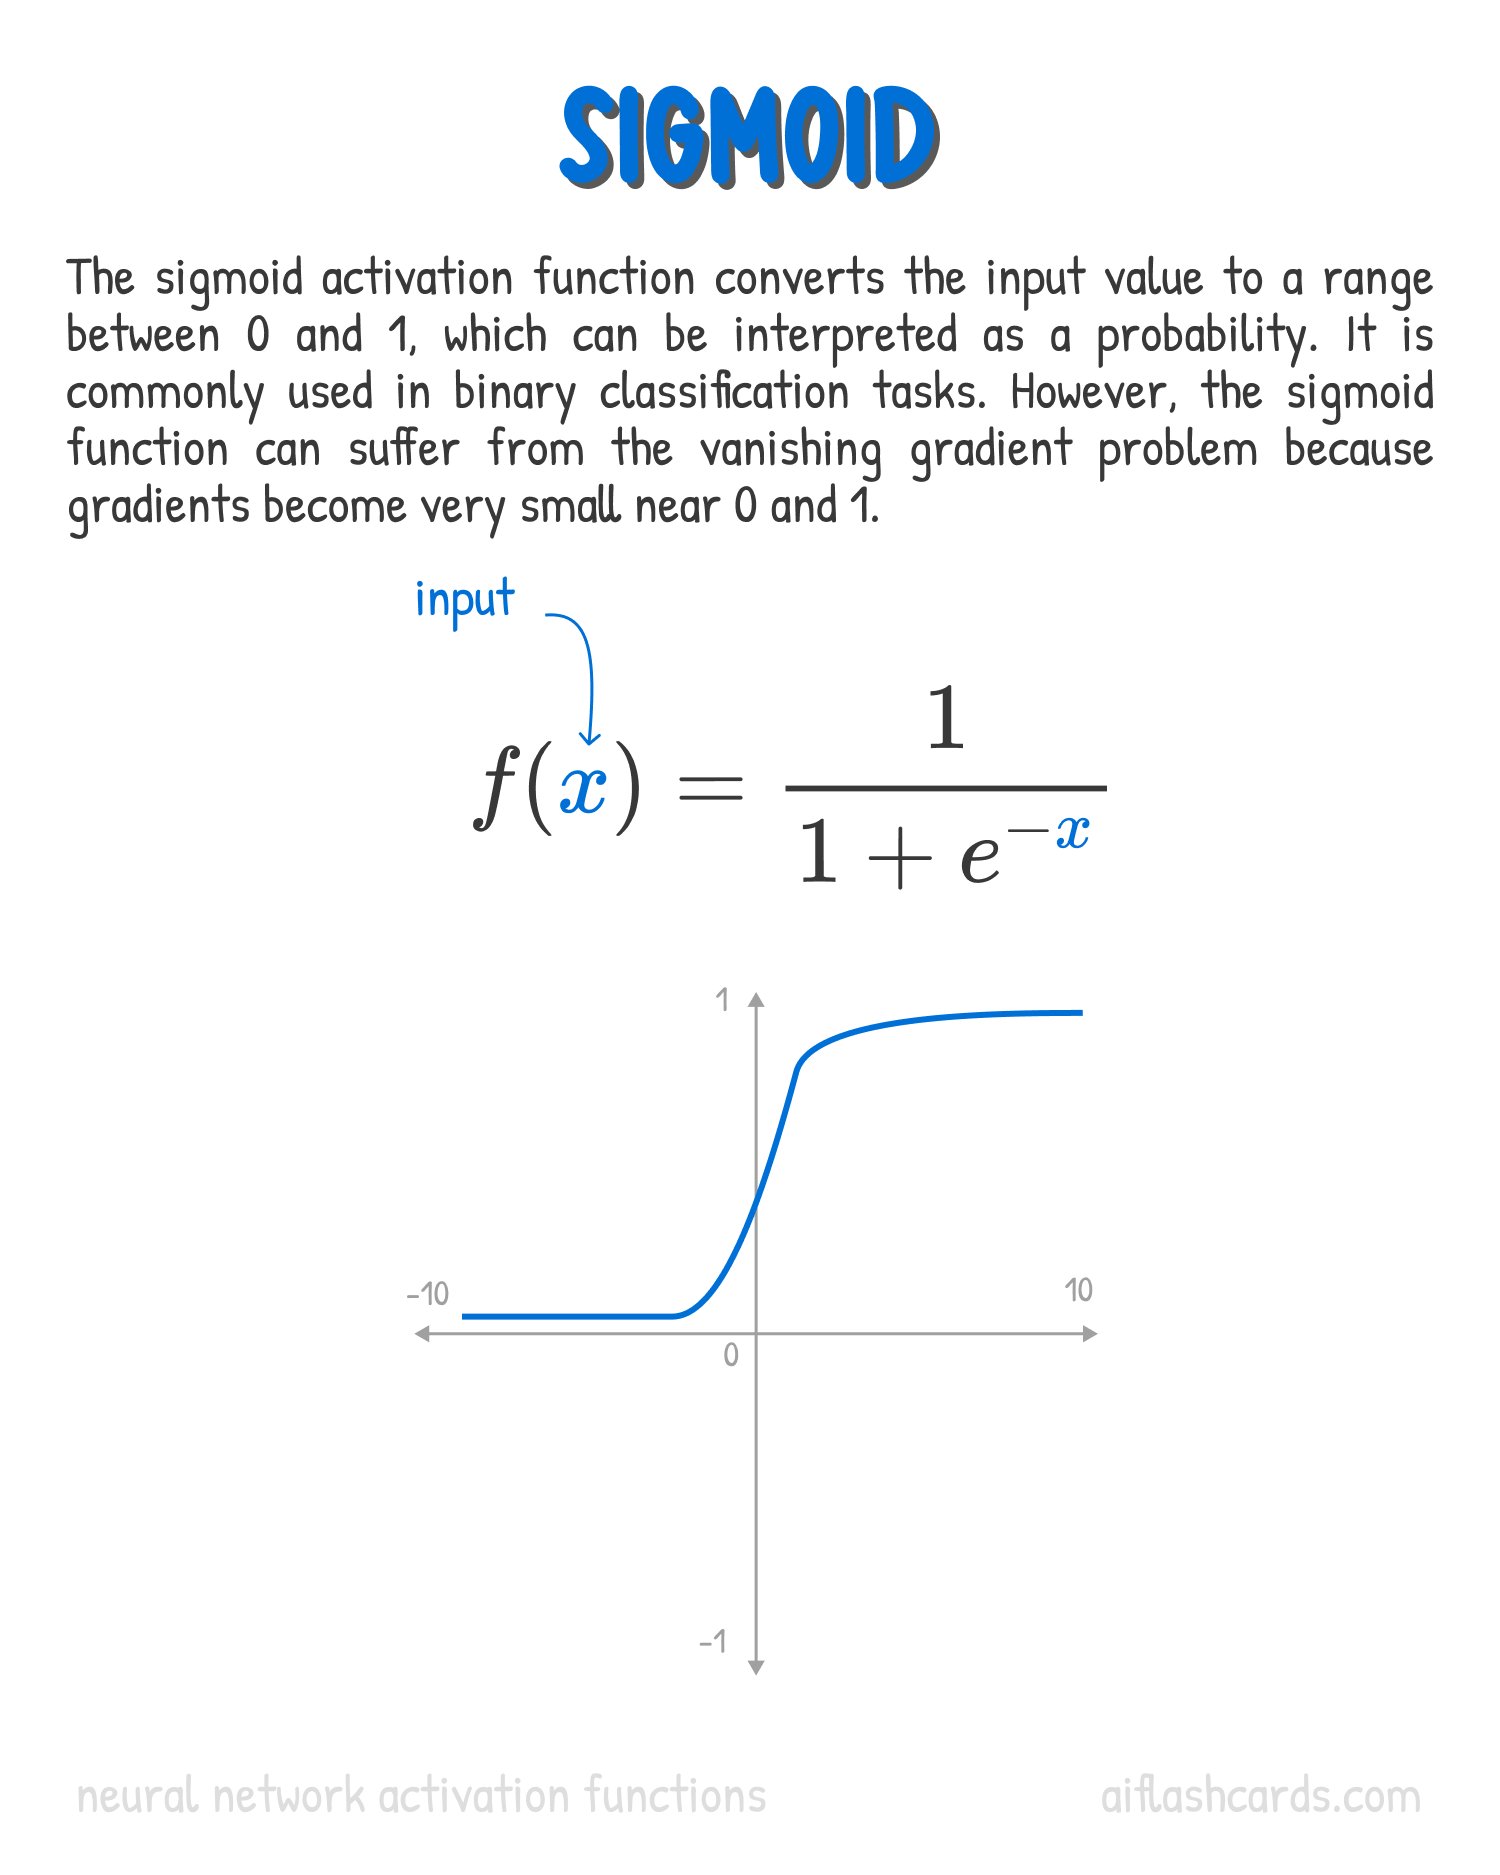
Reflecting on Past Restrictions on AI Terminology
By
–
Just a few years ago we were not allowed to say "sigmoid" on this app without a fear of getting canceled.
-
Codex AI’s Approximation Method Sparks Frustration Over Benchmarking
By
–
Now it looks like Codex was not necessarily OPTIMIZING certain algorithms for specific hardware, it was using APPROXIMATIONS instead to speeding things up. And all the benchmarking scripts might have been just the smokescreen. TWO WEEKS OF COWORK DOWN THE DRAIN!!!! AAARRRGH!!!