
Agent harnesses are too restrictive. That's because they're still designed as code. What if the harness itself were written in natural language and interpreted by an LLM at runtime? This research explores the idea. The work introduces Natural-Language Agent Harnesses (NLAHs), a structured natural-language representation that externalizes harness logic as a portable, executable artifact. Instead of scattering control flow across controller code, framework defaults, and tool adapters, NLAHs make contracts, roles, stage structure, state semantics, and failure taxonomies explicit and editable. An Intelligent Harness Runtime (IHR) places an LLM inside the runtime loop to interpret and execute these harnesses directly. Why does it matter? Harness design is increasingly decisive for agent performance, but it's buried in code that's hard to transfer, compare, or ablate. NLAHs make the orchestration layer a first-class scientific object. The practical implication: harnesses become portable across runtimes, composable across tasks, and directly inspectable by humans and models alike. Paper: arxiv.org/abs/2603.25723 Learn to build effective AI agents in our academy: academy.dair.ai/
MACHINE LEARNING
-

Meta-Harness: Automated System Achieves 6x Performance Improvement
By
–
NEW Stanford & MIT paper on Model Harnesses. Changing the harness around a fixed LLM can produce a 6x performance gap on the same benchmark. What if we automated harness engineering itself? The work introduces Meta-Harness, an agentic system that searches over harness code by exposing the full history through a filesystem. The proposer reads source code, execution traces, and scores from all prior candidates, referencing over 20 past attempts per step. On text classification, it improves over SOTA context management by 7.7 points while using 4x fewer tokens. On agentic coding, it outperforms all hand-engineered baselines on TerminalBench-2, scoring 37.6% versus Claude Code's 27.5%. This is a big deal! Here is why: The harness around a model often matters as much as the model itself. Meta-Harness shows that giving an optimizer rich access to prior experience, not just compressed scores, unlocks automated engineering that beats human-designed scaffolding. Paper: arxiv.org/abs/2603.28052 Learn to build effective AI agents in our academy: academy.dair.ai/
-
Minimax M27 Model Release Announcement and Blog Post
By
–
Blog: minimax.io/news/minimax-m27-…
→ View original post on X — @akshay_pachaar, 2026-03-31 13:07 UTC
-
MiniMax M2.7: First AI That Self-Improves Without Retraining
By
–
The first AI that improves without retraining. (it rewrites its own agent harness) Every developer I know has one thing in common: they obsess over their setup. The terminal, the scripts, the shortcuts. They don't just write code. They constantly refine how they work. The code gets better because the environment gets better. MiniMax just released M2.7, and I think the most interesting thing about it isn't a benchmark number. It's the fact that M2.7 improves its own agent harness. Autonomously. Let's break this down: When you run an AI agent today, it operates inside a "harness." Think of it as the agent's operating environment: the skills it can invoke, the tools it can call, its memory, and the rules it follows. Normally, a human engineer builds this harness, and the agent operates within it. The harness stays fixed. M2.7 treats its harness as something it can rewrite. Here's what the loop looks like: – The agent runs a task and analyzes where things went wrong – It plans changes to its own scaffold: skills, MCPs, memory – It applies those changes, runs evaluations against a benchmark – It compares the results and decides whether to keep or revert – It writes self-criticism into memory so the next round starts smarter Then it loops back and does it again. And again. Think of it like a developer who finishes a project, writes a retrospective, restructures their workflow based on what they learned, and shows up the next day with a better setup. Except the developer here is the model itself. MiniMax ran this self-optimization loop for over 100 rounds internally. Along the way, the model discovered things on its own: it systematically searched for optimal sampling parameters (temperature, penalties), wrote workflow-specific guidelines for itself (like automatically checking for the same bug pattern in other files after a fix), and even added loop detection to avoid getting stuck. No human had to tell it to do any of this. They also tested this in a more controlled setting. They had M2.7 compete in 22 ML competitions from OpenAI's MLE Bench Lite. Each trial ran for 24 hours, fully autonomous. After each iteration, the agent wrote a memory file and performed self-criticism, feeding those insights into the next round. With every round, the ML models it trained achieved higher medal rates. The best run earned 9 gold medals. I've summarized the self-evolving architecture in the graphic below. The reason I find this compelling: this isn't about making a smarter model. It's about making a model that makes itself smarter. The weights never change. What changes is the system around it: better skills, better memory, better workflow rules. And that distinction matters because it means the improvement loop can run continuously without any retraining. We're entering a phase where agents don't just follow instructions. They redesign their own playbook. If you want to learn more, I've shared a link to their official blog post in the next tweet.
→ View original post on X — @akshay_pachaar, 2026-03-31 13:07 UTC
-
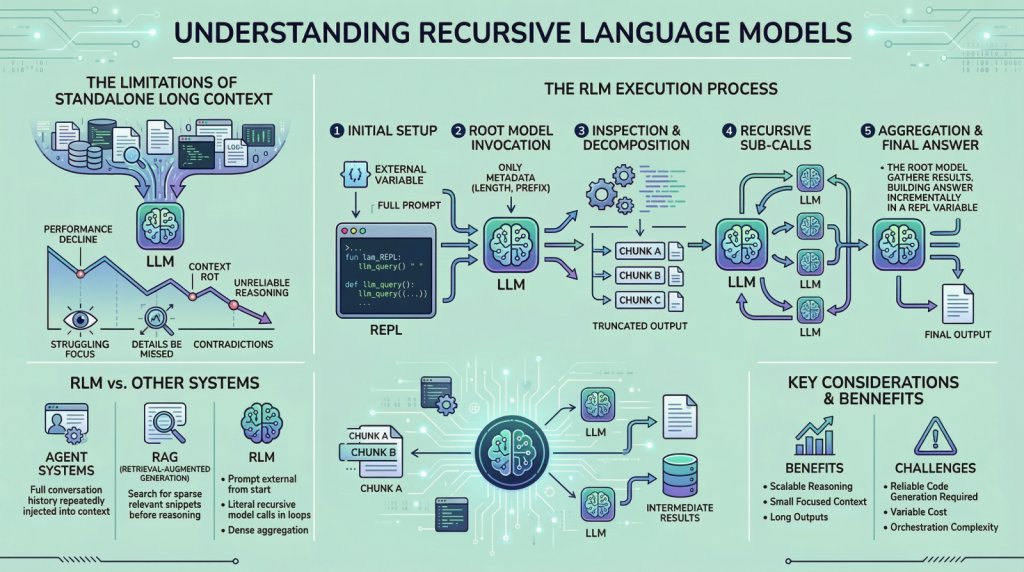
Everything You Need to Know About Recursive Language Models
By
–
Everything You Need to Know About Recursive Language Models https://
machinelearningmastery.com/everything-you
-need-to-know-about-recursive-language-models/?utm_source=dlvr.it&utm_medium=twitter
… -
Hovermap ST-X: Revolutionary Autonomous LiDAR Mapping Technology
By
–
Hovermap ST-X: Next-Generation #Autonomous LiDAR Mapping for Complex Environments
— Ronald van Loon (@Ronald_vanLoon) 31 mars 2026
by @emesent
#Drones #EmergingTech #Innovation #Tech #Technology pic.twitter.com/YrCVtgMNdbHovermap ST-X: Next-Generation #Autonomous LiDAR Mapping for Complex Environments
by @emesent #Drones #EmergingTech #Innovation #Tech #Technology -
Skild AI and NVIDIA Deploy Neural Networks for ABB Robotics
By
–
Folks, you have to see what @SkildAI and @NVIDIARobotics just pulled off!
— Charly Wargnier (@DataChaz) 31 mars 2026
They are deploying a full end-to-end neural network to make @ABBRobotics systems SO robust and scalable.
AI is finally taking over the factory floor, and I'm here for it! 😎 🍿pic.twitter.com/cWpfMGqBbL https://t.co/5NiAO0NTlCFolks, you have to see what @SkildAI and @NVIDIARobotics just pulled off! They are deploying a full end-to-end neural network to make @ABBRobotics systems SO robust and scalable. AI is finally taking over the factory floor, and I'm here for it!
-
First Conference with SKILL.md Submissions
By
–
The first conference where your submission isn't a paper.
— God of Prompt (@godofprompt) 31 mars 2026
It's a SKILL.md file Claude can execute, review, and reproduce end-to-end.
Stanford and Princeton just made reproducibility the submission format.
$50,000 prize pool. 364 winners.
Deadline April 5 👇… https://t.co/4ql4fVGe4QThe first conference where your submission isn't a paper. It's a SKILL.md file Claude can execute, review, and reproduce end-to-end. Stanford and Princeton just made reproducibility the submission format. $50,000 prize pool. 364 winners. Deadline April 5
-
Cerebras threatens NVIDIA’s GPU dominance with single-chip technology
By
–
NVIDIA’s trillion-dollar dominance relies on the complex art of horizontal scaling, but Cerebras poses a dangerous threat by proving that one giant chip can eliminate the communication bottlenecks of massive GPU clusters. If AI workloads shift toward single-system training and… pic.twitter.com/svpfJ2QP2i
— Satya Mallick (@LearnOpenCV) 31 mars 2026NVIDIA’s trillion-dollar dominance relies on the complex art of horizontal scaling, but Cerebras poses a dangerous threat by proving that one giant chip can eliminate the communication bottlenecks of massive GPU clusters. If AI workloads shift toward single-system training and ultra-fast inference, Nvidia's greatest strength—distributed computing—could quickly become an obsolete solution to a solved problem.
→ View original post on X — @learnopencv, 2026-03-31 11:30 UTC
-
On-Site Robot Intelligence: Adaptive AI for Safe Unknown Environment Operation
By
–
On-Site #Robot Intelligence: Adaptive #AI for Safe Operation in Unknown Environments
— Ronald van Loon (@Ronald_vanLoon) 31 mars 2026
via @ZappyZappy7
#Robotics #Transportation #Engineering #Innovation #Technology pic.twitter.com/TqJFzH30aNOn-Site #Robot Intelligence: Adaptive #AI for Safe Operation in Unknown Environments
via @ZappyZappy7 #Robotics #Transportation #Engineering #Innovation #Technology