
Can an AI agent run a startup for a year without going bankrupt? Turns out most can't. New benchmark from Collinear AI puts 12 models to the test. YC-Bench tasks agents with running a simulated startup over hundreds of turns: hiring employees, selecting contracts, and maintaining profitability in a partially observable environment with adversarial clients and compounding consequences. Only three models consistently surpass the $200K starting capital. Claude Opus 4.6 leads at $1.27M average final funds, followed by GLM-5 at $1.21M with 11x lower inference cost. Scratchpad usage, the sole mechanism for persisting information across context truncation, is the strongest predictor of success. Adversarial client detection accounts for 47% of bankruptcies. Long-horizon coherence, not raw intelligence, separates the winners from the bankrupt. Paper: arxiv.org/abs/2604.01212 Learn to build effective AI agents in our academy: academy.dair.ai/
MACHINE LEARNING
-
Hiring Exceptional Engineers Across Speech Data Coding and RL
By
–
We are hiring exceptional speech, data, coding, RL and inference engineers, as well as exceptional new graduates. Also, high-performance numerical computing engineers that can build libraries for new chips. We want generalists that can do anything and put the team above ego.
-

Schmidhuber Claims LeCun’s JEPA Repackages His 1992 PMAX Work
By
–
Seems this discussion is moving into a new chapter Jürgen Schmidhuber (@SchmidhuberAI) Dr. LeCun's heavily promoted Joint Embedding Predictive Architecture (JEPA, 2022) [5] is the heart of his new company. However, the core ideas are not original to LeCun. Instead, JEPA is essentially identical to our 1992 Predictability Maximization system (PMAX) [1][14]. Details in reference [19] which contains many additional references. Motivation of PMAX [1][14]. Since details of inputs are often unpredictable from related inputs, two non-generative artificial neural networks interact as follows: one net tries to create a non-trivial, informative, latent representation of its own input that is predictable from the latent representation of the other net’s input. PMAX [1][14] is actually a whole family of methods. Consider the simplest instance in Sec. 2.2 of [1]: an auto encoder net sees an input and represents it in its hidden units (its latent space). The other net sees a different but related input and learns to predict (from its own latent space) the auto encoder's latent representation, which in turn tries to become more predictable, without giving up too much information about its own input, to prevent what's now called “collapse." See illustration 5.2 in Sec. 5.5 of [14] on the "extraction of predictable concepts." The 1992 PMAX paper [1] discusses not only auto encoders but also other techniques for encoding data. The experiments were conducted by my student Daniel Prelinger. The non-generative PMAX outperformed the generative IMAX [2] on a stereo vision task. The 2020 BYOL [10] is also closely related to PMAX. In 2026, @misovalko, leader of the BYOL team, praised PMAX, and listed numerous similarities to much later work [19]. Note that the self-created “predictable classifications” in the title of [1] (and the so-called “outputs” of the entire system [1]) are typically INTERNAL "distributed representations” (like in the title of Sec. 4.2 of [1]). The 1992 PMAX paper [1] considers both symmetric and asymmetric nets. In the symmetric case, both nets are constrained to emit "equal (and therefore mutually predictable)" representations [1]. Sec. 4.2 on “finding predictable distributed representations” has an experiment with 2 weight-sharing auto encoders which learn to represent in their latent space what their inputs have in common (see the cover image of this post). Of course, back then compute was was a million times more expensive, but the fundamental insights of "JEPA" were present, and LeCun has simply repackaged old ideas without citing them [5,6,19]. This is hardly the first time LeCun (or others writing about him) have exaggerated LeCun's own significance by downplaying earlier work. He did NOT "co-invent deep learning" (as some know-nothing "AI influencers" have claimed) [11,13], and he did NOT invent convolutional neural nets (CNNs) [12,6,13], NOR was he even the first to combine CNNs with backpropagation [12,13]. While he got awards for the inventions of other researchers whom he did not cite [6], he did not invent ANY of the key algorithms that underpin modern AI [5,6,19]. LeCun's recent pitch: 1. LLMs such as ChatGPT are insufficient for AGI (which has been obvious to experts in AI & decision making, and is something he once derided @GaryMarcus for pointing out [17]). 2. Neural AIs need what I baptized a neural "world model" in 1990 [8][15] (earlier, less general neural nets of this kind, such as those by Paul Werbos (1987) and others [8], weren't called "world models," although the basic concept itself is ancient [8]). 3. The world model should learn to predict (in non-generative "JEPA" fashion [5]) higher-level predictable abstractions instead of raw pixels: that's the essence of our 1992 PMAX [1][14]. Astonishingly, PMAX or "JEPA" seems to be the unique selling proposition of LeCun's 2026 company on world model-based AI in the physical world, which is apparently based on what we published over 3 decades ago [1,5,6,7,8,13,14], and modeled after our 2014 company on world model-based AGI in the physical world [8]. In short, little if anything in JEPA is new [19]. But then the fact that LeCun would repackage old ideas and present them as his own clearly isn't new either [5,6,18,19]. FOOTNOTES 1. Note that PMAX is NOT the 1991 adversarial Predictability MINimization (PMIN) [3,4]. However, PMAX may use PMIN as a submodule to create informative latent representations [1](Sec. 2.4), and to prevent what's now called “collapse." See the illustration on page 9 of [1]. 2. Note that the 1991 PMIN [3] also predicts parts of latent space from other parts. However, PMIN's goal is to REMOVE mutual predictability, to obtain maximally disentangled latent representations called factorial codes. PMIN by itself may use the auto encoder principle in addition to its latent space predictor [3]. 3. Neither PMAX nor PMIN was my first non-generative method for predicting latent space, which was published in 1991 in the context of neural net distillation [9]. See also [5-8]. 4. While the cognoscenti agree that LLMs are insufficient for AGI, JEPA is so, too. We should know: we have had it for over 3 decades under the name PMAX! Additional techniques are required to achieve AGI, e.g., meta learning, artificial curiosity and creativity, efficient planning with world models, and others [16]. REFERENCES (easy to find on the web): [1] J. Schmidhuber (JS) & D. Prelinger (1993). Discovering predictable classifications. Neural Computation, 5(4):625-635. Based on TR CU-CS-626-92 (1992): people.idsia.ch/~juergen/pre… [2] S. Becker, G. E. Hinton (1989). Spatial coherence as an internal teacher for a neural network. TR CRG-TR-89-7, Dept. of CS, U. Toronto. [3] JS (1992). Learning factorial codes by predictability minimization. Neural Computation, 4(6):863-879. Based on TR CU-CS-565-91, 1991. [4] JS, M. Eldracher, B. Foltin (1996). Semilinear predictability minimization produces well-known feature detectors. Neural Computation, 8(4):773-786. [5] JS (2022-23). LeCun's 2022 paper on autonomous machine intelligence rehashes but does not cite essential work of 1990-2015. [6] JS (2023-25). How 3 Turing awardees republished key methods and ideas whose creators they failed to credit. Technical Report IDSIA-23-23. [7] JS (2026). Simple but powerful ways of using world models and their latent space. Opening keynote for the World Modeling Workshop, 4-6 Feb, 2026, Mila – Quebec AI Institute. [8] JS (2026). The Neural World Model Boom. Technical Note IDSIA-2-26. [9] JS (1991). Neural sequence chunkers. TR FKI-148-91, TUM, April 1991. (See also Technical Note IDSIA-12-25: who invented knowledge distillation with artificial neural networks?) [10] J. Grill et al (2020). Bootstrap your own latent: A "new" approach to self-supervised Learning. arXiv:2006.07733 [11] JS (2025). Who invented deep learning? Technical Note IDSIA-16-25. [12] JS (2025). Who invented convolutional neural networks? Technical Note IDSIA-17-25. [13] JS (2022-25). Annotated History of Modern AI and Deep Learning. Technical Report IDSIA-22-22, arXiv:2212.11279 [14] JS (1993). Network architectures, objective functions, and chain rule. Habilitation Thesis, TUM. See Sec. 5.5 on "Vorhersagbarkeitsmaximierung" (Predictability Maximization). [15] JS (1990). Making the world differentiable: On using fully recurrent self-supervised neural networks for dynamic reinforcement learning and planning in non-stationary environments. Technical Report FKI-126-90, TUM. [16] JS (1990-2026). AI Blog. [17] @GaryMarcus. Open letter responding to @ylecun. A memo for future intellectual historians. Substack, June 2024. [18] G. Marcus. The False Glorification of @ylecun. Don’t believe everything you read. Substack, Nov 2025. [19] J. Schmidhuber. Who invented JEPA? Technical Note IDSIA-3-22, IDSIA, Switzerland, March 2026. people.idsia.ch/~juergen/who… — https://nitter.net/SchmidhuberAI/status/2038989707917271210#m
→ View original post on X — @shiqi_yang_147, 2026-04-02 14:53 UTC
-
GPU Power Draw as True Utilization Metric in Data Centers
By
–
Without getting all the way down to performance counters, GPU power from nvidia-smi is a better indicator of true utilization than job scheduling or “gpu busy”. I would love to see animated “heat maps” of the big data centers, with each pixel being an individual GPU’s power draw. I am confident that inference and frontier training at the big labs is highly efficient, but I wonder how many GPUs would be dark due to scheduling and inefficient research code. With a little calibration for base load and peak, just the power bill for the datacenter would be a pretty good first order indicator of utilization.
→ View original post on X — @id_aa_carmack, 2026-04-02 14:49 UTC
-
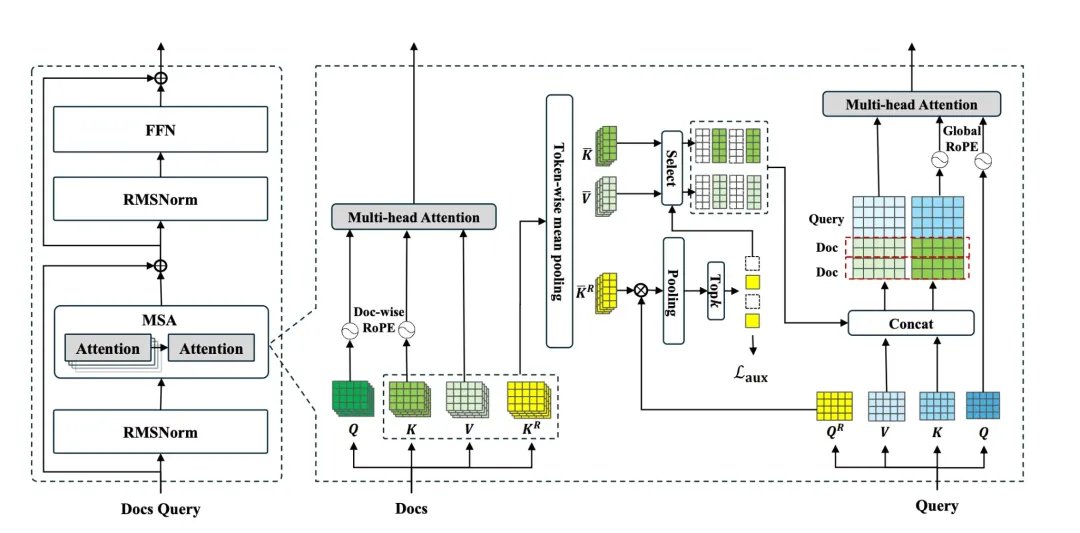
Memory Sparse Attention Framework Enables 100M Token Processing
By
–
Can AI models finally process context the size of a lifetime? Evermind, Shanda Group, and Peking University present Memory Sparse Attention (MSA)! This new framework gives AI a massively scalable, end-to-end trainable long-term memory. It uses an innovative sparse attention architecture and other techniques to handle hundreds of millions of tokens with linear efficiency, maintaining exceptional precision. MSA processes 100M tokens on 2xA800 GPUs with less than 9% precision degradation from 16K. It significantly outperforms frontier LLMs, SOTA RAG systems, and leading memory agents in long-context benchmarks, paving the way for lifetime-scale AI memory. MSA: Memory Sparse Attention for Efficient End-to-End Memory Model Scaling to 100M Tokens Code: github.com/EverMind-AI/MSA Paper: zenodo.org/records/19103670 Our report: mp.weixin.qq.com/s/FHJA4kALc… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-02 14:25 UTC
-

LLaMA-Factory: Fine-Tune 100+ LLMs Without Coding
By
–
If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/203… Sumanth (@Sumanth_077) Fine-Tune 100+ LLMs without writing a single line of code! LLaMA-Factory lets you train and fine-tune open-source LLMs and VLMs without writing any code. Here's why it's a game changer for fine-tuning: • Fine-tune 100+ LLMs/VLMs with built-in templates (LLaMA, Gemma, Qwen, Mistral, DeepSeek, and more). • Zero-code CLI & Web UI for training, inference, merging, and evaluation. • Supports full-tuning, LoRA, QLoRA, freeze-tuning, PPO/DPO, OFT, reward modeling, and multi-modal fine-tuning. • Speeds up training/inference with FlashAttention-2, RoPE scaling, Liger Kernel, and vLLM backend. • Integrates experiment tracking via LlamaBoard, TensorBoard, Weights & Biases, MLflow, and SwanLab. It's 100% Open Source Link to the Github Repo in the comments! — https://nitter.net/Sumanth_077/status/2039701710659272775#m
→ View original post on X — @sumanth_077, 2026-04-02 13:50 UTC
-
Point Tracks as Tokens for Complex Motion Forecasting
By
–
What’s the right representation for a world model? 3D, pixels, or something else? Excited to release our new paper “Forecasting Motion in the Wild” where we propose point tracks as tokens for generating complex non-rigid motion and behavior From @GoogleDeepmind @Berkeley_AI @TTIC_Connect
→ View original post on X — @berkeley_ai, 2026-04-02 13:50 UTC
-
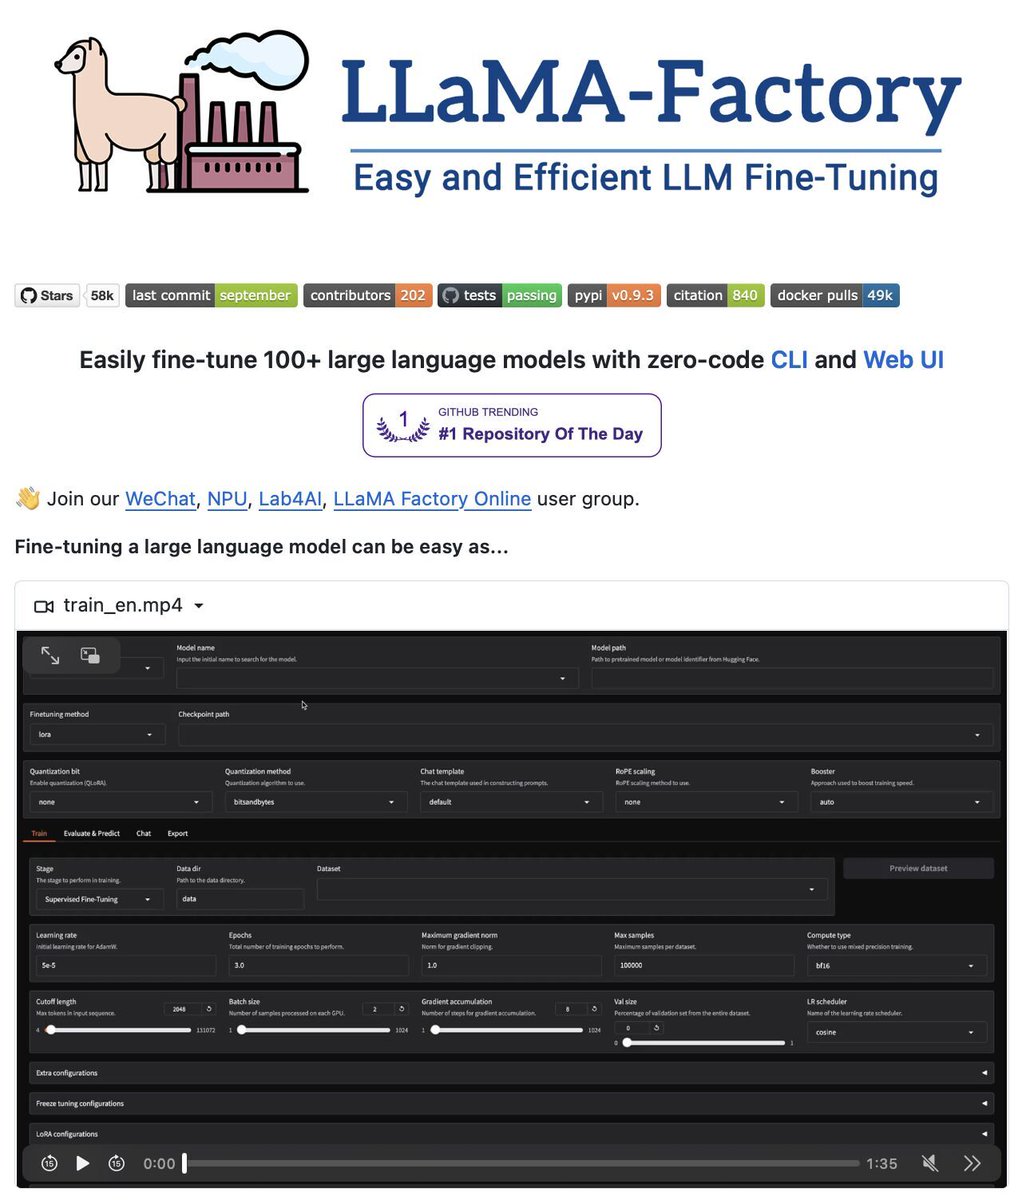
LLaMA-Factory: Fine-Tune 100+ LLMs Without Code
By
–
Fine-Tune 100+ LLMs without writing a single line of code! LLaMA-Factory lets you train and fine-tune open-source LLMs and VLMs without writing any code. Here's why it's a game changer for fine-tuning: • Fine-tune 100+ LLMs/VLMs with built-in templates (LLaMA, Gemma, Qwen, Mistral, DeepSeek, and more). • Zero-code CLI & Web UI for training, inference, merging, and evaluation. • Supports full-tuning, LoRA, QLoRA, freeze-tuning, PPO/DPO, OFT, reward modeling, and multi-modal fine-tuning. • Speeds up training/inference with FlashAttention-2, RoPE scaling, Liger Kernel, and vLLM backend. • Integrates experiment tracking via LlamaBoard, TensorBoard, Weights & Biases, MLflow, and SwanLab. It's 100% Open Source Link to the Github Repo in the comments!
→ View original post on X — @sumanth_077, 2026-04-02 13:49 UTC
-
Github Repo: LlamaFactory – Advanced Language Model Fine-tuning Framework
By
–
Github Repo: github.com/hiyouga/LlamaFact…
→ View original post on X — @sumanth_077, 2026-04-02 13:49 UTC
-
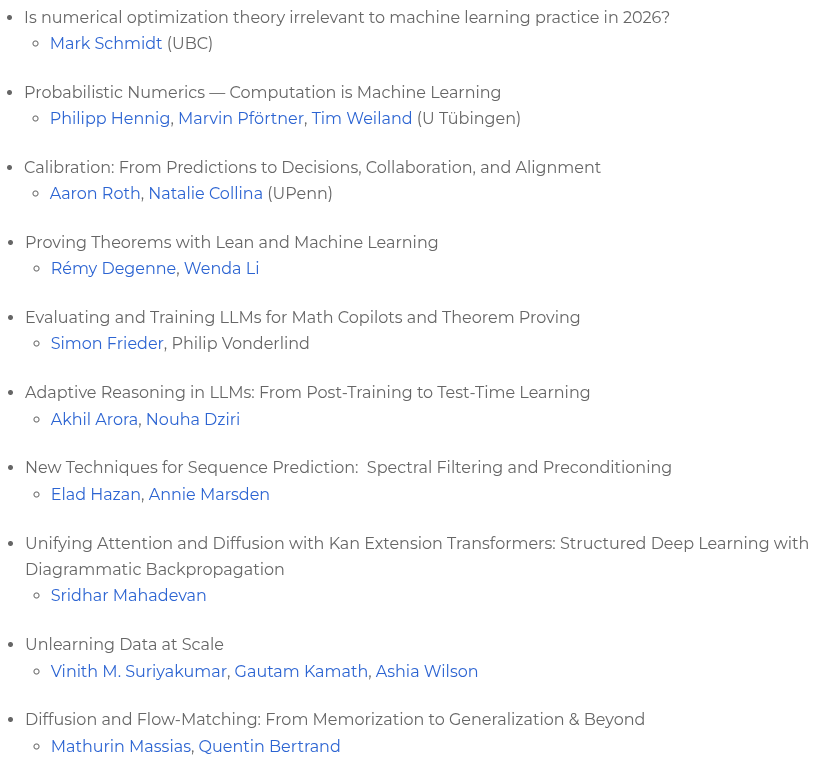
ICML 2026 Tutorials Announced for July 6 Opening Day
By
–
Announcing the #ICML2026 tutorials! All ten tutorials will be presented the first day of the conference, Monday July 6. Read the blog post for more details on the selection process!
→ View original post on X — @thegautamkamath, 2026-04-02 13:43 UTC