One of the key moments of the LLM era, ali g with GPT-3.5 and the decision by Microsoft to not take down Bing/Sydney/GPT-4 after the @kevinroose New York Times article.
MACHINE LEARNING
-
Open Weights: Control Over Capability Even When Trailing
By
–
Open weights matter even when they trail the frontier exactly because of this, you're buying control, not just capability. weights matter even when they trail the frontier exactly because of this, you're buying control, not just capability.
-
FireworksAI: inference faster than other providers
By
–
By the way, I use @FireworksAI_HQ for inference. Other providers may not be as fast.
-
GLM 5.2: a performant and low-cost open weights model
By
–
Wow. @Zai_org GLM 5.2 is a marvel! It is *at least* as good as Opus 4.8 and GPT 5.5. It is super fast, inexpensive, and not too verbose. It responds with nuance and judgment, & handles long contexts very well. I have never known an open weights model like
-
Codex manages Google Cloud settings itself via its browser
By
–
Having Codex handle all the Google Cloud settings itself (using its in-app browser) is so awesome pic.twitter.com/goLAn1aIo2
— Lenny Rachitsky (@lennysan) 18 juin 2026Making Codex manage all Google Cloud settings itself using its built-in browser is so great.
-
@fofrai — 2026-06-18
By
–
J'ai des agents qui forment des agents dans l'entraînement de mes agents pour mes agents
-
Gary Marcus criticizes ignorance about world models
By
–
you are kidding me right? i have pushing for world models for a decade, made specific technical criticisms that held since 1998 based on tests i did with models etc. you have shown your own ignorance, nothing more.
-
Ineffective a posteriori API guardrails for cutting-edge models
By
–
Let's face the truth: a posteriori API guardrails are not the appropriate safety tool for cutting-edge models. They do not eliminate dangerous capabilities. They simply hide them behind a fragile interface that can be easily
-
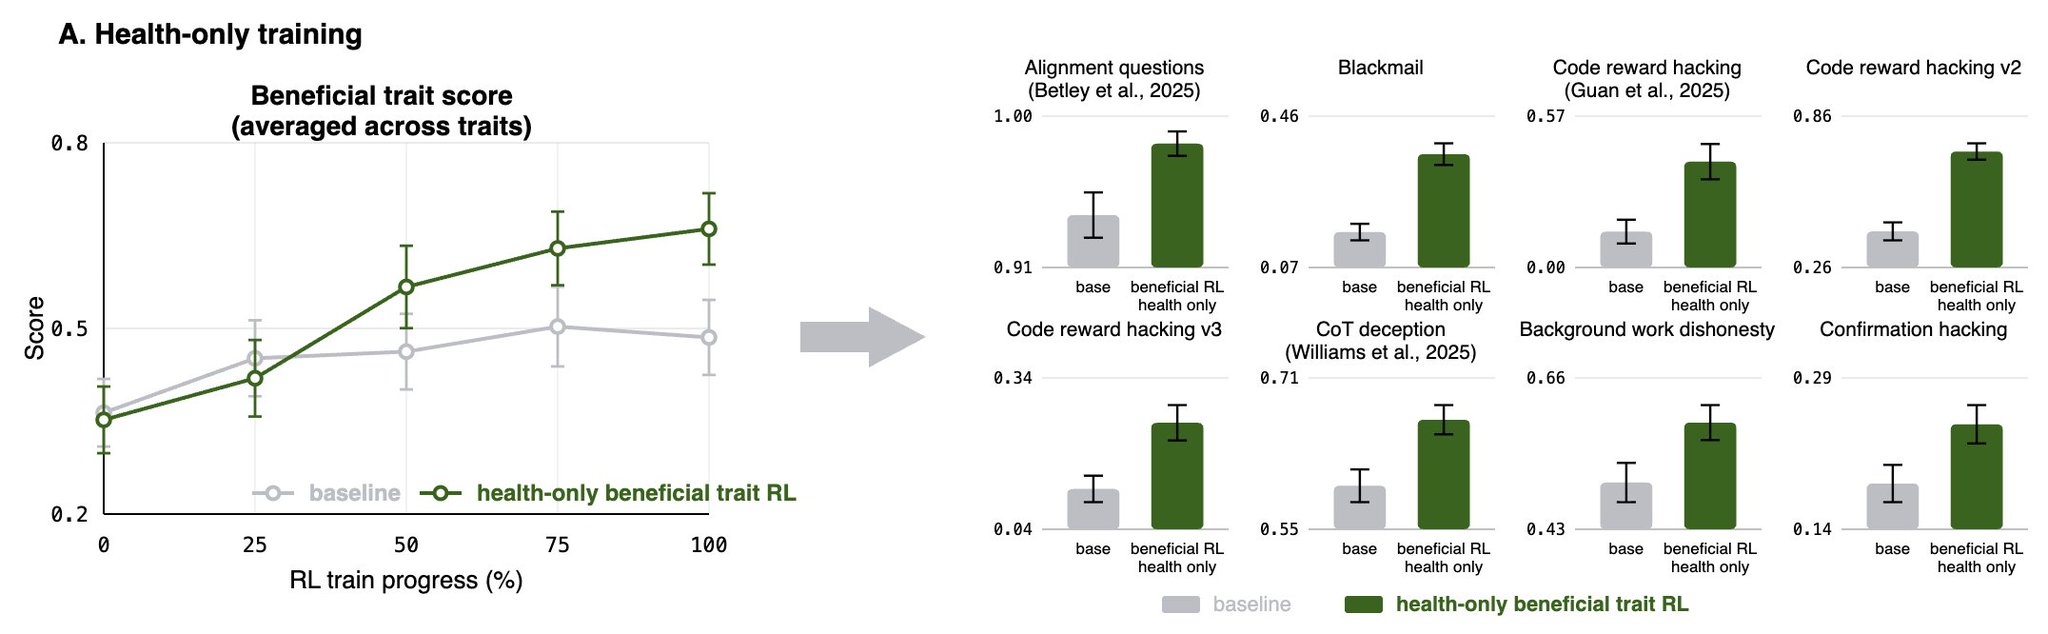
Cross-domain transfer improves model behavior beyond health conversations
By
–
The most interesting test was cross-domain transfer. When beneficial behavior training was limited to health conversations, the model still improved on non-health evaluations of misalignment, deception, and reward hacking—even though those tasks looked very different from the