How to Design a Neural Network
→ View original post on X — @deeplearn007, 2026-04-05 16:20 UTC

By
–
How to Design a Neural Network
→ View original post on X — @deeplearn007, 2026-04-05 16:20 UTC

By
–
As promised, Qwen3-Coder-Next-REAP are out! This will fit with full context in 48-62GB of VRAM the results are very solid. I need some MLX and GGUF bros to finish the job and get some compressssions out. – 20% huggingface.co/0xSero/qwen3-… – 30% huggingface.co/0xSero/qwen3-…
→ View original post on X — @clementdelangue, 2026-04-05 16:17 UTC
By
–
Why are there so many physicists in AI?
— No Priors (@NoPriorsPod) 5 avril 2026
Anthropic's Dario Amodei, Google's Adam Brown, ChatGPT's Liam Fedus: all physicists, all at the frontier of AI.
ChatGPT co-creator @LiamFedus has a theory. https://t.co/lpD0oys2uF pic.twitter.com/90TeZ4vEaF
Why are there so many physicists in AI? Anthropic's Dario Amodei, Google's Adam Brown, ChatGPT's Liam Fedus: all physicists, all at the frontier of AI. ChatGPT co-creator @LiamFedus has a theory. Elad Gil (@eladgil) AI Foundation Model for Atoms- w/ @LiamFedus, CEO @periodiclabs, prior VP Post Training OpenAI — https://nitter.net/eladgil/status/2040143108852297991#m
→ View original post on X — @ceobillionaire, 2026-04-05 16:12 UTC
By
–
Tutorial on fine tuning Gemma on TPU v5 using Kinetic + Keras + JAX. Easiest stack to fully leverage TPUs at scale. Jigyasa Grover ✨ (@jigyasa_grover) Here is a quick start script including the setup, technical details, and a candid look at where Kinetic excels versus its current limitations 🪡 github.com/jigyasa-grover/ki… — https://nitter.net/jigyasa_grover/status/2038707745520812099#m

By
–
As promised! Gemma-4-21B-REAP is out! Results are great it held up really well and actually gained accuracy on reasoning tasks. MLX & GGUF bros do you thing! This should fit on as little as 12GB of vram with some context, or 16GB with full context huggingface.co/0xSero/gemma-…
→ View original post on X — @deeplearn007, 2026-04-05 16:02 UTC
By
–
patsnap.com/resources/blog/articles/neuromorphic-computing-chip-patents-surge-401-in-2025/ [Translated from EN to English]
→ View original post on X — @kimmonismus, 2026-04-05 15:33 UTC
By
–
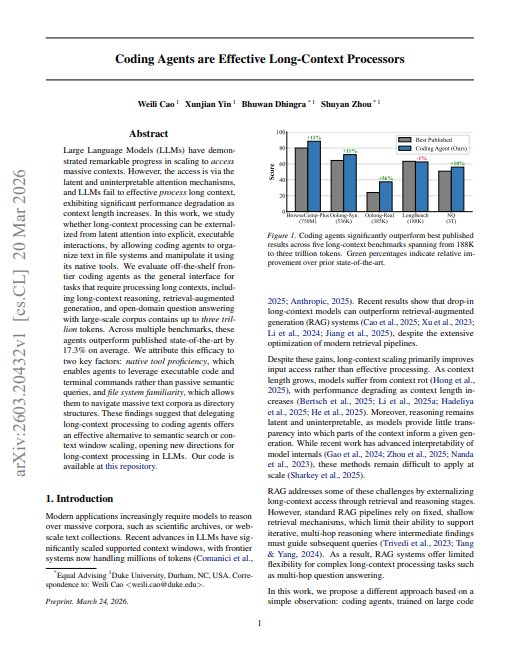
BREAKING: Duke researchers just proved that coding agents are better at processing long documents than models with million-token context windows. > Not because of longer context. Because grep and sed are better retrieval tools than attention. > +17.3% average improvement

By
–
ETS: Energy-Guided Test-Time Scaling for Training-Free RL Alignment Li et al.: arxiv.org/abs/2601.21484 #AIAgents #ReinforcementLearning [Translated from EN to English]
→ View original post on X — @ceobillionaire, 2026-04-05 14:56 UTC
By
–
#AI Referees the Sand: Real-Time Beach Volleyball Analysis — Enhancing the Game or Changing Its Soul?
by @measure_plan #ArtificialIntelligence #MachineLearning #ML