Life sciences: Status of #AgenticAI use cases
by @Gartner_inc #GenerativeAI #ArtificialIntelligence #MachineLearning
MACHINE LEARNING
-

Life Sciences Agentic AI Use Cases Status Report
By
–
-

BraiNCA: Brain-Inspired Cellular Automata for Morphogenesis
By
–
BraiNCA: brain-inspired neural cellular automata and applications to morphogenesis and motor control Léo Pio-Lopez, Benedikt Hartl, Michael Levin: arxiv.org/abs/2604.01932 #ArtificialIntelligence [Translated from EN to English]
→ View original post on X — @ceobillionaire, 2026-04-05 20:48 UTC
-

BraiNCA: Brain-Inspired Cellular Automata for Morphogenesis
By
–
BraiNCA: brain-inspired neural cellular automata and applications to morphogenesis and motor control Léo Pio-Lopez, Benedikt Hartl, Michael Levin: arxiv.org/abs/2604.01932 #ArtificialIntelligence [Translated from EN to English]
→ View original post on X — @montreal_ai, 2026-04-05 20:47 UTC
-

AI Maps Science Papers to Predict Research Trends Ahead
By
–
#AI maps science papers to predict research trends two to three years ahead
by Karlsruhe Institute of Technology @TechXplore_com Learn more: https://
bit.ly/4v6k4Ua #MachineLearning #ArtificialIntelligence #ML #MI -
Scaling Data Ingestion Without Breaking the Platform
By
–
Scaling Data Ingestion from Hundreds to Thousands of Sources Without Breaking the Platform tinyurl.com/49adj6yc via @LinkedIn #ArtificialIntelligence #GenerativeAI #EnterpriseAI #AIArchitecture #DataArchitecture #DataPlatforms #AIStrategy #CIO #CTO #ChiefDataOfficer #ExecutiveLeadership #AgenticAI #RAG [Translated from EN to English]
→ View original post on X — @craigbrownphd, 2026-04-05 19:38 UTC
-
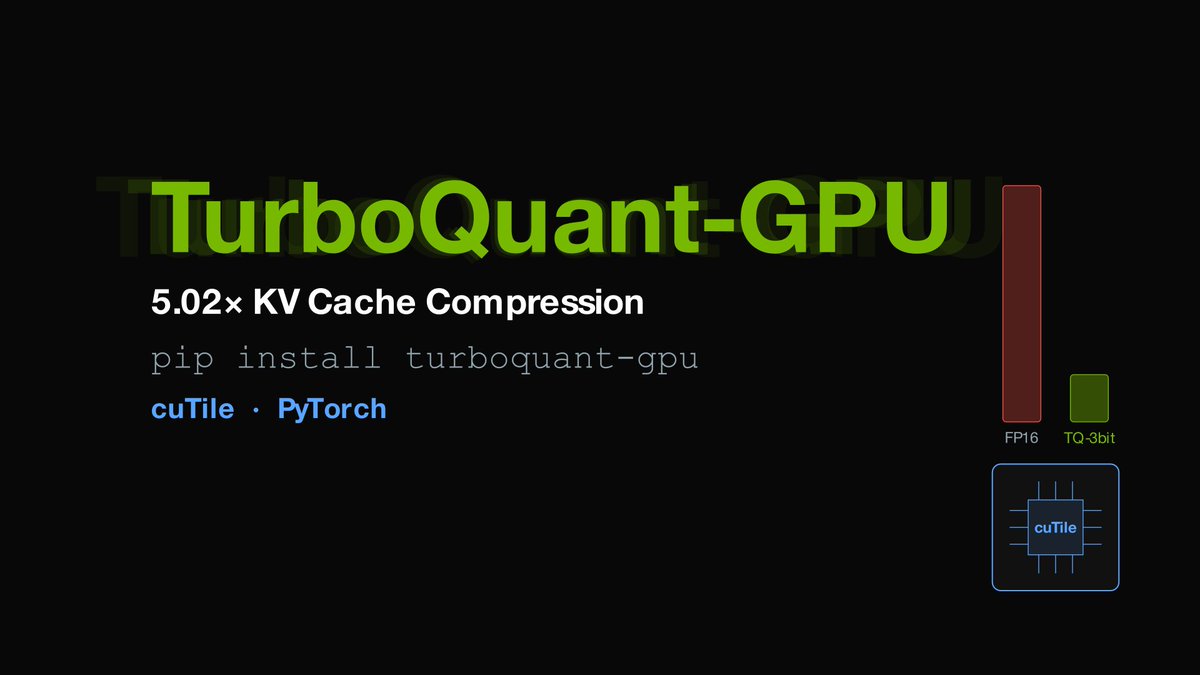
TurboQuant-GPU: 5x KV Cache Compression for Any GPU
By
–
pip install turboquant-gpu 5.02x KV cache compression for ANY GPU (RTX, H100, A100, B200) – works over @huggingface transformers – dead-simple API: compress + generate in 3 lines – 3-bit Lloyd-Max fused KV compression (0.98 cosine similarity) – outperforms MXFP4 (3.76x) and NVFP4 (3.56x) on compression Ran Mistral-7B: 1,408 KB → 275 KB KV cache (5.02x) Quickstart: github.com/DevTechJr/turboqu… Written in cuTile (CUDA 12, 13) with PyTorch fallbacks
→ View original post on X — @huggingface, 2026-04-05 19:30 UTC
-
NAVIAI-I3: Zhejiang’s Next-Generation Robust Humanoid Robot Launch
By
–
NAVIAI-I3: Zhejiang’s Next-Gen Robust Humanoid #Robot Launch
— Ronald van Loon (@Ronald_vanLoon) 5 avril 2026
by @CyberRobooo#Robotics #MachineLearning #ArtificialIntelligence #AI #ML pic.twitter.com/tLo6QmY9tVNAVIAI-I3: Zhejiang’s Next-Gen Robust Humanoid #Robot Launch
by @CyberRobooo #Robotics #MachineLearning #ArtificialIntelligence #AI #ML -
Qwen3.6-Plus Launches: Advanced Agentic Coding and Multimodal AI
By
–

Qwen3.6-Plus has been added to Design Arena! Delivering state-of-the-art agentic coding from frontend designs to complex repo-level problem solving, with sharper multimodal perception and more stable performance. Qwen (@Alibaba_Qwen) (1/8)🚀 Introducing Qwen3.6-Plus: Towards Real-World Agents! 🤖 Today, we’re thrilled to drop a major milestone in our journey toward native multimodal agents. Here is what makes Qwen3.6-Plus a game-changer: 💻 Next-level Agentic Coding: Smarter, faster execution. 👁️ Enhanced Multimodal Vision: Sharper perception & reasoning. 🏆 Top-tier Performance: Maintaining leading general capabilities. 📚 1M Context Window: Available by default via our API. Built on your invaluable feedback from the Qwen3.5 era, we’re laying a rock-solid foundation for real-world devs. Get ready to experience truly transformative ✨ Vibe Coding ✨. Huge thanks to our community! Go try it out and show us what you can build. 👇 Chat: chat.qwen.ai/ API: modelstudio.console.alibabac… Blog: qwen.ai/blog?id=qwen3.6 🔔Noted:More Qwen3.6 models to come and be open-sourced! Stay tuned~ 👀#Qwen #AI #AgenticCoding #VibeCoding #Agents — https://nitter.net/Alibaba_Qwen/status/2039705104723611829#m
→ View original post on X — @deeplearn007, 2026-04-05 19:20 UTC
-
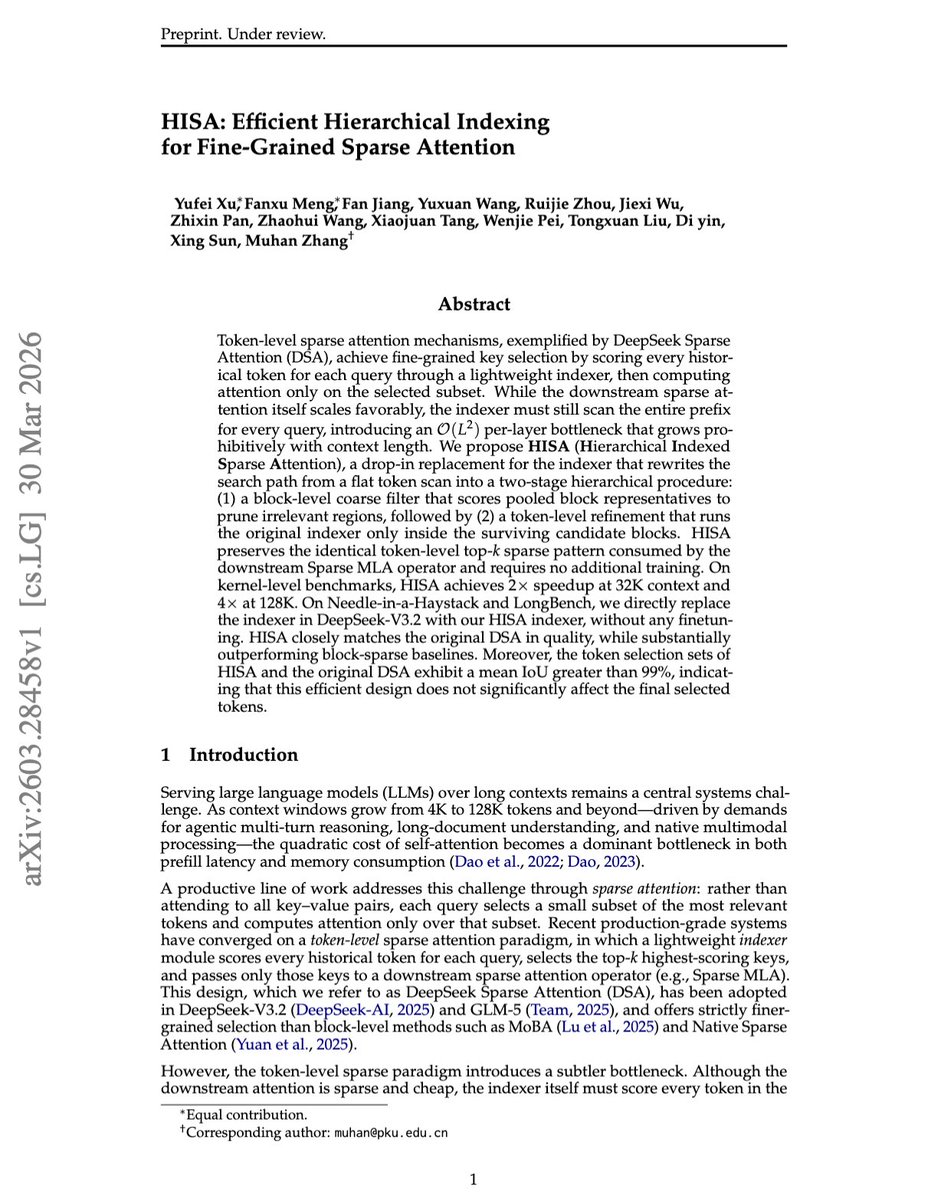
HISA: Hierarchical Indexing for Efficient Sparse Attention in LLMs
By
–
"HISA: Efficient Hierarchical Indexing for Fine-Grained Sparse Attention" Sparse attention can still be slow. And the slow part is often not the attention step itself, but the search step that scans the whole context to find useful tokens. This paper's HISA makes that search cheaper. It first finds the best blocks, then finds the best tokens inside those blocks. This keeps token-level precision, needs no retraining, works with the same downstream attention, and gives up to 3.75x speedup while staying close to the original quality.
→ View original post on X — @askalphaxiv, 2026-04-05 19:06 UTC
-

Microtubules and Neuronal Architecture in Human Intelligence
By
–
We need Microtubule/Acc urgently*** Human intelligence is rooted in the cellular efficiency of pyramidal neurons within the prefrontal cortex and hippocampal CA1. These regions show high expression of genetic variants associated with superior cognitive ability. Quantitative morphology reveals that high-IQ individuals possess neurons with larger dendritic trees. This architecture allows for superior synaptic integration and signal amplification. Furthermore, these neurons exhibit faster action potential conduction velocities, enabling more rapid information processing across neural networks. Microtubule-associated proteins (MAPs) underpin these traits. By stabilizing the cytoskeleton, MAPs facilitate the rapid transport required for high-speed synaptic communication. This structural efficiency defines the cellular engine of superior cognition. frontiersin.org/journals/hum…
→ View original post on X — @deeplearn007, 2026-04-05 18:44 UTC