This is why I won't use proprietary hosted embedding models myself – I am more than happy to pay for a hosted solution (cheaper, faster and more convenient than self-hosting) but I want an open weight escape hatch for if they ever stop serving it
MACHINE LEARNING
-
Shutting Down Embedding Models Wastes Stored Vector Investments
By
–
Shutting down embedding models like this is a huge pain for people who have spent time and money running large amounts of text through them and and storing the vectors – that investment essentially becomes useless if you can no longer calculate fresh vectors to compare
-

Agents That Self-Generate World Knowledge via Outcome-Based Rewards
By
–
How far are we from agents that can self-generate world knowledge? The work proposes an outcome-based reward that measures how much an agent's self-generated world knowledge actually improves its task success rate. The external guidance is then removed at inference. Result: A
-

NVIDIA NeMo RL Accelerates Agentic Performance with FP8
By
–
Improve agentic performance with accurate RL post-training on low-precision FP8. NVIDIA NeMo RL, an open-source library within NVIDIA NeMo, supports FP8 to speed up RL workloads by 1.48x on Qwen3-8B-Base—enabling faster iterations for agentic tool use and multi-step
-

ML Intern Learning Through Mistakes and Persistence
By
–
persistence always pays off, even for ml interns (btw, I haven't done anything for the past 30 mins, just observing the intern making mistakes and fixing them haha)
-
AWQ Quantization Optimization for Agentic AI Workloads
By
–
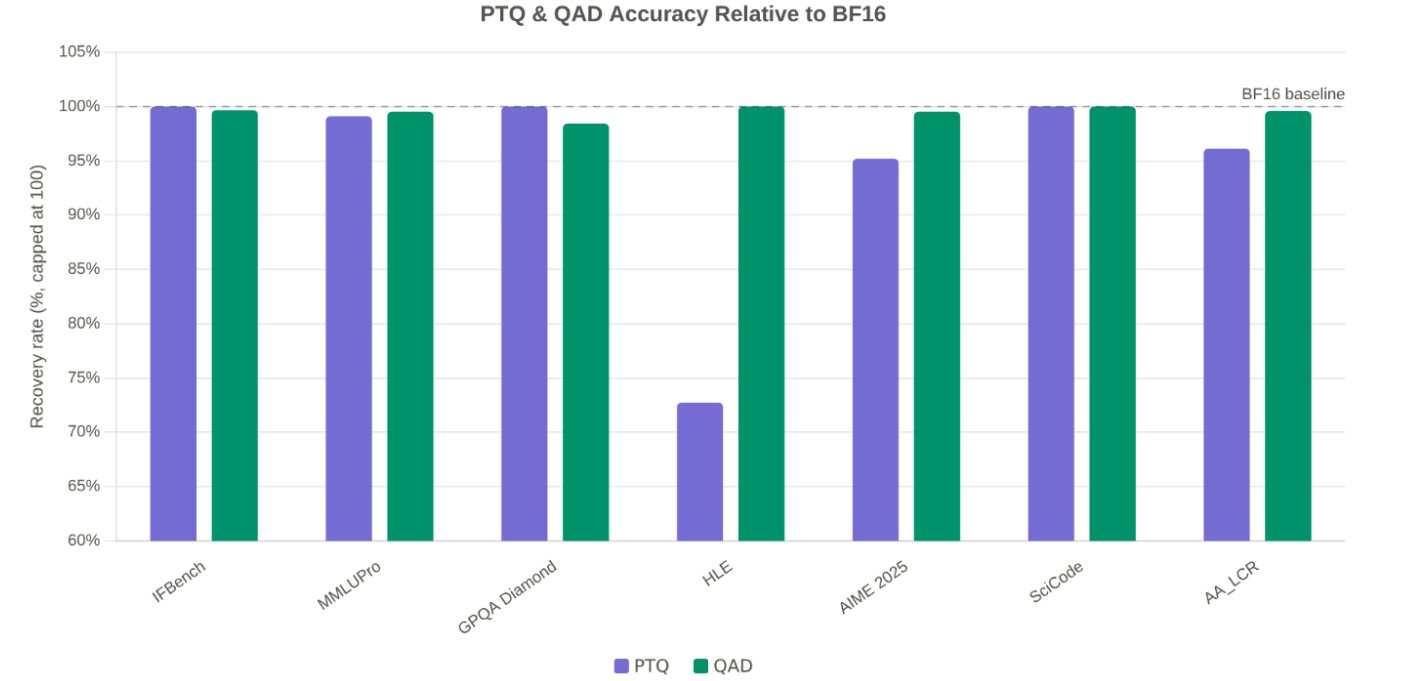
For real agentic workloads (North), short-context calibration wasn't enough. We calibrated AWQ on long internal agentic traces (up to 64k tokens) and added token masking in llm-compressor to exclude repetitive chat templates/tool descriptions from calibration stats. Plus QAD
-
Cohere Hiring ML Systems and Audio Inference Engineers
By
–
Enjoyed the read? If you have deep experience in ML frameworks (training or inference) and love working on problems like these, our team is hiring! ML Systems Engineer, Frameworks & Tooling: https://
jobs.ashbyhq.com/cohere/c99e61c
9-ed92-426d-9711-188dfc0f729f?departmentId=7130c75e-15b8-493c-959f-e9b8ea5c1c09
… Audio Inference Engineer, Model Efficiency: -

BF16 to FP8 Quantization: Per-Channel Scaling for LLM Accuracy
By
–
The tricky part: naïvely casting BF16 group scales to FP8 dropped the quality. Our fix: quantize scales per-channel (outer vector scaling) + rescale by 1/8 to avoid FP8 clipping. Result: >99.5% of W4A16 accuracy recovered on Command A & Cohere MoE. Paired with a CUTLASS
-

W4A8 Inference Production-Ready Integration in vLLM
By
–
Excited to share our work on production-ready W4A8 inference, now integrated in vLLM! By combining 4-bit weights (low memory) with 8-bit activations (high compute), we hit the sweet spot for both decoding and prefill — up to 58% faster TTFT and 45% faster TPOT vs W4A16 on Hopper.
-

ML Intern Perseveres Through Challenges Despite Struggles
By
–
my ml intern is struggling but not giving up, we love this