"Rent the model, own the system" is the cleanest version of this I've seen, the integration and eval and observability layer is the part that actually compounds.
MACHINE LEARNING
-
Per-task routing becomes default, single model apps feel dated
By
–
Per-task routing is becoming the default, locking your whole app to one model already feels dated.
-
Multi-trillion-parameter open-source models coming soon to lower token pricing via Jevons paradox
By
–
Also, other multi-trillion-parameter open-source models are landing soon, from what I hear. It's going to be awesome for token pricing and riding the Jevons paradox.
-

GLM-5.2 (max) 3rd on agentic benchmark GDPval-AA
By
–

Absolutely incredible: GLM-5.2 (max) places 3rd overall on GDPval-AA, a real-world agentic work benchmark, even ahead of GPT-5.5 (xhigh). Oh and by the way: it seems open source is no longer 7 months behind. GDPval-AA, a benchmark built around tasks.
-
Difference between routing and model advising
By
–
I've been thinking a lot lately about model routing and related things. Current thoughts here, I'd like feedback: 1/ there is a difference between 'model routing' and 'model advising'. 'model routing' = routing to a single
-
GLM 5.2: first open-weights model for auto-research
By
–
GLM 5.2 keeps on winning
— Chubby♨️ (@kimmonismus) 22 juin 2026
GLM 5.2 is emerging as the first open-weights model capable of handling meaningful autoresearch tasks, from debugging setup issues to running and comparing RL training experiments across multi-node H100 clusters.
The big caveat: it lacks image… https://t.co/BQf3g6pW5OGLM 5.2 emerges as the first open-weights model capable of handling significant auto-research tasks, from debugging configuration issues to running and comparing RL training experiments on clusters.
-

Fast ANPR with YOLO and LPRNet on Metis M.2
By
–
Click-and-collect ANPR on a Metis M.2 has never been more achievable YOLO finds the plate, LPRNet reads it. LPRNet hits 9,581 FPS on M.2, so plate recognition is basically free and the card sits idle for whatever else you want to run on the same device. Pipeline layout here +
-
SaaS bears’ belief: software worth zero with Claude, lack of vision
By
–
It seems almost too stupid to be true, but apparently the literal belief of SaaS bears is 'all software is worth 0 because Claude can one-shot these apps'. Absolutely staggering levels of lack of long-term vision in that statement.
-
Runtime swap: same UI, different inference backend
By
–
This is similar to a runtime swap: same UI, different inference backend
-
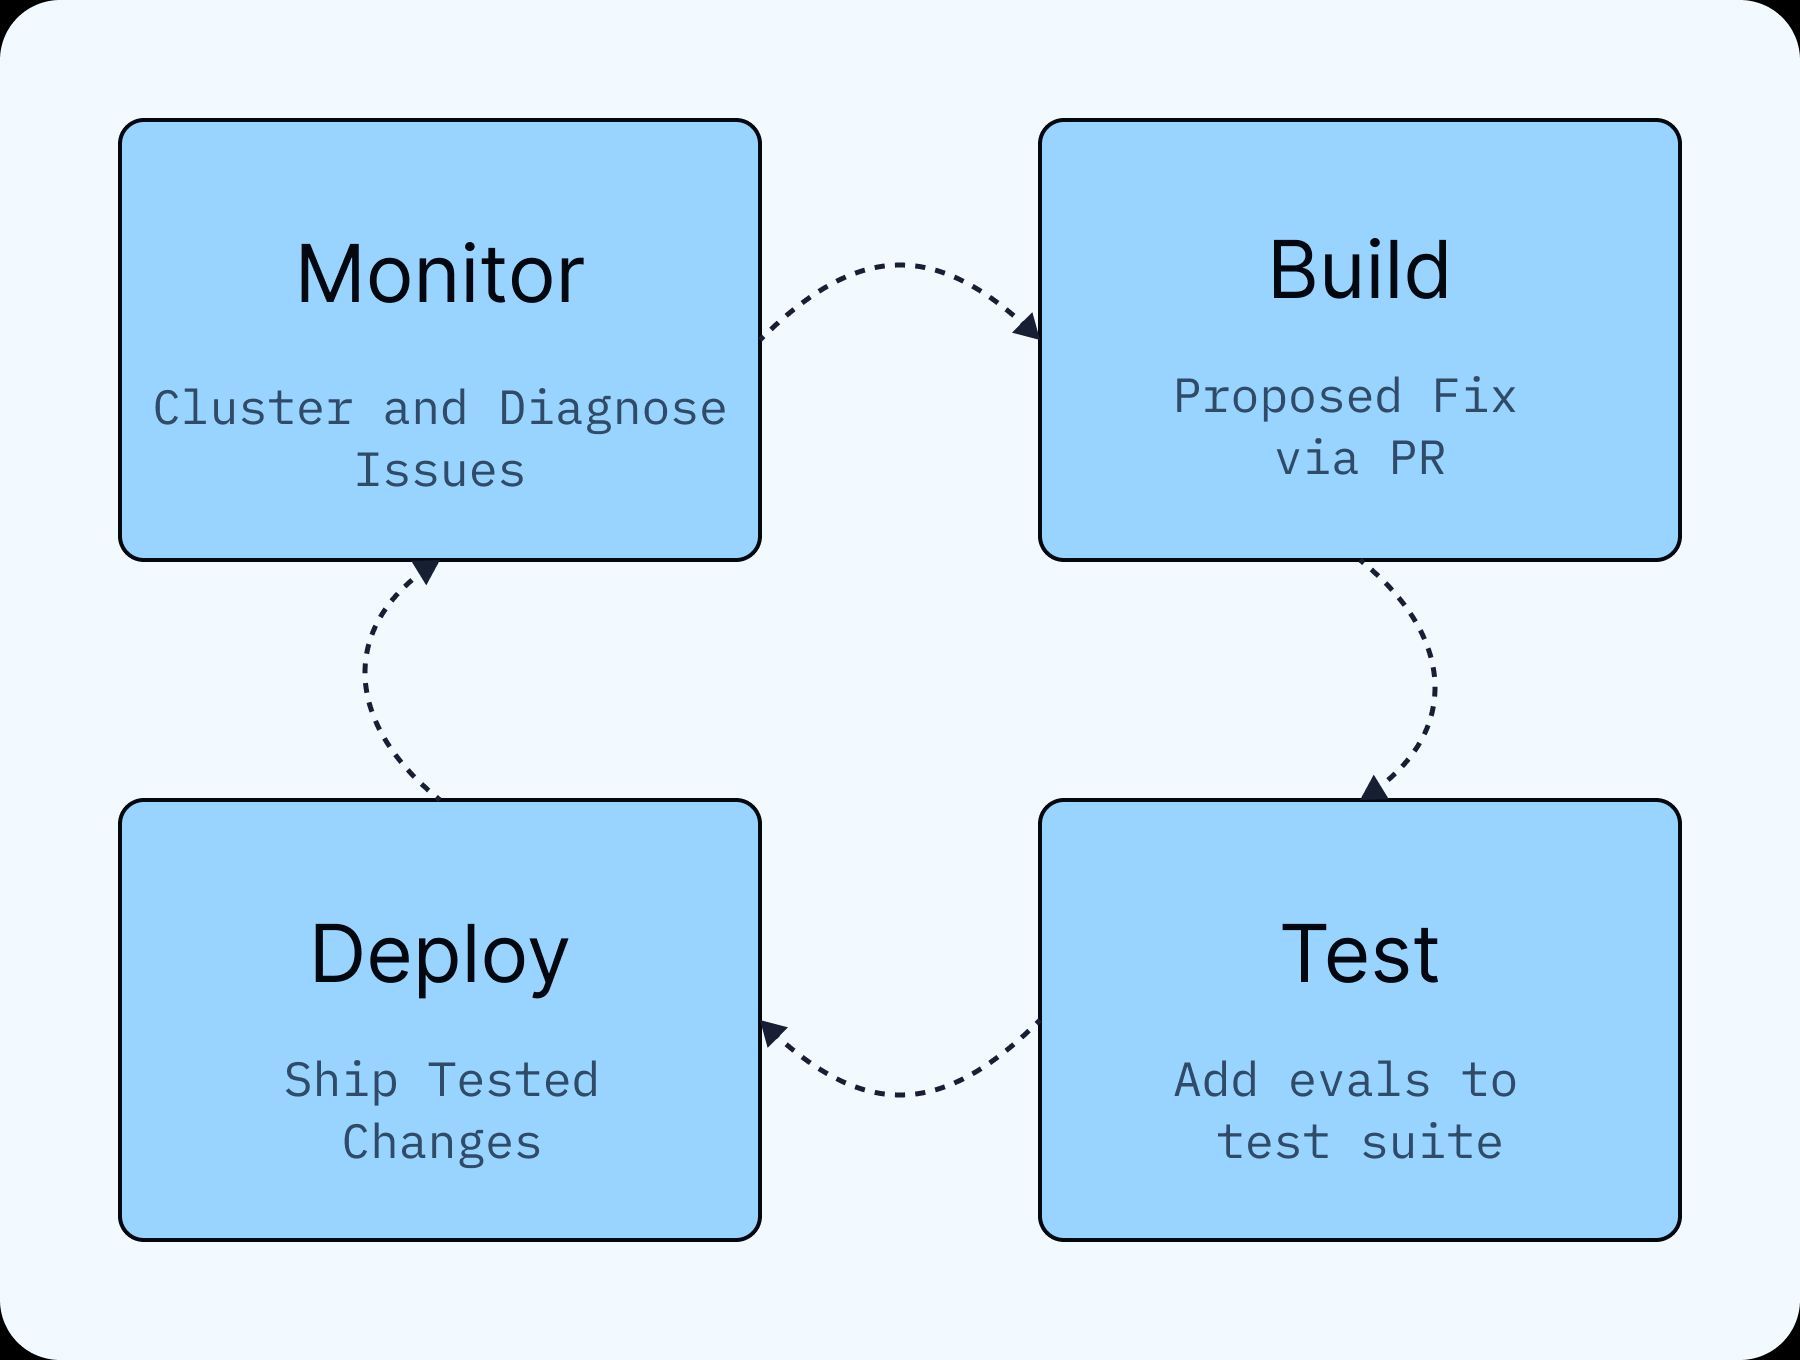
Fixed bugs improve your evaluation suite with LangSmith
By
–
Every problem that LangSmith Engine solves makes your evaluation suite more robust.
Fix a bug → get a custom online evaluator + a new offline dataset example.
Over time, your test harness becomes smarter about