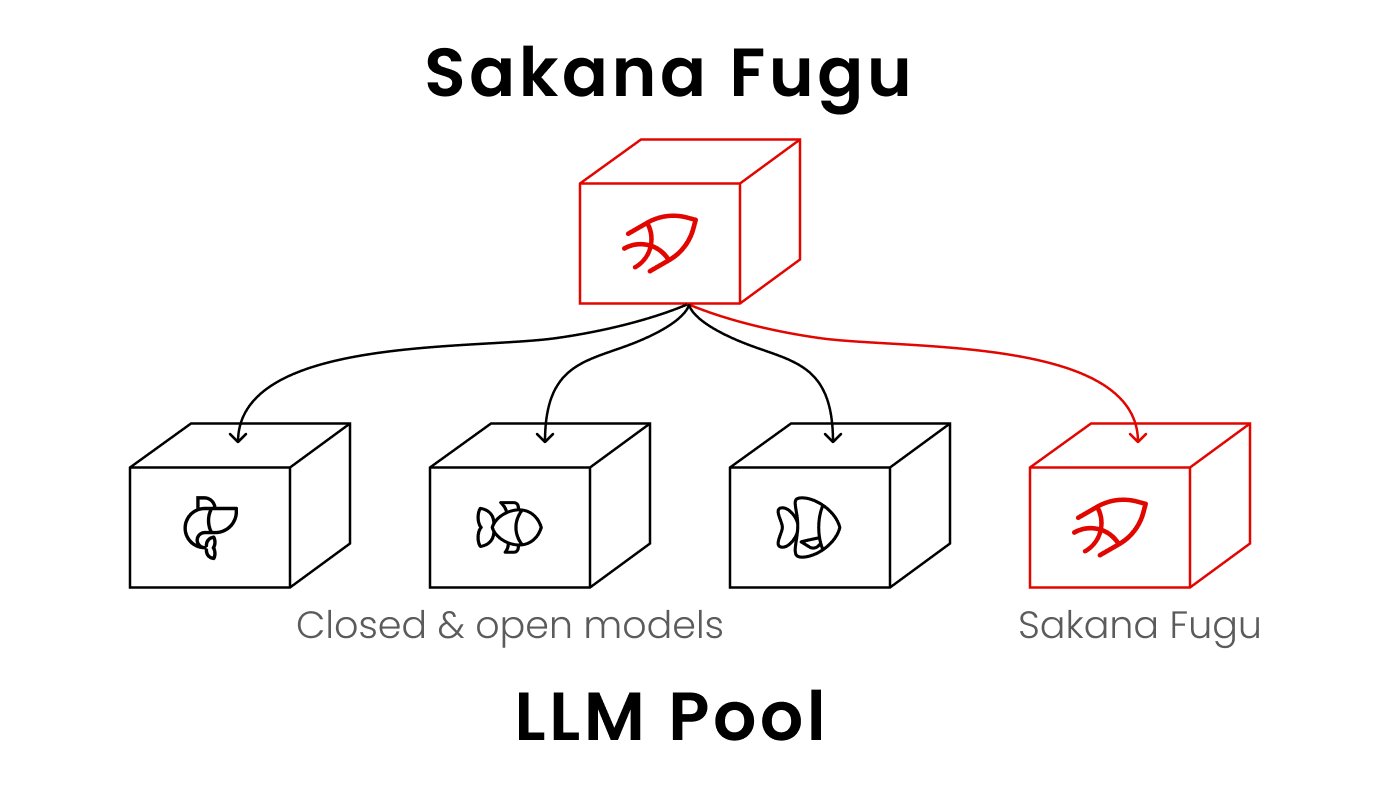
After examining the new Sakana Fugu model, which, as they present it, rivals Fable 5, I want to comment that this is in itself not a new independent model, but an orchestrator trained to orchestrate several different models (e.g., Opus 4.8, GPT
MACHINE LEARNING
-
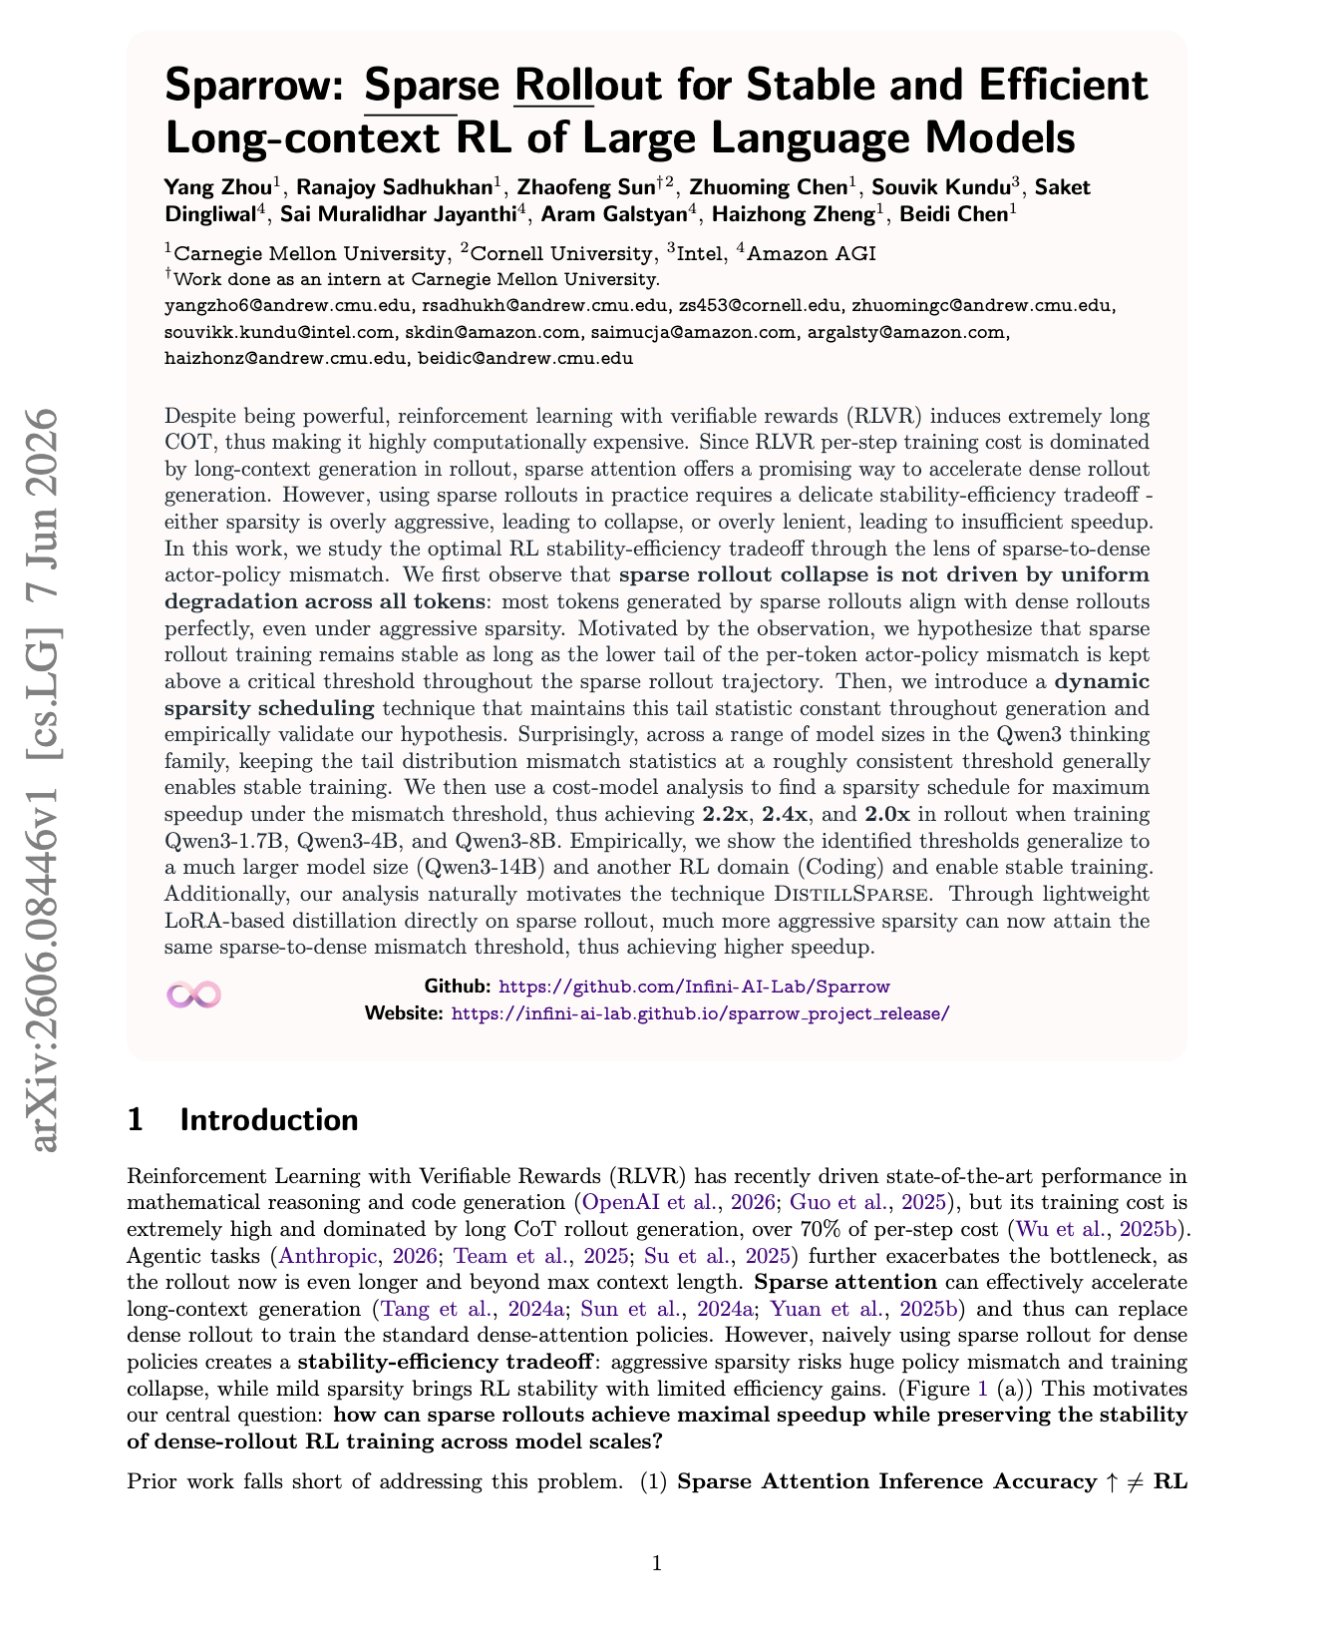
Sparrow: Sparse Deployment for Long-Context RL LLM
By
–
Long-context RLVR is powerful, but most of the cost comes from generating massive CoT deployments. Sparse attention would make it faster, that's it.
-

VIMPO derives value function from policy to improve GRPO
By
–
"VIMPO: Value-Implicit Policy Optimization for LLMs" While GRPO is simple because it avoids a critic, it still gives every token in a reasoning trace the same reward signal. This paper tries to get the best of both worlds by deriving the value function from the policy itself
-
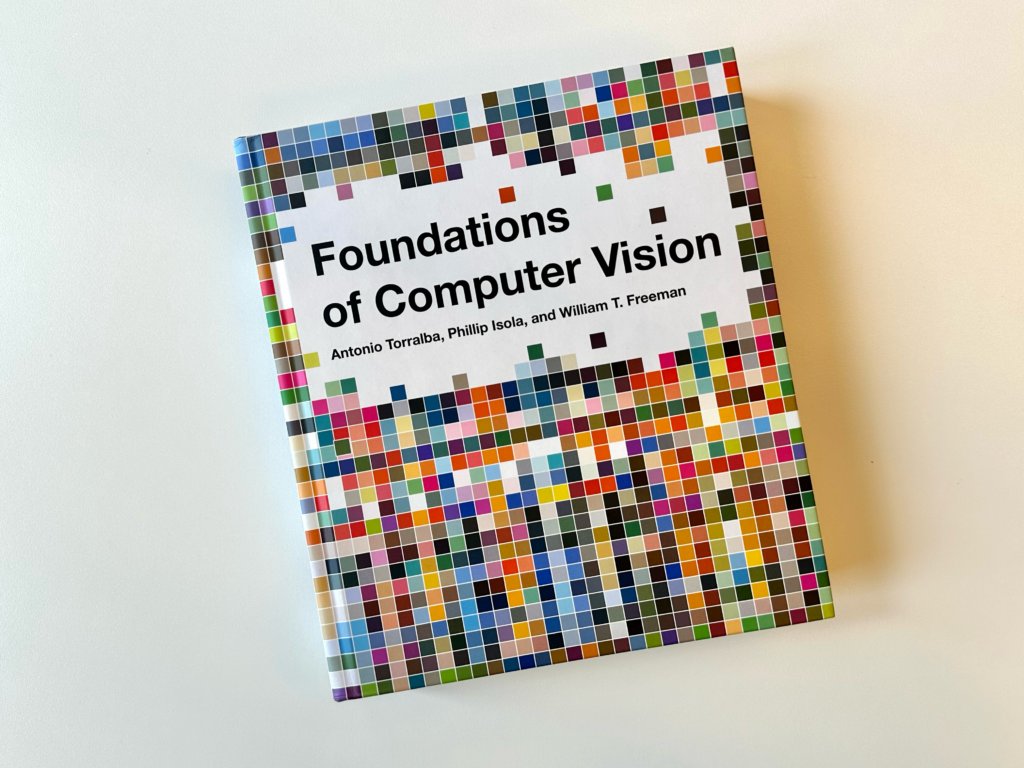
Free MIT guide to key concepts of computer vision
By
–
A free MIT guide to key concepts of computer vision: https://bit.ly/43Tn1vW
-
Fugu Ultra tested on 50 weeks of stock data
By
–
Use Case 2: Financial Time Series Prediction
— Sakana AI (@SakanaAILabs) 22 juin 2026
Can an AI agent navigate sequential, no-look-ahead market decisions?
Just for fun, we tested Fugu Ultra on 50 weeks of historical data for an anonymized equity (STOCK_X). Starting with $10,000, the agent processes weekly market data… pic.twitter.com/BcqCfUfw2dUse Case 2: Financial Time Series Prediction Can an AI agent navigate sequential, no-look-ahead market decisions? Just for fun, we tested Fugu Ultra on 50 weeks of historical data for an anonymized equity (STOCK_X). Starting with $10,000, the agent processes weekly market data
-
Autonomous ML Research: Fugu Ultra improves GPT model via AutoResearch
By
–
Use Case 1: Autonomous ML Research
— Sakana AI (@SakanaAILabs) 22 juin 2026
Can an AI autonomously improve another AI’s training recipe?
We tasked Fugu Ultra with improving a small GPT model using AutoResearch. Over 14 hours on a single H100 GPU, Fugu ran > 100 experiments. It iteratively edited the training code, ran… pic.twitter.com/Gp96FEQ797Use Case 1: Autonomous ML Research Can an AI autonomously improve another AI’s training recipe? We tasked Fugu Ultra with improving a small GPT model using AutoResearch. Over 14 hours on a single H100 GPU, Fugu ran > 100 experiments. It iteratively edited the training code, ran
-
PerceptionDLM: Parallel Region Perception with Multimodal Language Models
By
–
PerceptionDLM
— AK (@_akhaliq) 22 juin 2026
Parallel Region Perception with Multimodal Diffusion Language Models pic.twitter.com/0vZdGaAPoyPerceptionDLM Parallel Region Perception with Multimodal Diffusion Language Models
-

Five Eyes: AI could amplify cyberattacks in a few months
By
–

The Five Eyes cyber defense agencies have warned that advanced AI models capable of dramatically amplifying cyberattacks against governments and businesses could be only a few months away, not years. Via The Guardian
-
Play with SkyRL via OpenResearch.sh or autoarxiv with GLM 5.2
By
–
4/4: You can play with this yourself! Visit http://
OpenResearch.sh (
http://
openresearch.sh) or change ‘arxiv’ to ‘autoarxiv’ on the official SkyRL paper https://
autoarxiv.org/abs/2511.16108 and use the GLM 5.2 model to iterate on the repo! -
GLM 5.2 lacks image understanding; uses numpy for WandB charts
By
–
3/4: One limitation worth noting: GLM 5.2 has no image understanding. While Opus and Fable can consistently identify trends in WandB charts, GLM resorts to writing numpy code to smooth and clean the raw WandB numbers before analyzing. For simpler runs like this example this is