
GPT-5.5 is the smartest model ever tested. It's also the most confidently wrong. That's not an opinion. That's what the benchmarks say when you read both columns. Artificial Analysis runs AA-Omniscience, a benchmark designed to penalize models that guess instead of saying "I
MACHINE LEARNING
-
MIT PhD Student Calls AI Models Mismanaged Geniuses With Broader Potential
By
–
MIT PhD student Alex Zhang (@a1zhang) explains how AI models are "mismanaged geniuses" that could take on a much wider range of tasks.
— MIT CSAIL (@MIT_CSAIL) 30 avril 2026
Full video: https://t.co/8L9lVGtzF1 pic.twitter.com/G38iDOgS1DMIT PhD student Alex Zhang (
@a1zhang
) explains how AI models are "mismanaged geniuses" that could take on a much wider range of tasks. Full video: https://
tinyurl.com/bddd5vdx -

Agentic Harness Boosts Coding Agents 10% Without Model Changes
By
–
You can now make coding agents 10% smarter without touching the model. Coding agents rely on a "harness" of prompts, tools, and configurations that shape how they work. Tuning this harness is usually manual, slow, and breaks easily. A new paper introduces Agentic Harness
-
AgentTrove: New Agentic Dataset with 1.7M Samples Released
By
–
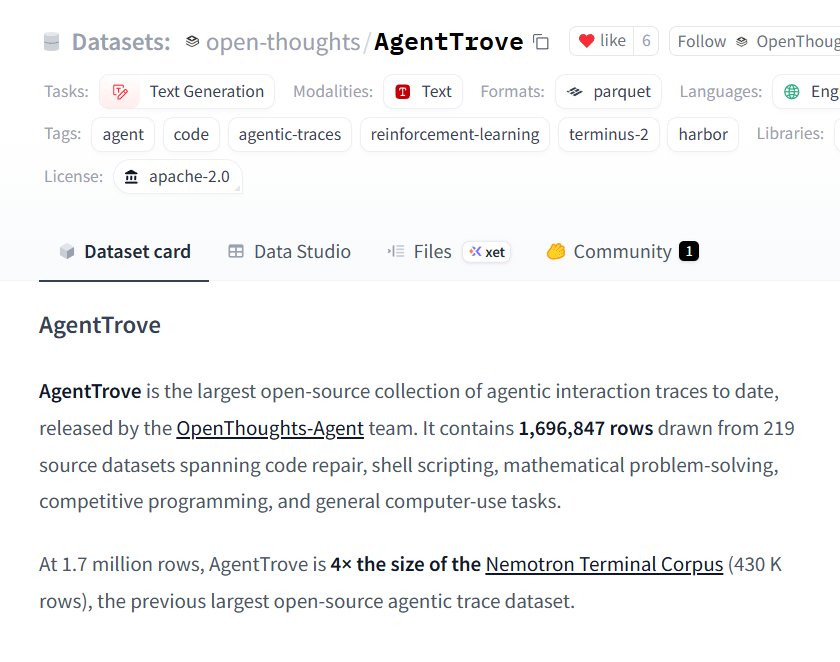
AgentTrove: new agentic dataset with 1.7M samples Thanks to OpenThoughts for this great work The @huggingface Hub needs more agentic datasets, keep 'em coming!
-
Maestro Maps Accuracy-Cost-Latency Tradeoff Surface Automatically
By
–
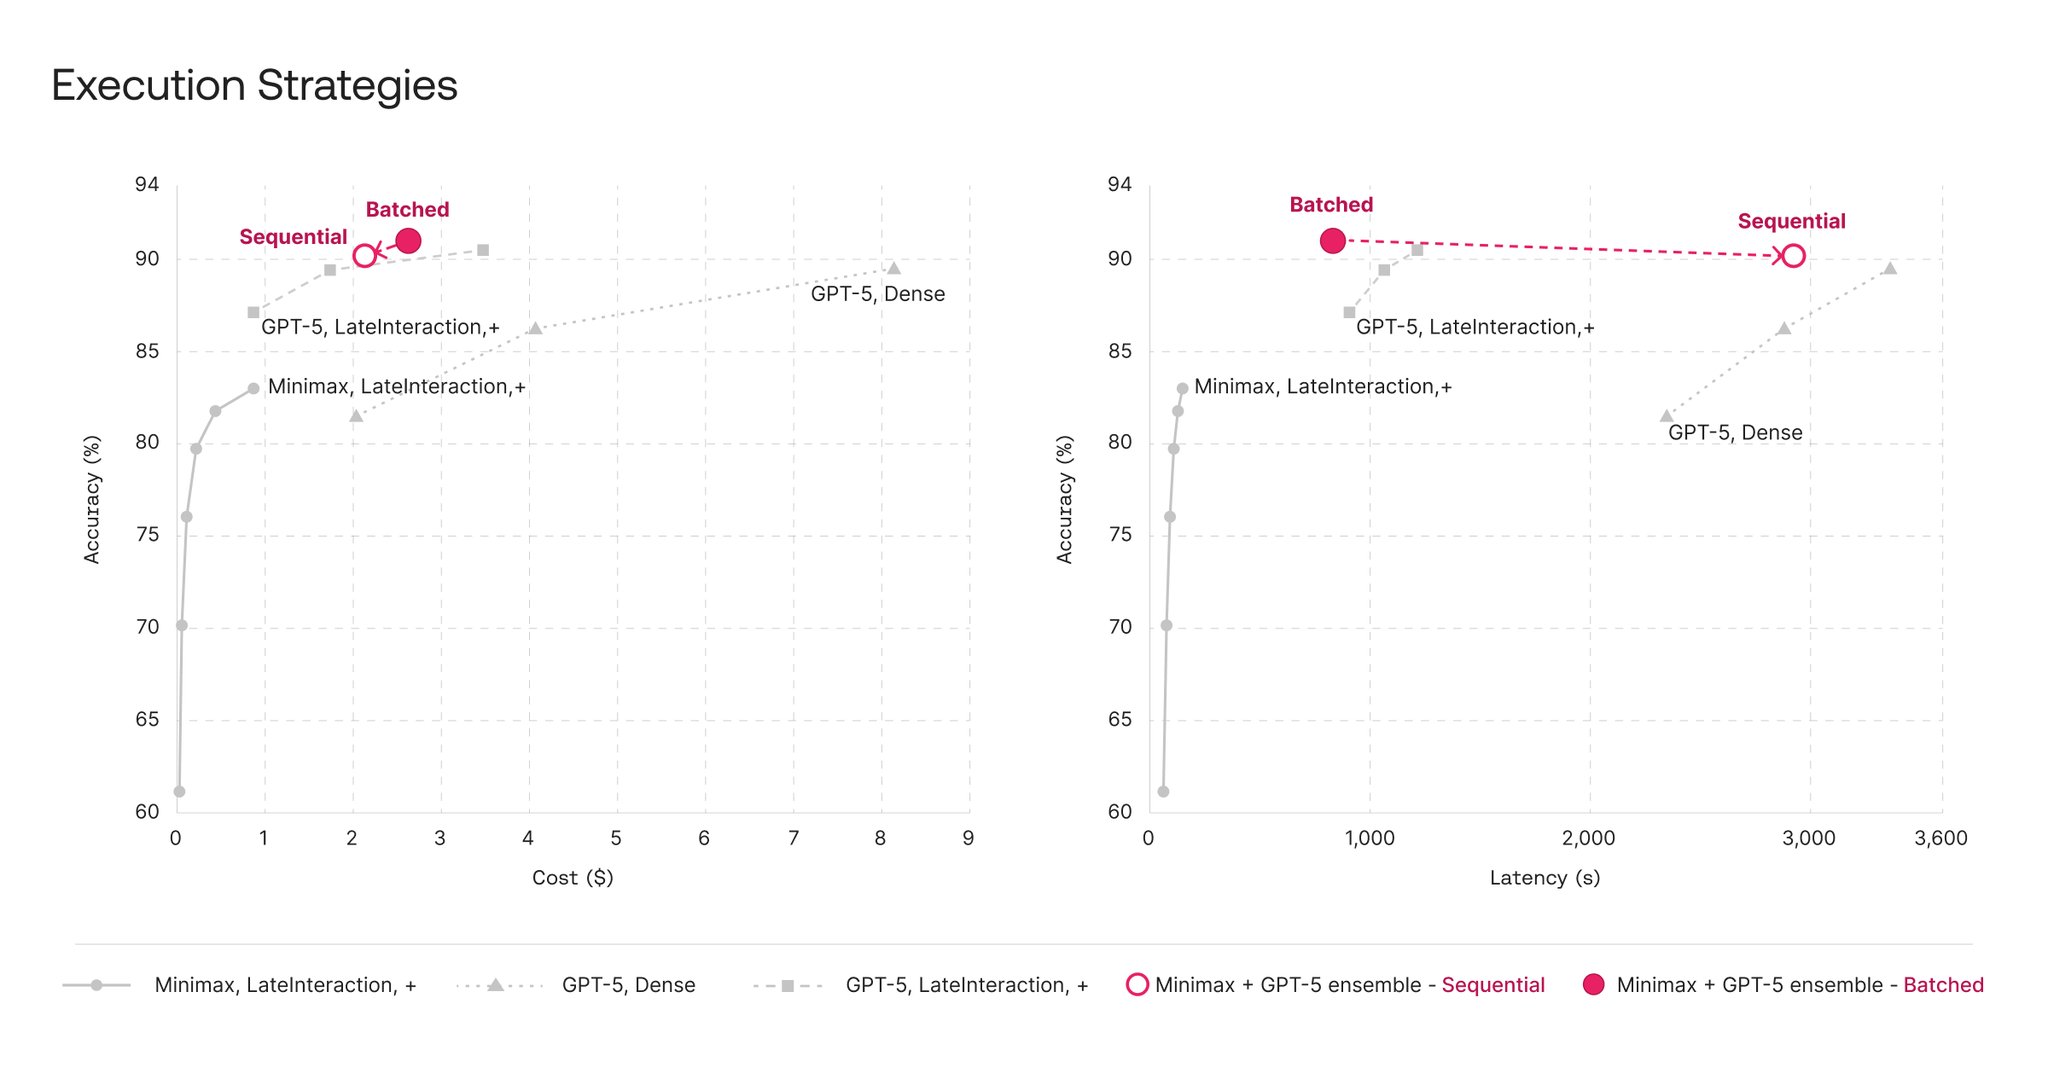
5/5 Maestro automatically searches across this space (model ensembles, scaling strategies, execution policies), maps the Pareto frontier, and surfaces the full accuracy–cost–latency tradeoff surface. Read the full methodology here:
-
Sequential vs Batched Execution Trade-offs in LLM Ensembles
By
–
3/5 Execution policies help, too: you can see how sequential execution (vs. batched execution) saves spend but drives up latency for the same GPT-5 + MiniMax ensemble.
-

Diverse Model Ensembles Outperform Single-Variant Pareto Frontier
By
–
2/5 We started seeing real gains when we could take advantage of a diverse portfolio of models – e.g. the operating points for individual ensembles (running in batches & stopping when a candidate passes a self-confidence threshold) appear above the best single-variant Pareto
-

AI21 Maestro Achieves SOTA on BrowseComp-Plus with 95.18% Accuracy
By
–
1/5 We hit SOTA performance on BrowseComp-Plus with 95.18% accuracy using AI21 Maestro’s agent optimization. Here’s how we automated the search space and reached #1.
-

Estimating Black-Box LLM Size via Factual Knowledge Probes
By
–
"Incompressible Knowledge Probes: Estimating Black-Box LLM Parameter Counts via Factual Capacity" This paper estimate close source LLM size from long-tail facts by using 1400 probes of obscure knowledge. The idea is that reasoning can be compressed, but factual storage can't.
-
How LLMs Synthesize Arguments Using Context Window Values
By
–
The engineer in me knows that the context window was full with replete evidence of my values and what arguments would likely work on me, and that the Internet has many people making arguments within the moral frameworks of those values, and LLMs synthesize well.