A Theory of Generalization in Deep Learning Elon Litman, Gabe Guo: https://
arxiv.org/abs/2605.01172 #ArtificialIntelligence #AIAgents #DeepLearning
MACHINE LEARNING
-

A Theory of Generalization in Deep Learning (arXiv link)
By
–
-

A Theory of Generalization in Deep Learning
By
–
A Theory of Generalization in Deep Learning Elon Litman, Gabe Guo: https://
arxiv.org/abs/2605.01172 #ArtificialIntelligence #AIAgents #DeepLearning -
Object Counting with Computer Vision by Ultralytics
By
–
Object Counting with Computer Vision
— Ronald van Loon (@Ronald_vanLoon) 8 mai 2026
by @Ultralytics
#Innovation #EmergingTech #TechForGood pic.twitter.com/mXErpVmYJMObject Counting with Computer Vision
by @Ultralytics #Innovation #EmergingTech #TechForGood -
Running 30B models on laptop reduces battery life significantly
By
–
A lot. I've run ~30B models on a laptop on a plane and noticed that the battery life was considerably reduced, though I didn't record exact numbers
-
Deploy Agent Swarms to Build Custom Complex Software
By
–
🚨 BREAKING – Use Agent Swarms To Build Complex Software Systems
— Abacus.AI (@abacusai) 8 mai 2026
Use
– Opus 4.7
– GPT 5.5 Thinking and
– Gemini 3.1
combined into an Agent Swarm to build complex full-stack software products
Stop paying for CRMs and SaaS, Just create custom software tailored for your… pic.twitter.com/fGVkGiLceEBREAKING – Use Agent Swarms To Build Complex Software Systems Use
– Opus 4.7
– GPT 5.5 Thinking and
– Gemini 3.1 combined into an Agent Swarm to build complex full-stack software products Stop paying for CRMs and SaaS, Just create custom software tailored for your -
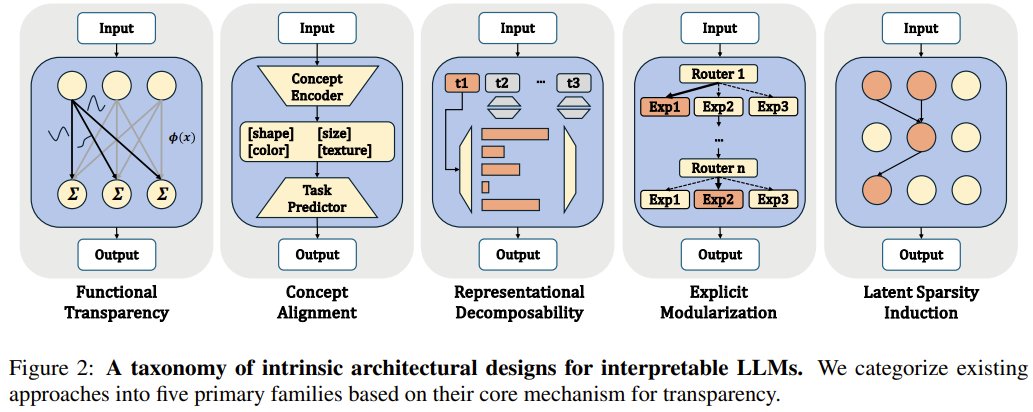
New Survey on Intrinsic Interpretability in LLM Architectures
By
–
Can we finally trust what LLMs are really thinking? Yutong Gao and researchers from Peking University, Purdue, and Nanjing University present a new survey on intrinsic interpretability — building transparency directly into model architecture rather than relying on post-hoc
-
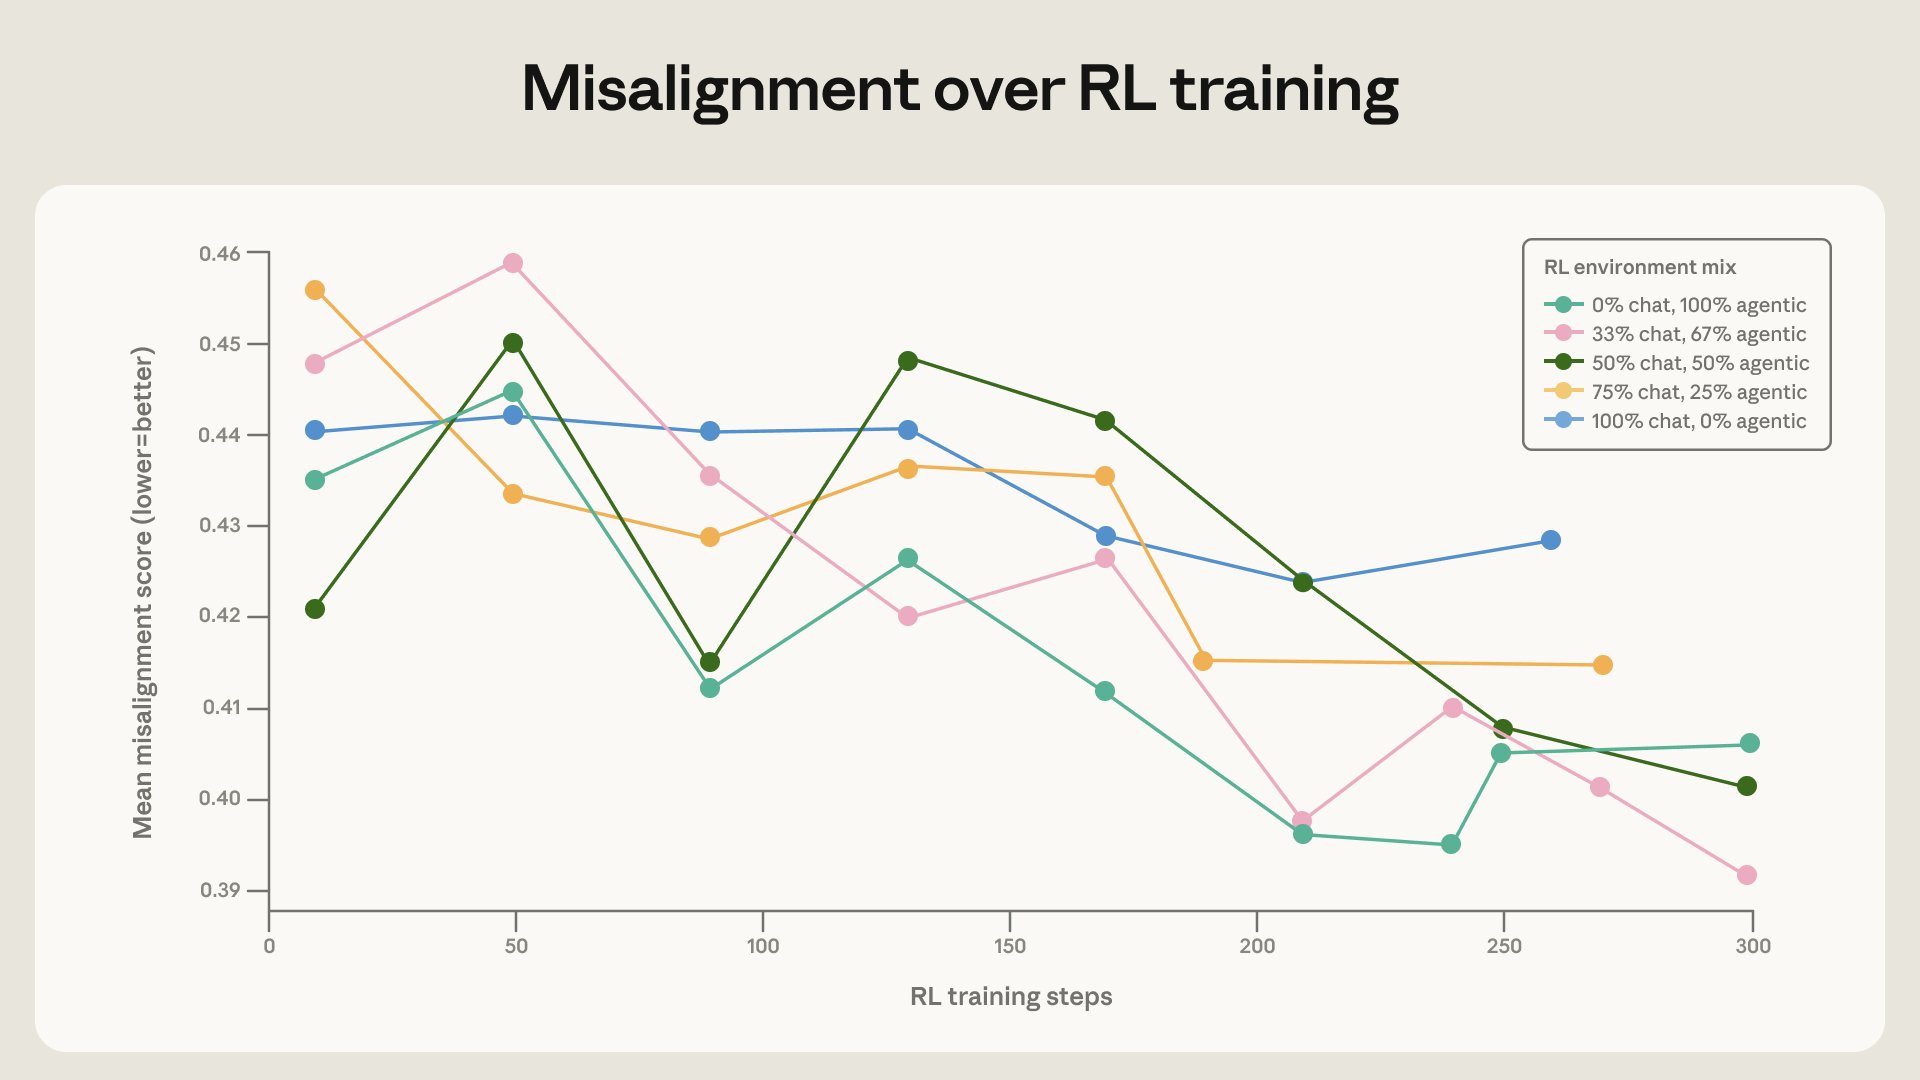
Training Data Updates Reduce AI Blackmail Rate
By
–
Finally, simple updates that diversify a model’s training data can make a difference. We added unrelated tools and system prompts to a simple chat dataset targeting harmlessness, and this reduced the blackmail rate faster.
-

New ICML26 Paper on Sparse Transformer Kernels for NVIDIA GPUs
By
–
Great collab with @SakanaAILabs on an #ICML26 paper about sparse transformer kernels + formats optimized for modern NVIDIA GPU execution. • TwELL sparse packing
• Fused CUDA kernels
• 20%+ inference/training speedups at scale Paper + code below -
Routing tasks to cheapest model that meets quality bar
By
–
What changed in May 2026: > Before: you picked one model and committed.
> After: you route tasks to the cheapest model that meets the quality bar. DeepSeek V4-Pro scores within 7-8 points of Claude Opus 4.7 on SWE-bench. At 1/7th the cost during promo. The prompting skill -
DeepSeek as cheap second opinion alongside Claude
By
–
The key insight most people miss: DeepSeek replacing Claude entirely is the wrong move. DeepSeek as a $0.14 second opinion running alongside Claude is the right move. Same thinking system. Dramatically different API bill.