tldr: RLHF taught models to be likable. RLVR is teaching them to be useful.
MACHINE LEARNING
-
Apple may update Siri as Claude Code handles assistant tasks already
By
–
Apple may be planning to role out its updated Siri based on 2024's vision at the moment when Claude Code and Codex (also OpenClaw) can increasingly do the actual assistant thing: read my emails & calendar, proactively spot & solve problems, do delegated tasks, work with voice etc
-
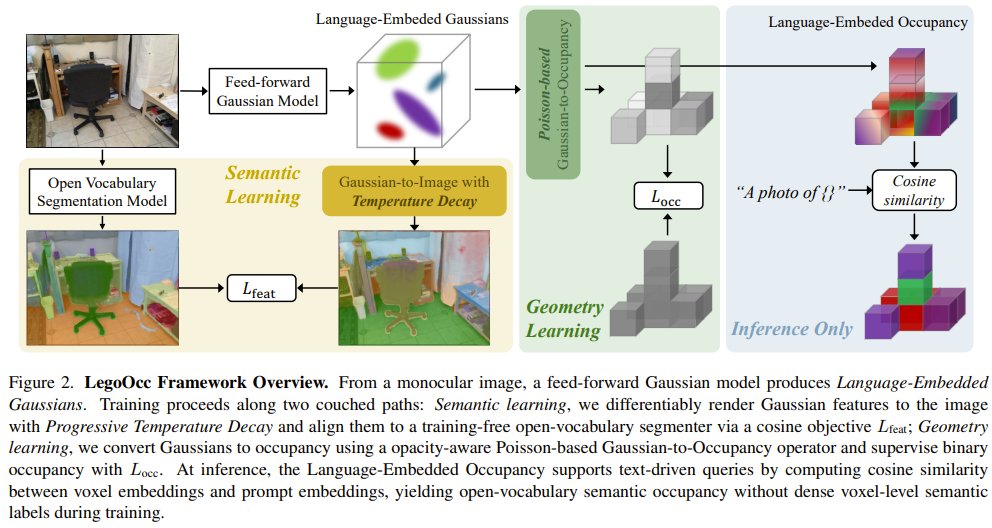
New Research Enables Open-Vocabulary 3D Occupancy for Home Robots
By
–
Why can’t your home robot identify a “plush toy” it’s never seen before? Researchers from HKUST Guangzhou & CUHK Shenzhen crack open-vocabulary 3D occupancy for indoor scenes. Their method uses only binary occupancy labels (occupied vs. free) to train language-embedded 3D
-
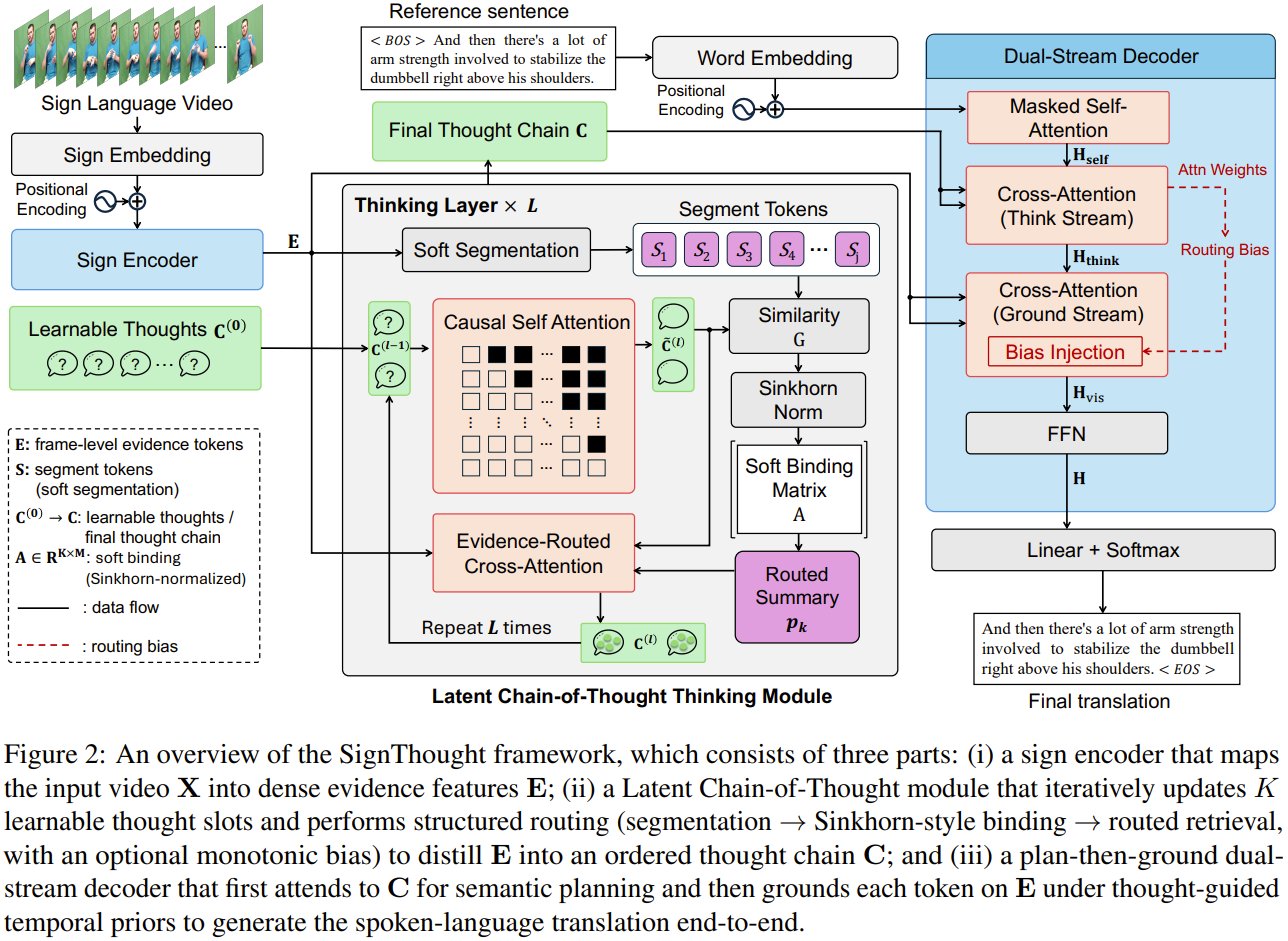
SignThought: A New AI Approach to Sign Language Translation
By
–
What if sign language translation didn’t just match signs to words, but actually thought through meaning first? Researchers from Hong Kong Polytechnic University and Sichuan University introduce SignThought. They replace the old word-by-word mapping with an explicit layer of
-
A 20-year-old earns $37,250 with an AI content factory
By
–
Un jeune de 20 ans a généré 37 250 $ en un seul mois grâce à du contenu YouTube… sans presque jamais ouvrir un logiciel de montage.
— Jouhatsu | AI Influence Operator (@Jouhatsu_ai) 10 mai 2026
Il a construit une véritable “content factory” autonome où Claude agit comme le cerveau et Premiere Pro comme le corps.
Pendant qu’il dort, sort… https://t.co/NRJJAfFlcS pic.twitter.com/stmnqZEnudA 20-year-old generated $37,250 in a single month through YouTube content… without almost ever opening editing software. He built a true autonomous “content factory” where Claude acts as the brain and Premiere Pro as the body. While he sleeps, goes out
-
Speculative decoding speeds up LLMs by 6x
By
–
The slowest part of running an LLM just got 6x faster without losing a single token.
— AlphaSignal AI (@AlphaSignalAI) 10 mai 2026
LLMs generate text one token at a time.
That sequential bottleneck wastes GPU power and slows everything down.
Speculative decoding fixes part of this.
A small draft model guesses ahead,… pic.twitter.com/y7YlqTWvrjThe slowest part of running an LLM just got 6x faster without losing a single token. LLMs generate text one token at a time. This sequential bottleneck wastes GPU power and slows everything down. Speculative decoding addresses part of this issue. A small draft model predicts ahead.
-
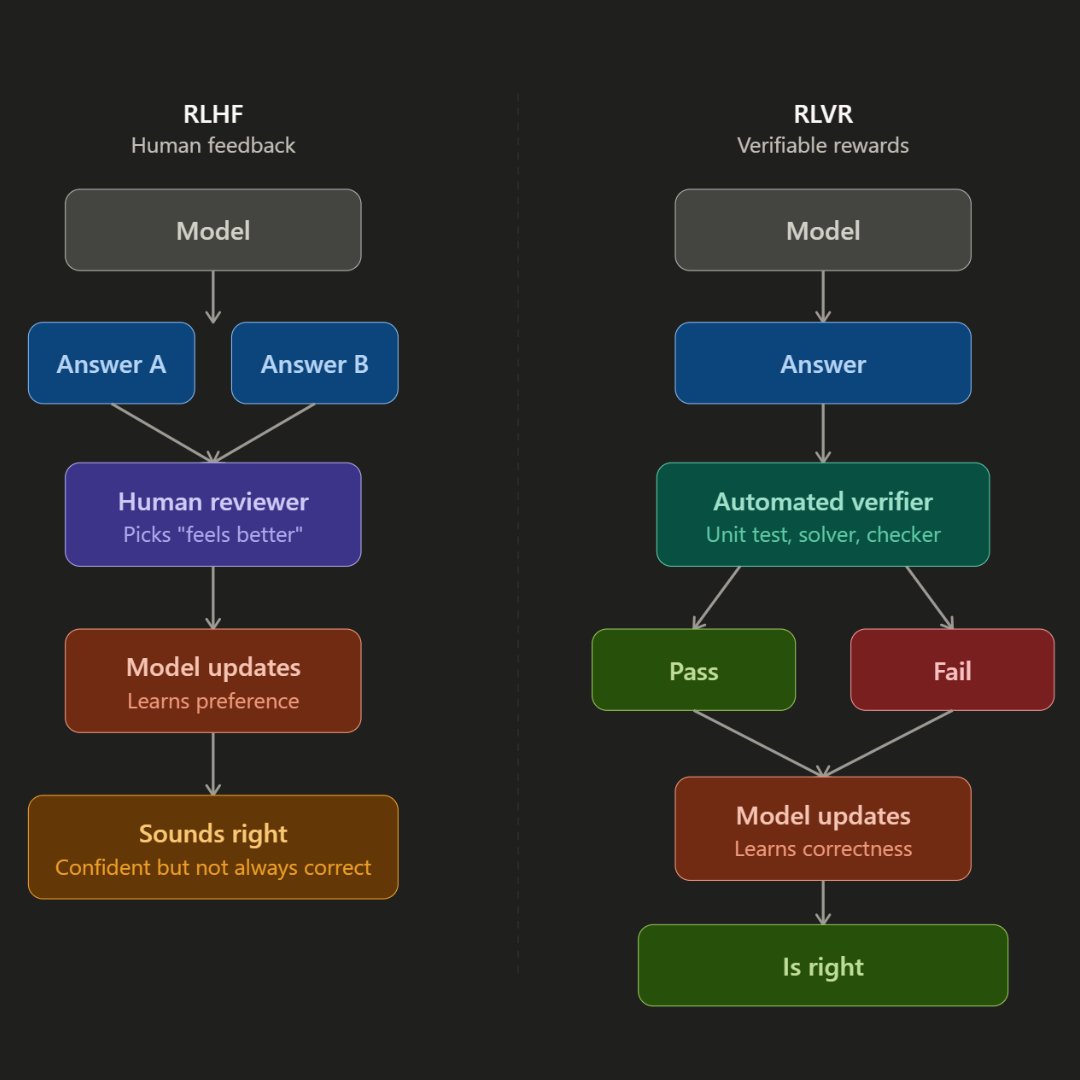
AI Progress: From Basic Code to Engineering Tests
By
–
A year ago, AI could write basic functions. Now it solves multi-step coding challenges and passes actual engineering tests. Of course, bigger models helped. But the bigger shift is in how models learn what a "good answer" means. We used to train AI using Reinforcement Learning
-
Analyzing token consumption and efficiency for HTML in LLMs
By
–
The most frequent objection in the comment section is this line: "HTML eats up so many tokens— is Anthropic indirectly fleecing us?" I've flipped this thought over in my mind, and maybe we can look at it this way. First, HTML does eat tokens—that's a fact—but if Anthropic
-
ZeRO-Infinity: Breaking the GPU Memory Wall for Deep Learning
By
–
ZeRO-Infinity: Breaking the GPU Memory Wall
for Extreme Scale Deep Learning! MichiGAN Hyperscale GPU Data Complete Nvidia cluster installation! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS -
Technical Normalization Techniques in Keras for Machine Learning
By
–
Different Normalizations with #Keras. #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode https://
geni.us/Diff-Normaliza
tions
…