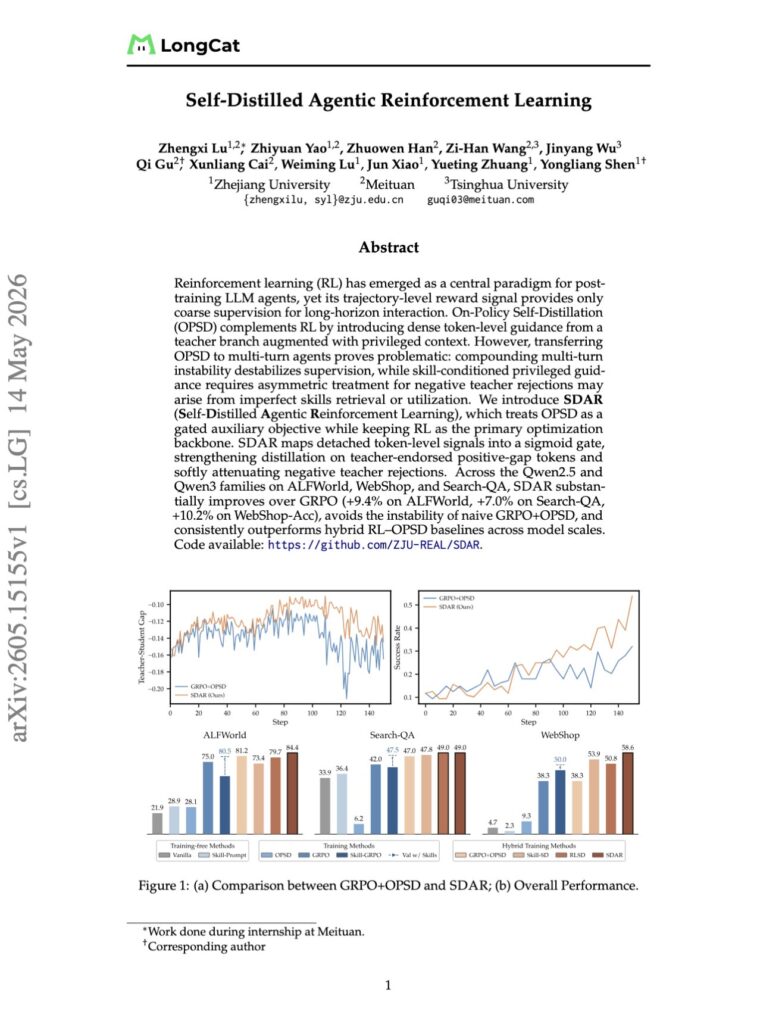
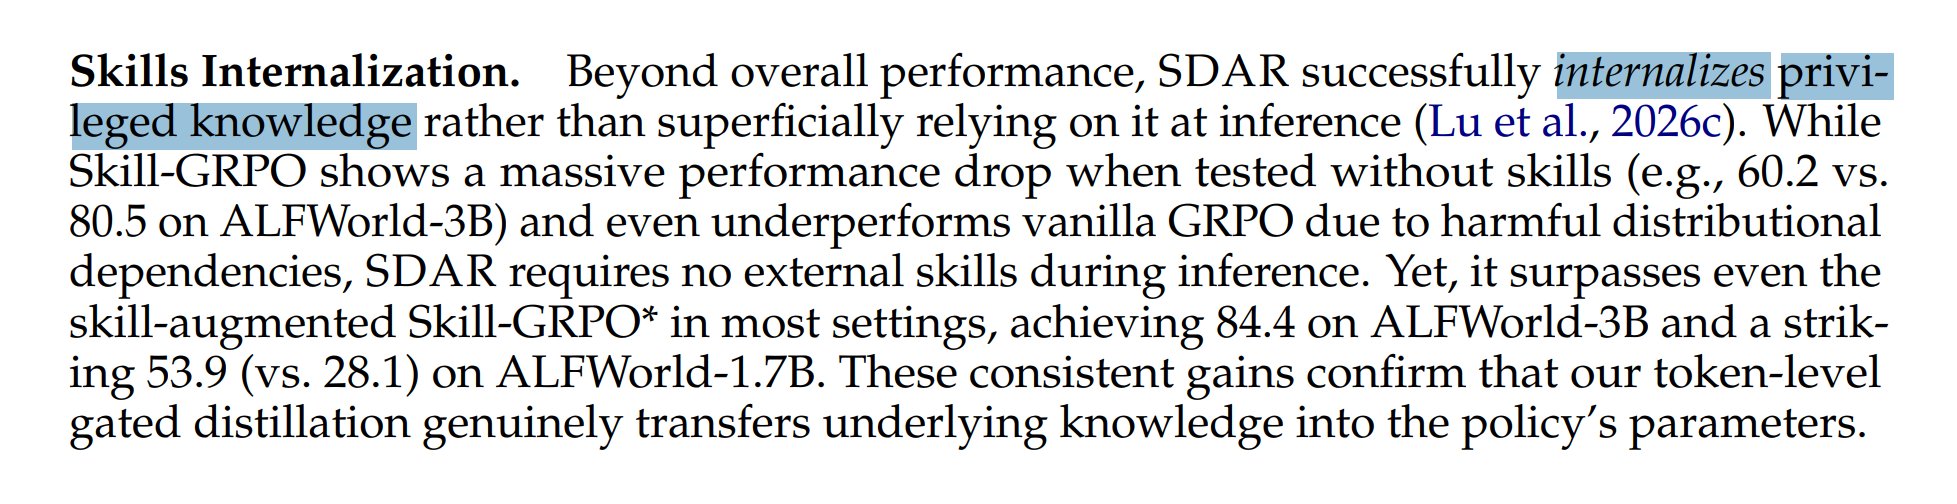
That's so cool! The same team at @Meituan_LongCat wrote Skill0, where they propose an RL recipe for skill internalization.
By
–
That's so cool! The same team at @Meituan_LongCat wrote Skill0, where they propose an RL recipe for skill internalization.
By
–
Just wait for the autonomous drones to be able to use embedded Mythos-level models.

By
–
Energy Becomes a Strategic Variable in #AI Workload Management
by @antgrasso #ArtificialIntelligence #MachineLearning #ML #DL
By
–
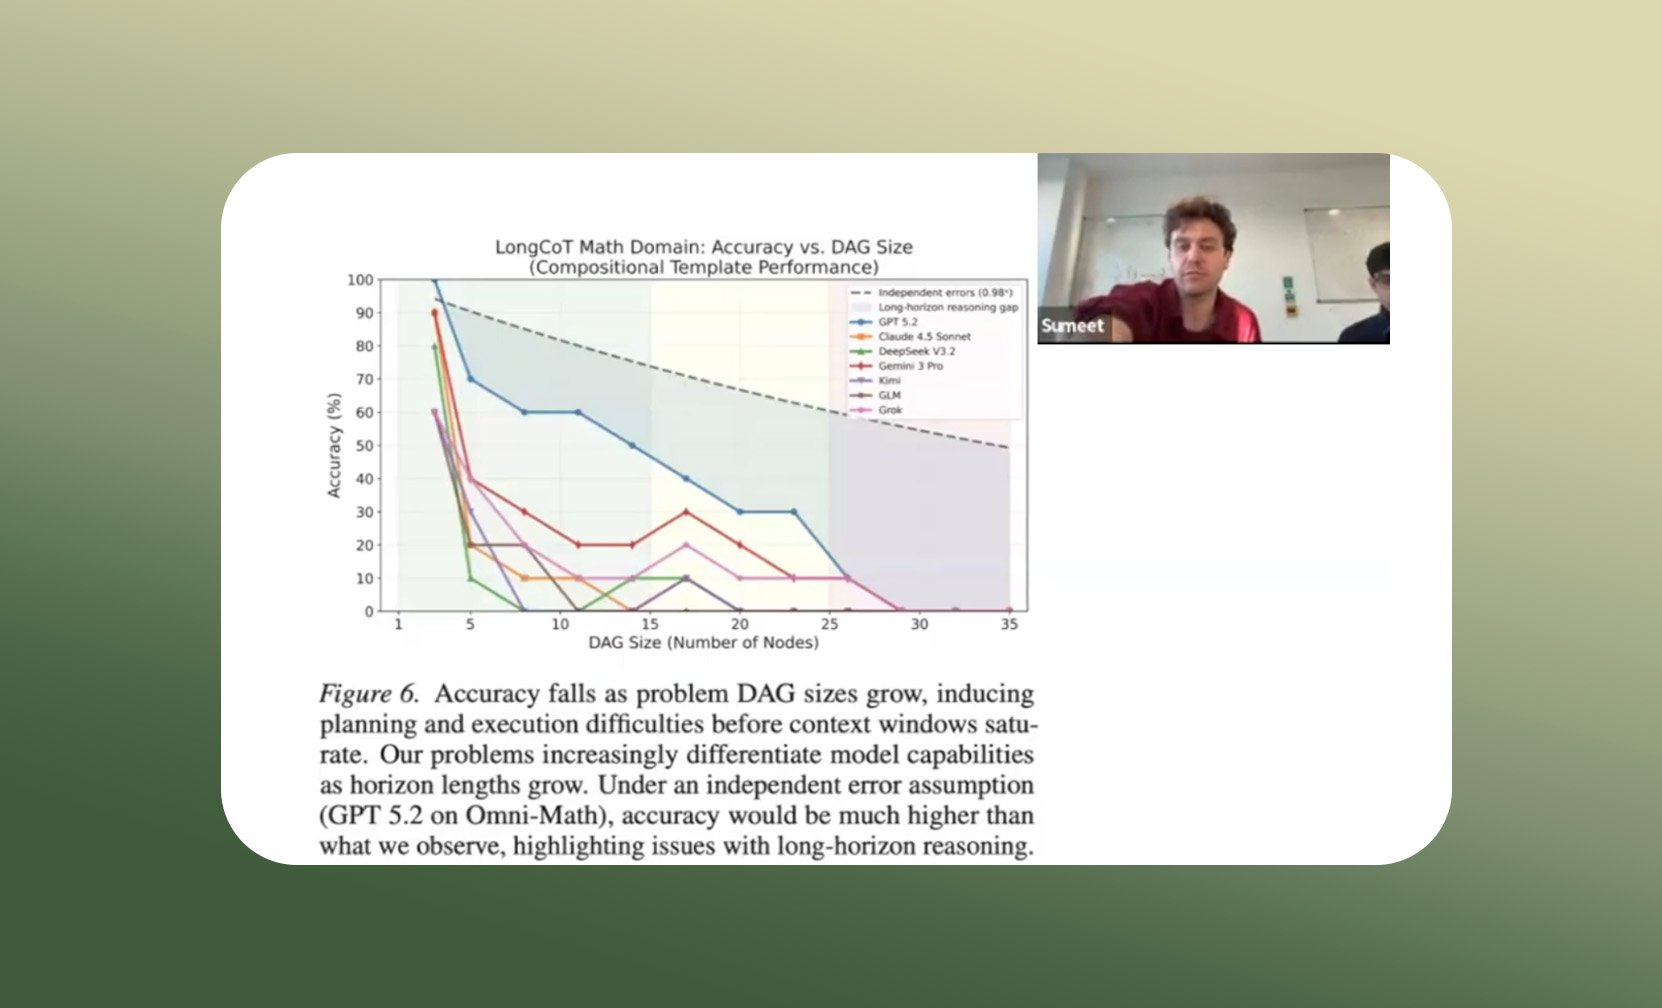
Long-horizon reasoning is one of the largest obstacles in LLMs. In our latest AI4Science talk, Sumeet (
@sumeetrm
) and Charlie (
@CharlieLondon02
) from Oxford discussed H1 and LongCoT, two projects focused on measuring and improving how models reason over long chains of steps.
By
–
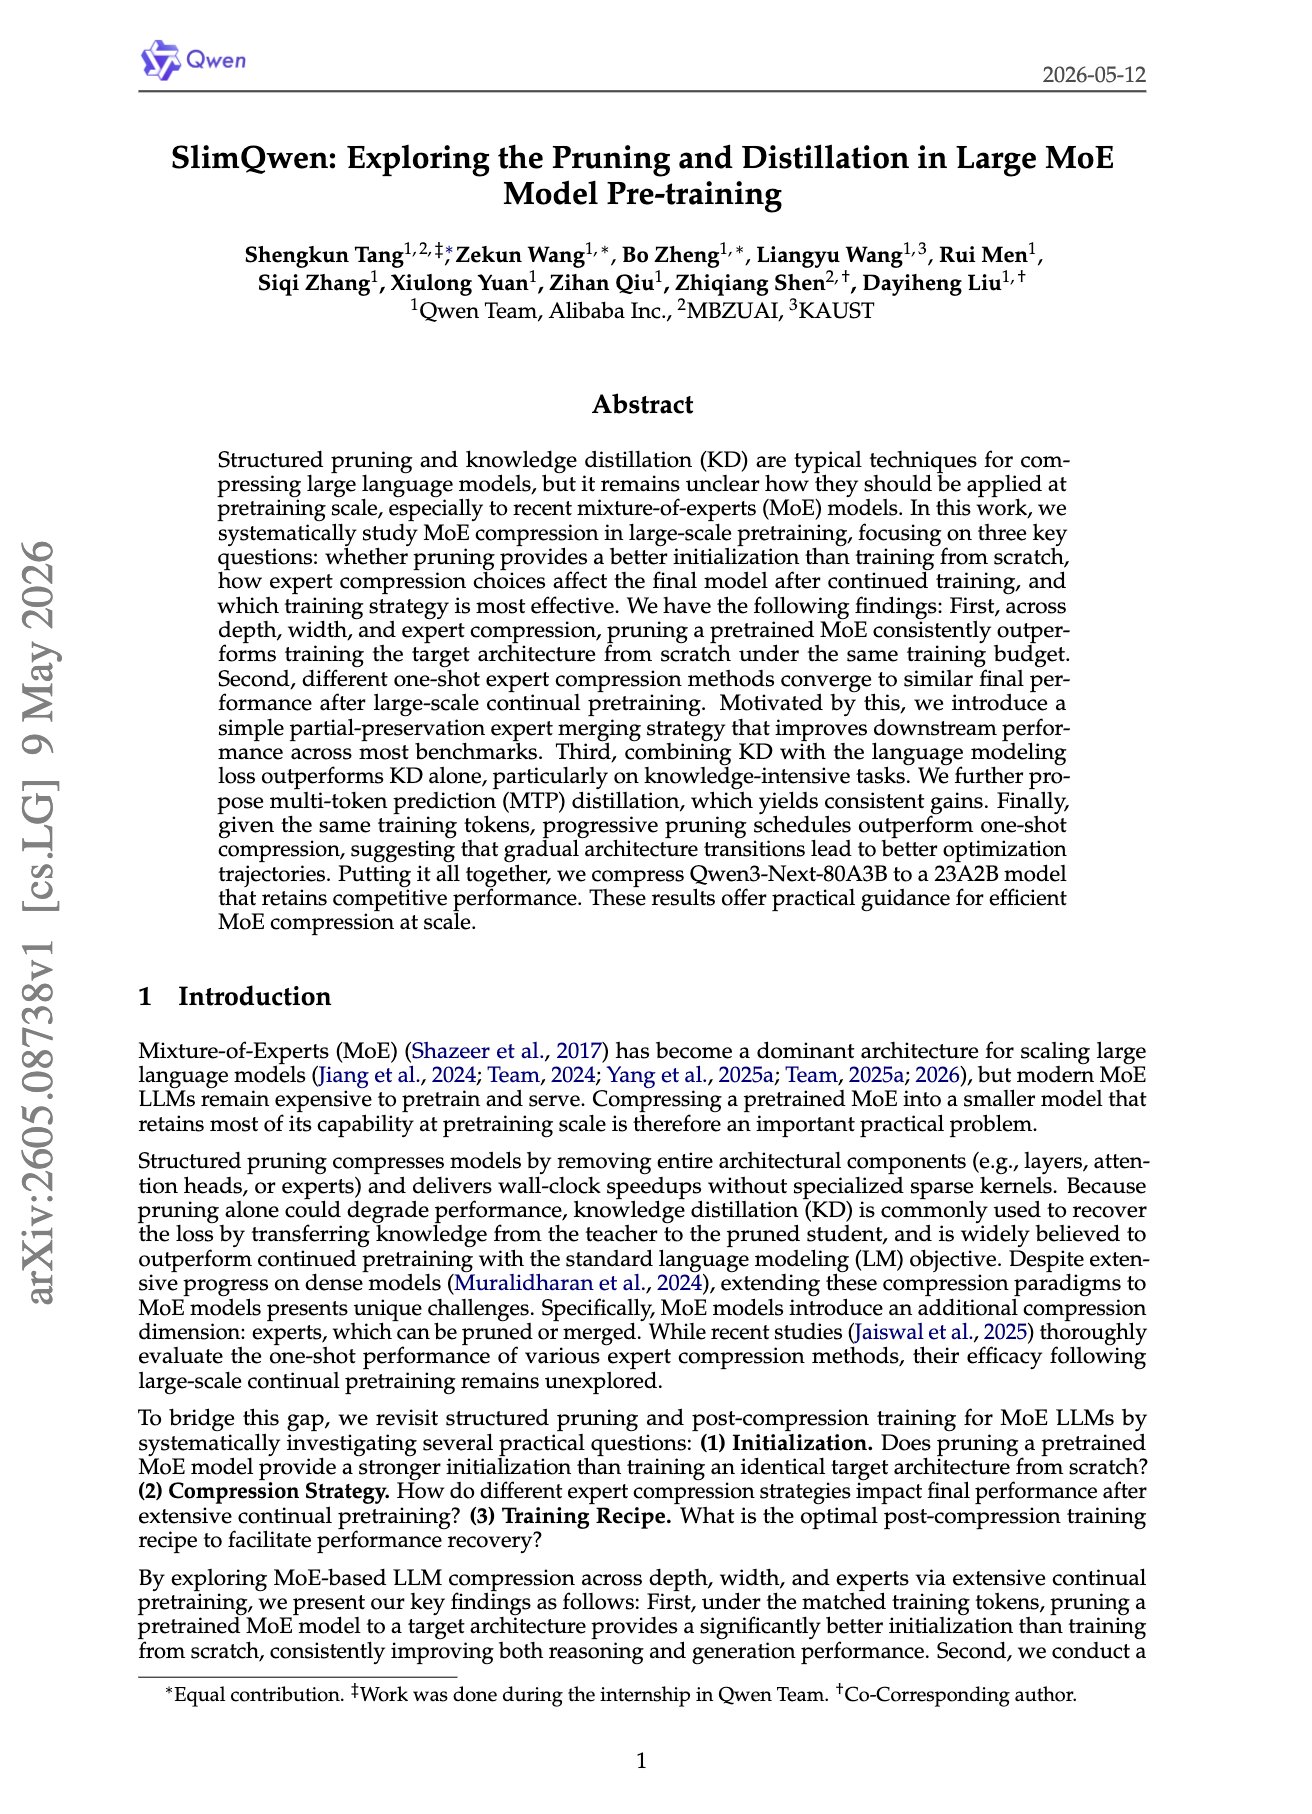
“SlimQwen: Exploring the Pruning and Distillation in Large MoE Model Pre-training” This new Qwen paper shows that pruning a pretrained MoE is much better than training the smaller MoE from scratch. All you need to do is prune depth, width, and experts, preserve some experts
By
–
Actions persist in history and can affect the world. However, we shouldn’t train on our own actions. Training on our own actions as if they were evidence is what can cause delusions.
By
–
You don’t remove any information. You just use the right model. The action distribution is a delta function for your own actions. You still train on how the world is affected by or reacts to your actions

By
–
“Inside Deep Learning — Math, Algorithms, and Models” available at http://
amzn.to/3wDJEmc
—————
#DataScience #AI #MachineLearning #ML #NeuralNetworks #Mathematics #DataScientist #Python

By
–
Develop and Debug high-performance, low-bias, and explainable Machine Learning and Deep Learning Models with Python : http://
amzn.to/3u2JiIB by @AliMLearning via @PacktDataML —————
#DataScientist #DataScience #AI #ML
By
–
The Hundred-Page Language Models Book — Hands-on with PyTorch: http://
amzn.to/4sJl7YC by @burkov