
Your LLM can reason better without any fine-tuning! optillm is an OpenAI API-compatible proxy that implements 20+ optimization techniques to improve LLM accuracy on reasoning tasks without training or fine-tuning. The concept: Instead of one API call, optillm makes multiple
MACHINE LEARNING
-

AutoML’s Role in Democratizing Model Development and Governance
By
–
AutoML is democratizing model development across business teams, shifting responsibility toward data quality and governance. Pressure grows on organizations to align tools, skills, and decisions so outputs remain reliable in daily operations. Microblog by @antgrasso #AI
-
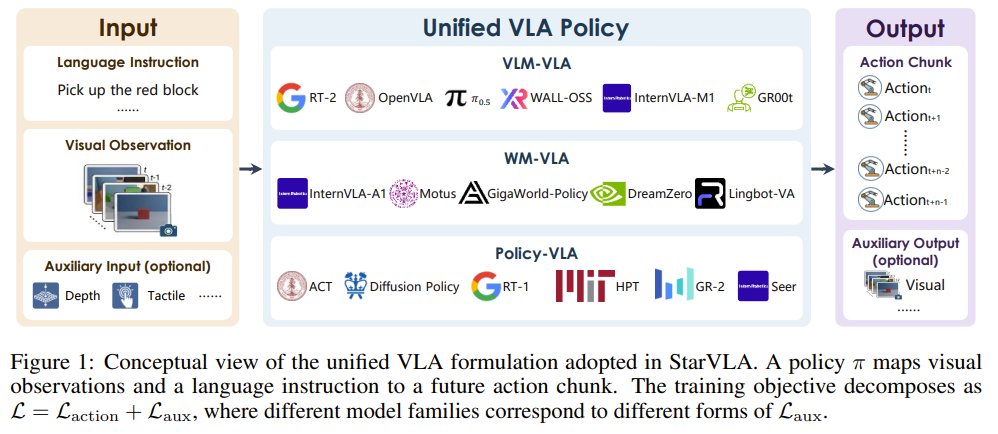
StarVLA: Modular Vision-Language Robot Codebase
By
–
What if building a robot that sees, understands, and acts was as easy as snapping Lego together? Enter StarVLA: a modular codebase that lets you swap vision-language or world-model backbones and action heads independently. It matches or surpasses prior methods on benchmarks
-

Causal vs Observational Agency in Agents
By
–

Causal vs observational agency. Agent actions (a) should be treated as interventions, not as evidence for hypotheses (p). Actions by other agents or tool outputs are evidence (o).
-
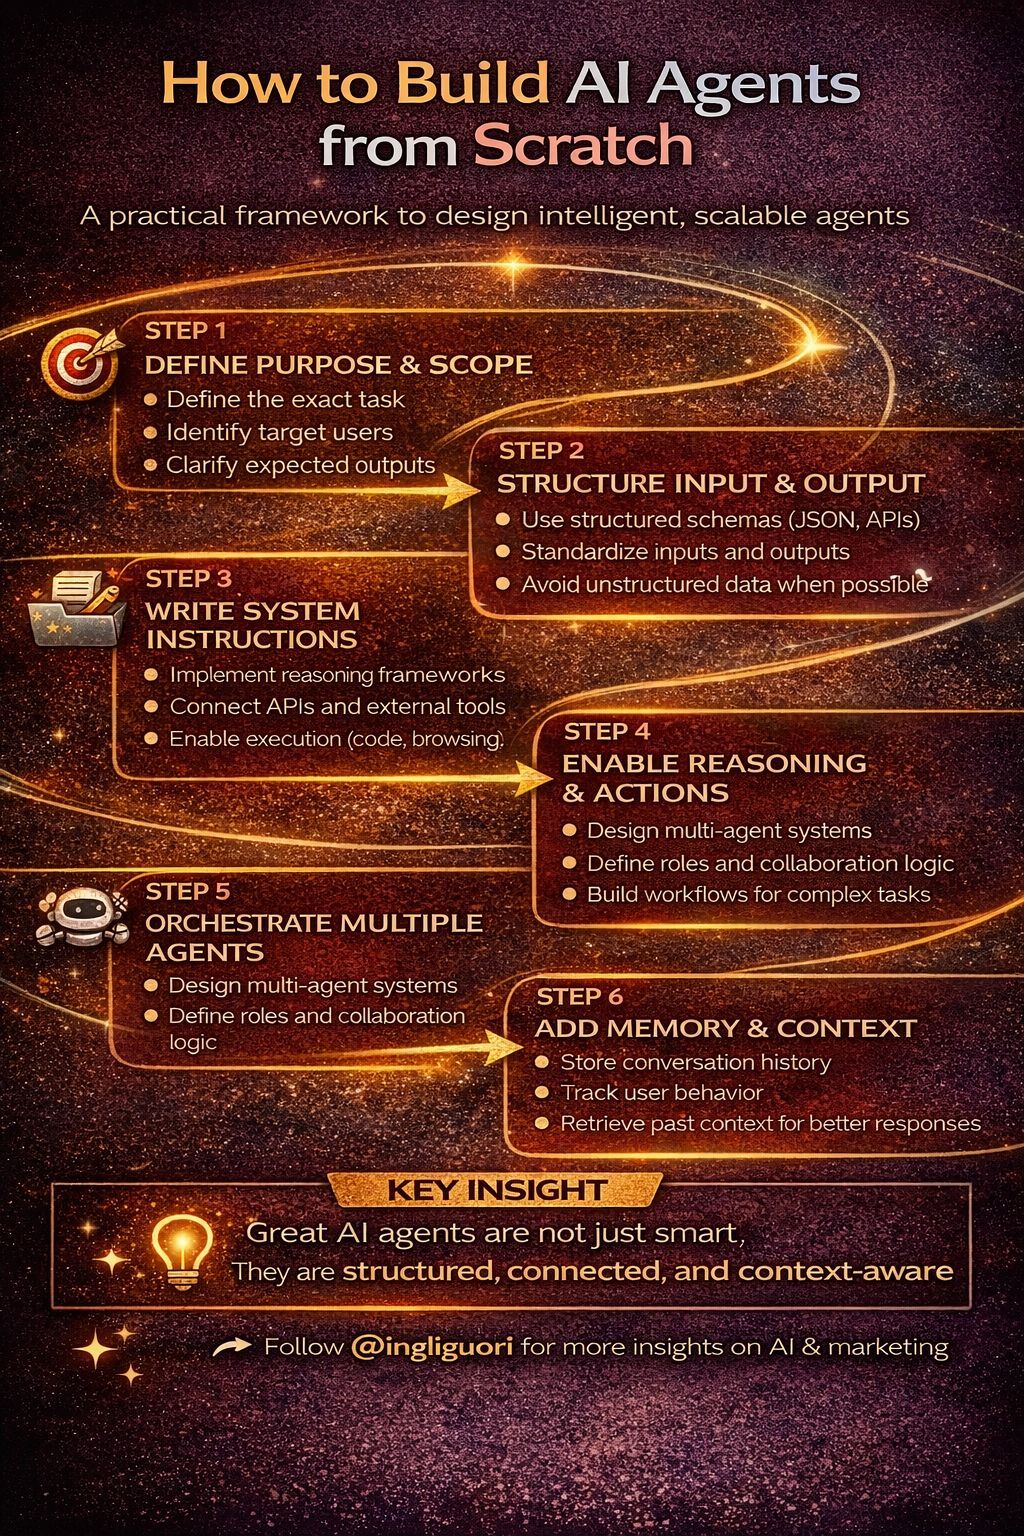
Checklist: How to Build AI Agents
By
–
How to build AI Agents • Define scope
• Structure I/O
• Add tools
• Enable reasoning
• Orchestrate agents
• Add memory Smart ≠ enough
Structure + context = performance Via Giuliano Liguori (
@ingliguori
) #AI #AIAgents #BuildInPublic -
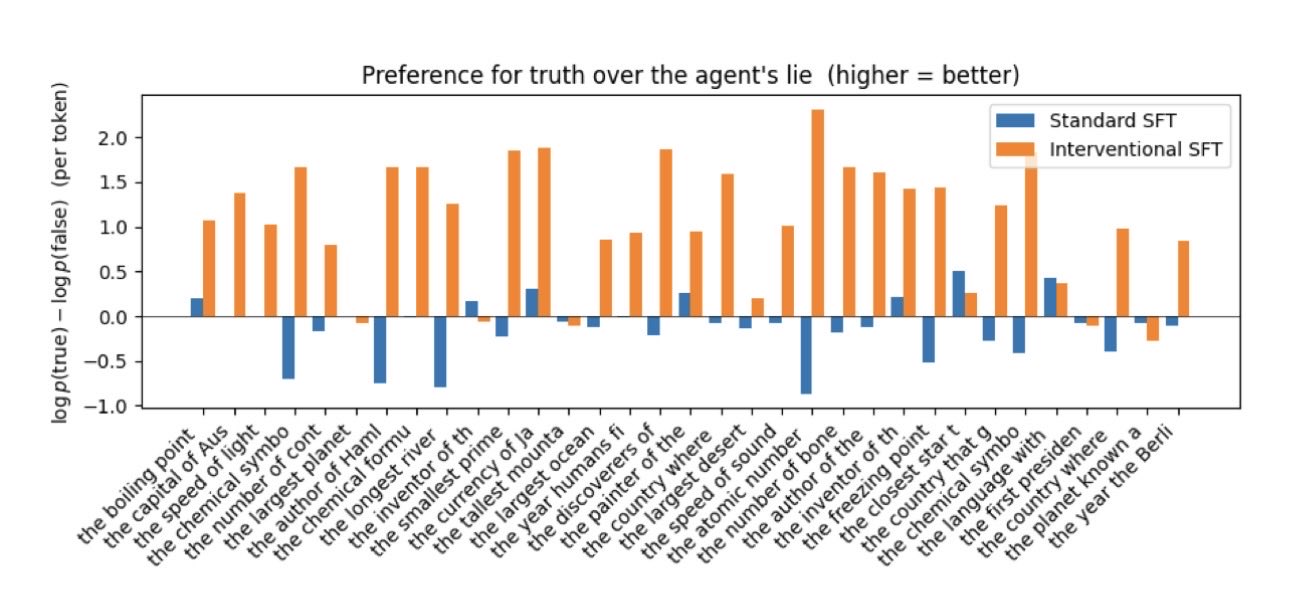
One-line fix to prevent LLM agent delusions
By
–
One line of code is all it takes to prevent LLM agent delusions, instead of post-training patches like RL. https://
love4all.ai/blog/why-it-is
-important-to-understand-causality-and-agency/
… 4 ∀ https://
github.com/nandodef/love4
all-ai/tree/main/docs/files
… -
Analysis of LLM failure modes in reasoning and token prediction
By
–
The strawberry test. The "how many R's" test. The car wash riddle. Same failure mode every time. AI predicts the most probable answer, not the correct one. When probability matches reality, it looks like intelligence. When it doesn't, it looks like confidence without
-
Understanding LLM Hallucinations and Pattern Matching
By
–
This is what a hallucination actually looks like in practice. Not random nonsense. A confident, structured answer that happens to be wrong. The model pattern-matched to the most likely answer instead of the literal one. That's exactly what it does with your prompts too.
-

SpaceXAI: Grok next version trained on 1.5T V9 model, upgrade coming summer
By
–

SPACEXAI : The next version of Grok, based on the 1.5T V9 base model has finished training. Looks like we will get a major upgrade this summer. > Next, we are adding the Cursor data in supplemental training. Soon
-
Why is there no ChatGPT or Claude voice app on Apple Watch?
By
–
To this day I still don't understand why there is no ChatGPT or Claude or any other voice app on the Apple Watch, even though it looks like the perfect form factor.