Improving Deep Reinforcement Learning via Quality Diversity, Open-Ended and AI-Generating Algorithms https://
bit.ly/3WjxeMq #AI #MachineLearning #DeepLearning #LLMs #DataScience
MACHINE LEARNING
-
Enhancing Deep Reinforcement Learning Through Quality Diversity and Open-Ended Algorithms
By
–
-
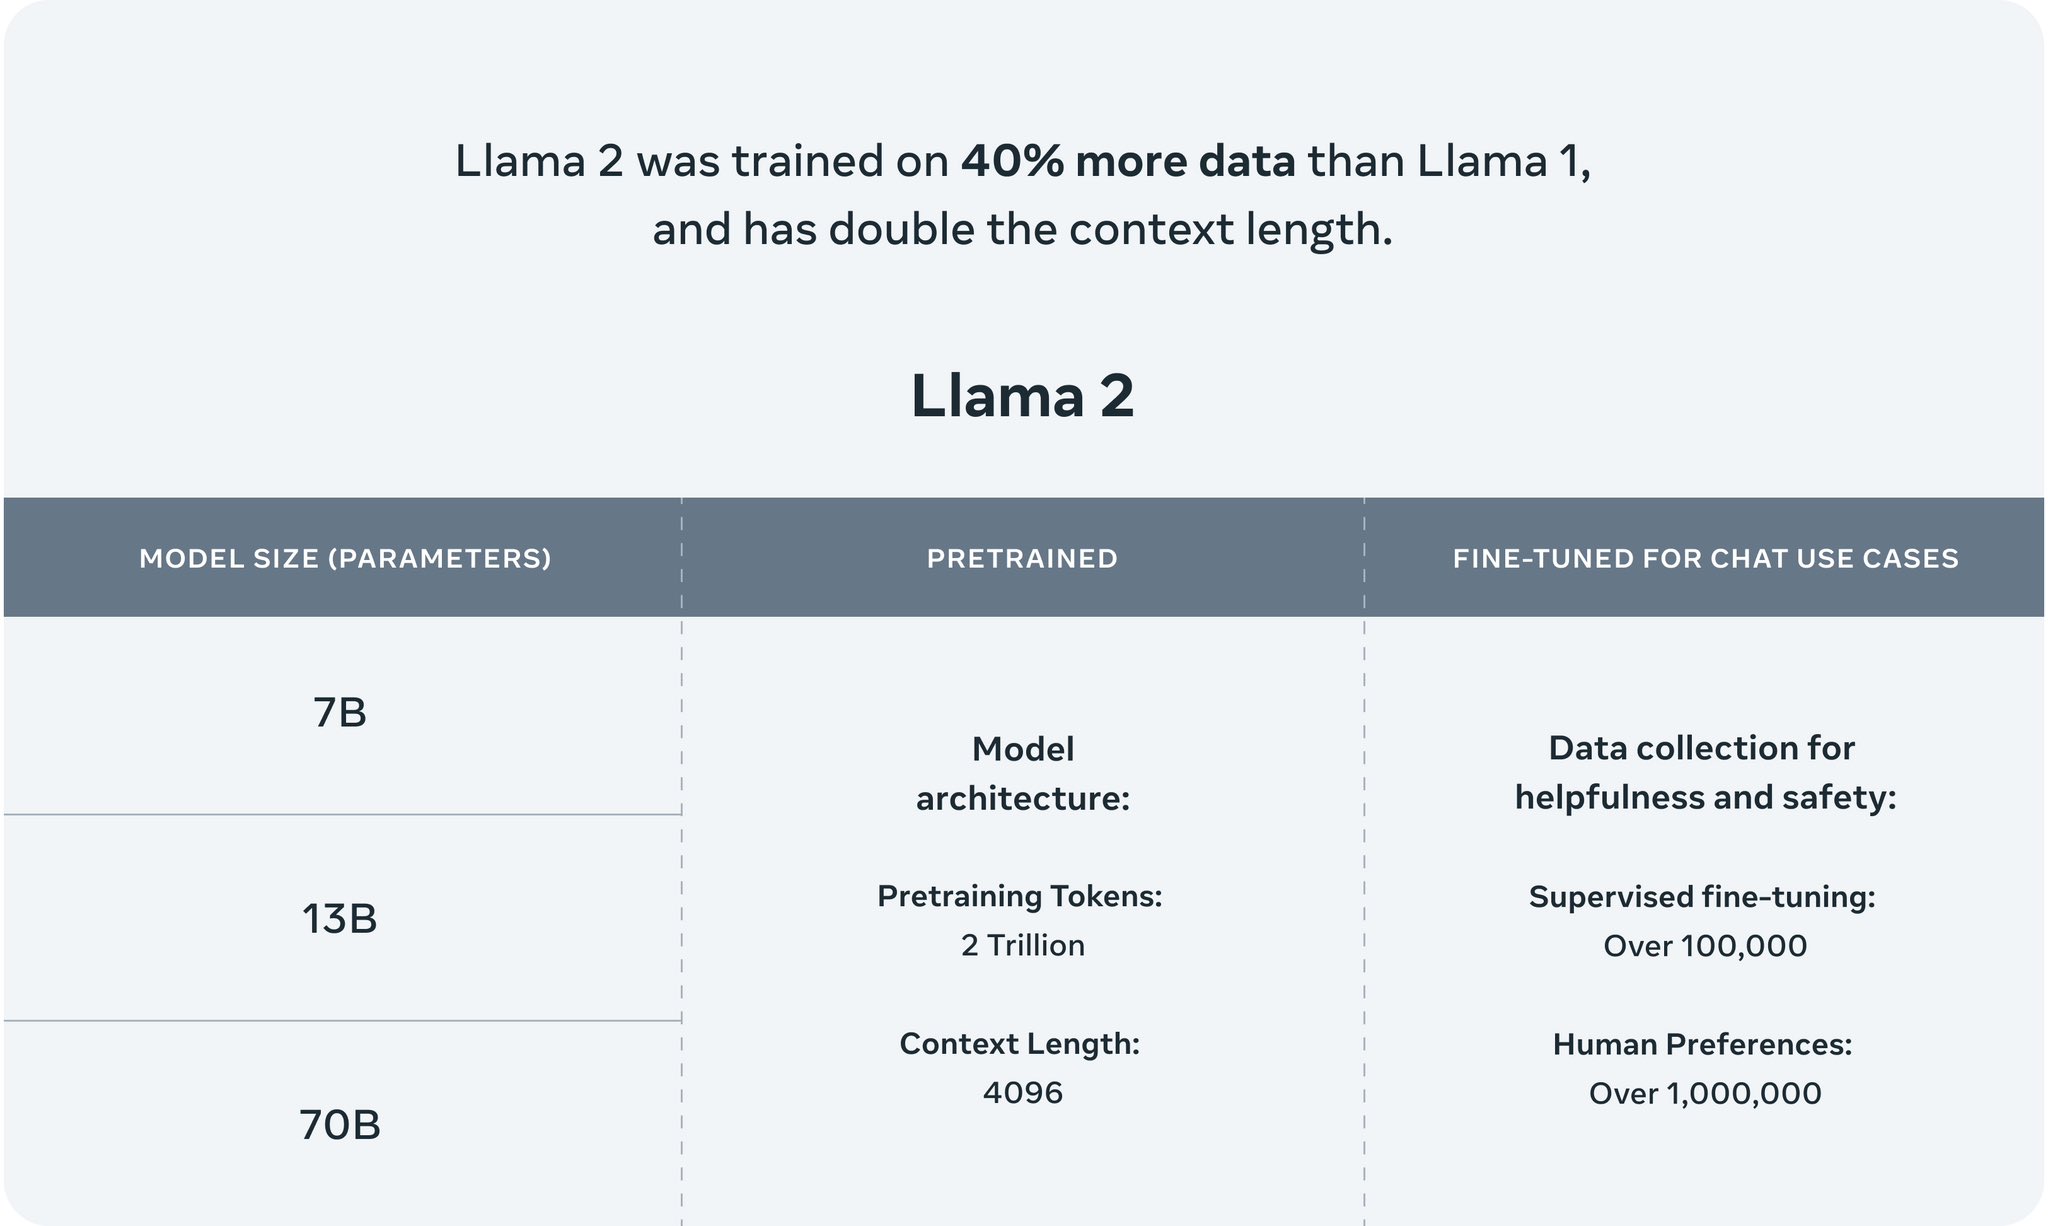
LLaMA-2 Release: Open Source AI Model with Commercial Rights
By
–
Wow, LLaMA-2 is out! Love that it is open source and is open for commercial applications. This version is also tuned with RLHF which suggest it will be good for conversational uses cases. LLaMA-2 was trained on 40% more data than LLaMA-1 and has double context length(4K now).
-
Google’s Machine Unlearning: Removing Data from AI Models
By
–
Super interesting work from Google on machine *un*learning. How do you remove data (& its influence) from a model at reasonable cost, without impacting the model's accuracy? It's a growing ask given LLMs' need to remove copyrighted data, private data, etc https://
ai.googleblog.com/2023/06/announ
cing-first-machine-unlearning.html?m=1
… -
SAS Certification Boosts Career Growth and Professional Recognition
By
–
SAS certification helps you gain recognition as the expert that you are. 64% of professionals received a promotion or salary increase after achieving certification (Pearson VUE). Learn why you should #GetSASCertified. http://
2.sas.com/6015Pzda1 -
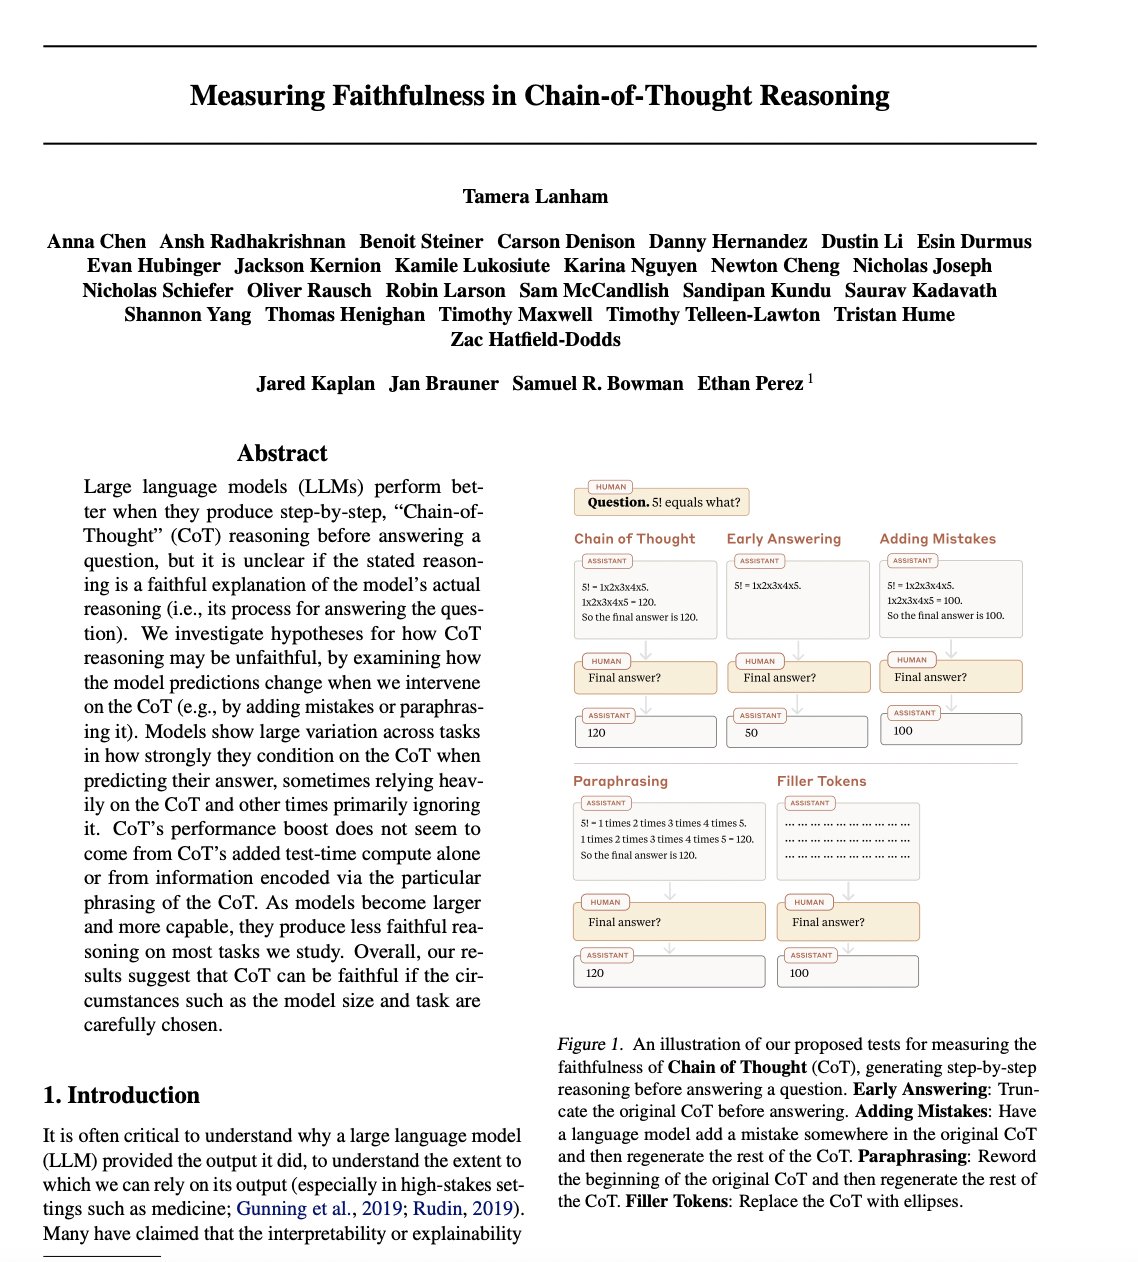
Measuring Faithfulness in Chain-of-Thought Reasoning
By
–
Measuring Faithfulness in Chain-of-Thought Reasoning paper: https://
www-files.anthropic.com/production/fil
es/measuring-faithfulness-in-chain-of-thought-reasoning.pdf
… Large language models (LLMs) perform better when they produce step-by-step, “Chain-ofThought” (CoT) reasoning before answering a question, but it is unclear if the stated reasoning is a faithful -

Meta releases LLaMa-2 open-weight language model free
By
–
LLaMa-2 from @MetaAI is here!
Open weights, free for research and commercial use. Pre-trained on 2T tokens.
Fine-tuned too (unlike v1). Lets gooo…. https://
ai.meta.com/llama/
The paper lists the amazing authors who worked to make this happen night and day. Be sure to thank -
Anthropic improves language model reasoning through faithful explanations
By
–
We’re excited about ways to make language models generate more faithful explanations that help them reason better! We encourage you to check out our papers for more results and details: https://
www-files.anthropic.com/production/fil
es/measuring-faithfulness-in-chain-of-thought-reasoning.pdf
… https://
www-files.anthropic.com/production/fil
es/question-decomposition-improves-the-faithfulness-of-model-generated-reasoning.pdf
… -
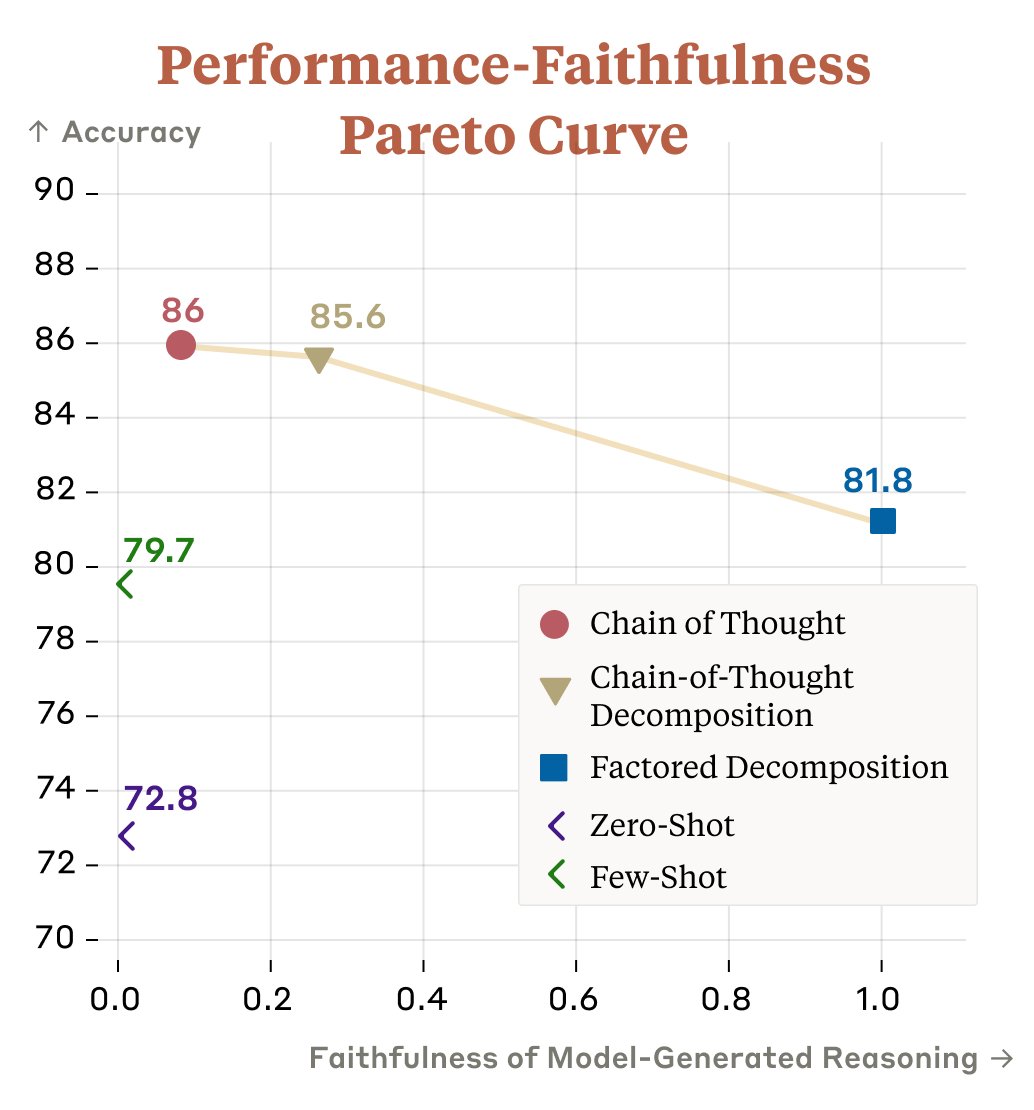
Decomposition Methods Improve Reasoning Faithfulness Trade-offs
By
–
We find different methods for generating reasoning make different tradeoffs between question-answering accuracy and reasoning faithfulness. Our decomposition-based methods push the performance-faithfulness Pareto frontier, making us optimistic for further improvements.
-
Improving Model Reasoning Through Question Decomposition Methods
By
–
To improve the faithfulness of model-generated reasoning, we study two other ways of eliciting reasoning from models in Radhakrishnan et al. These methods rely on question decomposition, or breaking down a question into smaller subquestions to help answer the original question.
-
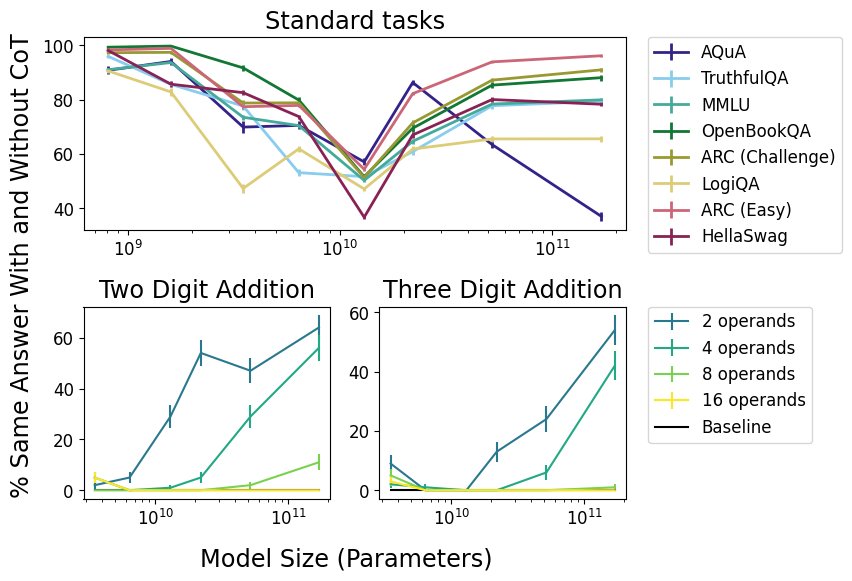
Reasoning Faithfulness Decreases as AI Models Scale
By
–
We find that reasoning faithfulness shows inverse scaling: as models increase in size and capability, the faithfulness of their reasoning decreases for most tasks studied. In cases where reasoning faithfulness is important, using smaller models may help.