AI companies have been testing and using synthetic data (at least) since we a) realised that labels are expensive in supervised deep learning and b) started seriously looking at AI on sensitive data.
MACHINE LEARNING
-
Word and Sentence Embeddings: Building Blocks of Language Models
By
–
Did you know that word and sentence embeddings are the building blocks of most large language models? Learn more about how they work and how they're used to understand human language in this exciting piece by luis_likes_math
-
AI Unlocks Animal Communication Mysteries With ML Models
By
–
Ever wondered if we could talk to animals like Dr. Dolittle? AI is unlocking the mysteries of animal communication and our understanding of the animal kingdom with the help of ML and voice-recognition models. Tap to read more: https://
rb.gy/jrekh -
Reflecting on the validity of transfer learning approaches
By
–
Je trouvais ca super cool comme approche , ca avait l'air d'être un transfer learning intelligent… Mais bon… quand c'est trop beau c'est surement que c'est pipeauté.
-
Identifying code errors in machine learning research benchmarks
By
–
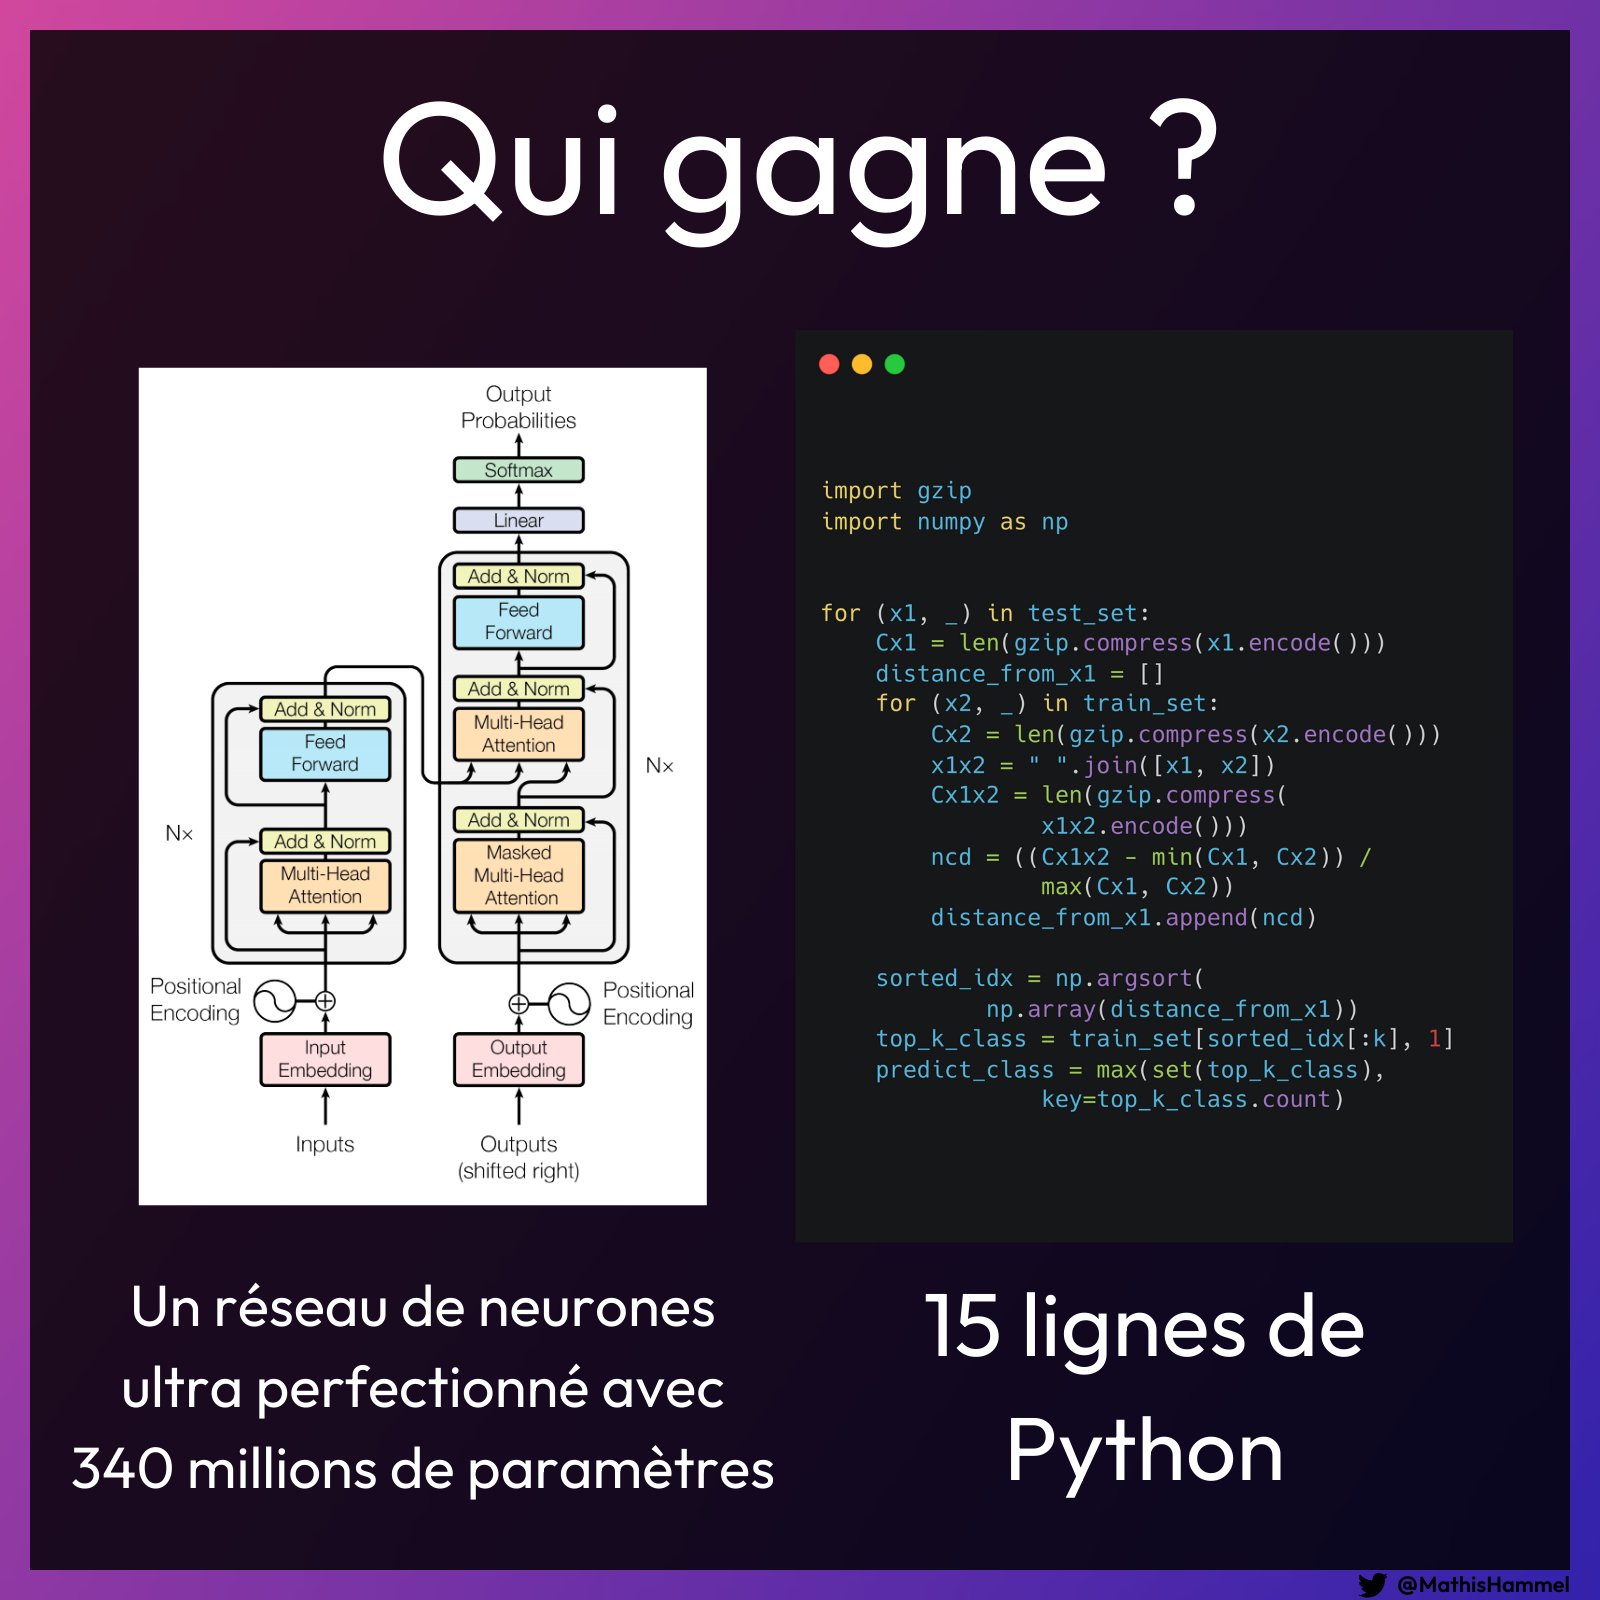
Looks like the gzip paper I was enthusiastic about over-estimated its scores because of a bug in the code: it did top-2 knn instead of k=2. We should remember this as (yet another) a strong case for testing in ml code. I still like that it put a new idea in my toolbox. t.co/MyJA2BEExs
-

Critique of Gzip OOD Evaluation and Data Leakage in ML
By
–
I looked a little into the Gzip OOD results and there seems to be another big problem: train-test overlap. E.g. DengueFilipino has the same train and test set. KirundiNews has 90% overlap… Still nice to see people revisit old ideas and the use of information theory for ML 🙂 x.com/giffmana/statu…
-
Critical Analysis of ML Research Evaluation Methodology
By
–
Fun Fact : ce papier semble avoir commis des erreurs assez grave en termes d’évaluation et n’est pas aussi bon qu’attendu. Il est même pire. Donc non ça ne révolutionnera pas le monde du ML si ce n’est pour rappeler des bases de ML… Les chercheurs ont pris un top2 accuracy à
-
The challenge of building national datasets for AI training
By
–
Avec quelles bdd ? L’anglais c’est la langue d’internet donc c’est obvious de trouver des quantités astronomiques de données. Les seuls autres pays qui ont construit des bdd nationales qui serait de taille ok c’est la Russie et la Chine. En Europe on découvre à peine.
-
Synthetic Data: AI’s Solution to High-Quality Data Scarcity
By
–
High-quality data is a major limiting resource in advancing AI – it’s expensive, hard to obtain & increasingly being locked down. So what do AI companies do? My
@FT
piece on the trend of creating “synthetic data” to push forward AI development. -
NU-MCC: Multiview Compressive Coding for 3D Reconstruction
By
–
NU-MCC: Multiview Compressive Coding with Neighborhood Decoder and Repulsive UDF
— AK (@_akhaliq) 19 juillet 2023
paper page: https://t.co/fy7pygMD5w
Remarkable progress has been made in 3D reconstruction from single-view RGB-D inputs. MCC is the current state-of-the-art method in this field, which achieves… pic.twitter.com/XFYUp3ddxPNU-MCC: Multiview Compressive Coding with Neighborhood Decoder and Repulsive UDF paper page: https://
huggingface.co/papers/2307.09
112
… Remarkable progress has been made in 3D reconstruction from single-view RGB-D inputs. MCC is the current state-of-the-art method in this field, which achieves