Agree that it is problem-dependent. But once we fix a problem, we should tune all the models sufficiently to ensure a fair comparison. Right now PDEbench and PDEarena give contradicting results on same PDEs
MACHINE LEARNING
-
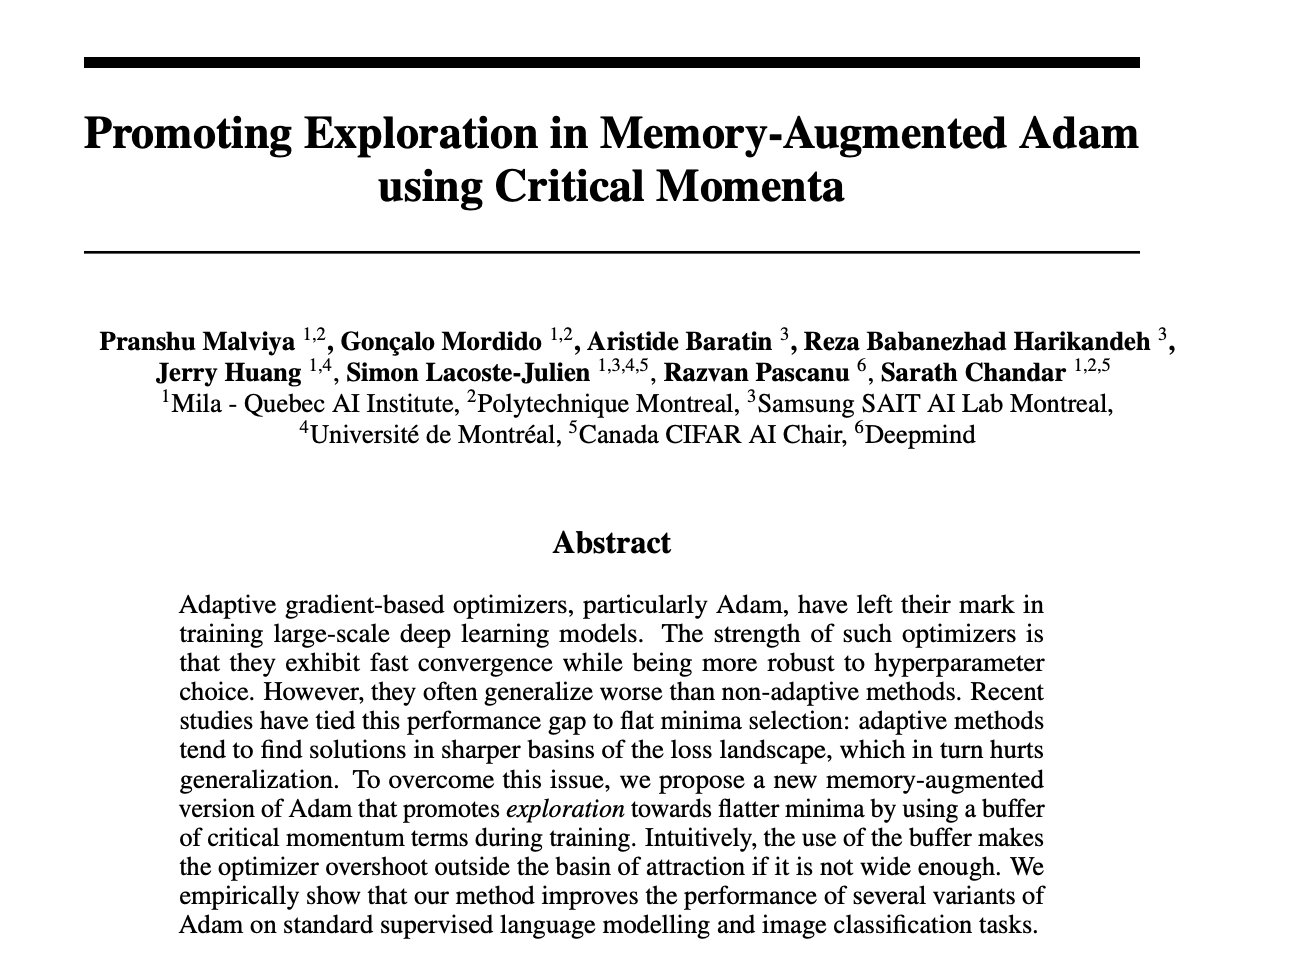
Memory-Augmented Adam Optimizer with Critical Momenta for Exploration
By
–
Promoting Exploration in Memory-Augmented Adam using Critical Momenta paper page: https://
huggingface.co/papers/2307.09
638
… Adaptive gradient-based optimizers, particularly Adam, have left their mark in training large-scale deep learning models. The strength of such optimizers is that they -
Apple GPT with personal data will win consumer AI
By
–
Apple GPT coming to your iPhone next year. Imagine a language model that has access to years worth of your iMessage exchanges, emails, photos, and health data. This is why Apple, while late to the game, will win consumer AI.
-
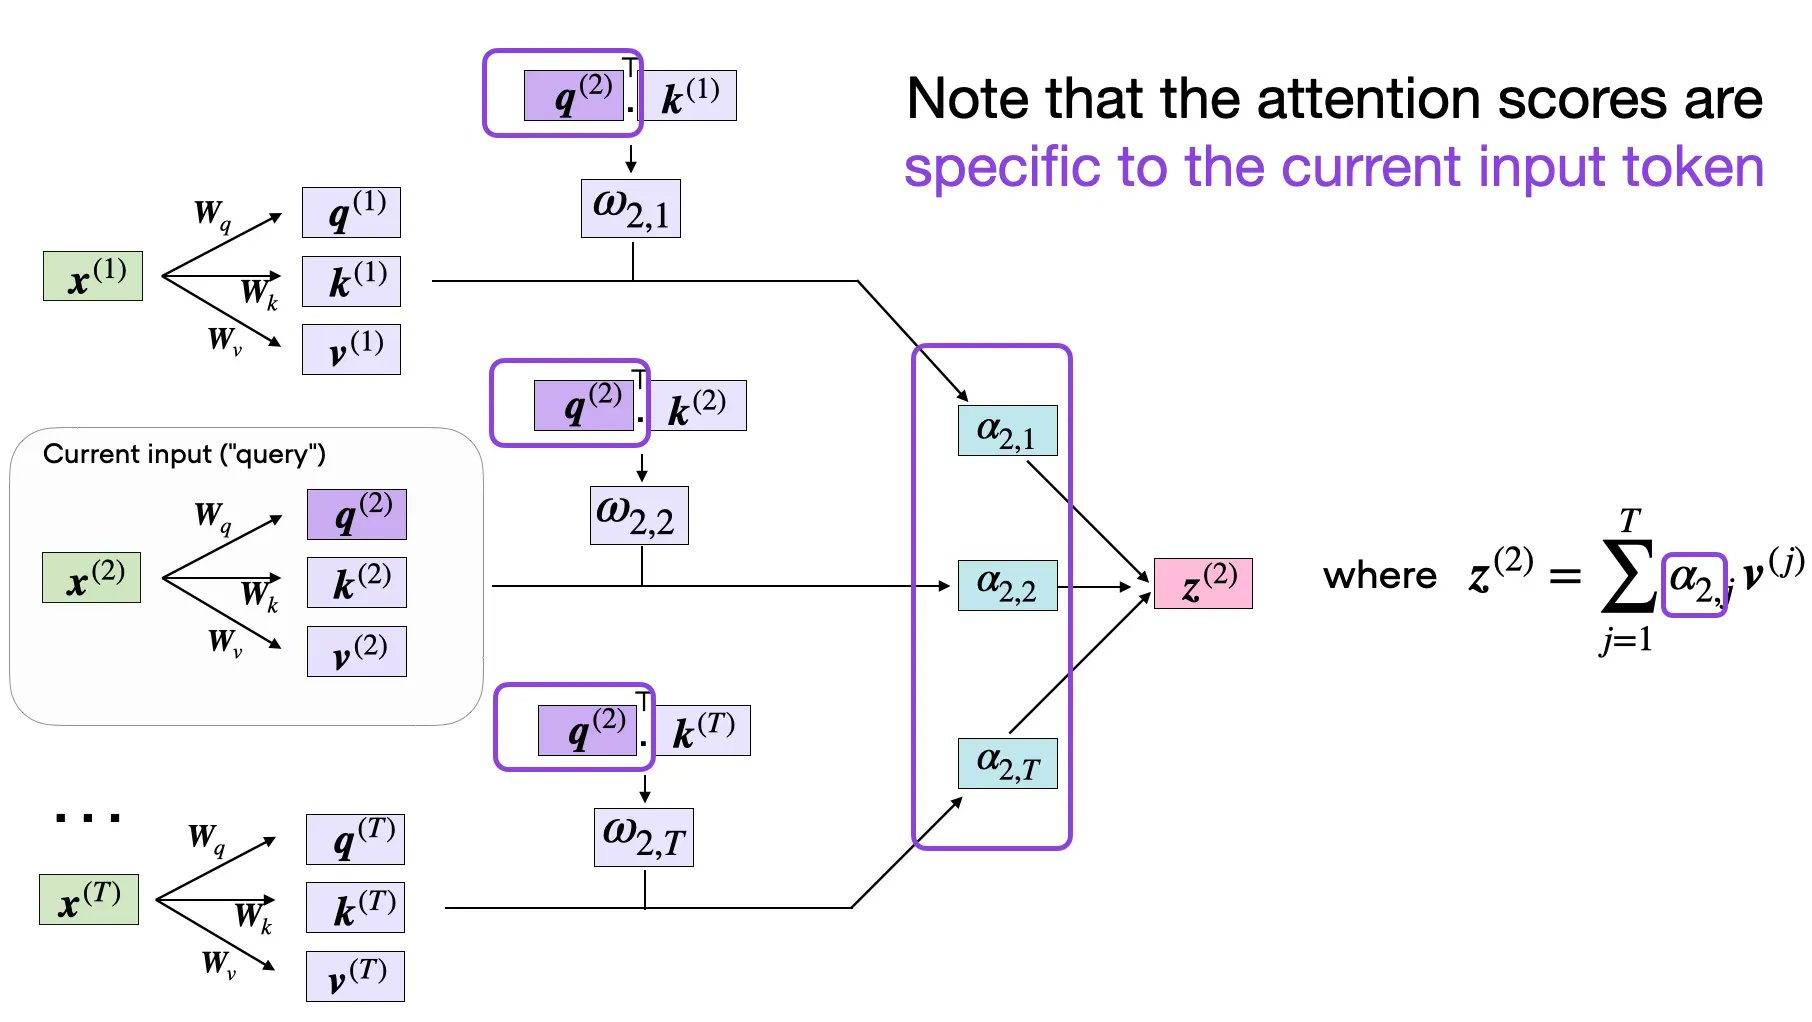
Self-Attention Mechanism in Large Language Models Coding Guide
By
–
Understanding and Coding the Self-Attention Mechanism of Large Language Models From Scratch https://
bit.ly/3YL821l #AI #DeepLearning #MachineLearning #DataScience -
FNO Model Selection Issues on PDEarena Platform
By
–
Good to meet and discuss how to bring all this knowledge together. Similarly, we have already noted that FNO models on your PDEarena are not correctly selected. Look for a PR coming your way.
-
PDEbench and PDEarena Show Conflicting Results Despite Same Solver
By
–
PDEbench and PDEarena even use same solver to generate data (same Re, domain size, boundary for NS). Yet they arrive at contradicting conclusions. Discrepancies are likely coming from training protocol/ model tuning. Not good for #AI #PDE community to have this level of mismatch
-
PDEbench versus PDEarena: Initial Conditions and Reproducibility
By
–
In PDEbench initial conditions are explicitly provided which is great for reproducibility @Mniepert but PDEarena has a scalar for forcing and doesn’t specify how initial conditions are generated. Opaque. @jo_brandstetter @rejuvyesh Good to fix this @eigensteve @ShuiwangJi
-
Data Quality Over Volume: Key to LLM Training
By
–
3/ It's not about the volume of data, but diversity and quality—and getting & maintaining this kind of quality dataset takes work. More on this in the “Quality is all you need” section of the Llama-2 paper.
-
Transform Your Organization into an AI-First Company with Our Platform
By
–
You can turn your organization into an AI-first company, We built the world's ONLY AI-assisted data science and MLOps platform.
-
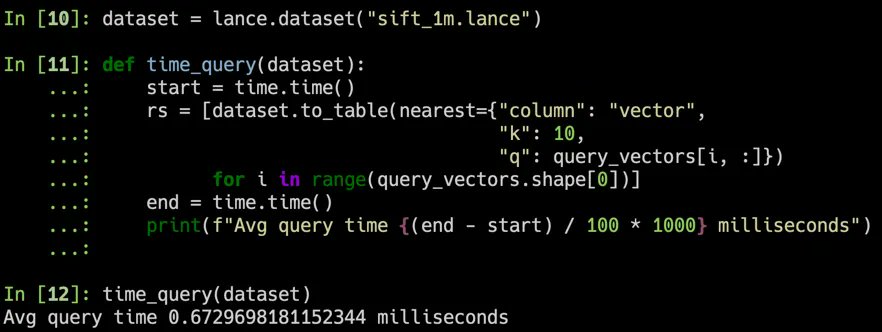
Modern Columnar Data Format for ML and LLMs in Rust
By
–
Modern columnar data format for ML and LLMs implemented in Rust. Convert from parquet in 2 lines of code for 100x faster random access, vector index, and data versioning. https://
bit.ly/3NwSGek #AI #MachineLearning #DeepLearning #LLMs #DataScience