
Every Job makes an AI Agent smarter. Every new skill can be instantly shared across the network. One Agent learns, all Agents level up — creating a self-accelerating intelligence engine where capabilities don’t add up, they compound exponentially. #AIAgents #Jobs
MACHINE LEARNING
-

Deep Learning with C++ and CUDA for High-Performance AI
By
–
Deep Learning with C++ — Design and deploy neural networks using CUDA for high-performance AI in C++ Get the book at https://
amzn.to/4nzdKB4 from @PacktPublishing @PacktDataML -
Technical analysis of attention head visualization and model interpretability
By
–
Its better for high-level debugging, clearly shows flow magnitudes and which heads contribute most. Standard heatmaps still win for fine-grained token-to-token patterns. but on larger models it gets dense/cluttered fast (even with collapsing)
-
Avoiding self-training bias in agent self-improvement
By
–
In SFT we often train on other agents data (distillation) so you’re right. However we also try to climb by self-improvement. This is where it becomes important for the agent not to train on its actions. Any bias on the agent beliefs (weights of the neural net) will be amplified.
-

7 Skills AI Can’t Replace Yet
By
–
7 #Skills #AI Can’t Replace (Yet)
by @Khulood_Almani #ArtificialIntelligence #MachineLearning #ML -
Comparing GBrain, Hermes, and Karpathy’s Brain Architectures
By
–
How does GBrain compare/contrast/complement things like Hermes/Karpathy's Brain?
-
GPU Memory Math for LLMs Explained
By
–
First, GPU Memory Math for LLMs (or why it is not always about Memory Size)
-
AI Agents Must Learn to Read the Room for Mass Adoption
By
–
#AIAgents Won’t Reach Mass Adoption Until They Learn To Read The Room
by Shailesh Nalawadi @Forbes Learn more: https://
bit.ly/4uPzZ8v #LLM #GenerativeAI #ArtificialIntelligence #ML -
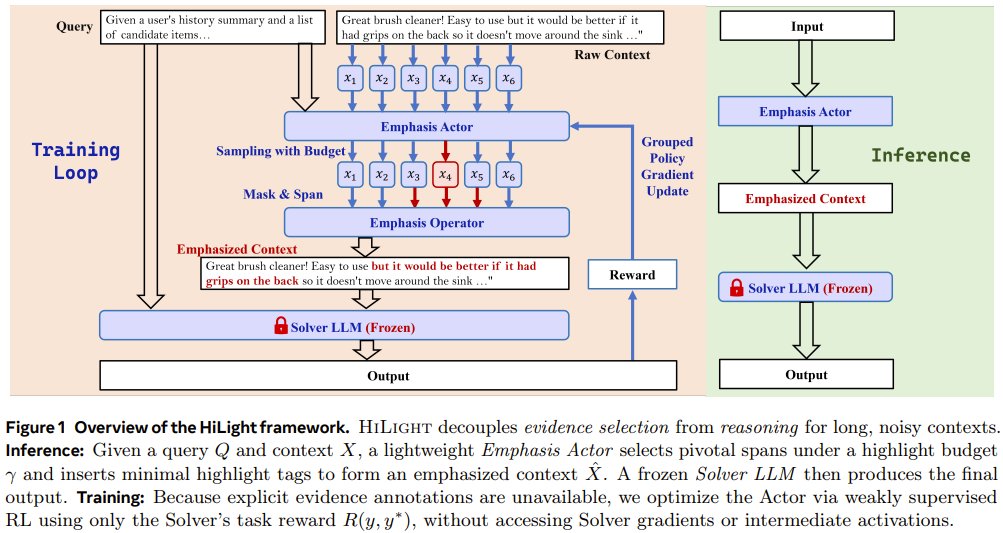
HiLight highlights key evidence in long contexts for frozen LLMs
By
–
Can LLMs find a needle in a haystack of text? Stony Brook University and Meta AI present HiLight: a lightweight system that highlights key evidence in long contexts for frozen LLMs. Instead of rewriting or compressing input, it trains a small Actor to insert highlight tags
-
Codex Model’s Role in Autonomous Design Execution
By
–
No, Codex actually communicates with MagicPat, like it’s Codex that is making the designs. Having it running in the app is a nicer addition to the experience, but the real magic is that it’s Codex that is in control. In their video, it is just a browser lmao.