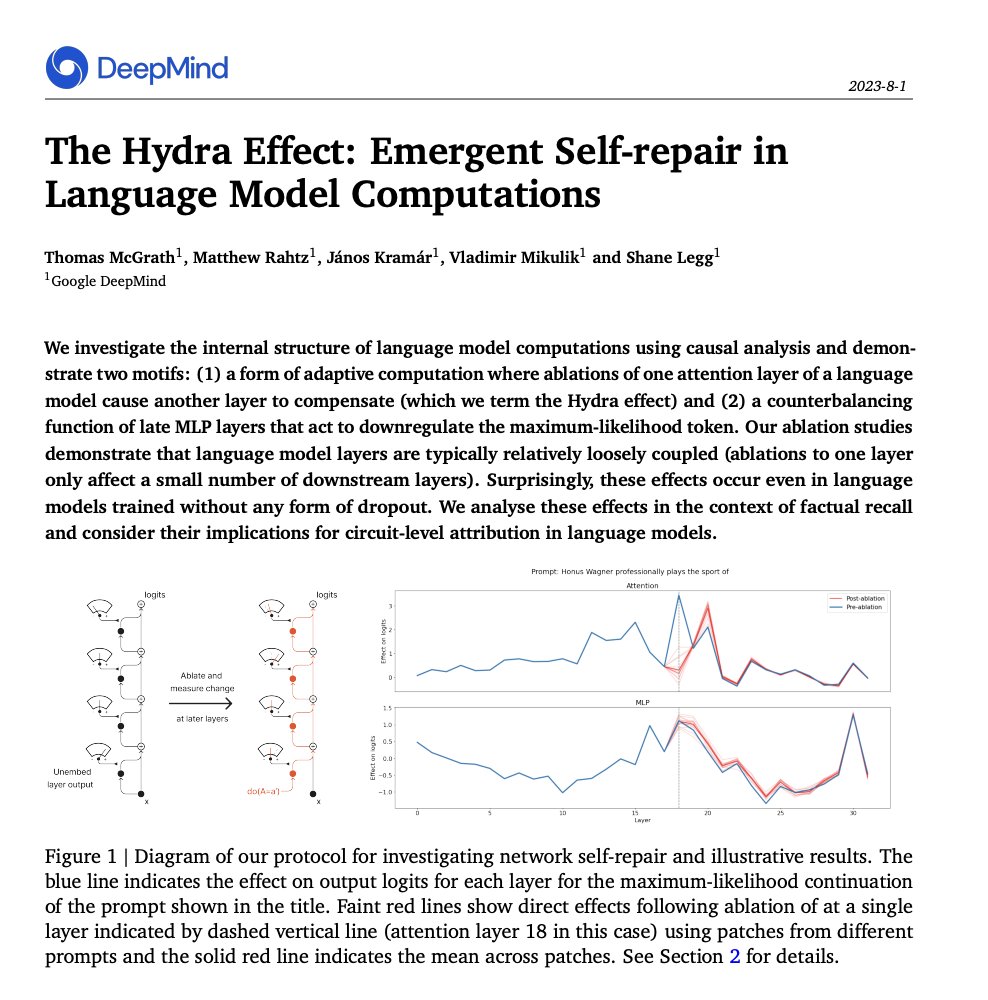
7/ The Hydra Effect – shows that language models exhibit self-repairing properties — when one layer of attention heads is ablated it causes another later layer to take over its function.
MACHINE LEARNING
-

Building Metrics for DevOps DataOps MLOps Data Ecosystems
By
–
You’ve built a solid #data ecosystem for your organization — now, let’s fire it up Move to producing and tracking metrics for robust data sets across #DevOps, #DataOps, and #MLOps in this part of The Executive’s Guide to Data, Analytics, and #AI https://
bit.ly/43UbSaZ -
Machine Learning’s Revolutionary Potential in Marketing Industry
By
–
Machine learning has the potential to revolutionize the marketing industry #AI #AIio #BigData #ML #NLU #Futureofwork @oluskayacan @richardkimphd @MariaFariello @johnpearcenews5 @ResurgentAV @rohanmuralee @globaliqx http://
ow.ly/cnjS30swzNB -
AI’s Superpower: Rewiring Work with Intelligence
By
–
Rewired to use AI’s superpower
#AI #AIio #BigData #ML #NLU #Futureofwork @CRudinschi @AntonioSelas @alexjc @RobotLaunch @karpathy @andyjankowski @bobgourley @CadeMetz http://
ow.ly/K5X130swzJS -
RLHF and Encoder Modules in Decoder Architectures
By
–
Sure I don’t disagree, but since all these were before RLHF finetuned decoder architectures, I am curious whether it’s still necessary to have an encoder module. LLaMA-Adapter would be an example of adding img2txt capabilities w/o cross attention.
-

Thoughts On AI Impact In Banking
By
–
Thoughts On AI Impact In Banking
#AI #AIio #BigData #ML #NLU #Futureofwork @Kevin_Jackson @sallyeaves @schmarzo @kdnuggets @akwyz @BrettKing @TechNative @MiaD http://
ow.ly/eUWl30swzJQ -
Fancy Index Lookups in Embedding Layers and Batch Matrix Operations
By
–
*fancy index lookups in embedding layers followed by fancy batch matrix-matrix products
-
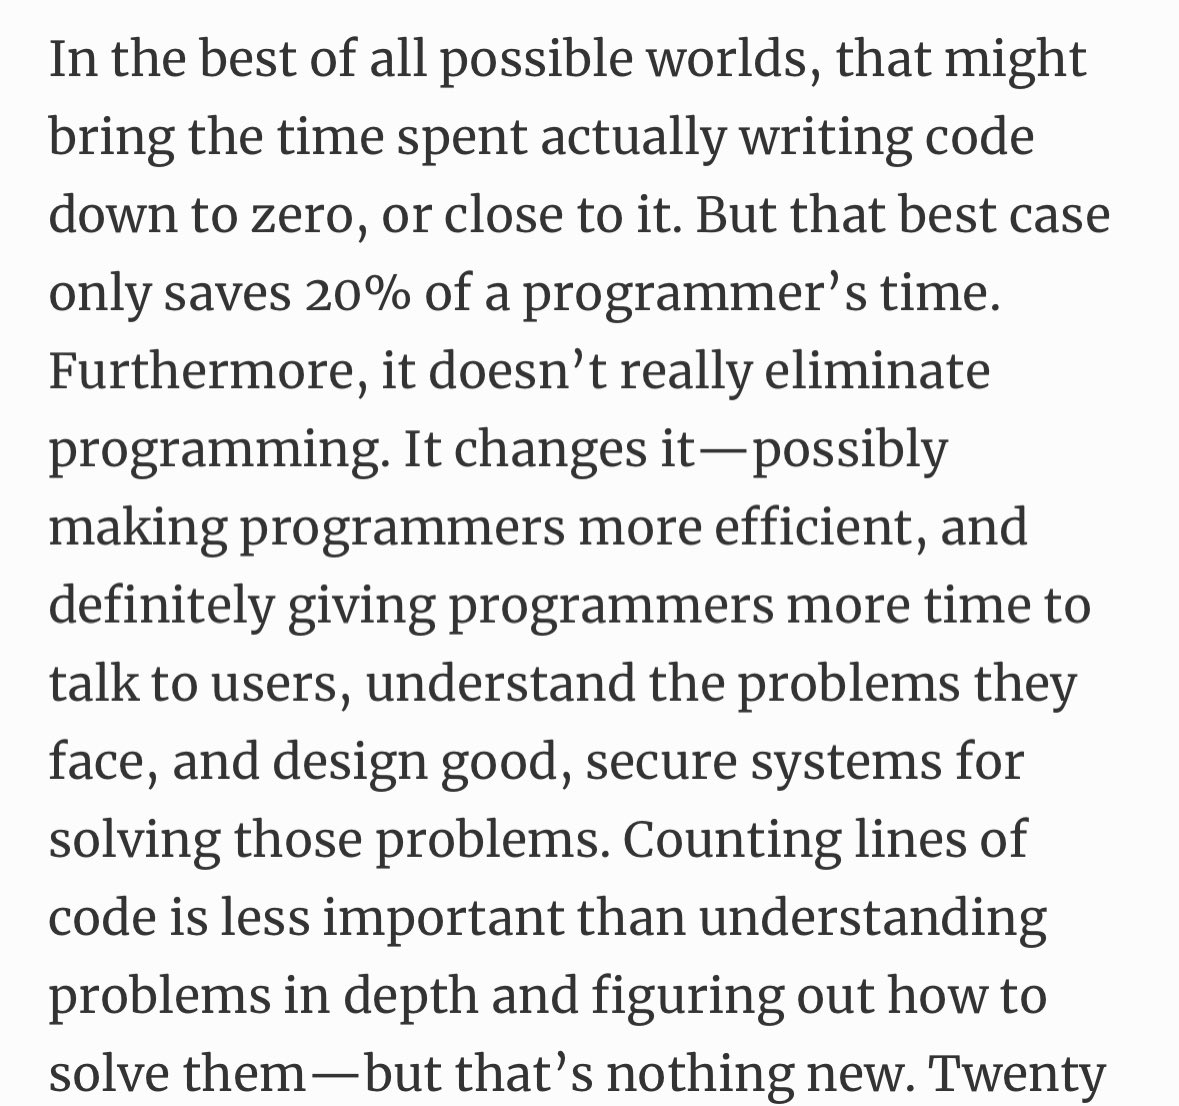
ChatGPT won’t revolutionize programming as much as feared
By
–
@mikeloukides on how things like ChatGPT will change programming, but not as much as we may think https://
oreilly.com/radar/fearing-
the-wrong-thing/
… -
Curiosity about empirical results in NeurIPS LLM efficiency challenge
By
–
Oh yeah, that makes intuitive sense. I am just curious about how this works out empirically. (The NeurIPS LLM efficiency challenge permits encoder, encoder-decoder, and decoder LLMs, so will will probably have to wait until the leaderboard is finalized haha)
-
Decoder-Only Architectures for Vision-Language Models
By
–
That makes sense. But you could also use a decoder-only architecture (with embedded image tokens as part of the input, as in LLaMA-Adapter, for example). (* This uses an encoder for the tokens, but it's still a decoder-only architecture due to the lack of cross-attention)