NN + Gzip because we got bored waiting https://
magazine.sebastianraschka.com/p/large-langua
ge-models-and-nearest
…
MACHINE LEARNING
-
Neural Networks with Gzip Compression for Language Models
By
–
-
Foundation math textbooks and advanced ML AI resources
By
–
Depends on your background and interests. Math textbooks are usually a good foundation for most technical fields.
Shameless plug: if you are into ML and AI and want to pick up some more advanced concepts after an intro book, my ML Q & AI might be useful: -
Lakehouse Monitoring: Unified Data and ML Asset Quality Control
By
–
#Lakehouse Monitoring offers a unified service to monitor the quality of your data and #ML assets. Check out this demo to learn how to: Diagnose errors in your projects Set up a monitor with low friction Enable self-serve experiences & more https://
bit.ly/44Si3xa -
Improving Question Answering Systems for Tabular Data
By
–
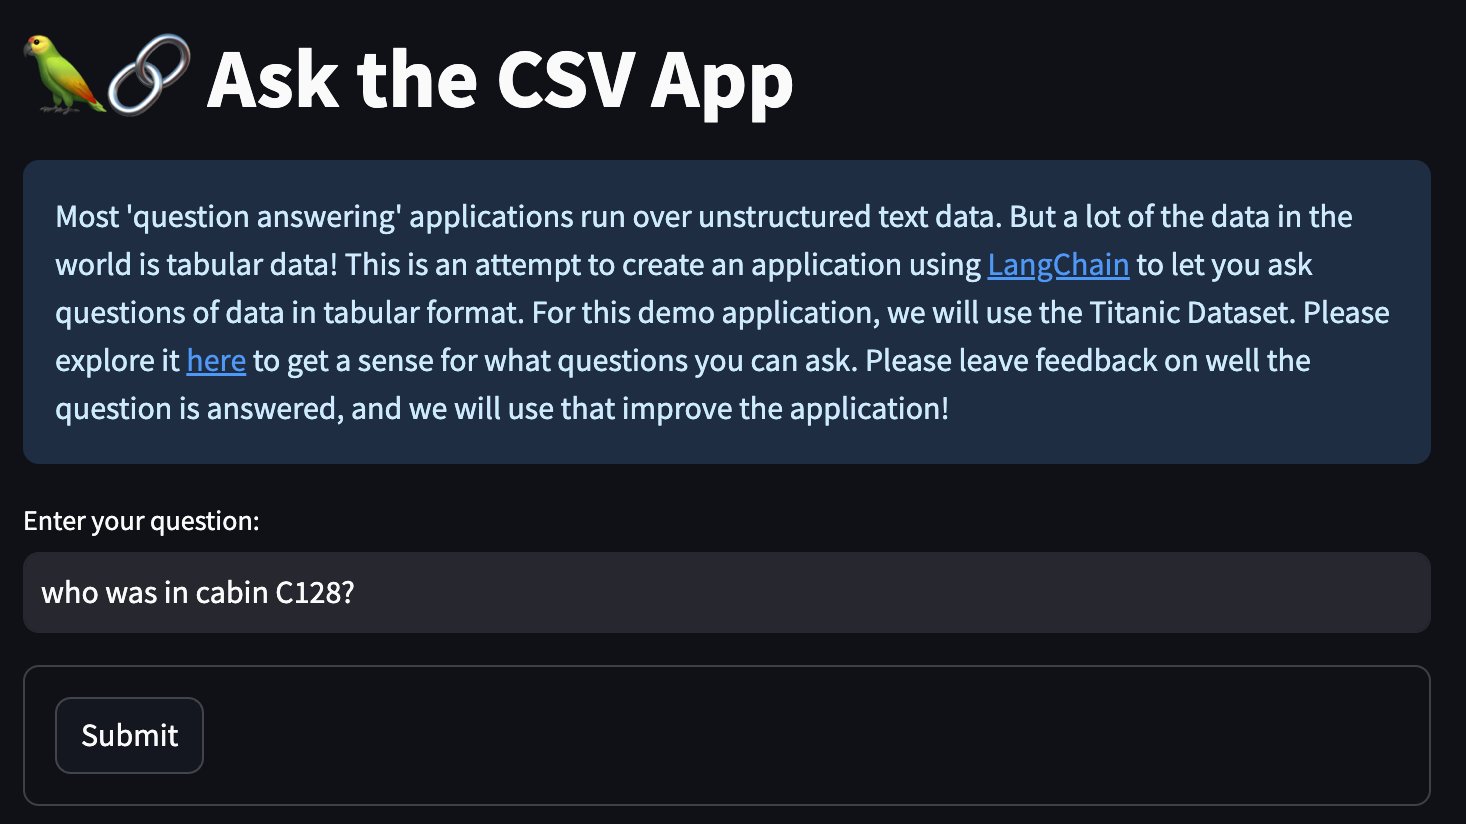
CSV Question Answering Most QA applications deal with asking questions of unstructured data. But a lot of data is in tabular (excel, csv) format! This has always been tricky to get right. We want to improve that! But we need your help
-
Comparison of decoder models with ChatGPT and GPT-4 after RLHF
By
–
! I’m mainly curious how it compared to decoders like ChatGPT or GPT-4 after RHLF
-
Comparing Decoder-Only Models to Encoder-Decoder Architectures for Translation
By
–
The original transformer is an encoder-decoder arch for translation. T5 is a great encoder-encoder that’s pretty good at translation. ChatGPT / GPT-4 is a decoder-only that’s pretty good at translation too. How does it compare to encoder-decoder architectures of similar size?
-
Clarification on inference versus pretraining data requirements
By
–
You mean during inference or regarding amount of data needed for pretraining?
-
Encoder-Decoder vs Decoder-Only Architecture Training Efficiency
By
–
You mean, assuming that both an encoder-decoder and a decoder-only architecture, the encoder-decoder is easier to train because you make better use of the data due to the masking pretraining tasks?
-
Encoder vs Decoder LLMs: Benefits for Seq2Seq Tasks
By
–
Use cases for encoder LLMs (classification) & decoder LLMs (chatbots) are obvious. Seq2seq tasks like translation, where it makes sense to have access to the whole input, is where it gets interesting.
Re encoder-decoder LLMs (eg T5): Is there still a benefit of using an encoder? -
Restarting Cosine Schedule at Epochs or Checkpoints
By
–
That's actually a good point. But it would be quite trivial to restart the cosine schedule after each ~epoch or checkpoint