Chez moi c’est déjà le cas, des IA codent des IA.
MACHINE LEARNING
-
Neurosymbolic Necessary but Not Sufficient, Says Marcus
By
–
neurosymbolic is necessary but not sufficient, see eg my 2020 arxiv The Next Decade in AI and the 2018 arxiv with innateness in the title
-
Marcus agrees on need for intrinsic spatial and temporal logic
By
–
oh i certainly agree on the need for intrinsic spatial and temporal logic, see eg my 2018 essay with innateness in the title, rebooting AI, etc
-
AI hype compared to sustainability hype, ways to fix it
By
–
Companies are hyping #AI the same way they talked up #Sustainability, but there are ways to fix that
by Suvrat Dhanorkar @ConversationUS Learn more: https://
buff.ly/gPLsvZR #ArtificialIntelligence #MachineLearning #ML -

Data Value Density framework boosts AI learning from less data
By
–
What if AI could learn more from less data? Researchers from Shanghai Jiao Tong University and Shanghai AI Lab introduce 'Data Value Density (DVD) enhancement' — a unified framework to make every training token count. Instead of just piling on more internet data, DVD methods
-

Cloud codex runner using Cloudflare Firecracker and Ghostty
By
–
Still limited by compute, so I built a thing that runs codex in the cloud, powered by @Cloudflare firecracker boxes (and since that's not beefy enough for larger projects, tests are run via crabbox) Uses Ghostty ofc, via WebAssembly.
Codex replicated itself, basically. -
Get a fourth RTX PRO 6000 to enable TP=4 flexibility
By
–
Get a fourth RTX PRO 6000 so you can run TP=4, you’ll have a lot more options and flexibility that way
-
ConvexTok: Linear Programming for Optimal LLM Tokenization
By
–
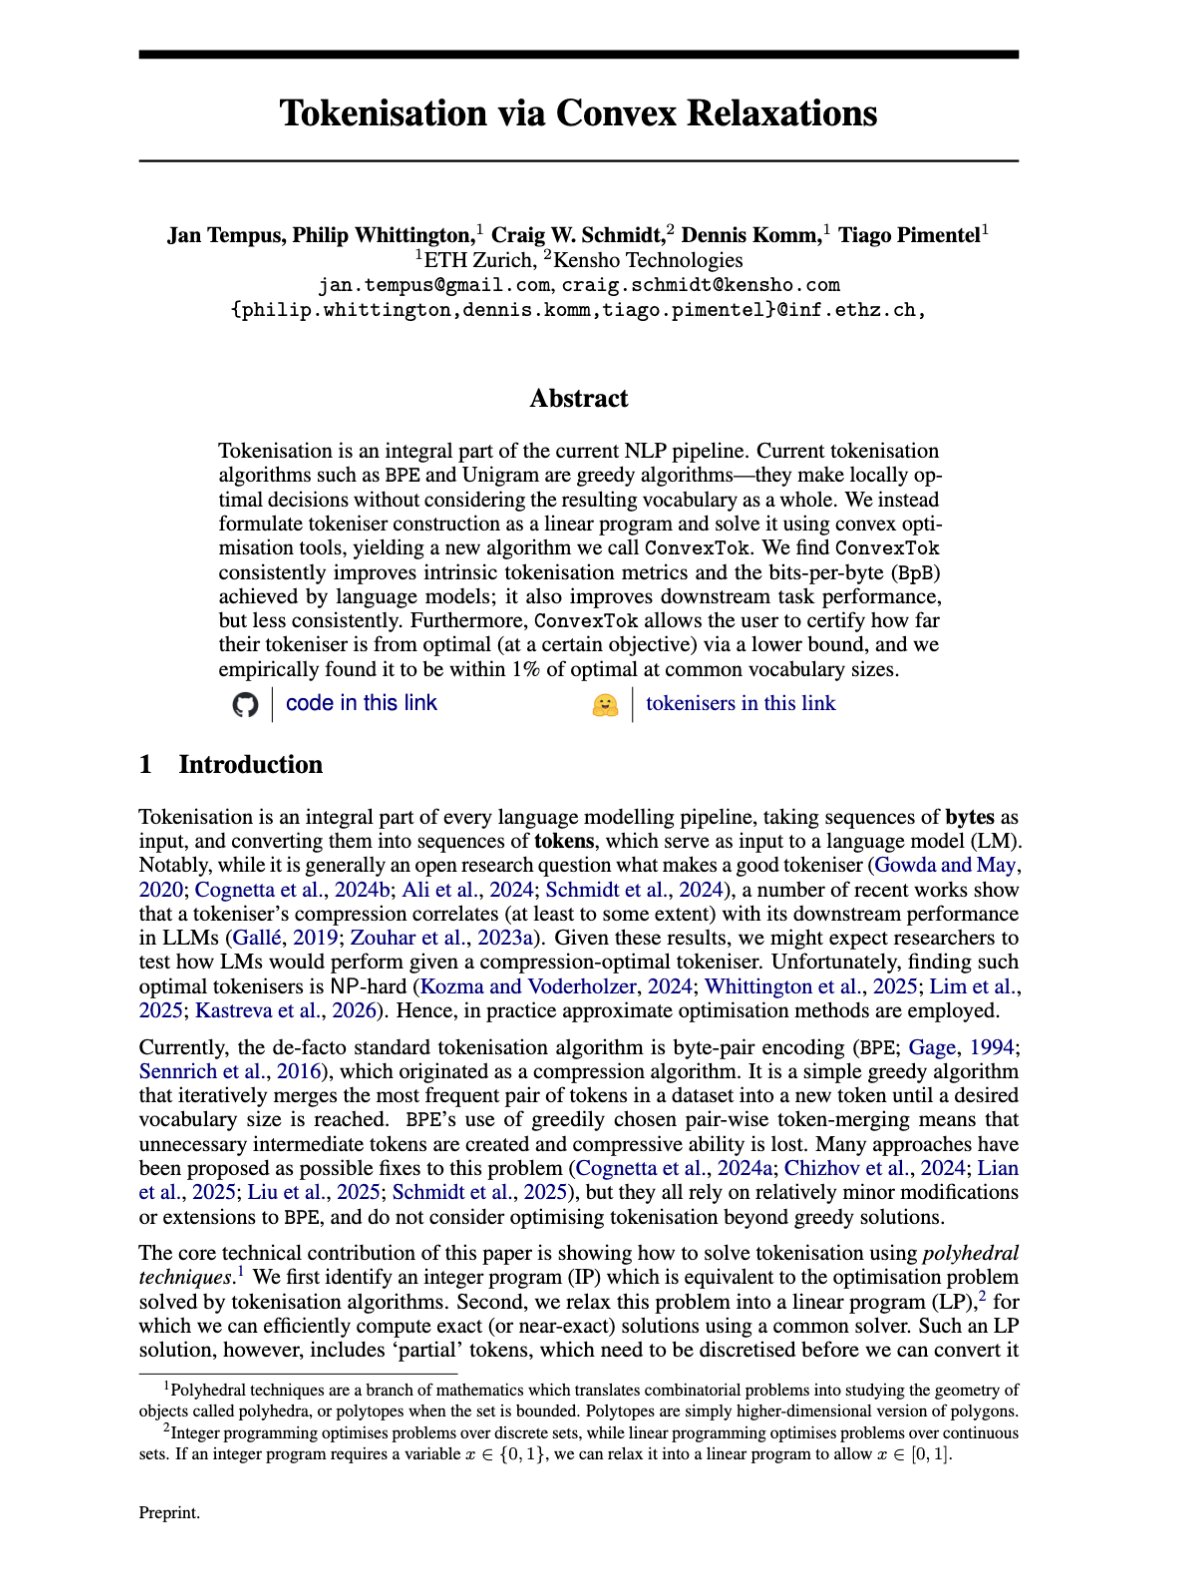
"Tokenisation via Convex Relaxations" Most LLM tokenizers still use BPE, a greedy merge algorithm that can waste vocab slots on locally good but globally suboptimal tokens. This paper turns tokenizer training into a linear program, then rounds the solution into ConvexTok. This
-
Gary Marcus: Deep Learning hitting a wall, possible Substack essay
By
–
almost all is clearly explained in my article Deep Learning is hitting a wall, in Nautilus: https://
nautil.us/deep-learning-
is-hitting-a-wall-238440
… but maybe i will go line by line in a substack essay? -
ConvexTok vs BPE: moving tokenization toward optimality
By
–
The key distinction: BPE gives us a strong procedure. ConvexTok gives us a procedure, an optimization relaxation, and a certificate. That moves tokenisation from engineering folklore toward measurable optimality.