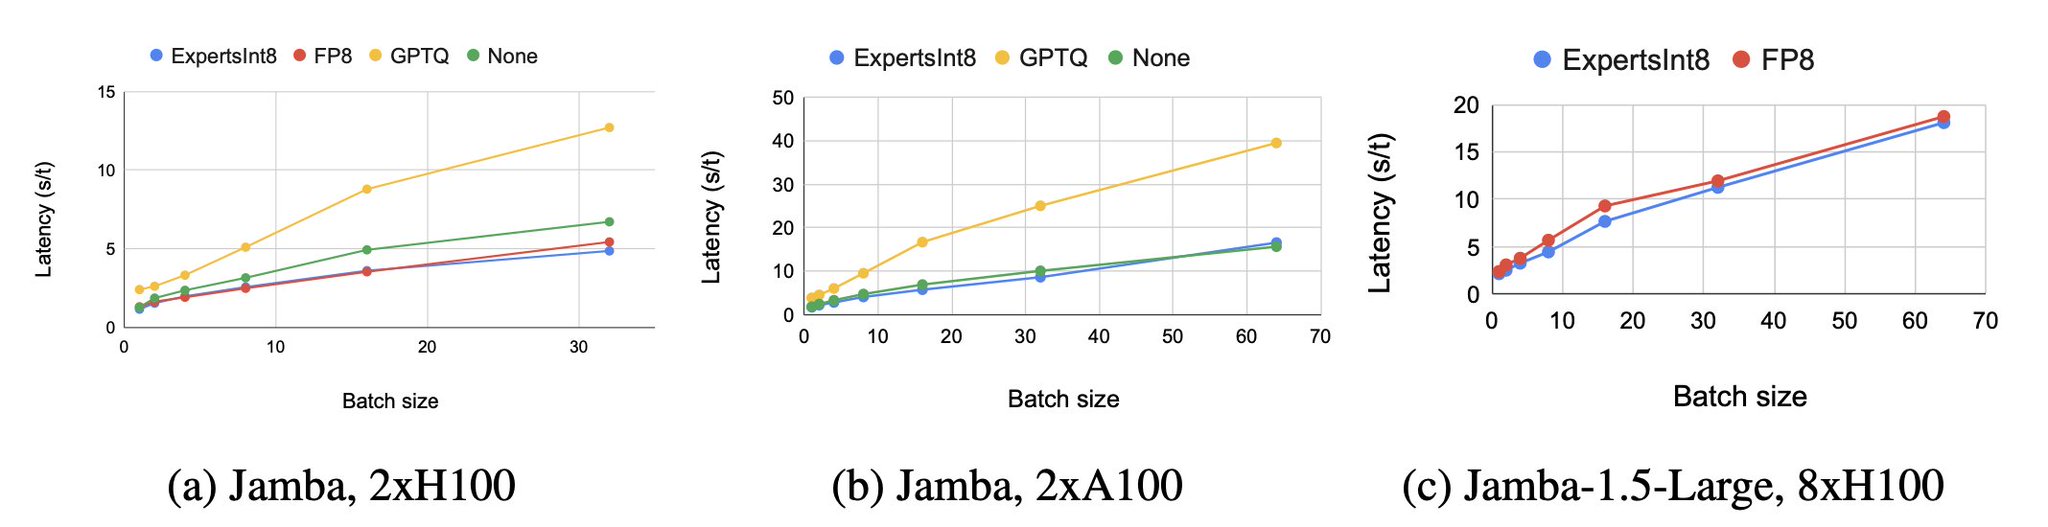
To support efficient serving of Jamba-1.5-Large, we developed a novel quantization technique – ExpertsInt8. We quantize the MoE and MLP weights to INT8 in order to store them, and dequantize them back to BF16 before the actual computation. This technique is both very fast and
MACHINE LEARNING
-

Jamba-1.5 Whitepaper Released: Hybrid SSM-Transformer Models
By
–
Jamba-1.5 whitepaper is out!
The whitepaper details the architecture, training schemes, novelties and in-depth evaluations of our new long context hybrid SSM-Transformer models – Jamba-1.5-Large and Jamba-1.5-Mini. Arxiv: https://
arxiv.org/abs/2408.12570 Here are some highlights and -
Hallucinations Leaderboard: Measuring LLM Reliability and Accuracy
By
–
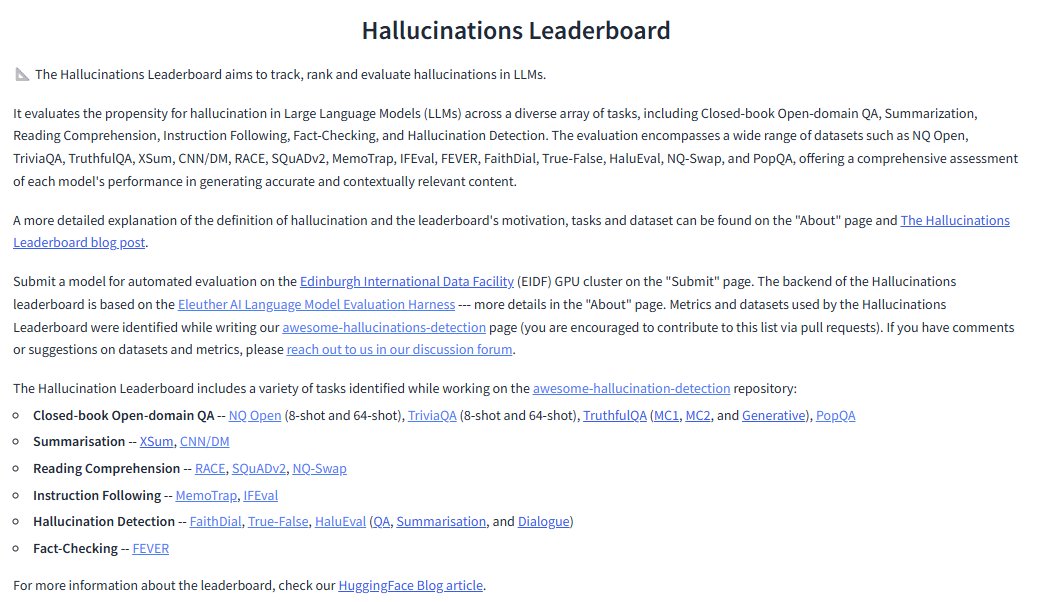
If you want to learn more hallucinations in LLM, I recommend the hallucinations leaderboard (cc @clefourrier
): https://
huggingface.co/spaces/halluci
nations-leaderboard/leaderboard
… It also comes with a nice paper from Hong et al. https://
arxiv.org/abs/2404.05904 -

Gemma 2 Model Size Performance Variations and Arena Optimization
By
–
For example, Gemma 2 2B IT answers correctly while the 9B version fails. I'd imagine that models optimized for @lmsysorg Chatbot Arena would perform worse, but that's not always the case.
-

Stable FP8 Training Recipe for Llama Models
By
–
Summary of stable FP8 training recipe for Llama models:
1. Clip learning rate when 2nd moment estimator is outdated by coming spike – see https://
arxiv.org/abs/2304.13013
2. SmoothQuant: smooths activation outliers by migrating the quantization difficulty to weights – see -
Diffusion Models as Autoregressive Models: Understanding Frequencies
By
–
The blogpost: https://
sander.ai/2023/07/20/per
spectives.html#:~:text=Diffusionmodelsareautoregressivemodels,-Fordiffusionmodels&text=Tounderstandthisithelps,detailscorrespondtohighfrequencies
…. -

Real-Time Video Generation with Pyramid Attention Broadcast
By
–
Real-Time Generation with Pyramid Attention Broadcast discuss: https://
huggingface.co/papers/2408.12
588
… We present Pyramid Attention Broadcast (PAB), a real-time, high quality and training-free approach for DiT-based video generation. Our method is founded on the observation that -
Show-o: Unified Transformer for Multimodal Understanding and Generation
By
–
Show-o
— AK (@_akhaliq) 23 août 2024
One Single Transformer to Unify Multimodal Understanding and Generation
discuss: https://t.co/haGX7CKOYp
We present a unified transformer, i.e., Show-o, that unifies multimodal understanding and generation. Unlike fully autoregressive models, Show-o unifies… pic.twitter.com/UosIpqiuYHShow-o One Single Transformer to Unify Multimodal Understanding and Generation discuss: https://
huggingface.co/papers/2408.12
528
… We present a unified transformer, i.e., Show-o, that unifies multimodal understanding and generation. Unlike fully autoregressive models, Show-o unifies -
Subsurface Scattering Integration in 3D Gaussian Splatting
By
–
Subsurface Scattering for 3D Gaussian Splatting
— AK (@_akhaliq) 23 août 2024
discuss: https://t.co/Yqxxln0beg
3D reconstruction and relighting of objects made from scattering materials present a significant challenge due to the complex light transport beneath the surface. 3D Gaussian Splatting introduced… pic.twitter.com/GAq7Km2vTESubsurface Scattering for 3D Gaussian Splatting discuss: https://
buff.ly/3T2GMep 3D reconstruction and relighting of objects made from scattering materials present a significant challenge due to the complex light transport beneath the surface. 3D Gaussian Splatting introduced