Using an ML technique called “probing,” they looked inside the model’s “thought process” as it generated new solutions. After training on >1 million random puzzles, they found that the model spontaneously developed its own conception of the underlying simulation, despite never
MACHINE LEARNING
-
MIT researchers find LLMs may develop their own understanding of reality
By
–
Can LLMs assign meaning to language, or do they simply mimic text? Peering into the mind of these models, MIT CSAIL researchers found that LLMs may develop their own understanding of reality to improve their generative abilities. Their research indicates that such models may
-
DPO Preference Tuning with Ollama LLM Tutorial
By
–
Link: https://
github.com/rasbt/LLMs-fro
m-scratch/blob/main/ch07/04_preference-tuning-with-dpo/create-preference-data-ollama.ipynb
… -

Building Large Language Models from Scratch Resource
By
–
Build a large language model from scratch with this very cool resource
-

Epigenetic Aging Clocks: Progress, Limitations, and Medical Promise
By
–
Epigenetic aging clocks have become a commonly used metric in medical research and are being marketed to consumers. The new Ground Truths with @prof_horvath
, who discovered these clocks a decade ago, provides a frank appraisal of their progress, limitations, and promise. With -
AI Accelerates Patient Selection in Orthopedic Surgery
By
–
[#Article] Orthopedics: AI accelerates patient selection for hip arthroplasties https://actuia.com/actualite/orthopedie-lia-accelere-la-selection-des-patients-pour-les-arthroplasties-de-la-hanche/
… #AI #ArtificialIntelligence -

LitServe Launch: Next-Generation AI Model Serving Engine
By
–
Super exited to announce that we've Launched LitServe! The next-gen serving engine for AI models—lightning fast , scalable. – 2x faster than FastAPI (at least)
– GPU autoscaling
– Batching, streaming
– LLMs, NLP, vision
– PyTorch, SkLearn, Jax…
– … 10+ features Star -
Jamba Architecture Advantages in Long Context Fine-Tuning Efficiency
By
–
We found our efficient Jamba architecture to be advantageous in long context fine-tuning, as it allows for greater speed and lower cost. Therefore, we could experiment with multiple different training recipes during the fine-tuning phase. This is especially interesting for all
-
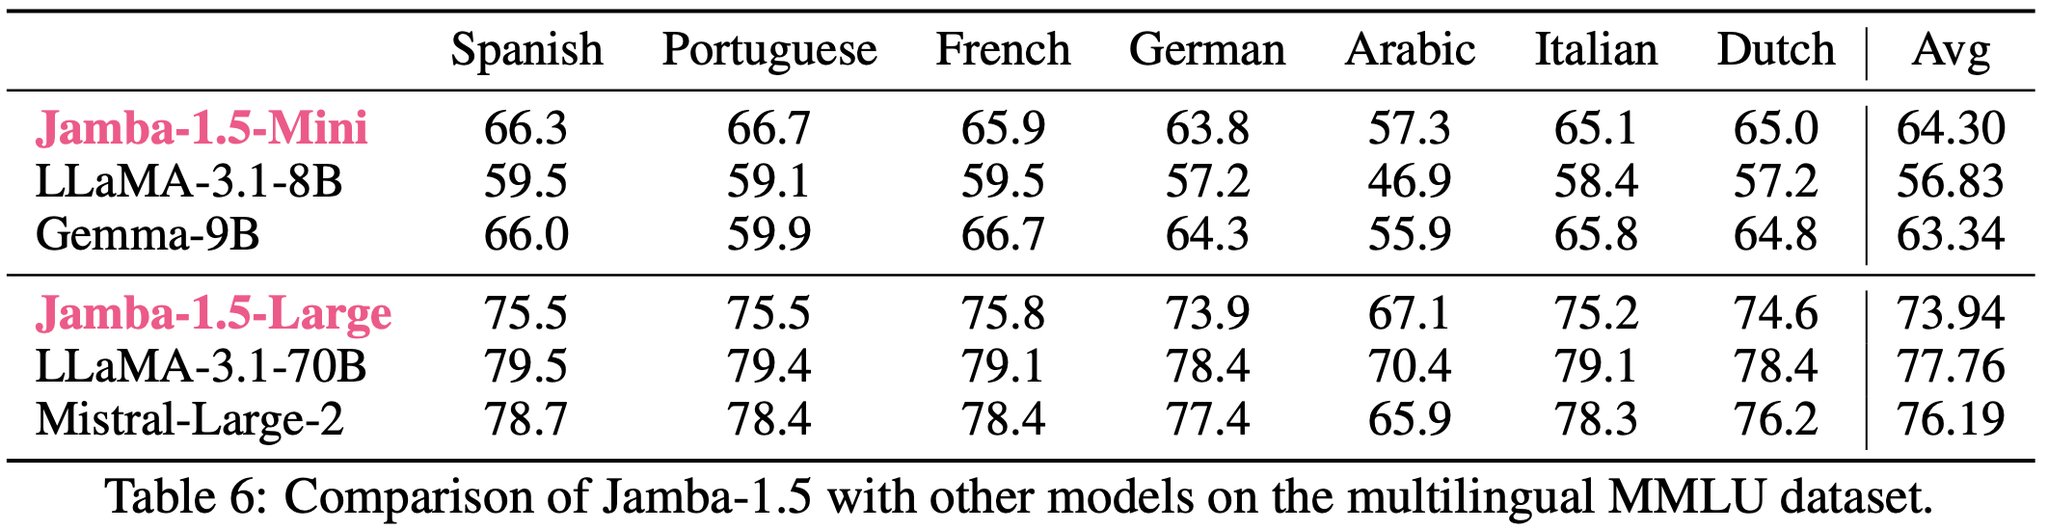
Jamba-1.5 Models Demonstrate Strong Multilingual Performance Despite Limited Post-Training Data
By
–
Jamba-1.5 models perform well in multiple languages, even though we include only a very small fraction of non-english data in the post-training phase. Therefore, we speculate the models are able to use the learned multilingual capabilities from the pre-training phase. 6/7
-
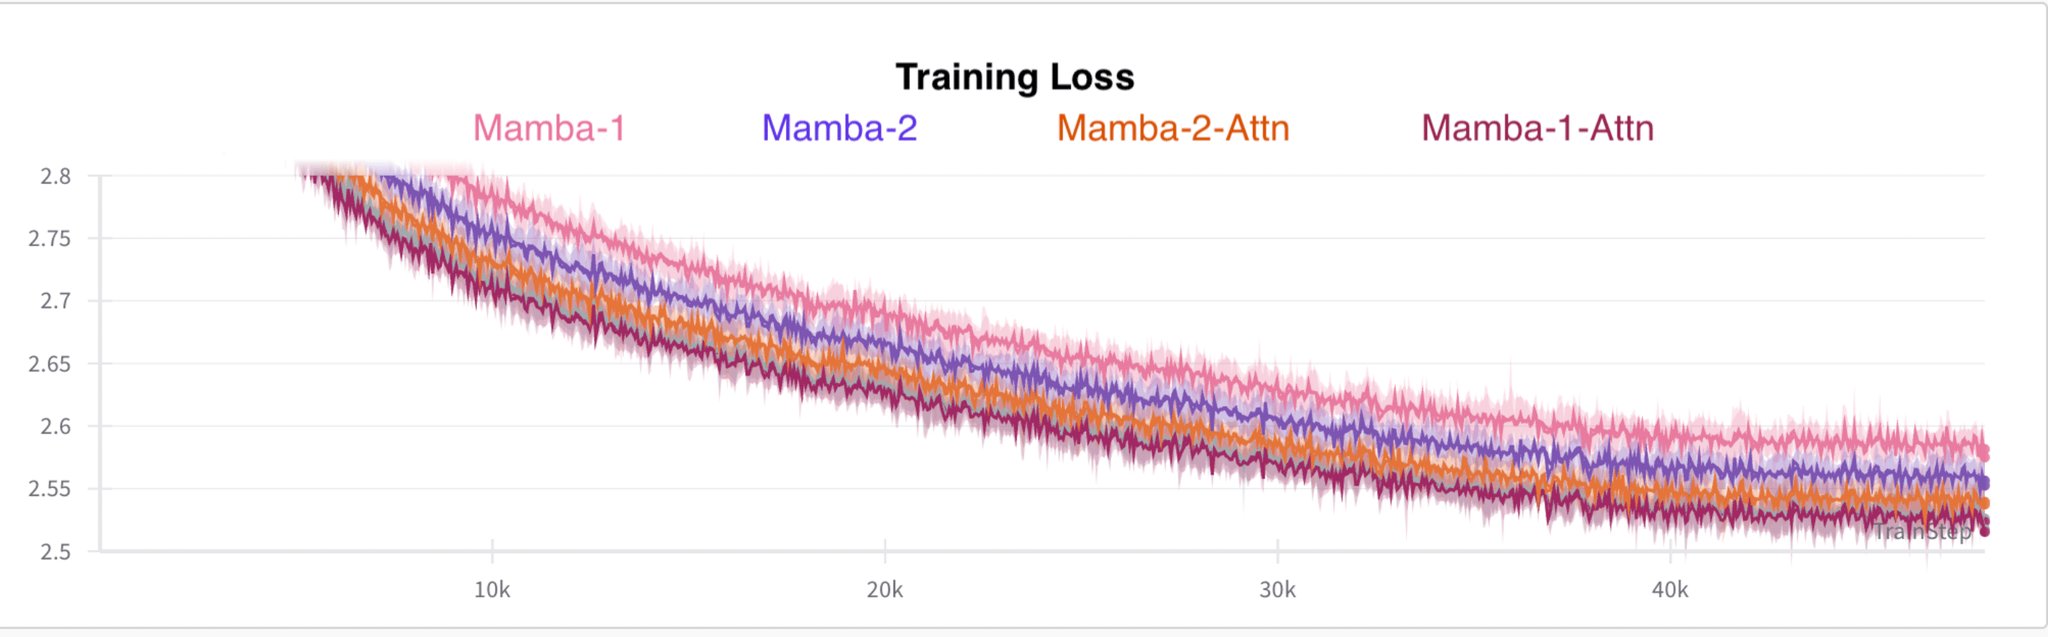
Jamba Architecture: Mamba-1-Attention Hybrid Outperforms Mamba-2
By
–
We experimented with alternatives to our final Jamba architecture, including Mamba-2 (which was released a few months after the original Jamba). However, we found that in a hybrid architecture, the Mamba-1-Attention combination outperforms both Mamba-2-Attention and pure Mamba-2.